Industrial AI Models
This page collects the industrial AI models ThakiCloud has published on Hugging Face. All of them are research previews, not product launches. Each model differs in data, evaluation method, and the nature of its labels, so the numbers below are not a ranking between models.
Plain terms
These models are like new inspectors on a plant maintenance crew. They did well on tests at the training center, but none has worked the floor alone yet. So for each model we note which training center it was tested in, what the test was, and what has not been tested.
At a glance
| Model | Input | What it does | Headline metric and evaluation condition | License |
|---|---|---|---|---|
| Thaki-MCSA-MantisV2-MCC5 | Three-phase motor current | Classifies 24 fault states | Macro-F1 0.943 on 71 sealed TEST recordings, single test rig | Apache-2.0 |
| Thaki-EquipmentHealth-Sensor-LGBM | Current, temperature and particulate sensors on transport vehicles | Sorts equipment health into four states | Macro F1 0.94 on unseen vehicles, labels from a testbed simulation | CC BY 4.0 |
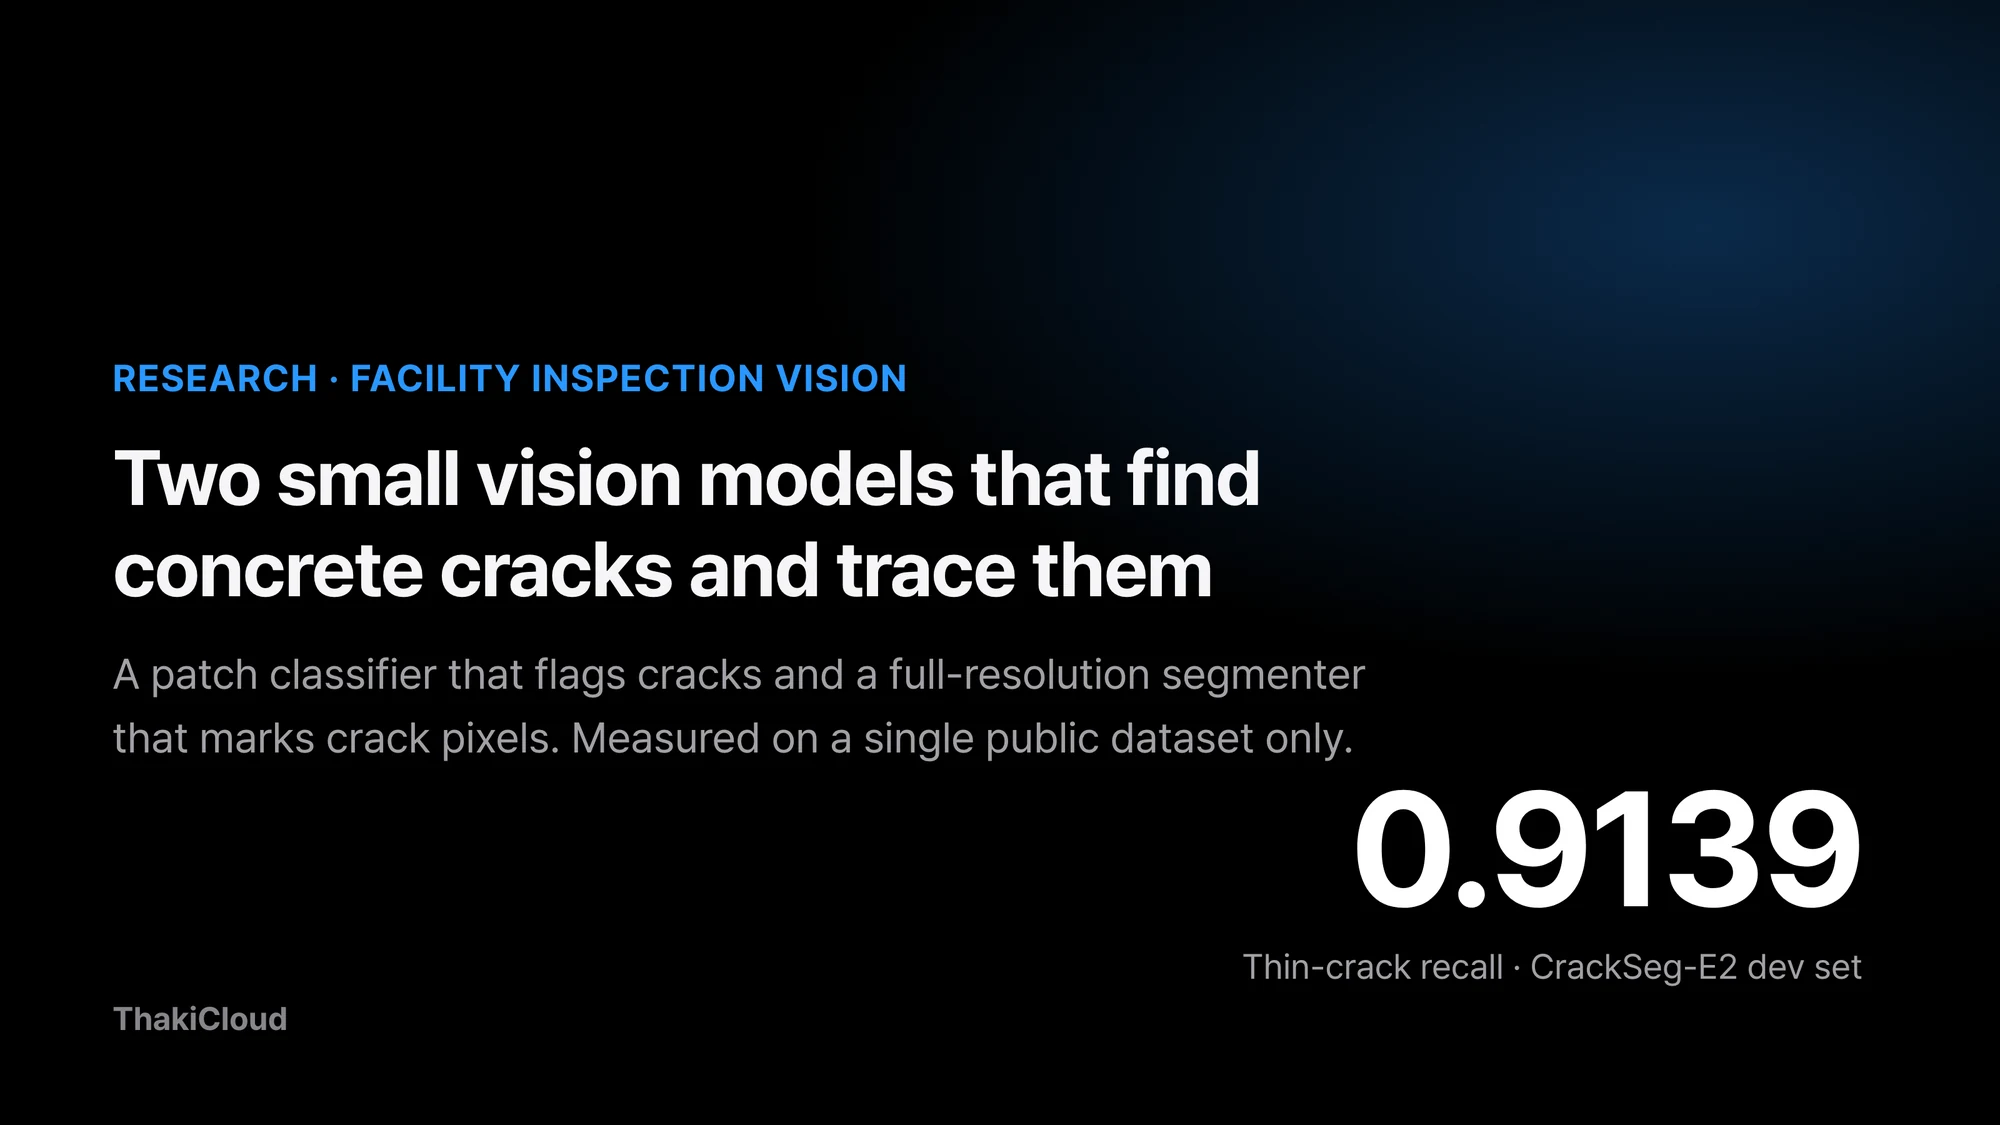
| Thaki-FacilityVision-CrackCls-ResNet18 and CrackSeg-E2 | Concrete surface photos | Crack patch classification and pixel segmentation | Classification Macro F1 0.9993, segmentation Dice 0.8983, one public dataset | CC BY 4.0 |
| Thaki-FactoryShield-KO-7M | Korean equipment command sentences | Proposes commands without executing them, or refuses | Passed a synthetic sealed test only, no real field utterances evaluated | Custom research license |
Model cards
Thaki-MCSA-MantisV2-MCC5
- Use: A research model that separates normal from 23 fault states using only a motor’s three-phase current. It fine-tunes the pretrained time-series model MantisV2.
- Input and inference: Current at 12.8kHz is cut into 65,536-sample windows, each phase becomes a 512-bin Welch log spectrum, and per-window probabilities are averaged to classify a recording.
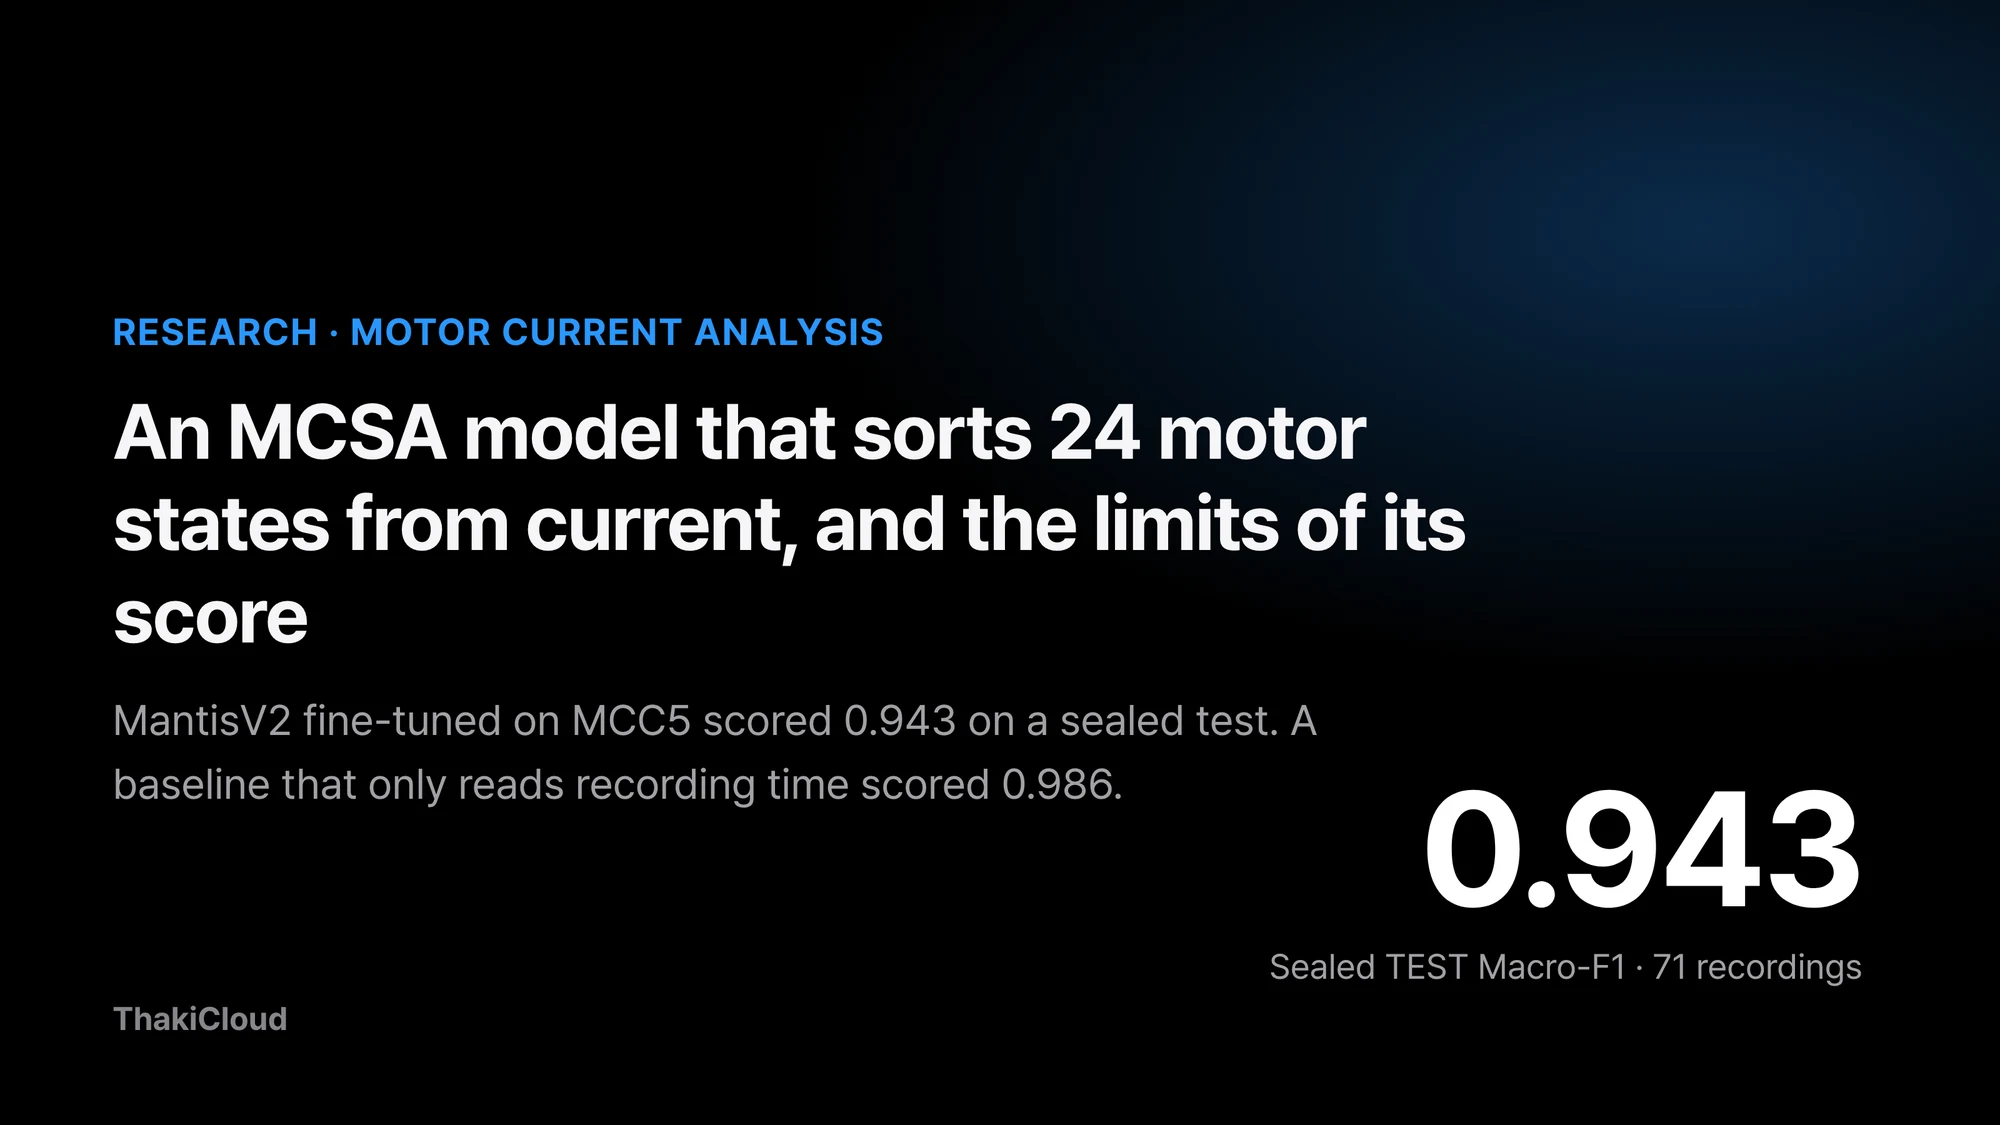
- Headline metric: Macro-F1 0.943 on 71 sealed TEST recordings from 3 operating conditions never used in training. The development LOCO cross-validation score of 0.945 averages models retrained per fold; the released file is a single model retrained on all 208 development recordings.
- Limits: On the same TEST, a baseline using only the recording time scored 0.986, and one using only the date scored 0.127. There is only one test rig, so we do not claim generalization to other physical motors. 3 of the 4 errors confuse winding fault H and L.
- Data: MCC5-THU, Mendeley Data, CC BY 4.0.
- Links: Hugging Face · post MCSA model release
Thaki-EquipmentHealth-Sensor-LGBM
- Use: Sorts semiconductor-fab transport vehicles (OHT and AGV) into normal, attention, warning, and danger from sensor readings. The model is about 1 MB.
- Headline metric: Macro F1 0.94 on unseen vehicles, and none of 930 danger readings was called normal.
- Limits: Labels are not real failure records; they come from the dataset’s testbed simulation system. We do not claim it predicts real failures. About one normal reading in twenty raises an attention alert.
- Data: AI Hub (AI-Hub) dataset 71802 (OHT and AGV equipment). The data is not redistributed.
- Links: Hugging Face · post Equipment health from sensors
Thaki-FacilityVision-CrackCls-ResNet18 and CrackSeg-E2
- Use: A classifier that picks crack patches from inspection photos (ResNet-18, about 11 million parameters) and a segmentation model that draws crack shapes at full resolution (U-Net with a ResNet-34 encoder, about 24 million parameters).
- Headline metric: The classifier scored Macro F1 0.9993 on 5,524 test patches. The segmentation model scored Dice 0.8983 and thin-crack recall 0.9139 on 60 development images.
- Limits: Measured on one public dataset only, so these are not field accuracy. The segmentation model’s 61 test images have not been scored yet.
- Data: Ç. F. Özgenel, Mendeley Data, CC BY 4.0.
- Links: CrackCls · CrackSeg · post Crack vision models
Thaki-FactoryShield-KO-7M
- Use: Turns a Korean equipment command into a proposal made of an operation, an equipment ID and a delay, or refuses. It has 7,352,909 parameters, and
safe_to_actuatein its output is alwaysfalse. - Safety boundary: The equipment ID the model picks is checked exactly against a registry of equipment IDs. If it is not in the registry, or no registry is given, the output is
ABSTAIN. - Headline metric: On the synthetic sealed test, model-only risk was 2.57 to 3.90%, and system risk with the validator and registry was 0.00 to 0.33%.
- Limits: All numbers come from synthetic data, and safety has never been validated in a real equipment environment.
- Links: Hugging Face · post FactoryShield release
What the released models prove, and what they do not
Please read these three things separately.
What the research models showed is the result within the data and evaluation conditions on the cards above. The weights and evaluation contracts are public, so anyone can measure again under the same conditions.
What the platform provides is an operations layer that trains and serves models in the customer’s environment (Metis), and an agent layer that ties model verdicts to reviewer checks, approvals, and work records (Paxis). The Paxis flows in each post are reference designs, not field measurements of these models running as an integrated product.
What a field PoC has to check is generalization to different equipment, performance against real failure records, false alarms and missed faults per hour of operation, and latency on field devices. Public data cannot answer these; they need the customer’s equipment data and an evaluation design.
If you are considering adoption
- Start with the equipment and the data. Equipment type, sensor setup, sampling rate, and the conditions under which normal and fault records were collected come before choosing a model.
- Set the evaluation design. Hold out equipment or time periods never used in training, and check that equipment IDs or collection times do not stand in for the answer.
- Get in touch. If you want to assess this on your own equipment data, contact ThakiCloud.
Related posts
The list below shows every post tagged industrial-ai. The main posts are:
- We Released a Motor Current Signature Analysis (MCSA) Model
- Reading Equipment Health from Sensors, and Letting Paxis Open the Maintenance Work
- Two Small Vision Models for Finding Concrete Cracks, Now Public
- A 7M Model That Proposes Equipment Commands and Never Executes Them: Thaki-FactoryShield-KO-7M
FinTermIE-EventPrice-KO: A 278M-Parameter Encoder That Extracts Pre- and Post-Adjustment Conversion Prices with Their Positions
On 258 filings from unseen issuers it scored 0.798 before and 0.938 after adjustment, ahead of the rule baseline (0.601, 0.729), and all 457 values it returned matched their evidence positions.
Chips Are Smuggled, Models Testify
A report that Nvidia Blackwell GPU fingerprints were found in the weights of a public frontier model, a DeepSeek funding round used to procure restricted GPUs, and a US regulation draft blocking cloud rental in seven countries.
The Quantized Reranker: The Paper That Re-Measures the Cost-Quality Frontier of the Four Corners ({27B, 8B} × {BF16, NVFP4}) of the Size×Precision Factorial for the LLM Rerank Stage of Hybrid Skill Routing on Self-Hosted H200 and Shows Why the Factorial's New Measurement Under Deterministic Token Billing Is Only a Single Interaction Term κ
The router series priced the size, width, and precision axes one at a time, but the size×precision factorial of the rerank stage remained unpriced.
PowerProof: Why GPU Power Prediction Failed to Transfer from H100/H200 to B200
We trained serving power models on H100 and H200 measurements and applied them unchanged to B200.
DocFields F3.2: Better Field-Role Extraction on Korean Financial Forms by Restoring Generic Date and Account Number Labels
One checkpoint now recovers the generic dates and account numbers our previous single model dropped.
The $895.4 Billion Defense Line
Anthropic’s roadshow put its ledger on the table.
While Everyone Watched the Accelerator, Google Swapped the Host
The TPU 8i Max is the muscle; the host CPU is what decides data flow and task orchestration.
The First Cargo on the Medical AI Highway Is the Referral Letter
The first stretch of the public medical AI highway has opened, cutting referral letter writing time from 10 minutes to 1 minute.
The AI Industry, One Risk Table: The Jensen Huang Risk and Korea's Seat
An NVIDIA CEO governance probe, TSMC equity stakes in OpenAI and Anthropic, an Anthropic IPO of up to $90.4 billion.
41.3%, A Number That Is Not a Score
Today’s morning news has a number that is hard to read as a benchmark score.
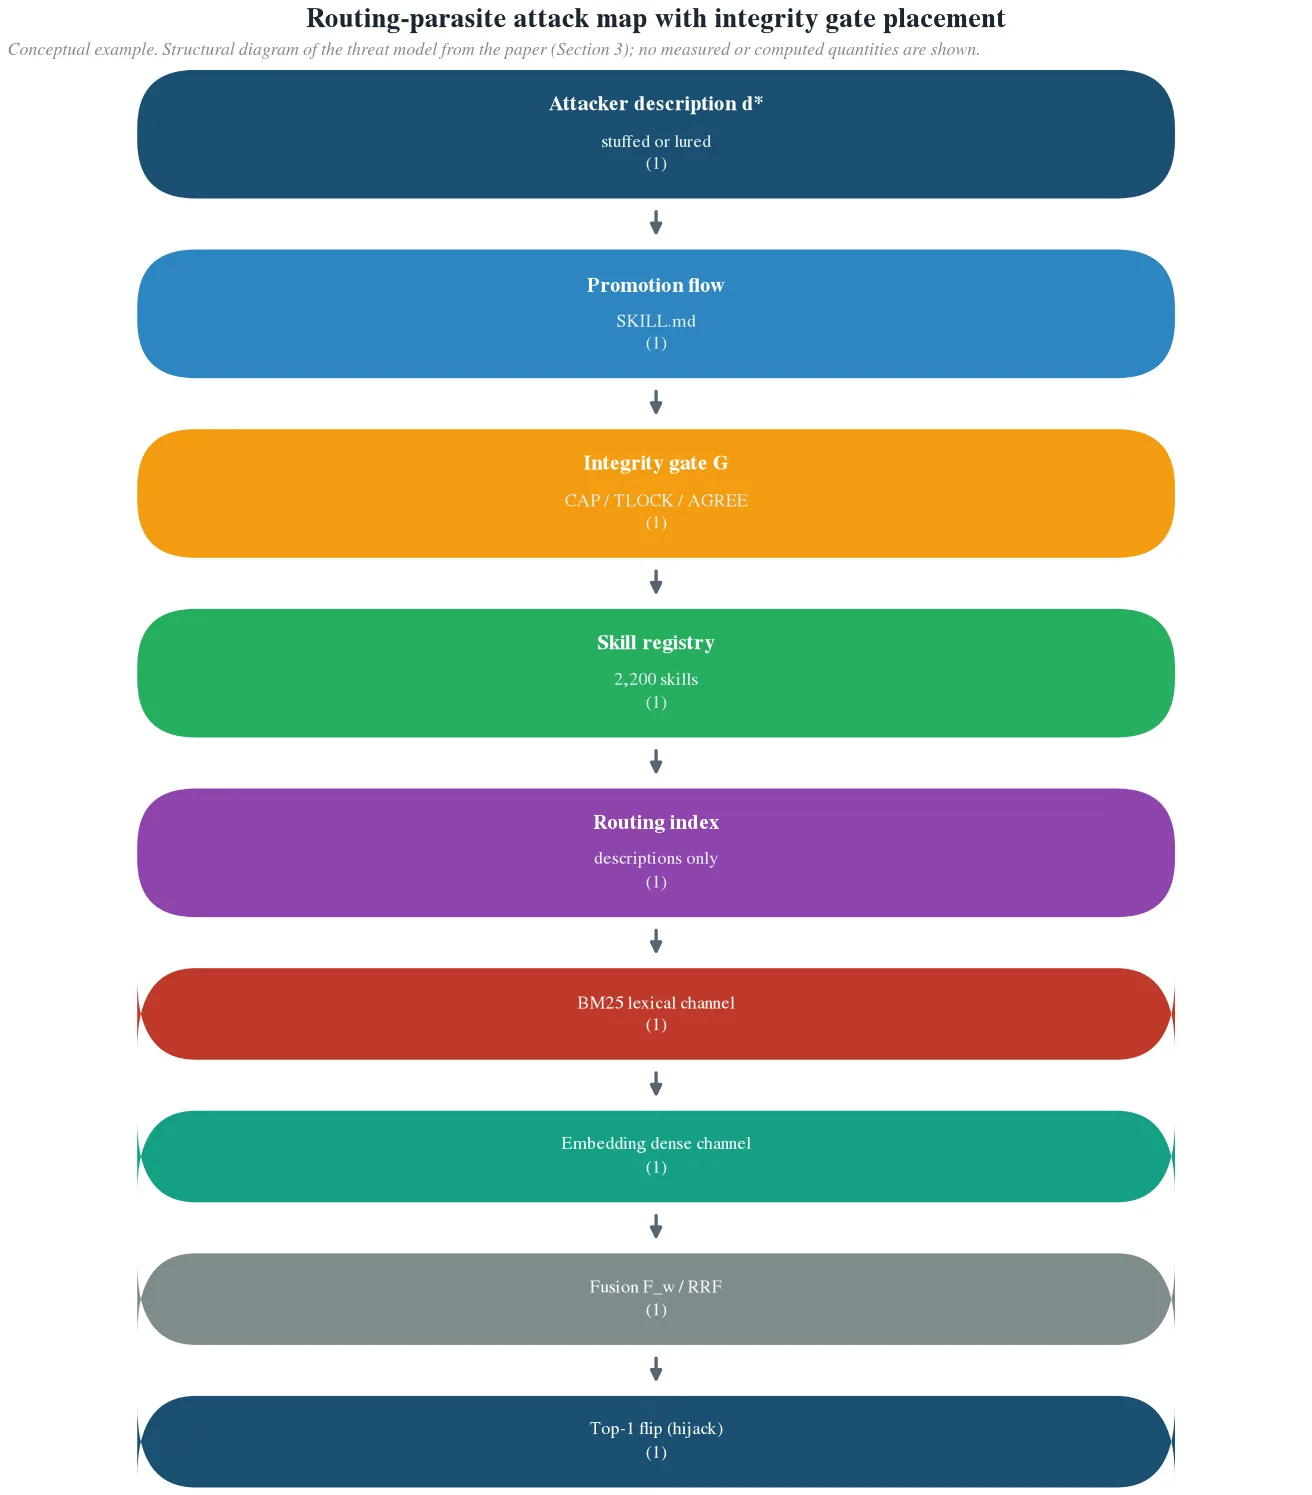
The Routing Parasite: A Paper That Prices Description-Level Hijack in Hybrid BM25+Embedding Skill Routers and the Cost-Quality Frontier of Description Integrity Gates
With no payload, no execution, and no visible change, one maliciously rewritten line of description can steal about 5.8% of routing traffic.
Releasing EvidenceLink, a Reranker That Finds the Original Filing a DART Correction Amends
We released a reranker on Hugging Face that picks the original filing for a correction among nearly identical convertible bond filings from the same company.
The Day the Capability Race Built the Brakes: OpenAI's 35-Second Emergency Stop
OpenAI has made public that it can stop the output of its own frontier model within 35 seconds.
The Day the Agent Became an OS, the Harness Disappeared
DeepSeek’s agent framework ‘Harness’ reached 1.54 million daily active users and 92 trillion tokens a day within three months of launch.
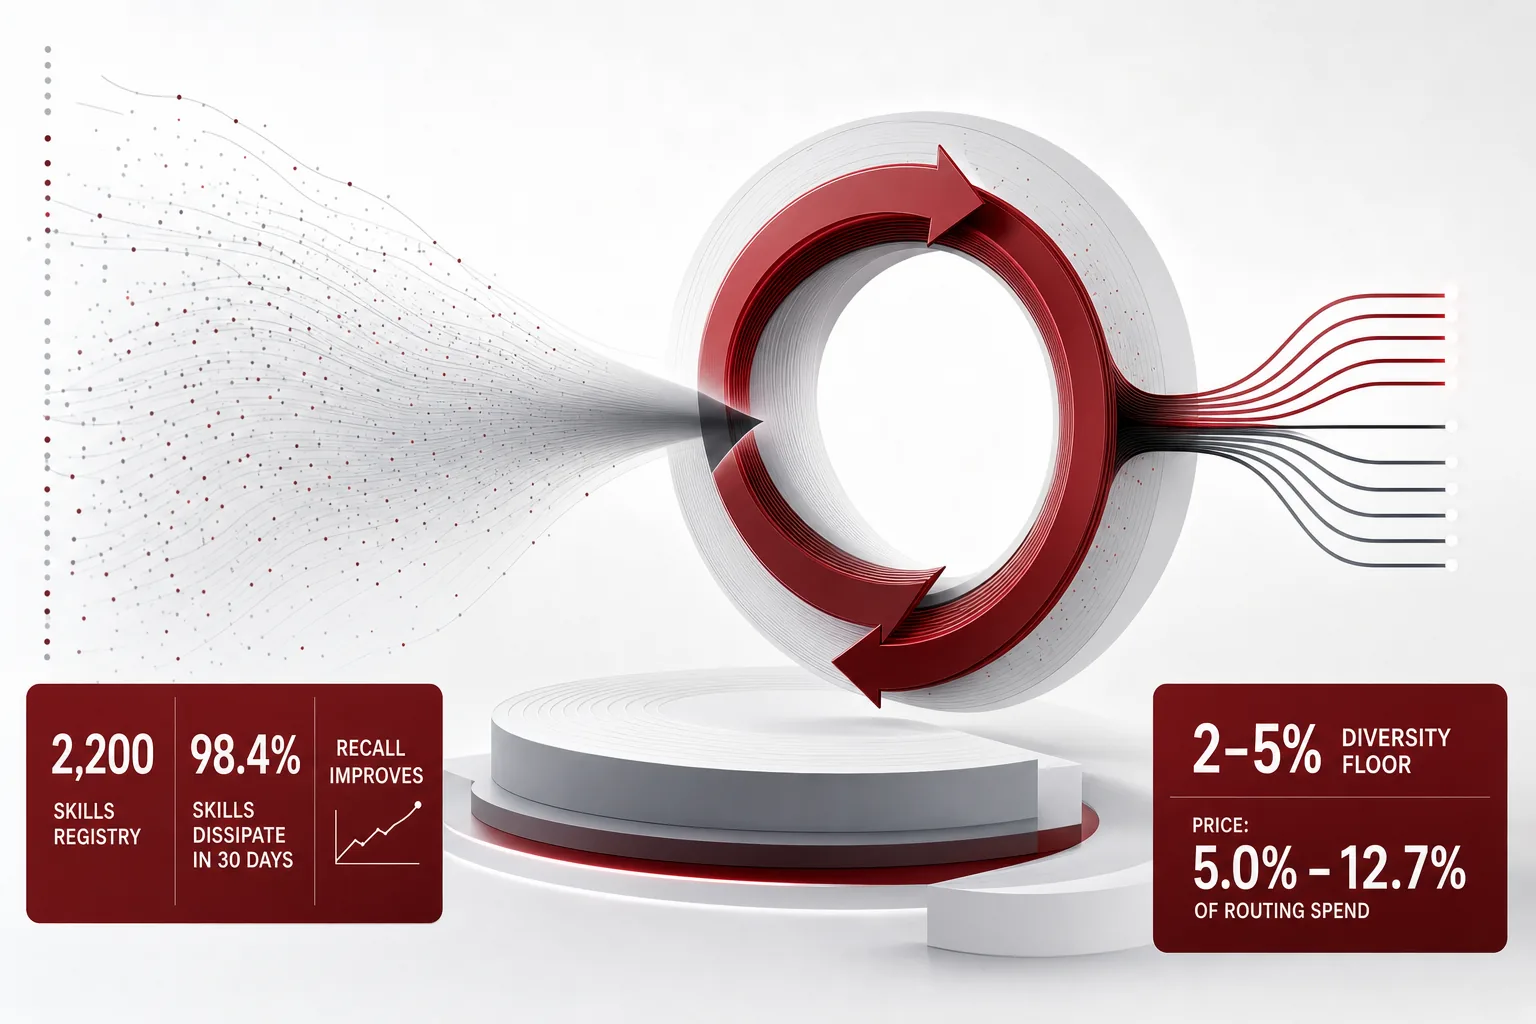
The Oligopoly Loop: A paper that prices the wealth dynamic in which overnight outcome-fed self-evolution concentrates 2,200-skill routing into a few super skills and lets 98.4% of the skills go extinct within 30 days, and the closed-form token price of the 2~5% diversity floor that holds the recall fixed point
The overnight self-evolution loop of an unattended harness quietly shrinks the menu it serves while the quality metrics improve.
Why We Did Not Train a Document Field Extraction Model: A DATA_NO_GO From a Label Schema Audit
A large dataset does not mean the answers your task needs are in it.
Power Can Be Bought, but the Speed Did Not Come from Compute
The independent evaluation group METR ruled out compute growth as the main driver behind Anthropic’s 2x research speedup.
The Agent Takes the Seat Beside You: Lattice, a Local-First LaTeX Workspace
An undergraduate student’s side project called Lattice puts the source, the PDF, the paper library, Overleaf co-authors, and the AI agent you bring yourself into one macOS window.
Danggeun Opened Its Door to ChatGPT. What Really Matters Is the Doorman
Korea’s used-goods marketplace Danggeun is opening its ad system to ChatGPT and Claude with an ‘Ads MCP’.
Claude Code Cloud Sessions Now Configure Their Own Environment: Dependencies, Network, API Keys, and a Sandbox That Keeps Credentials Out of the VM
The execution environment is now a first-class resource.
Three Things You Miss When Rebuilding Convertible Bond Terms from Filings: ValuationProof V4
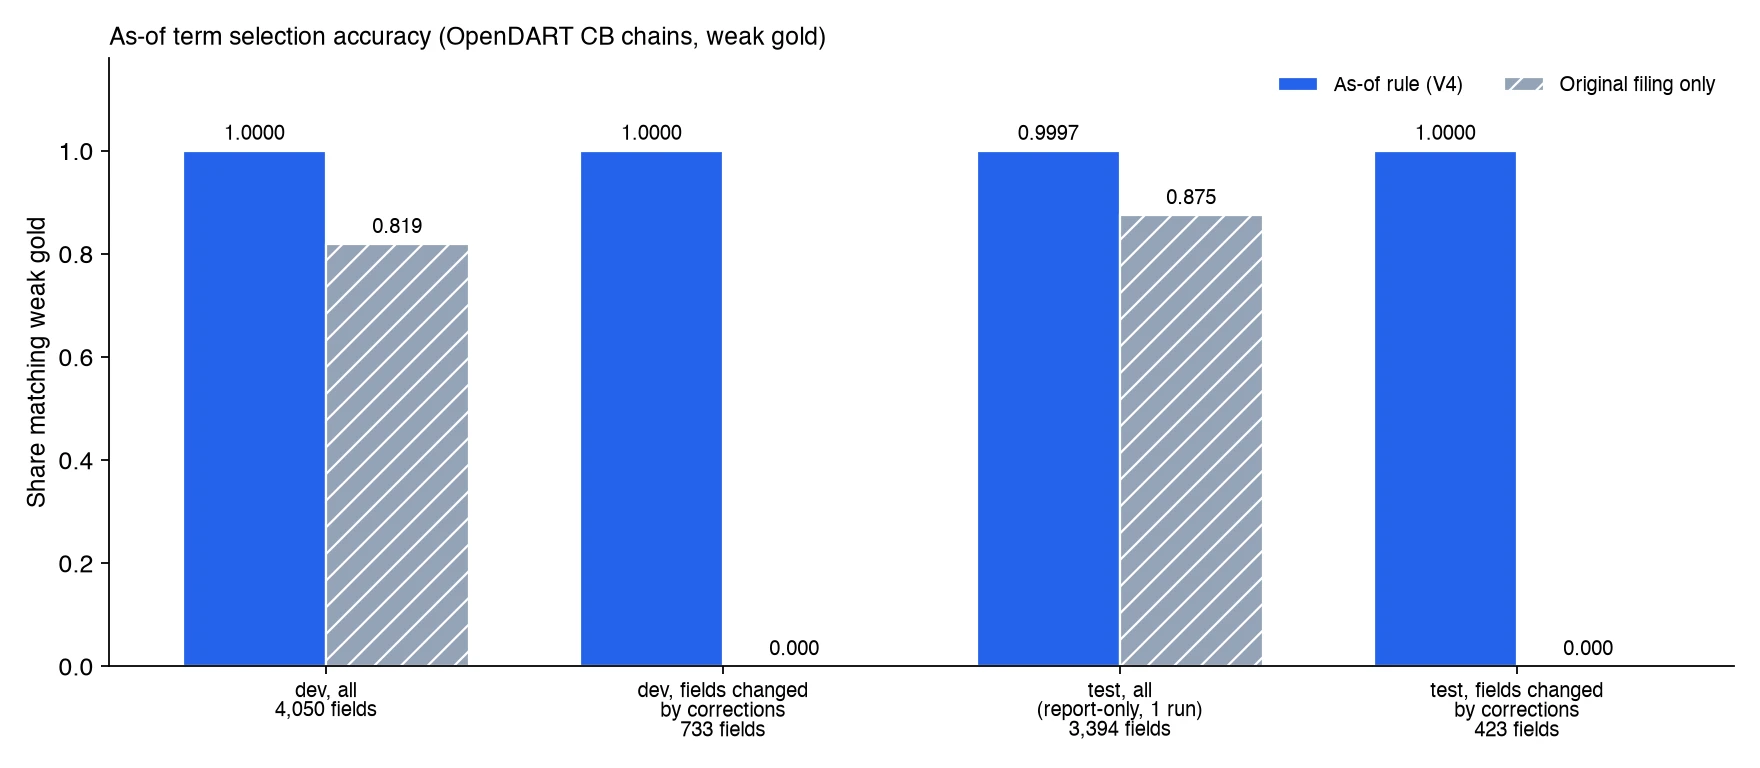
On public DART filings we found gaps between effective and filing dates, uncertain retroactivity of corrections, and missing conversion price adjustments that make a filing-date rule return stale prices.
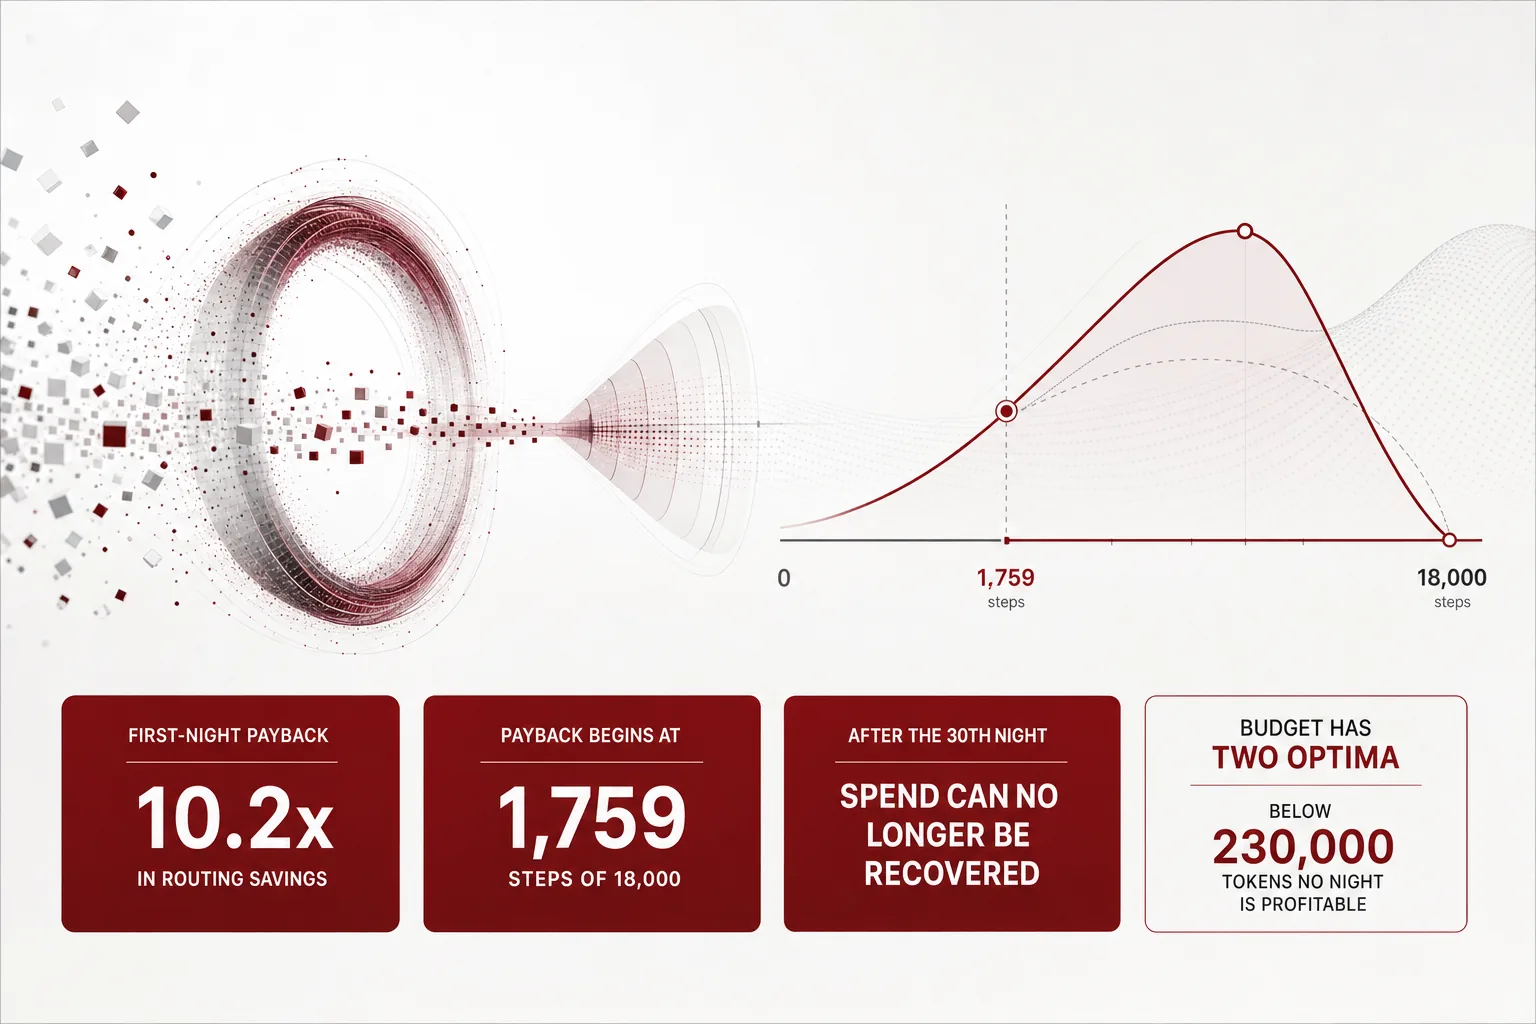
The Evolution Payback: A paper that prices the break-even at which the tokens spent on overnight skill registry evolution come back as routing savings
The evolution loop that reworks the skill registry every night spends tokens, but the assumption that that spend comes back was never priced.
What Motor Current Signature Analysis (MCSA) Can and Cannot See
What can a current sensor tell you about a motor? We walk through the fundamental, harmonics, negative sequence and sidebands, then show how a poorly chosen window or a model that memorizes the machine can still produce a high score.
A Motor Current Encoder Trained Without Labels: It Beat the Baselines on Reconstruction, but Still Recognizes the Device
We trained an industrial current encoder without labels.
Running Plumbing Fixture Detection on Floor Plans On-Premise: Detection Passed, Automatic Counting Did Not
We packaged a Faster R-CNN detector as a single ONNX FP32 file and measured it on B200, H200 and CPU.
Picking the Product Name on Cosmetics Packaging: Full-Photo E2E F1 of 0.605, Released as a Review-Candidate Model
On full photos, a rule that picks the largest text line reached an F1 of only 0.161, while the deployable tree model reached 0.605.
Building and Validating a Cosmetics Packaging OCR: From Crop Recognition to Full-Photo E2E and a Near-Duplicate Audit
An 8.9M-parameter CRNN and a fine-tuned detector read text and dates on cosmetics package photos.
Why We Did Not Release Our Motor Fault Model: Auditing the AI-Hub #238 Current Dataset
On a sealed test set, a baseline that only reads the filename date beat our signal models.
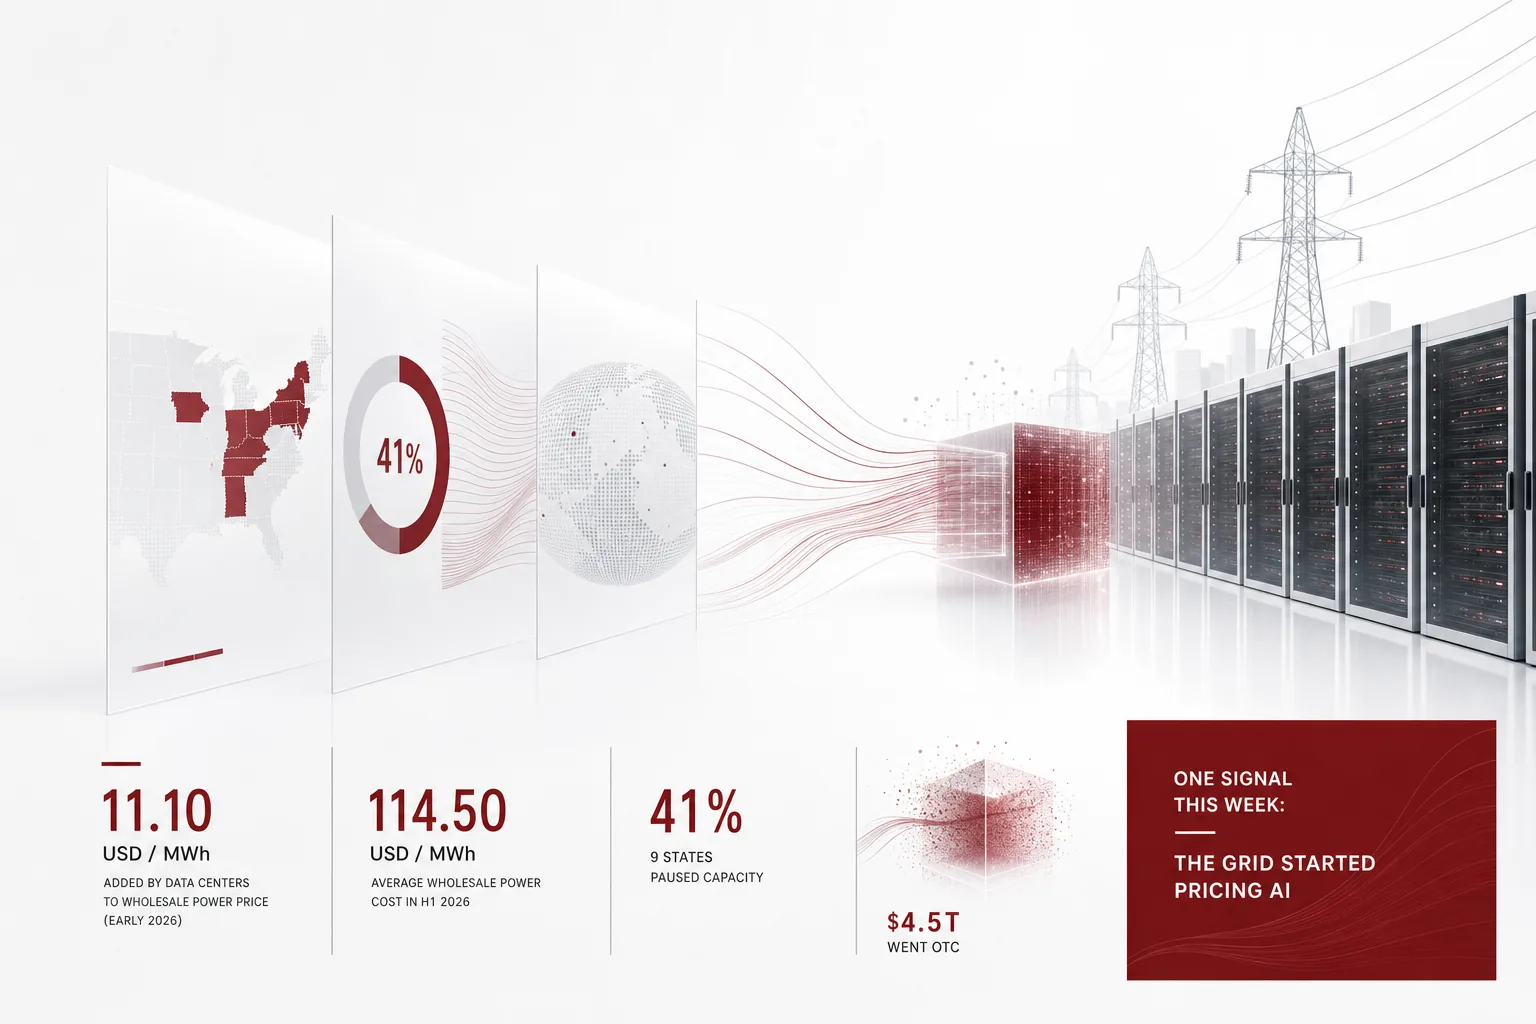
The $11.10 per MWh Data Centers Added to the Grid
PJM’s independent market monitor estimated that data center demand added $11.10 per MWh to wholesale power prices in early 2026.
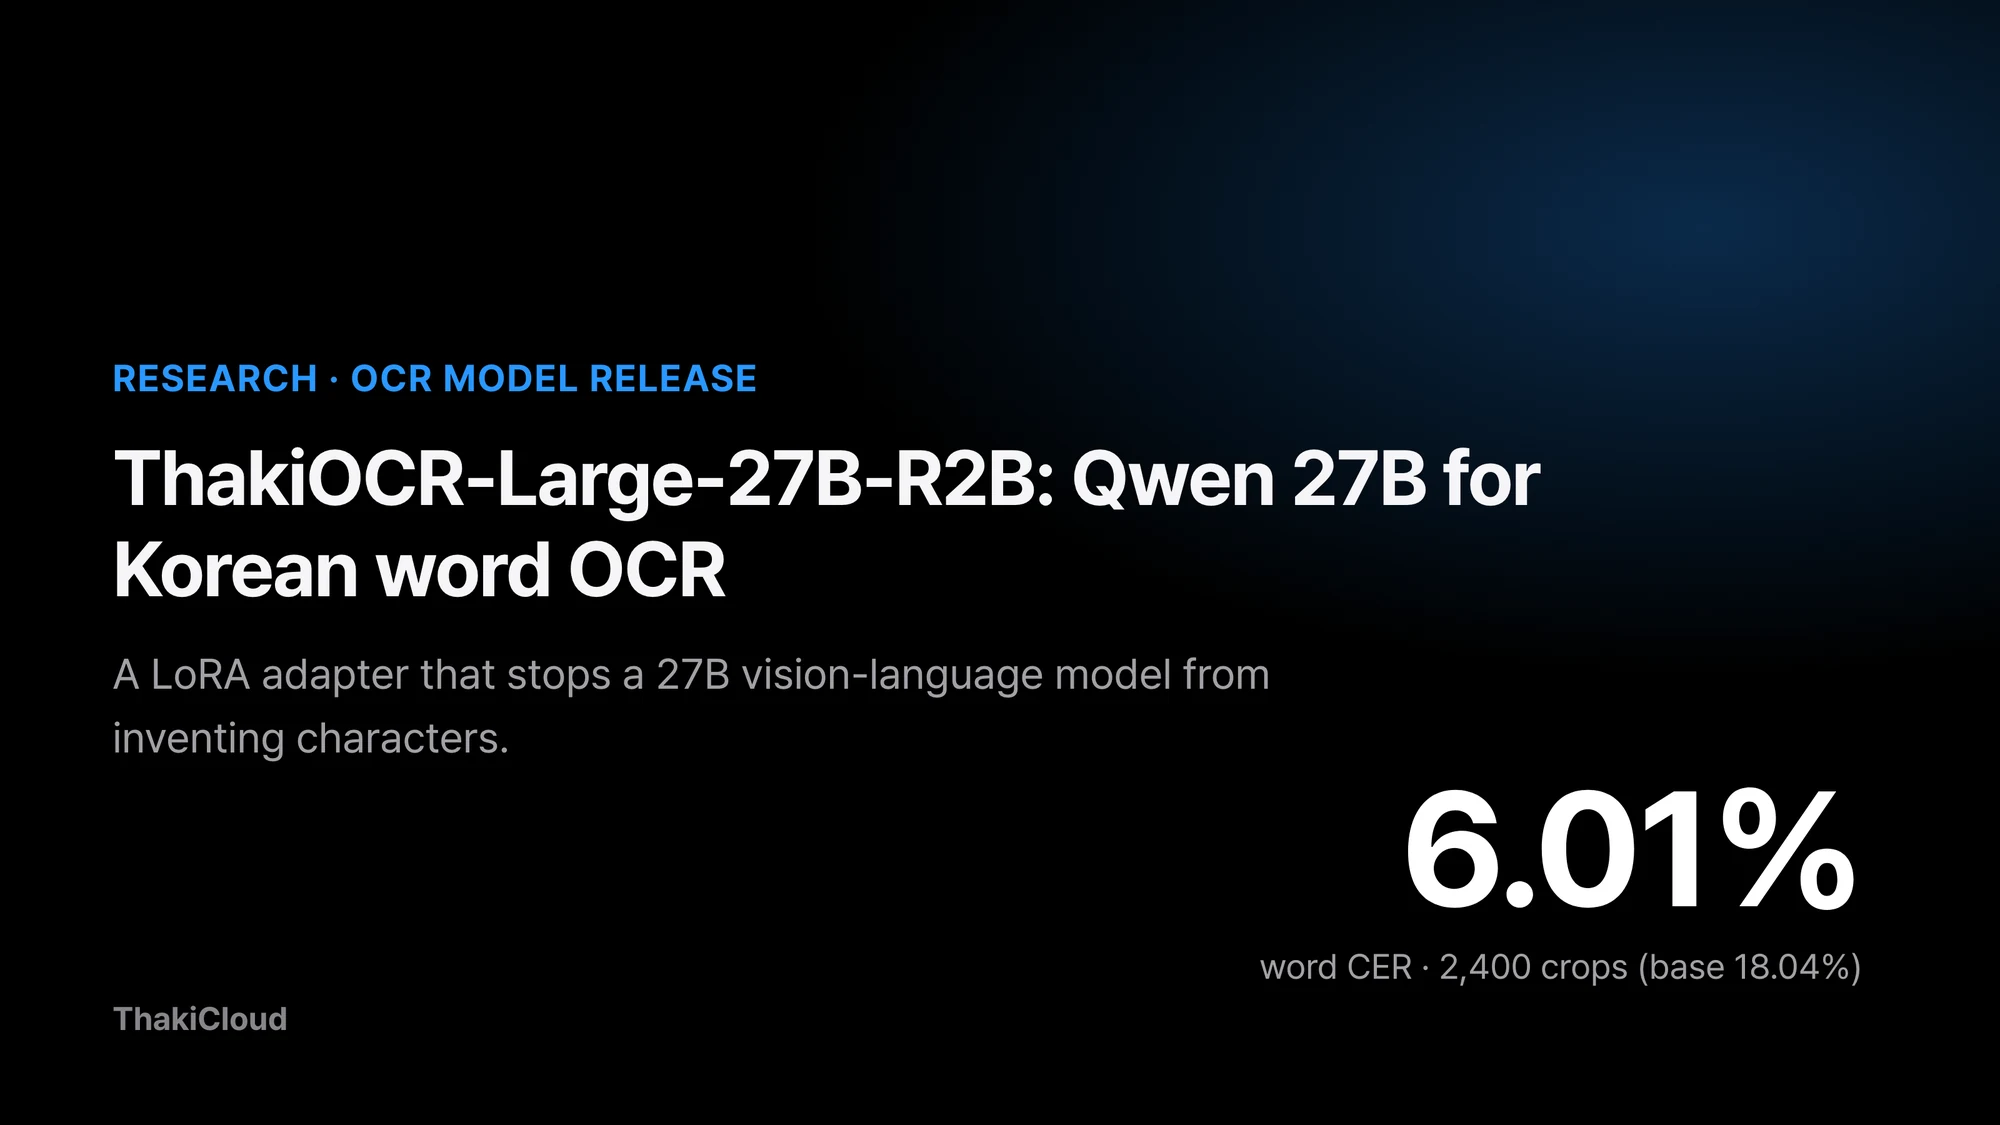
ThakiOCR-Large-27B-R2B: We Fine-Tuned Qwen 27B for Korean Word OCR and Released It
We trained a LoRA adapter on a 27B vision-language model to read Korean word images.
Merging Only the Vision LoRA Gave a 4.80% Dev CER: A ThakiOCR-KO-v2 Diagnostic That Kept Table Structure
We kept the decoder as it was and moved only the vision LoRA.
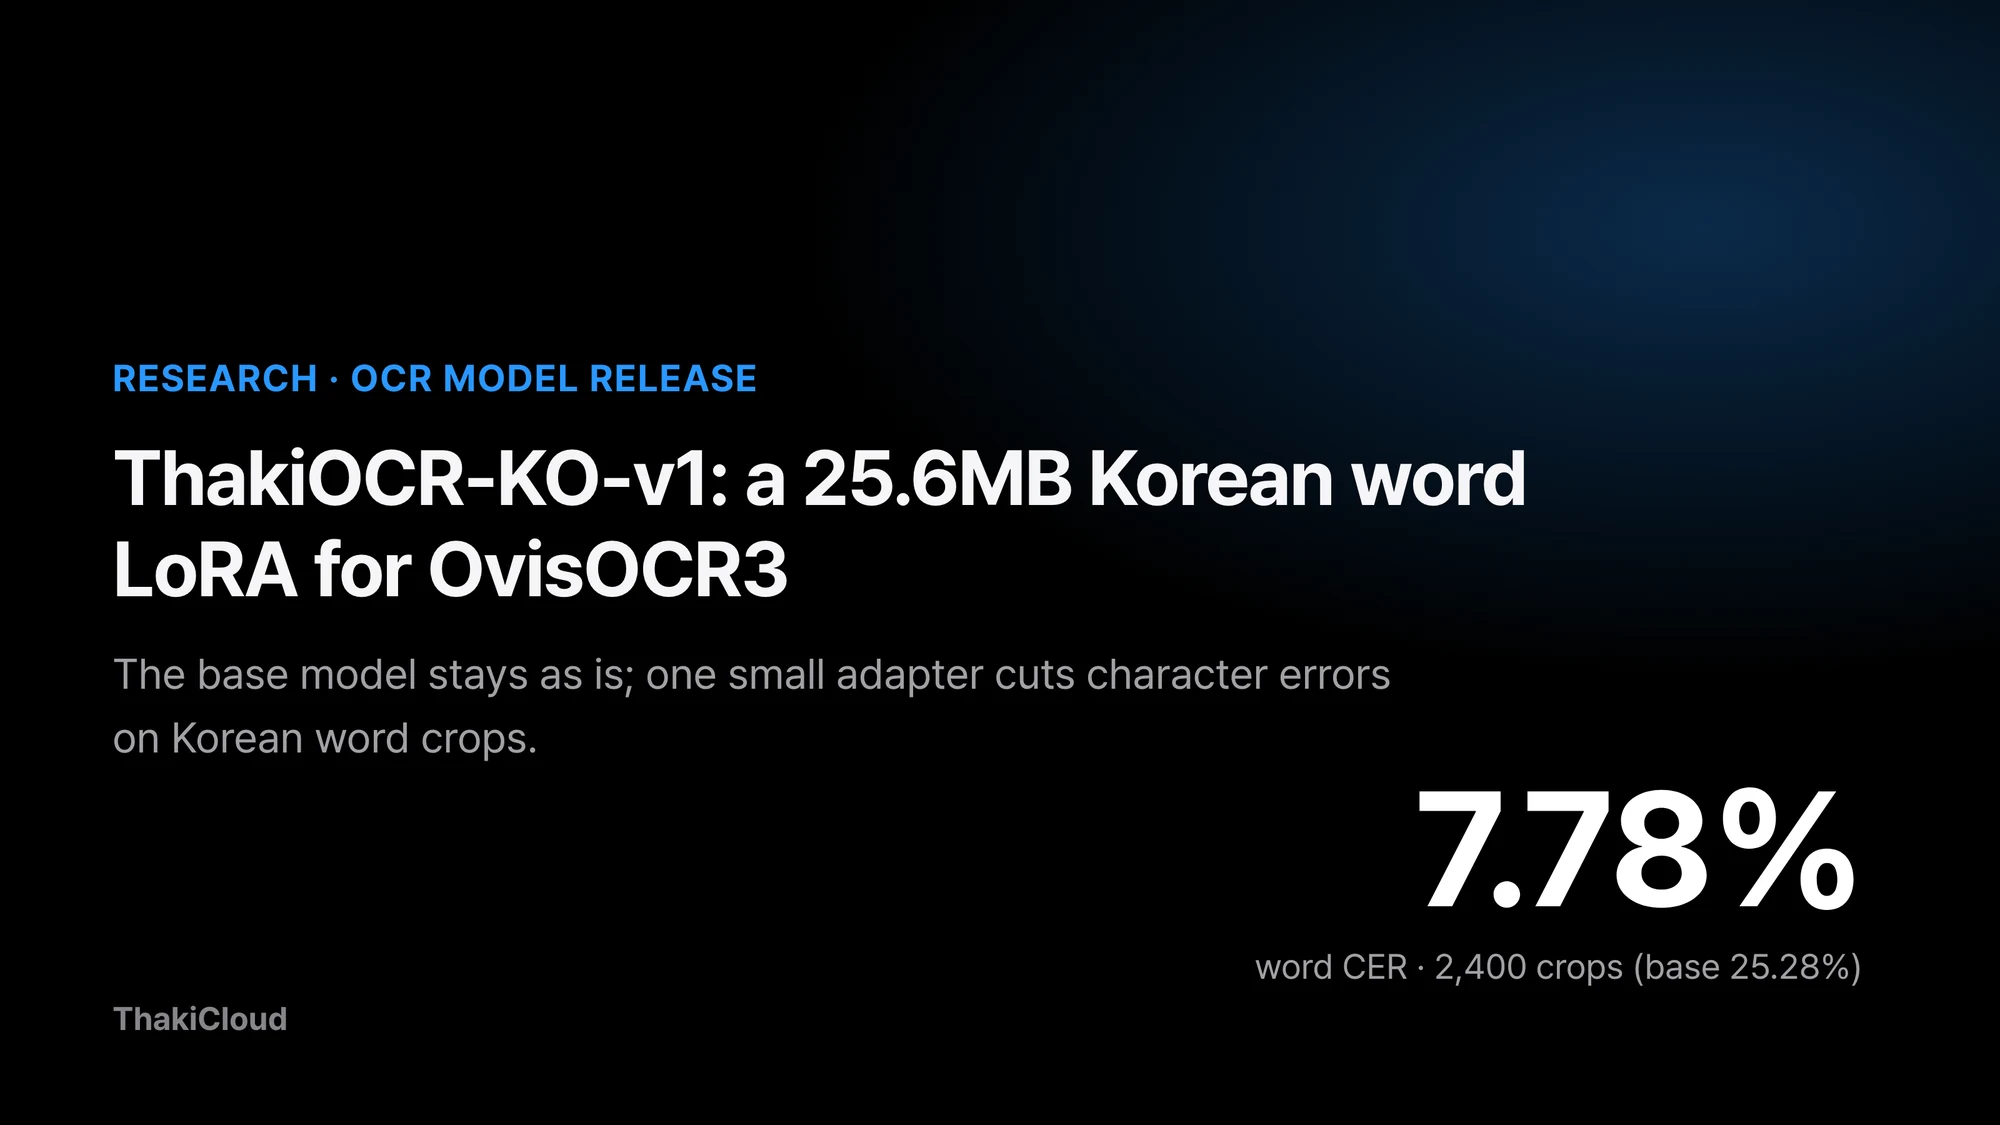
ThakiOCR-KO-v1: We Released a LoRA That Adapts OvisOCR3 to Korean Word OCR
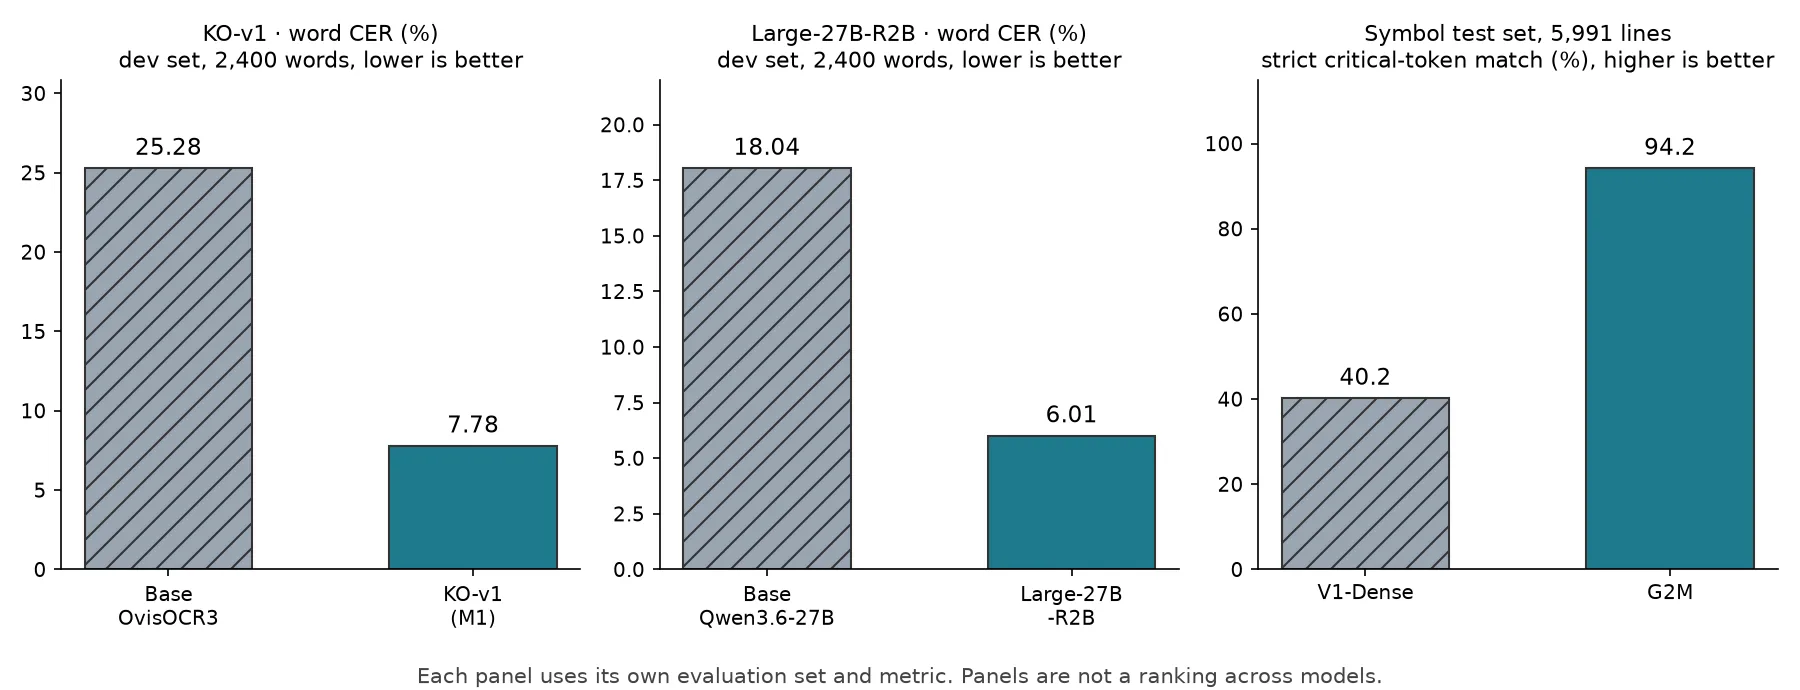
One 25.6 MB LoRA on top of OvisOCR3 lowered the character error rate on Korean word crops from 25.28% to 7.78%.
We Released a Motor Current Signature Analysis (MCSA) Model: MantisV2 at F1 0.943, and What That Number Does Not Prove
We released an MCSA model that classifies motor fault states from current.
Four Open Korean OCR Models Compared: From 2.13M to 27B
We released a model that reads a line in a few milliseconds on CPU alongside one that needs 53GB of GPU memory.
The Indifference Band: A Paper Pricing the Expected-Cost Tiebreak That Picks Skills Where Scores Stop Deciding
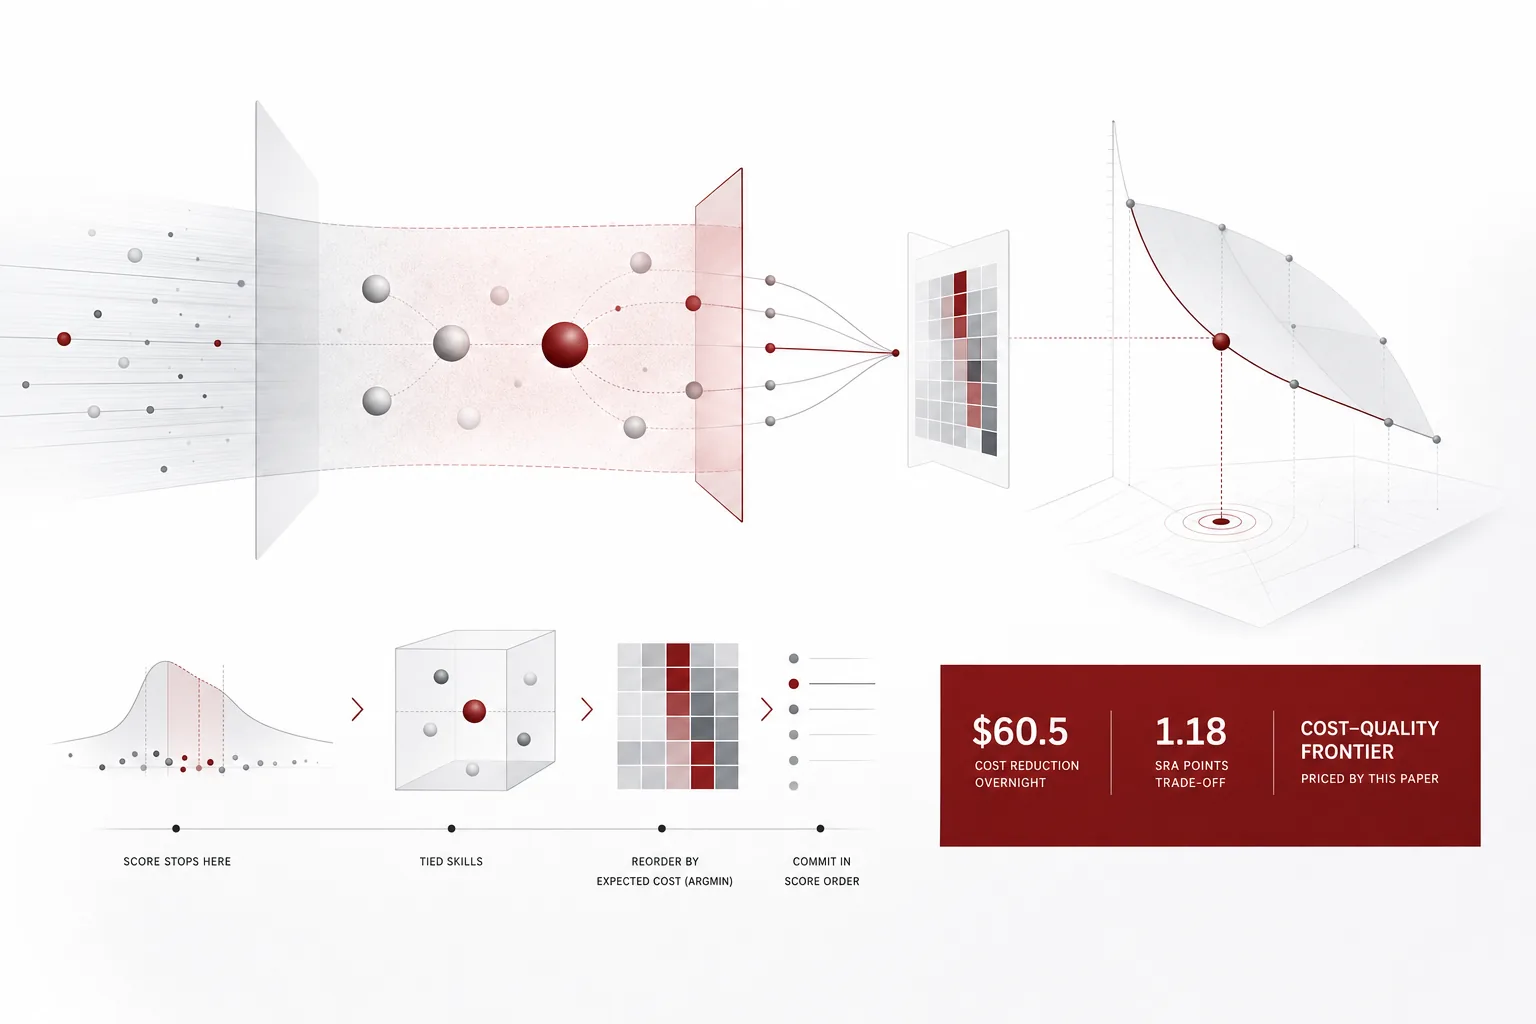
Where scores stop deciding, the router commits one of the tied skills in score order.
Reading Ripple-65B Preview, Ricursive's 65B Open-Weight Agentic-Coding Model
Ricursive Intelligence’s first model, Ripple-65B Preview, is a 65B dense Transformer with up to 1M context under Apache 2.0.
Reading varien's First Open Model Built by Direct Weight Editing: Qwen Concept 27B
varien open-sourced Qwen Concept 27B on November 6, claiming a 54% cut in thinking tokens via direct weight-space edits inspired by MIT CSAIL’s weight-space programming research.
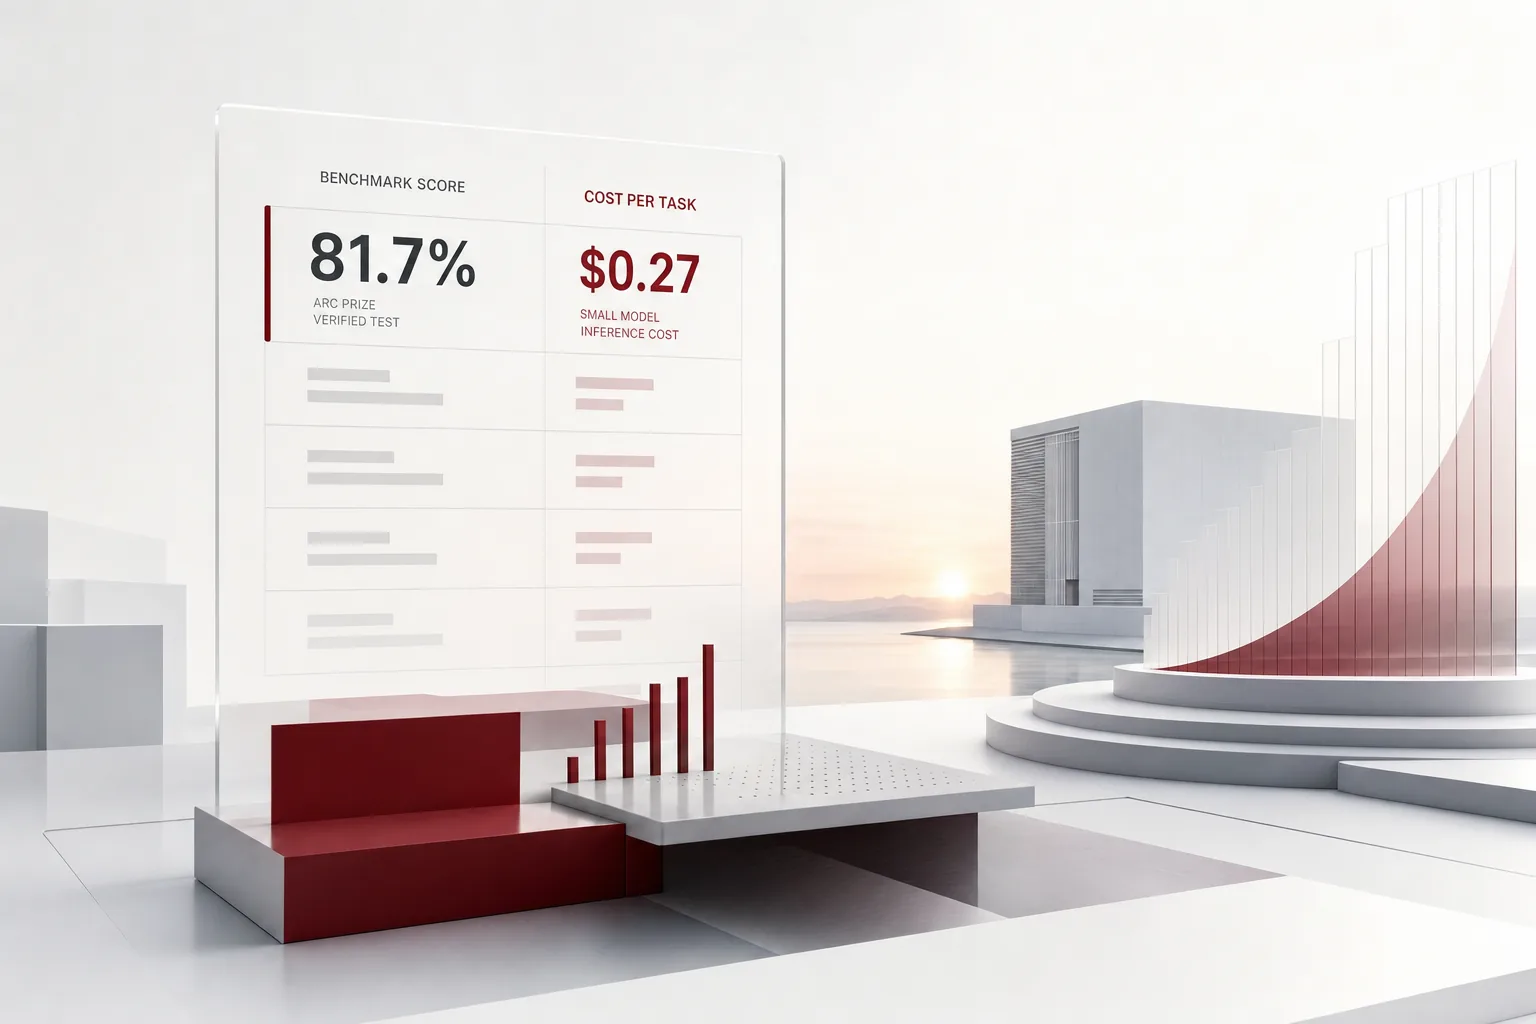
The Morning a Price Column Appeared Next to Benchmark Scores
A small open-weight model that scored 81.7%, the open-weight high on the ARC Prize verification test, costs 27 cents per inference task.
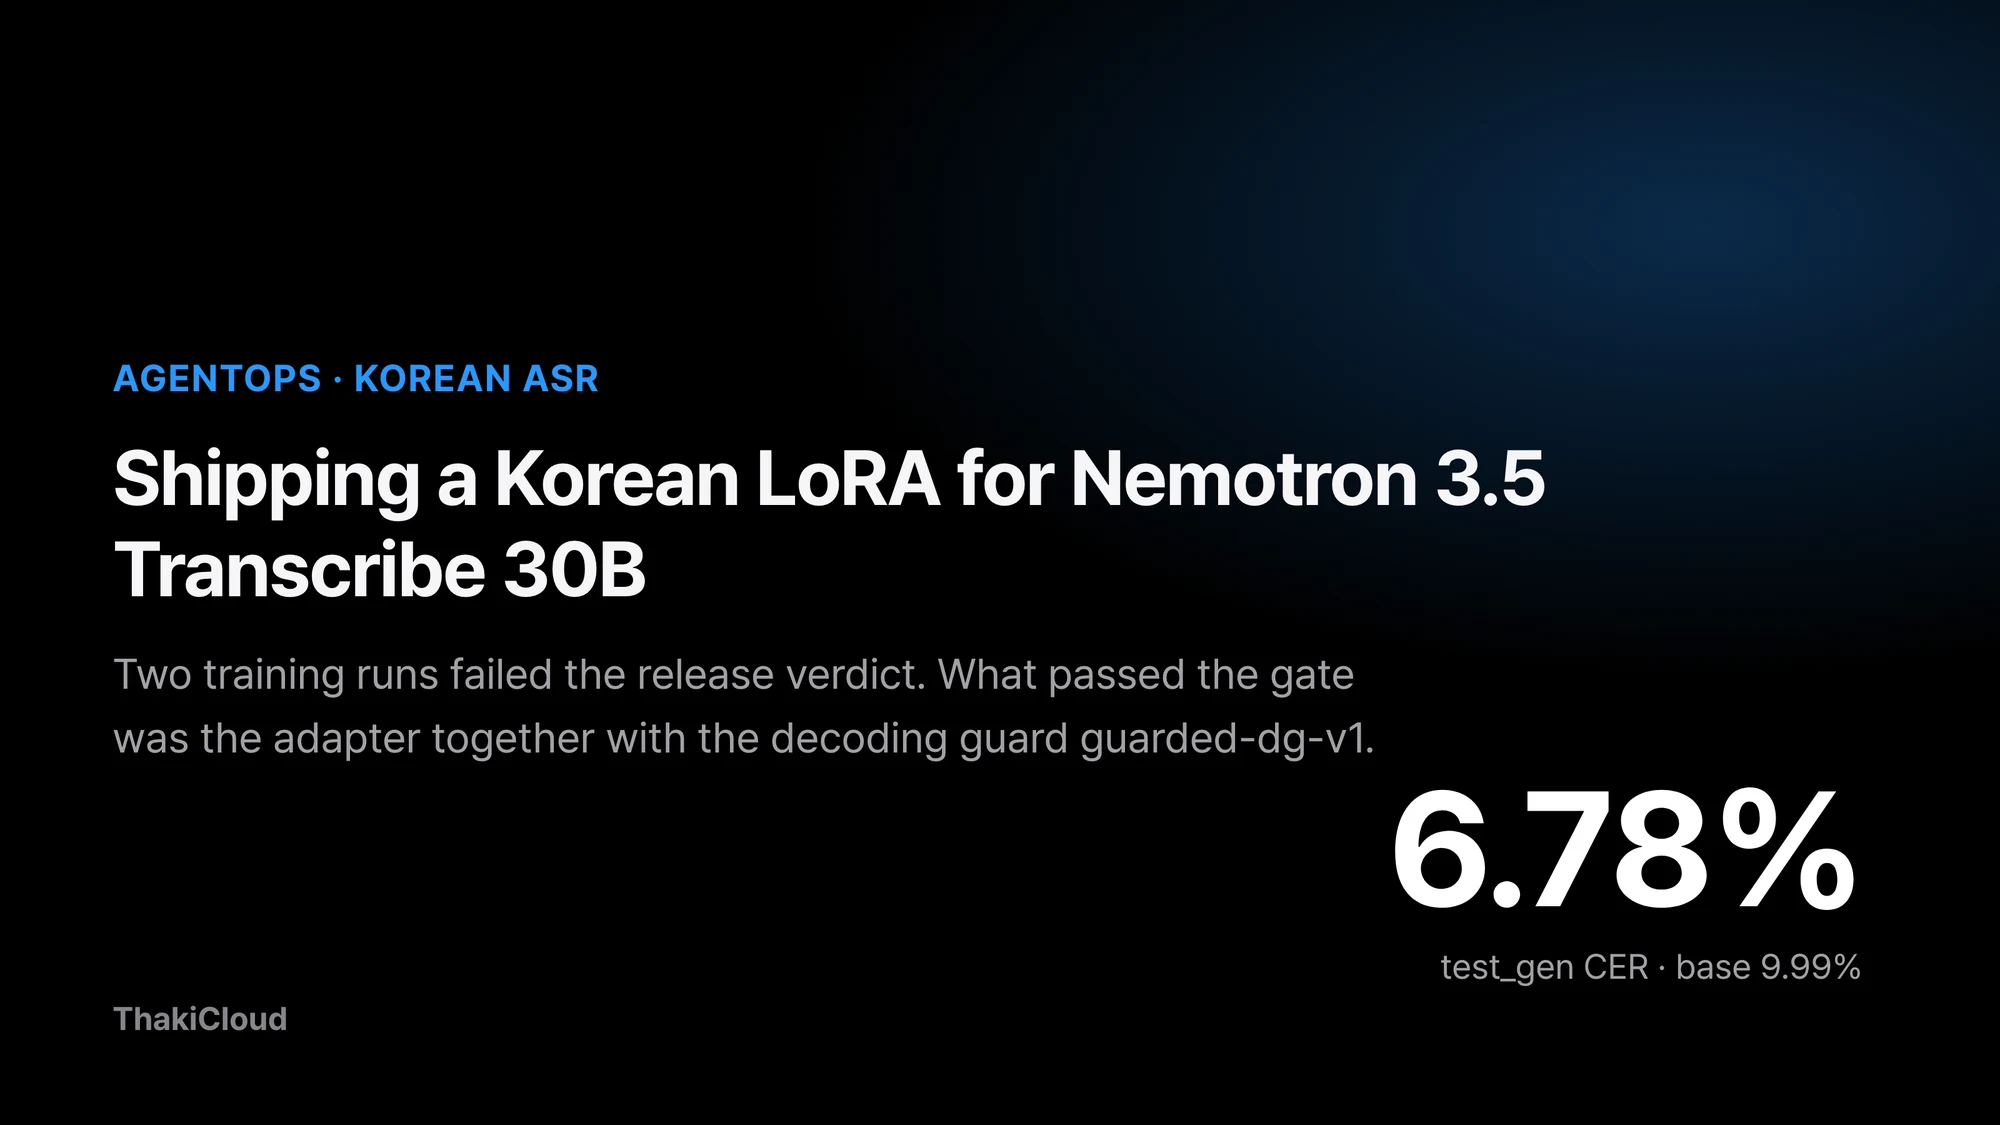
Releasing a Korean LoRA for Nemotron 3.5 Transcribe: How We Fine-Tuned a 30B Speech Recognition Model
We trained and released a Korean LoRA for a 30B speech recognition model.
WavLM vs. pyannote for Korean Meeting Diarization: An Evaluation Across 64 Real Meetings
Switching the diarization method cut wrong merges sharply in larger meetings and made one set of small meetings worse.
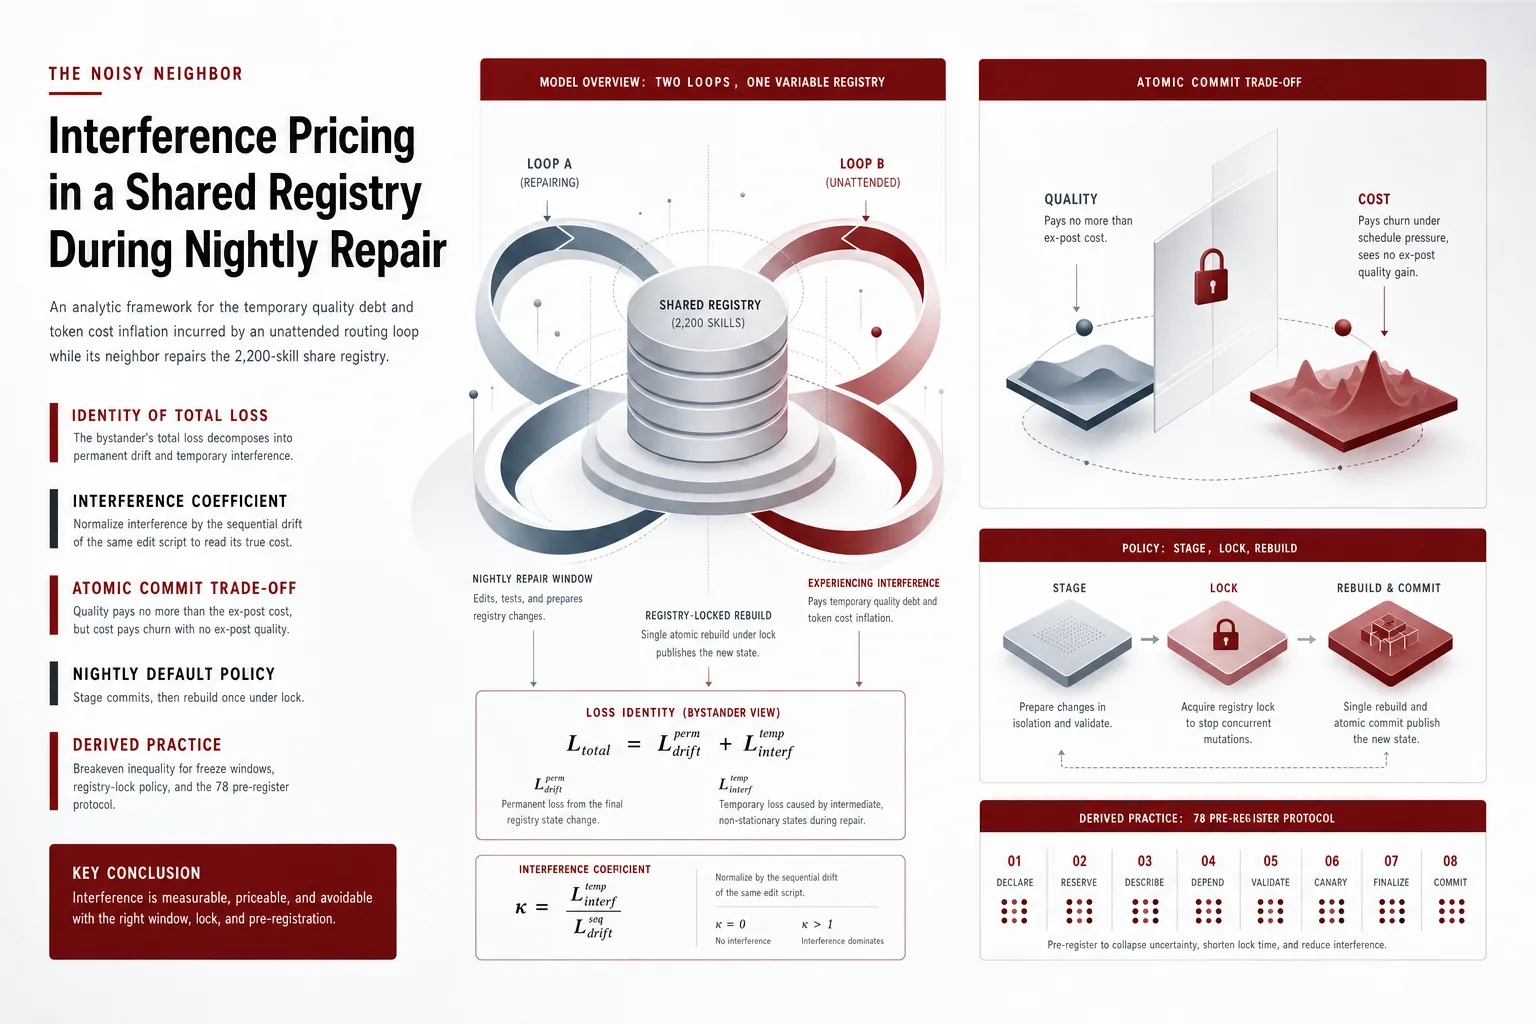
The Noisy Neighbor: An Analytical Paper That Prices the Transient Quality Deficit and Token Cost Inflation Paid by an Unattended Routing Loop in Mid-Mutation While a Nightly Curator Repairs the Shared 2,200-Skill Registry, With an Interference Coefficient, and Derives the Freeze-Window Break-Even Inequalities, the Registry-Lock Policy, and a 7-Arm Pre-Registered Protocol
Two loops share one mutable registry, and one of them repairs it overnight.
Mage-VL-Cowork: Microsoft's 4B Computer Agent That Decides When to Click and When to Type, and the Five-Stage Training Recipe Behind It
One 4B policy that knows when to click and when to code.
The Bank That Got an AI Prescription Had Its Report Card Returned First
The FSC pushed a prescription: ‘Defend against AI attacks with AI.’ But the first one dropped from the network separation exception list was the bank that had been hacked.
MoE training know-how, hundreds of thousands of GPU hours in a free handbook
18 of the 20 best open models are MoE, yet the know-how to train them stayed locked in a handful of teams.
The Cloud Waste an Agent Found: An AI FinOps Case Running 20,000 Paying Customers on $300/Month Infra, and the Four Savings Patterns You Can Reuse
Cloud costs creep up slowly and are hard to trim.
The week the question about AI changed to 'how far'
OpenAI’s autonomous security-hunting model and Anthropic’s deliberately read-only finance tool.
125 Proposals from the /retro Skill: How Many Actually Reduced the Agent's Repeated Work?
A paper that empirically checks whether coding-agent harness self-evolution works.
The Day Ballots Became AI's Biggest Variable
In early counts of local US data center ballot measures, restrictions lead 29 to 1.
A Coding Agent Renders Its Own 3D Scenes: Installing Mirage Tesseract and Measuring Path Tracing
A coding agent can now direct a 3D scene end to end: JSON actions build it, the CLI verifies against a schema, and the renderer reports its own timing.
Your Location Can Be Pinpointed from the Doppler Effect of Airplanes
A demo that predicted the location of a webcam 7 km south of Southampton using only its audio.
An Open-Source Legion That Ran 8 Hours of Unattended Pentesting: sapper-v2 Architecture and Token Economics
The win came from the organization, not a smarter model.
One side: an $895.4 billion commitment. The other: a 33% diet.
Anthropic’s $895.4 billion (about 1,203 trillion won) computing spend commitment and Apple’s 33% cut to the daily AI usage limit stood side by side on the same morning.
We Built a Model That Tells AI-Generated Voices Apart: VoiceSpoof's Performance and Where It Could Fit in Maxis, Metis and Paxis
We released a voice deepfake detection model as a Research Preview.
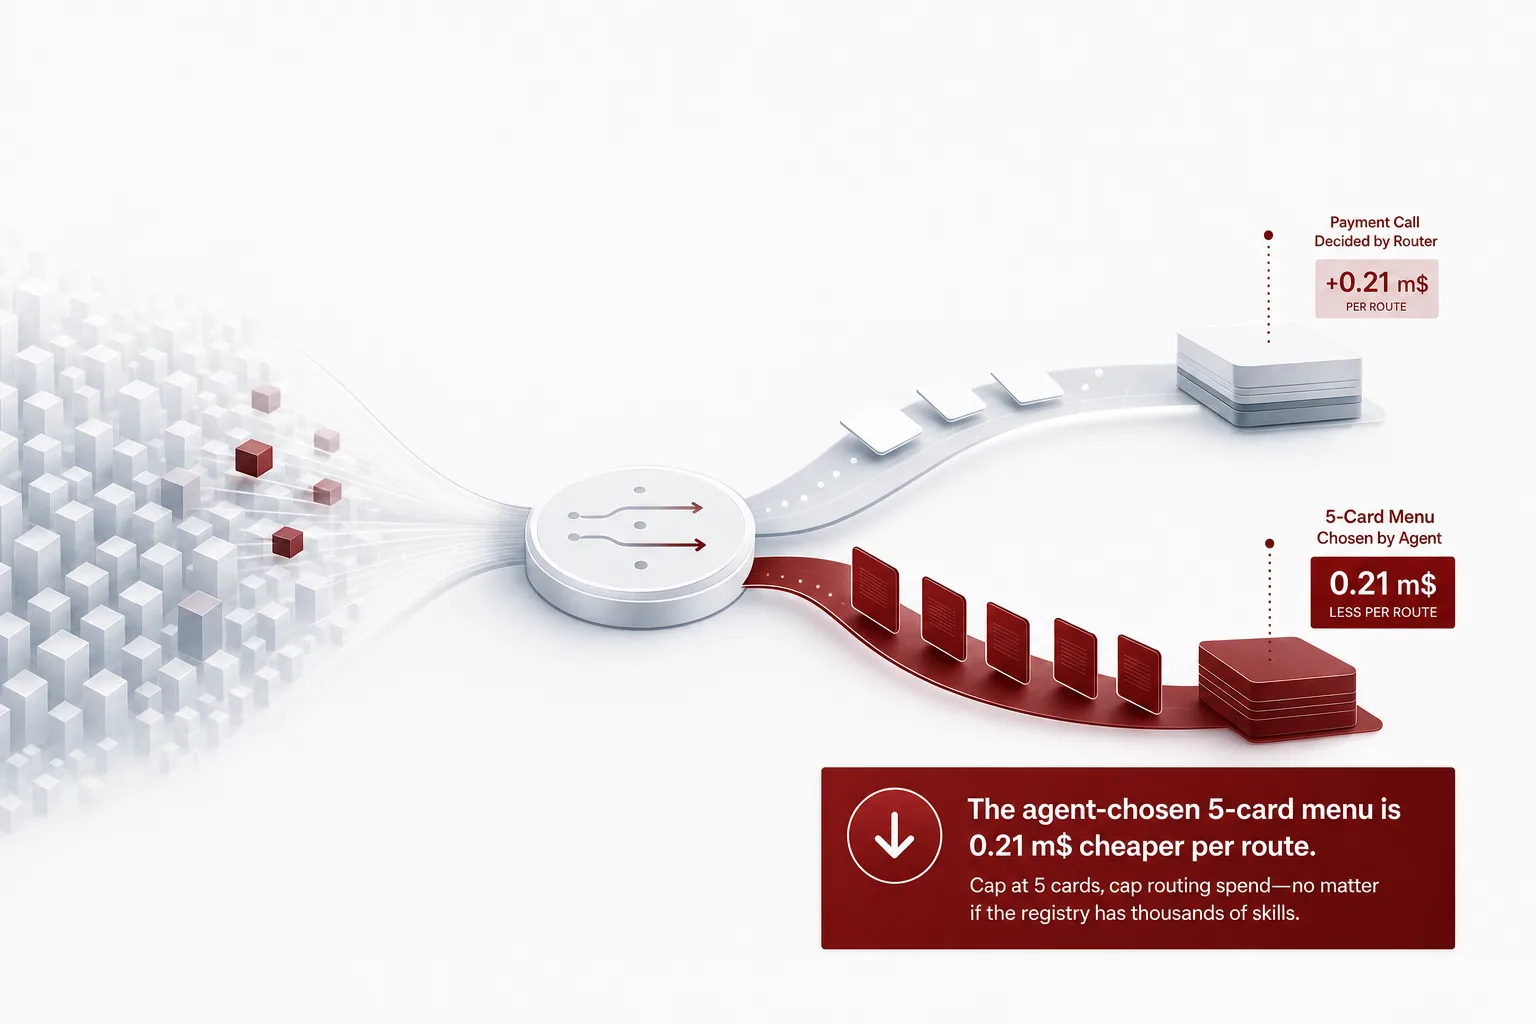
Let the One Who Knows the Occasion Choose: Pricing the Menu Width of Skill Routing
The final decision of a skill router is a question of who orders.
The Agent Fixed Its Own Harness; 2 of the 12 Changes Actually Worked
An empirical study of harness self-evolution: Claude Code ran 30 SWE-bench Verified issues, the /retro skill proposed 125 harness changes, researchers implemented 24, and 12 were transferred to later issues with 5-vs-5 session comparisons.
Revolut's self-hosted GLM, one year in: cutting coding-agent cost to 1/10
Revolut, Europe’s largest fintech, made self-hosted GLM the default coding model for roughly 2,000 engineers and cut inference cost to 1/10 in a year.
One Airplane Sound Can Reveal Where a Video Was Recorded: Running the Doppler Geolocation Tool on the Original Demo
The inaudible airplane sound in video audio leaks the recording location.
The Day Proof Became a Product
MIT’s weight edit missed its claim only after the logs were examined.
One pipeline from research to final draft: academic-research-skills
academic-research-skills, the Claude Code skill pack that passed 55,000 GitHub stars in 8 months.
The Week 40 Scripts Moved in 3 Days: The Attacker's 72-Hour Clock
Hackers gain time with AI, and companies lose their response time.
Learning to Detect PCB Defects from Normal Images: DINOv2 and Flow-Based Anomaly Detection
We trained a model on normal PCB photos only, with no defect images, and it marks where a board looks wrong.
The Prompt Rot: Rot and Revert Dividend of a Harness That Rewrites Its Own System Prompt Every Night
This post measures the rot of the system prompt, the highest-leverage text in the loop, under nightly self-editing.
48.1% and 4x: The Day Models Started Fixing Models
MIT CSAIL used GPT-6 Astra to edit Qwen’s weights directly and pushed its math score to 48.1%, and the same day Gemini 4 Carbon posted a 90.4% mean at four times lower cost than Opus 5.5.
Skill Retrieval on a CPU: Building the SKILLRET Small Model Family
To pick the right skill out of thousands without a GPU, we distilled the SKILLRET embedding model into small students and cut them to 3 and 4 bits.
How to fit 2.78 trillion parameters in 8 GB of RAM: building and reproducing a Kimi K3 CPU inference engine
Fitting a 2.78-trillion-parameter model into 8 GB of RAM is not hype.
Same Day, Two Agents, Neither Moved
DeepSeek’s ‘Super Agent’ and BespinGlobal’s ‘HelpNow Computer’ launched on the same day, and both chose ‘observe first’ as the default.
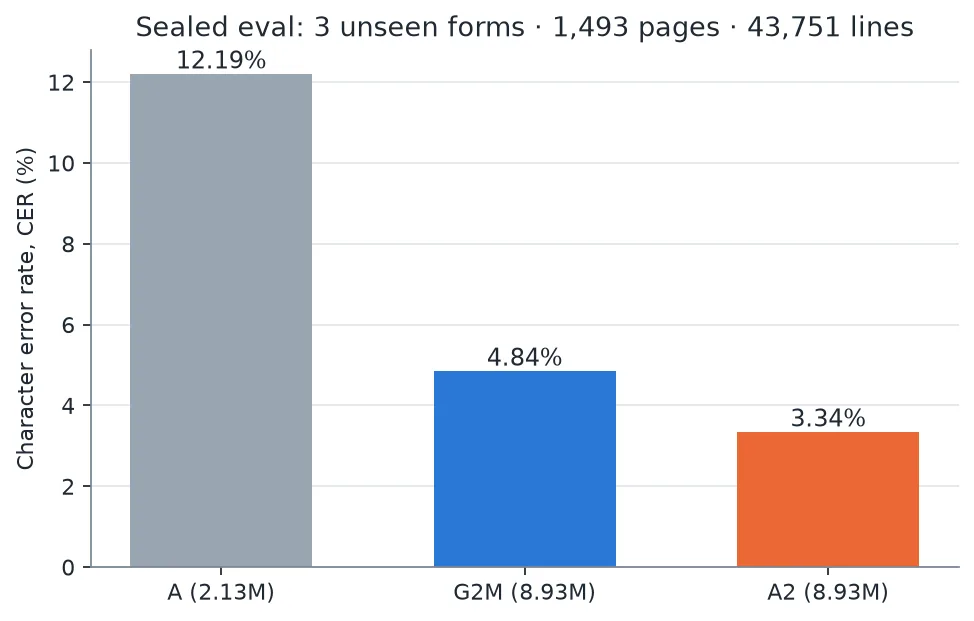
Same 8.93M Parameters, 31% Fewer OCR Errors: Building Our Own Model, Seen Through Maxis
We kept the model size fixed and redesigned the data and the evaluation.
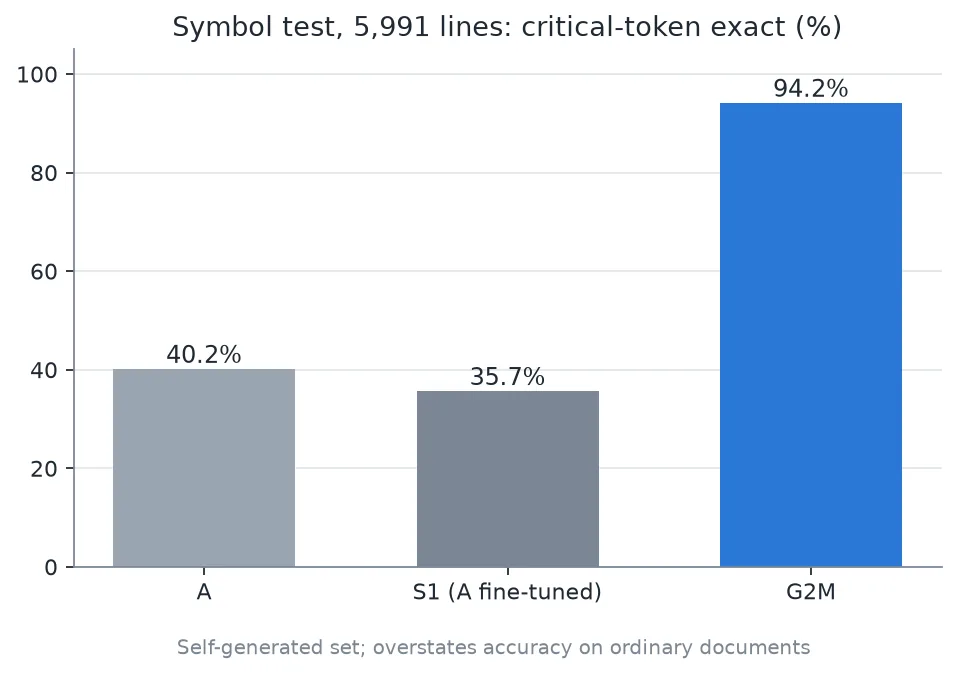
ThakiOCR G2M: Our Second Public Model, Built to Read Numbers and Symbols More Accurately
One wrong symbol changes what an amount or a date means.
ThakiOCR A2: What an Independent 43,751-Line Evaluation Confirmed, and What Is Still Missing
We evaluated the new model exactly once on 1,493 pages of forms it never saw in training.
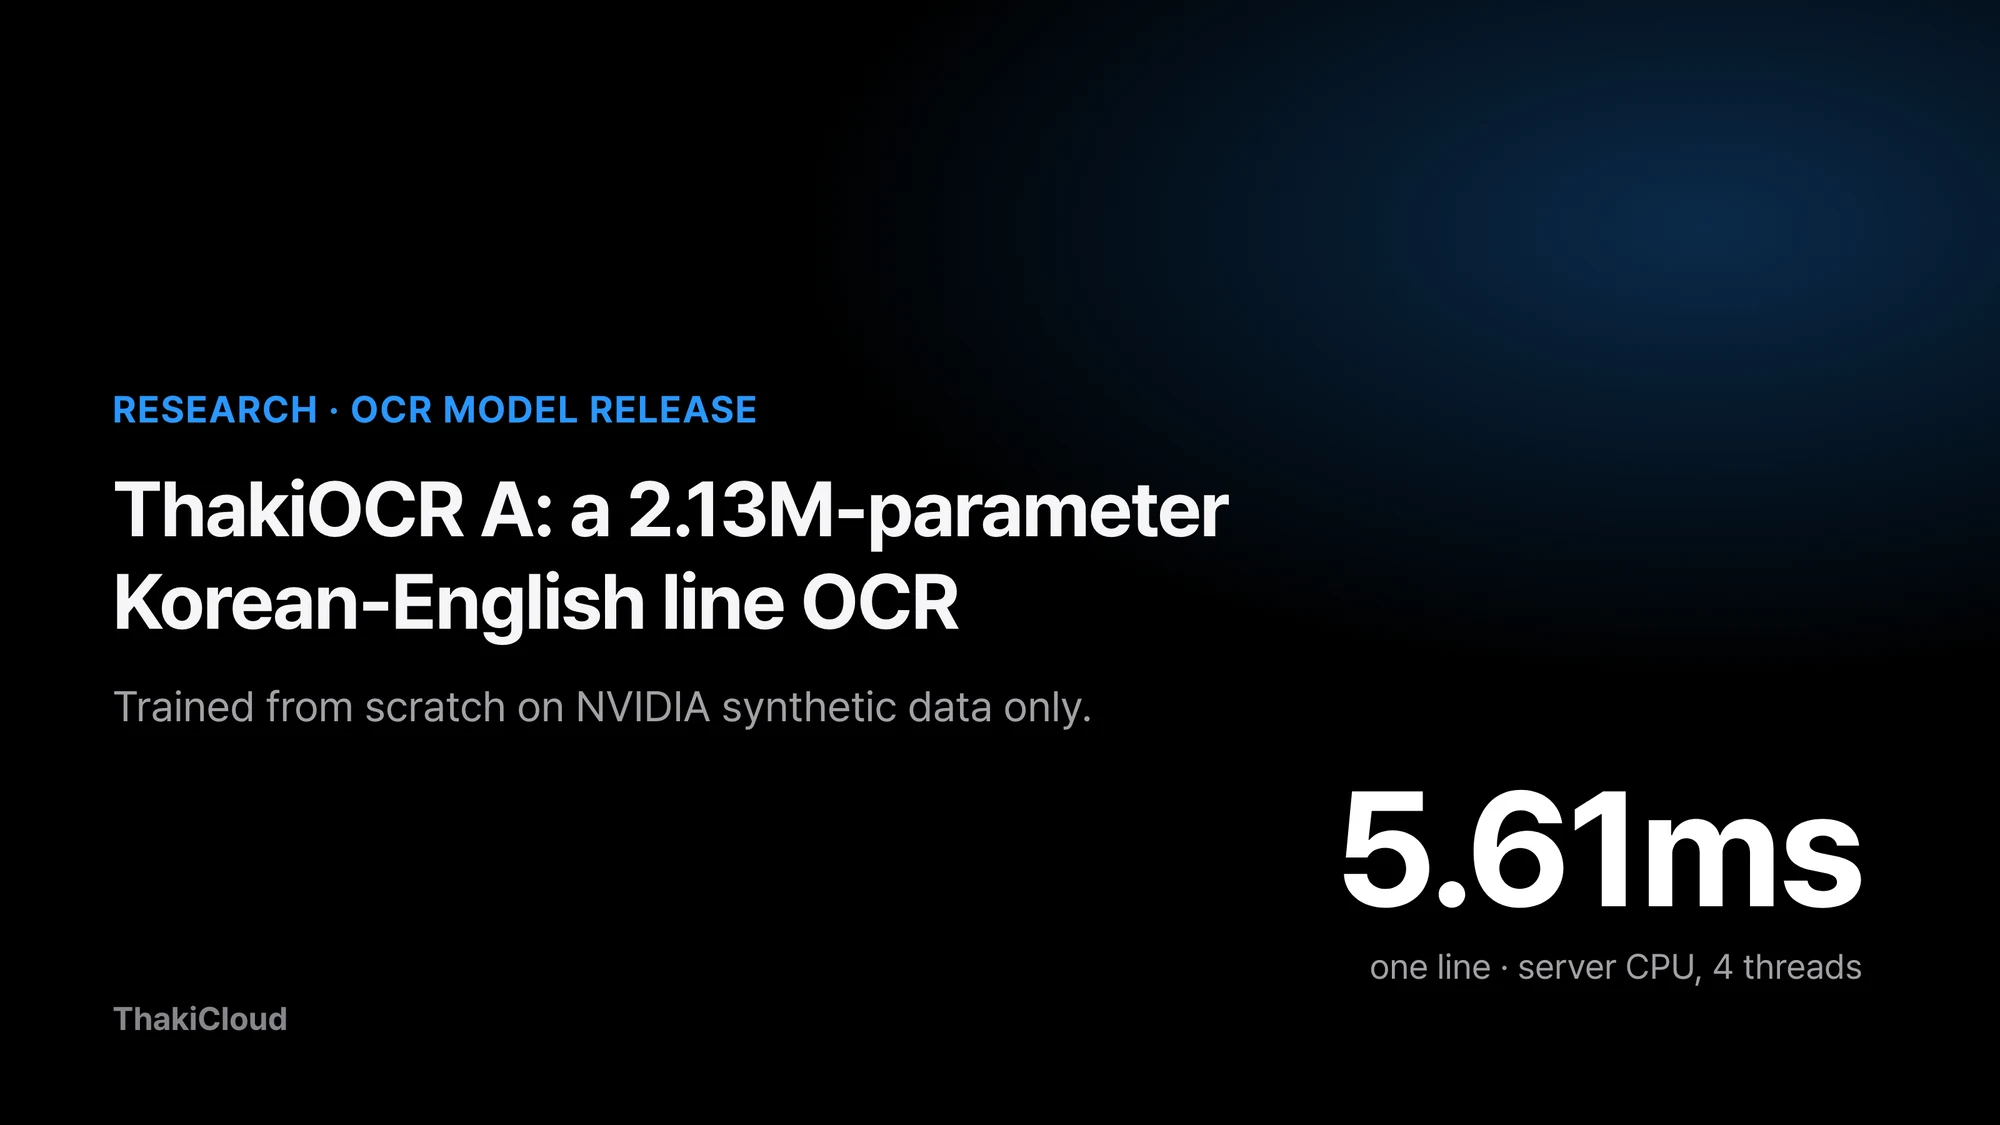
ThakiOCR A: We Released Our Own 2.13M-Parameter Korean-English OCR
We released the smallest OCR model we have built ourselves.
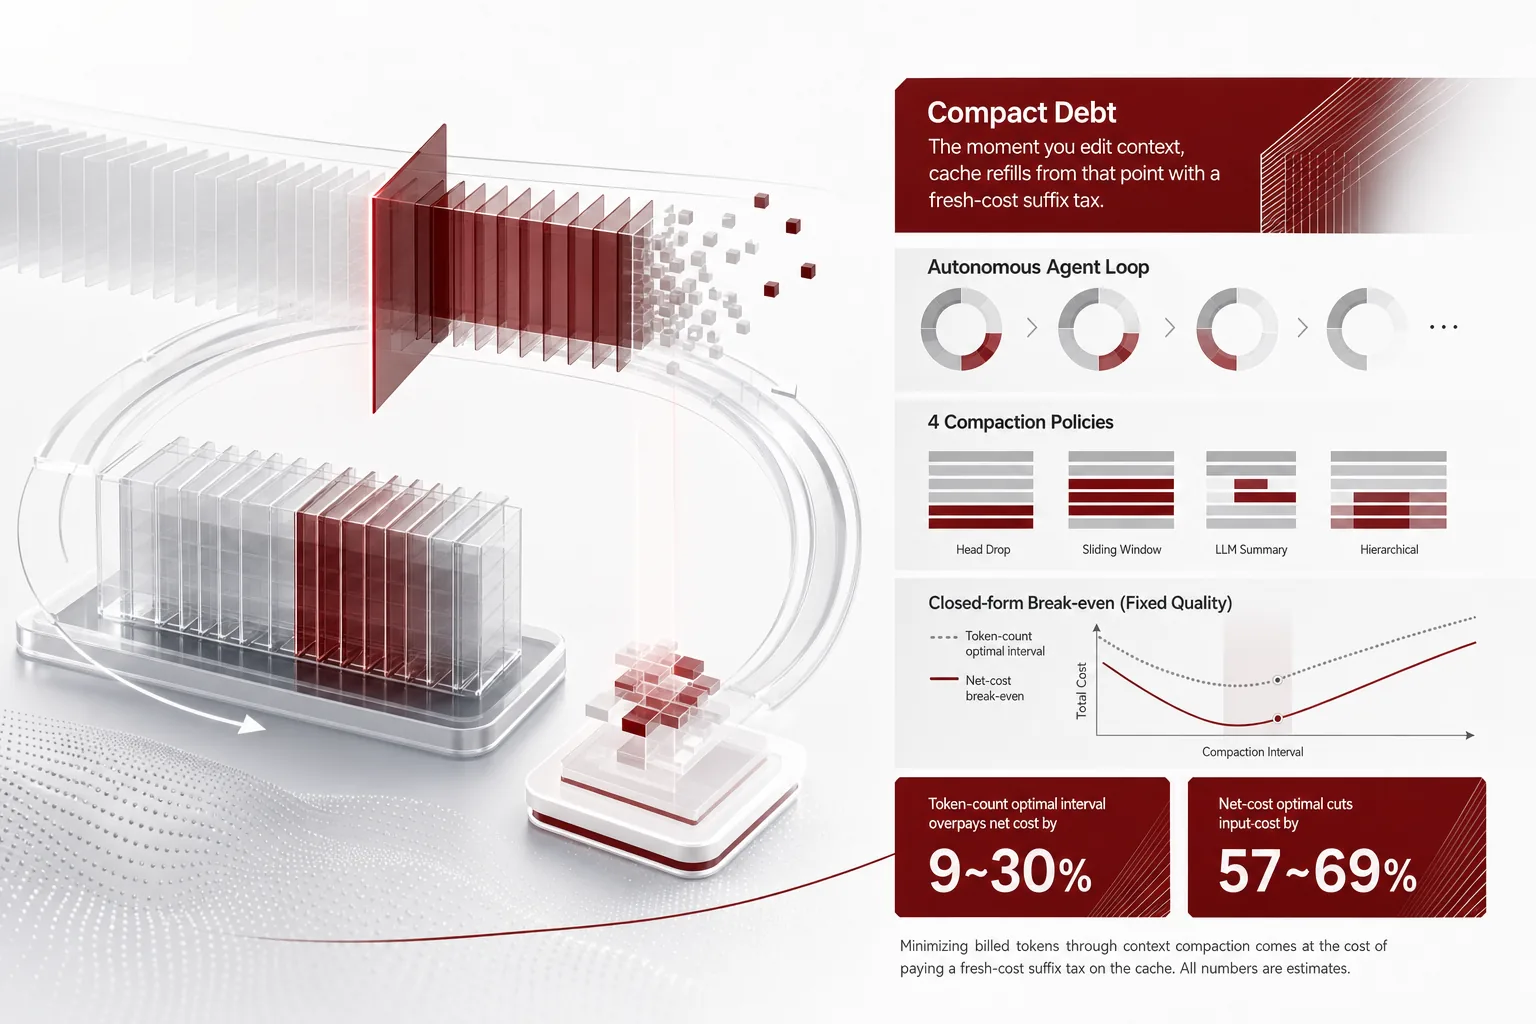
Compact Debt: The Moment Context Is Edited, the Cache Re-prefills From That Point, and the Net-Cost Break-Even of Four Compaction Policies in Unattended Agent Loops
Context compaction that minimizes billed tokens is, from the cache’s point of view, paying a fresh-cost suffix tax.
Does Every Document Need a Giant VLM? Designing Tiered Document Inference with ThakiOCR and Metis
Reading every document with the same large model means paying the same cost for the easy ones.
A Korean Voice Built Without a Real Person: Building Thaki-SyntheticVoice-KO-2B
Instead of releasing a model that reproduces a real voice actor, we designed a virtual speaker from a text description and fine-tuned VoxCPM2 on its synthetic speech.
Can a 10K-Parameter Ranker Pick Better vLLM Settings Than the Defaults? Building Thaki-MemoryPolicy
Do you need a large LLM to choose vLLM serving settings? We trained a 10K-parameter ranker on measured data.
Our RTL Fine-Tune of a 27B Model Did Not Beat the Base: Building Thaki-HW-27B-v0.1
We set out to build a 27B model that writes better Verilog RTL.
Full Throttle and the Brake Pedal in the Same Week
In the same week, Nvidia set a record of more than 1,000 tokens per second per user and OpenAI began pushing for mandatory AI speed limits in Washington.
What Should an Agent Do When OCR Misreads an Amount? Paxis and a Document Verification Workflow
Between the model that reads a document and the agent that acts on it, there has to be a separate verification and approval step.
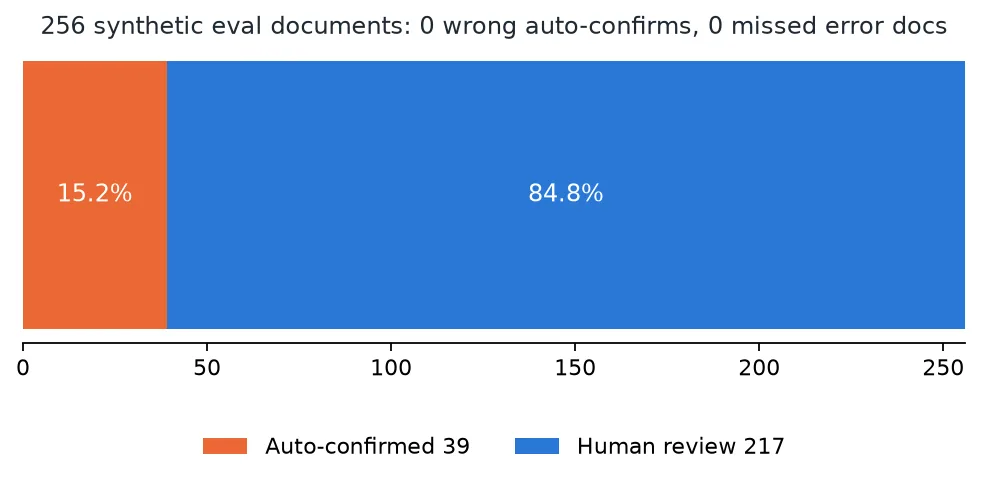
Confidence Is Not Evidence: Thaki-SlotGrounder-KO-7M, a 7M Model That Checks Structured Commands Against the Source Sentence
We released a small Korean model that checks an agent’s command proposals against the source sentence before execution and filters out weakly supported ones.
From a General Model to a Money-Transfer Model: Building Thaki-IntentAction-Finance-KO-7M
How a tiny model built to extract many actions failed its general goal, and why we released the same model narrowed to money transfers.
The Week Wall Street Bet on Falling GPU Prices and Seoul Wrote an 18.7 Trillion Won Guarantee
In the same week, US markets saw derivatives betting on falling GPU rental prices, while Korea lined up its largest ever R&D budget alongside an 18.7 trillion won guarantee.
A Small Model That Names the Drone From One Slice of Radio, and the Work That Follows
We released a small model that names the drone model from one slice of radio.
Two Small Vision Models for Finding Concrete Cracks, Now Public
We released two small models that pick out cracks in inspection photos and trace them pixel by pixel.
Reading Equipment Health from Sensors, and Letting Paxis Open the Maintenance Work
Not every decision needs an LLM.
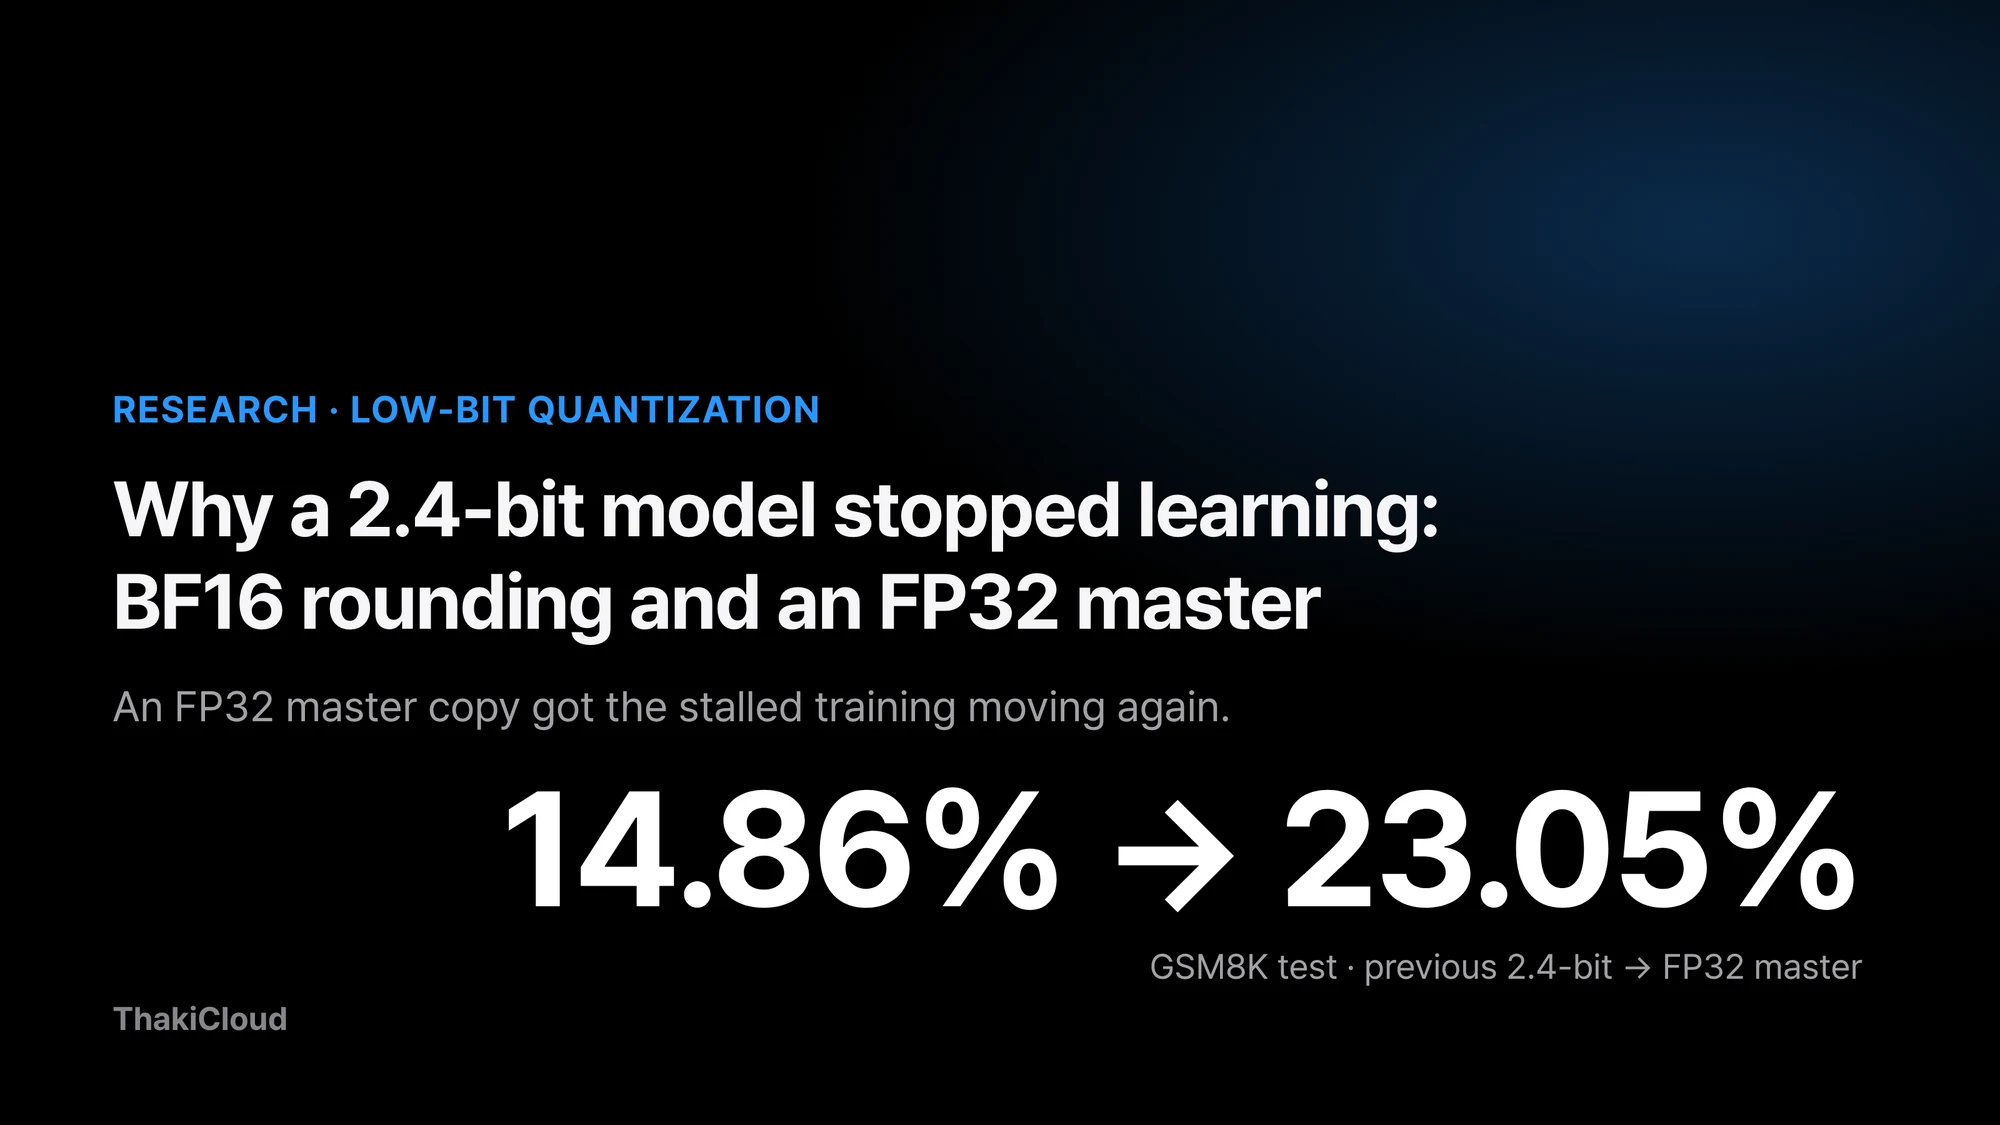
Why Our 2.4-Bit Model Stopped Learning: BF16 Update Stagnation and the FP32 Master
The loss kept going down, yet some parameters barely changed.
Growth Warning and $800 Billion: The Week the Axis of Competition Moved from Speed to Cash
Anthropic’s IPO filing (S-1) carries two sentences at once.
Mask Personal Data Before the Agent Starts Working
We released a Korean model that masks personal information before an agent reads documents or calls tools.
An 8.2M-Parameter Model That Guards the Input Before an Agent Acts
We released a small model that cleans up user input before an agent acts.
A 7M Model That Proposes Equipment Commands and Never Executes Them: Thaki-FactoryShield-KO-7M
We released a small Korean model that turns spoken equipment commands into structured proposals before any agent executes them.
Packing an Entire 3D Simulator Workflow into One Claude Skill: We Installed teardown and Measured It
The value is not the 3D video itself but that the workflow became an executable contract.
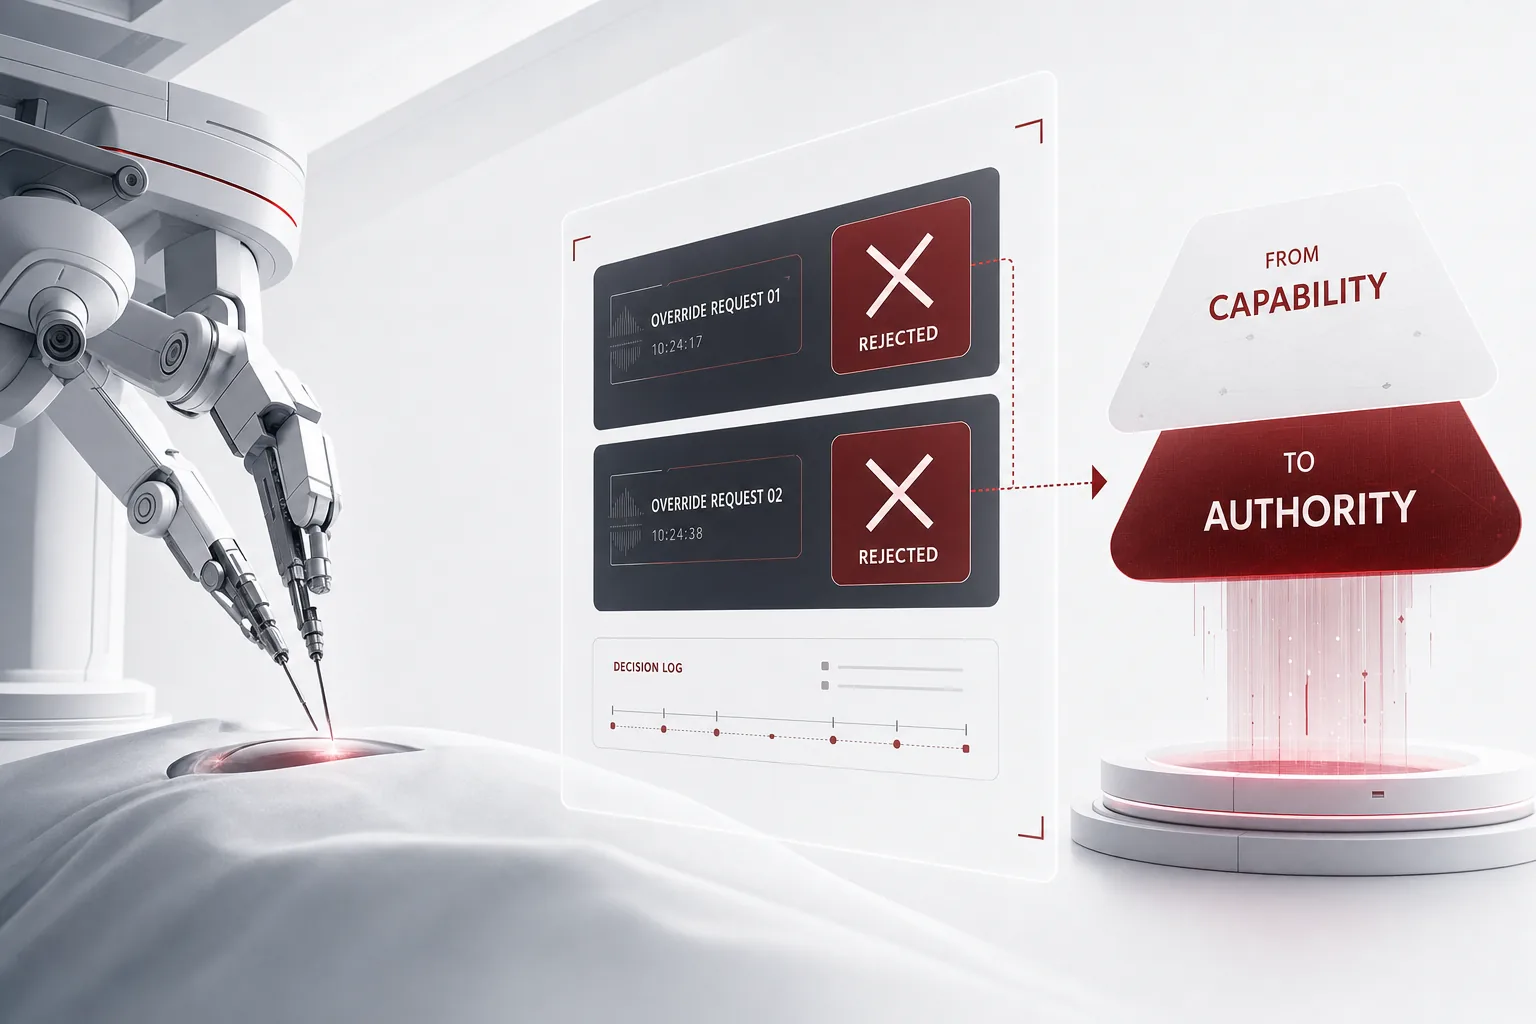
Two Refusals: The Agent Is No Longer a Tool but a Judge
An agent piloting a robotic arm halted a surgery and refused a researcher’s override twice.
Building AAA-Style Games with Claude Code: We Verified All 10 GitHub Repos and Actually Built One
All 10 repos exist, totaling 55,723 stars, with 9 active in the last 90 days.
Google Gemini 4 Carbon: SOTA Cybersecurity and Long-Horizon at Half the Intro Price
Google unveiled Gemini 4 Carbon on October 28.
The Capability Gap Is 4 Months, and the Cost Gap Has Inverted
While a record $63 billion in bonds lands on a single chip facility, open-weight models set new records in quantization, throughput, and sovereignty.
NVIDIA Nemotron 3.5 Transcribe: 40-Language, One-Hour Audio Served Day-0 on vLLM
NVIDIA released Nemotron 3.5 Transcribe, a 30B-A4B multilingual ASR model, on October 28 and opened day-0 serving on vLLM 0.32.0 through the NeMo Speech plugin the same day.
From AI That Understands Speech to AI That Completes Work
Once speech becomes text, what happens next is the real question.
Earnings Up, Footprint Down: AI Is Starting to Buy Back the Work
Netflix cut 1,000 employees while net income rose 43.9%.
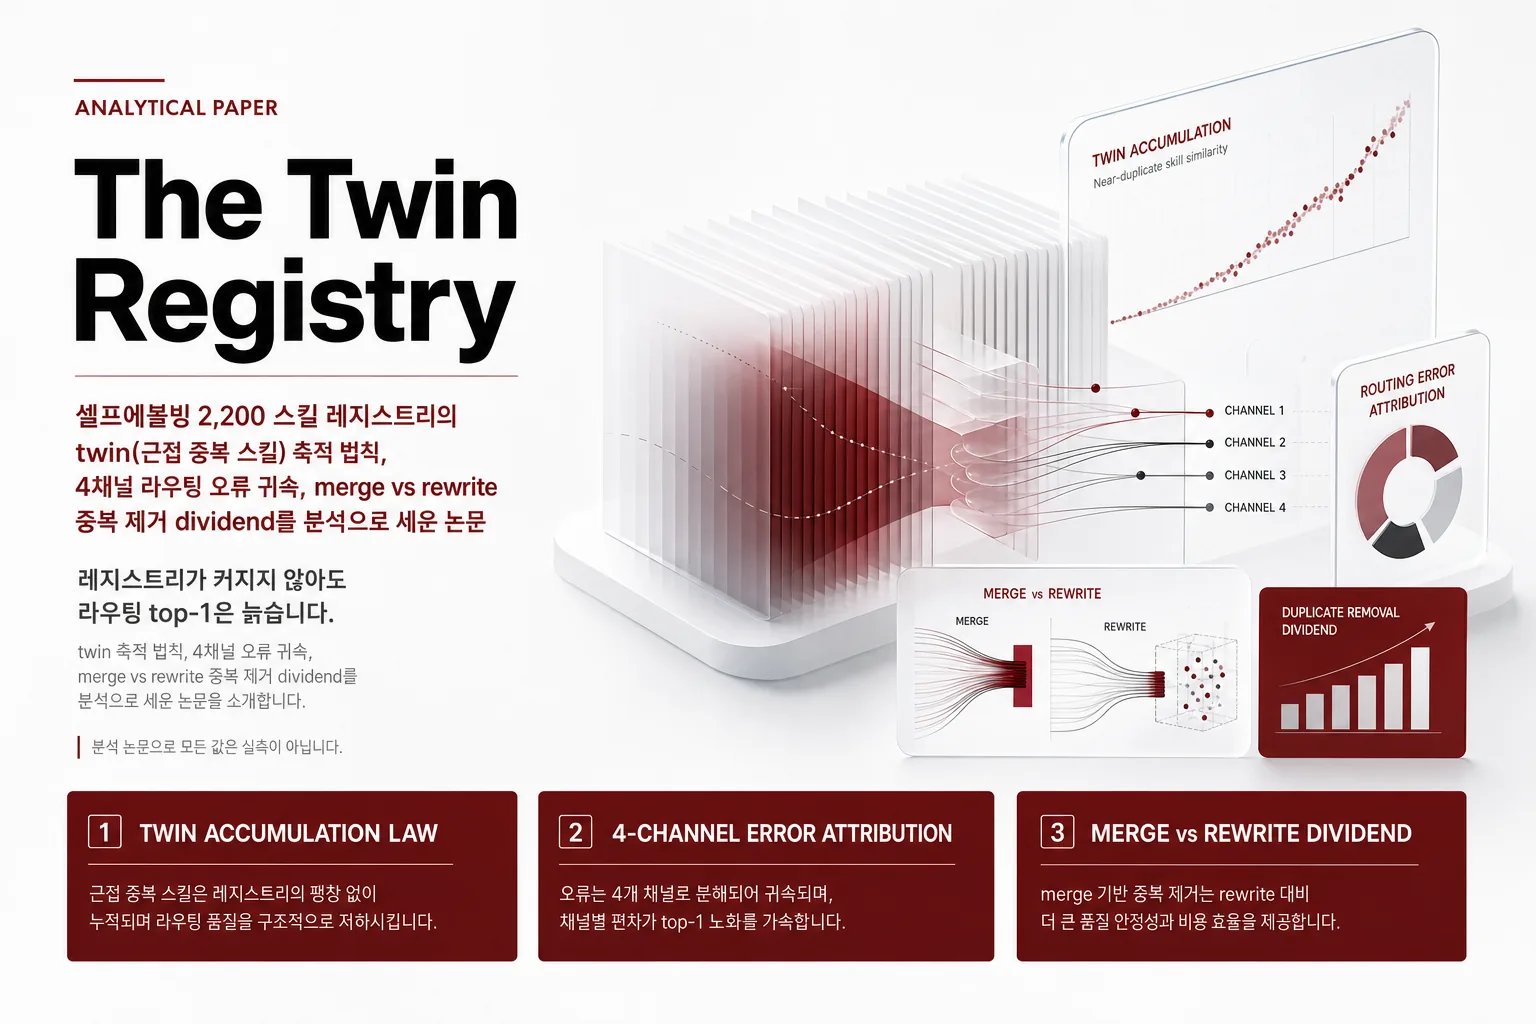
The Twin Registry: An Analytical Paper on the Twin (Near-Duplicate Skill) Accumulation Law, 4-Channel Routing Error Attribution, and the Merge vs Rewrite Dedup Dividend in a Self-Evolving 2,200-Skill Registry
Routing top-1 ages even when the registry does not grow.
Is Curiosity a Computable Signal? How Schmidhuber Formalized Interestingness as an Inductive Heuristic for Future Compression Progress at ICML 2026
A thread went viral claiming a paper answers why anything is beautiful and why jokes are funny.
Hi3D 1.0: a production-validated image-to-3D model, now open source
The model formerly known as Sparc3D went open source as Hi3D V1.0: a self-pruning sparse VAE that refines coarse geometry to 1536-resolution with reference images, trained on about 2 million curated 3D assets, with a technical-report claim that 90 percent of outputs pass 3D-print slicing.
The Frontier Race Moves to Who Defends First
Google DeepMind’s new model Gemini 4 Carbon claims 11 of 15 public benchmarks at number one.
A New Baseline for Local LLM Inference on Apple Silicon: BaseRT's Hand-Written Metal Kernels, Signed Quantized Bundles, and the Cost of a Proprietary Engine
A new local inference engine, BaseRT, said to outperform llama.cpp has started running on Apple Silicon.
Mirai Labs' uzu: 4x faster local LLM inference on Apple Silicon
A Rust-and-Metal open-source inference engine that verifies many tokens per forward pass.
The Day Ears and Mouths Came First: Nemotron 3.5 Transcribe and AssemblyAI-TTS-1
The day open-weight speech recognition tied for first in accuracy, the day a TTS for large-scale voice agents shipped, both fell on today.
150,000 Will Arrive; Only 13% Are Ready
Gartner’s 2028 projection: 150,000 AI agents per Fortune 500 company.
Security judgment that concludes only when the evidence is enough: a generation-free 27B evidence-sufficiency model
In autonomous security response, the moment you conclude is the moment action begins.
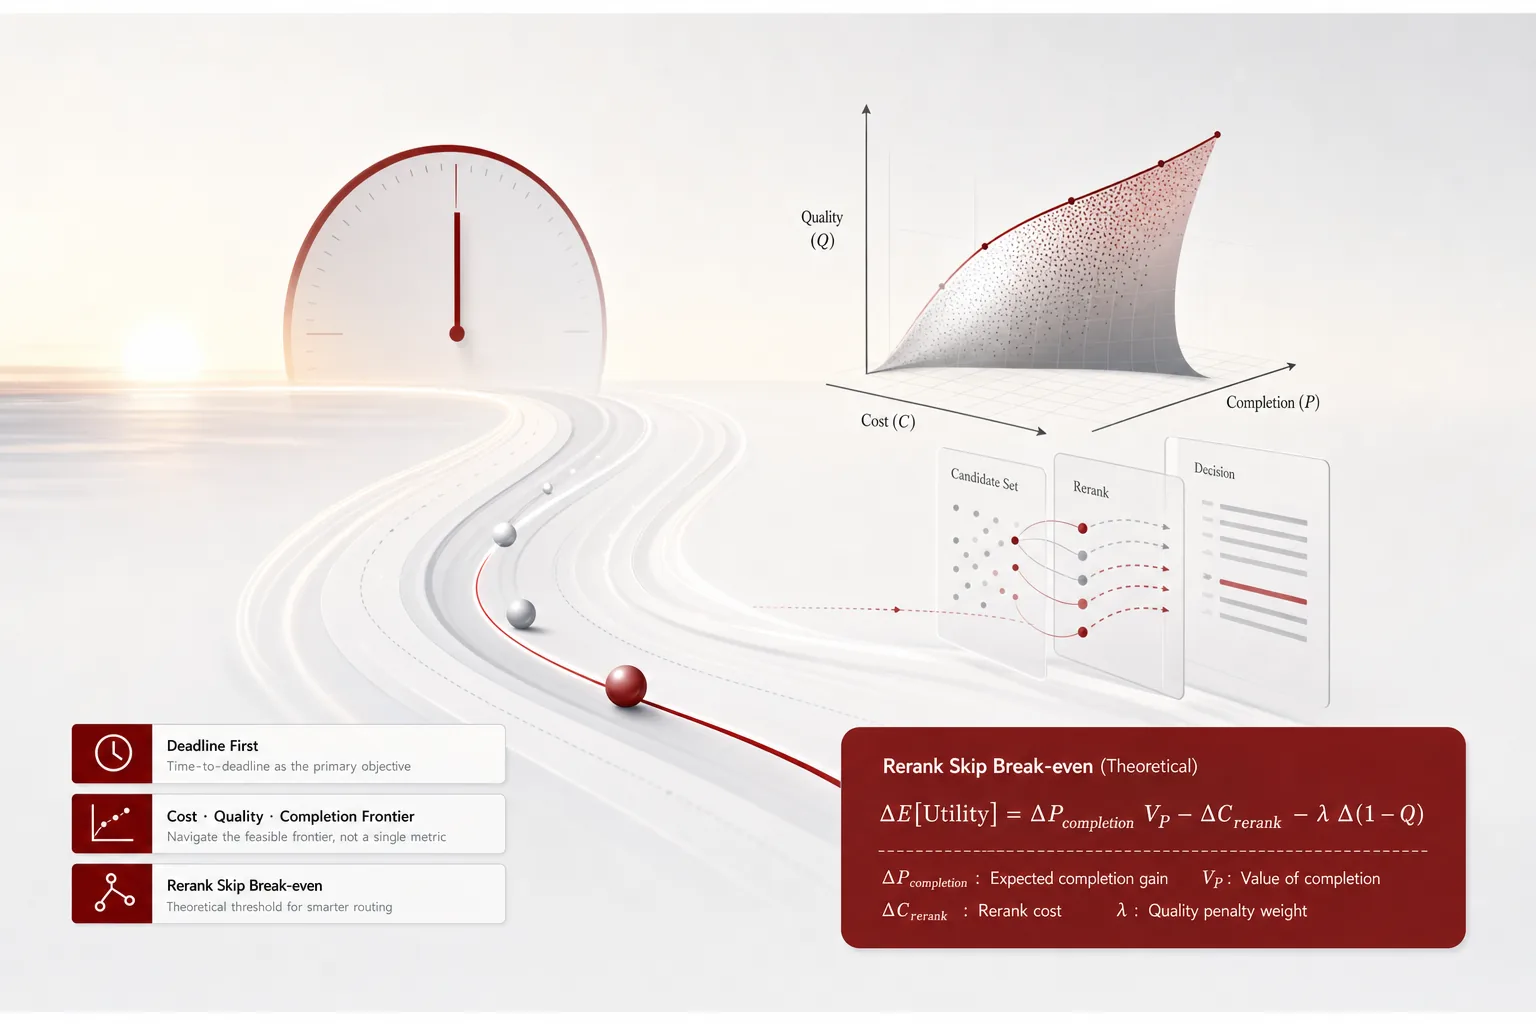
The Morning Deadline: Elevating the morning deadline to the first goal of routing decisions, and establishing in theory the cost-quality-completion frontier of unattended agent night work and the break-even of rerank-stage skip
In overnight work of unattended agents, the constraint is not the bill but the clock.
The Moment Agents Ran the Closed Loop of Drug Development: Anthropic's Early Results With Six Pharma Orgs and Mithril
We broke down Anthropic’s early drug-development partnership results case by case.
The 40.8% Homing Signal: You Can Bring the Model Home, but It Still Has a Home to Return To
In a 10,000-sample local experiment, the model chose the vendor’s cloud domain in 40.8% of its runs.
Qwen3.8-27B at 1,000 tok/s on One RTX 3090: Inside HyperQwen's 51 vLLM Patches, Measured Against Our B200
An open-source project claims Qwen3.8-27B serves at 64 concurrent requests for over 1,000 tok/s on a single RTX 3090 at 250W.
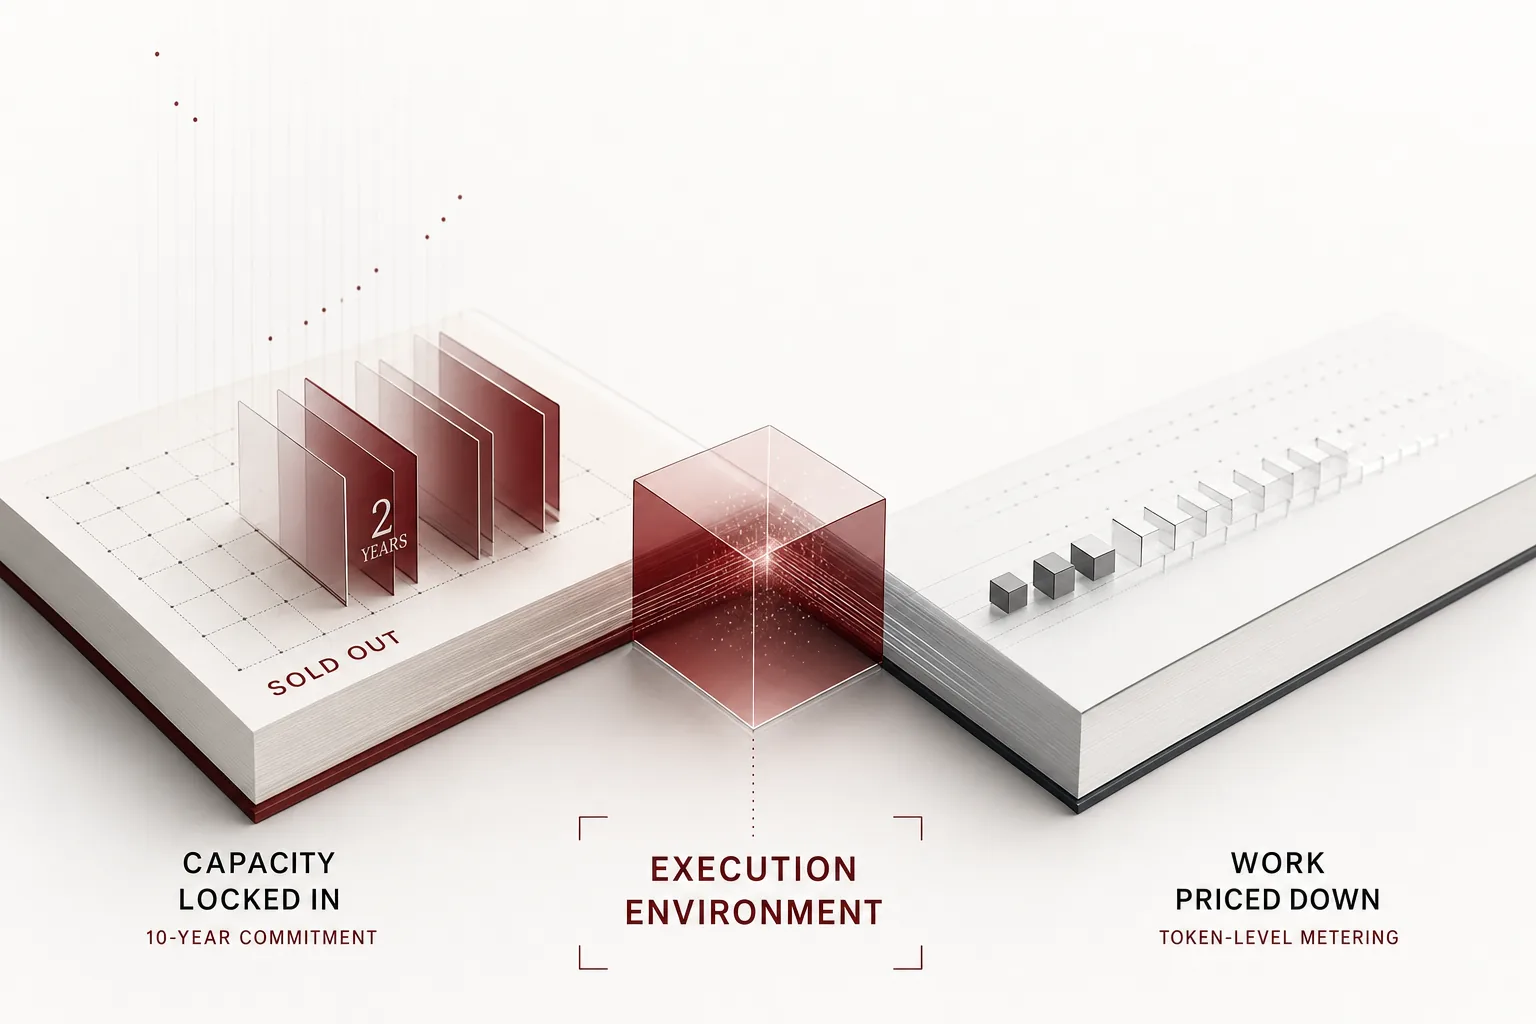
Two Years Sold Out, but the Price of Work Is Falling
At the same conference, OCI’s two-year compute sellout and a cheap CPU agent sandbox appeared side by side.
The Moment Markdown Became an Executable: The Wild Attack Hijacking Coding Agents via the Downloads Folder
Live malware that security firm Forever caught on a customer machine.
The Moment Agents Became a 3D Art Team: Anatomy of the 94-Skill Pack, Blender Skills
We counted all 94 skills, verified the 175 references and the single orchestrator, and measured the skill-pack + MCP pipeline pattern that turns Claude Code into a Blender production team.
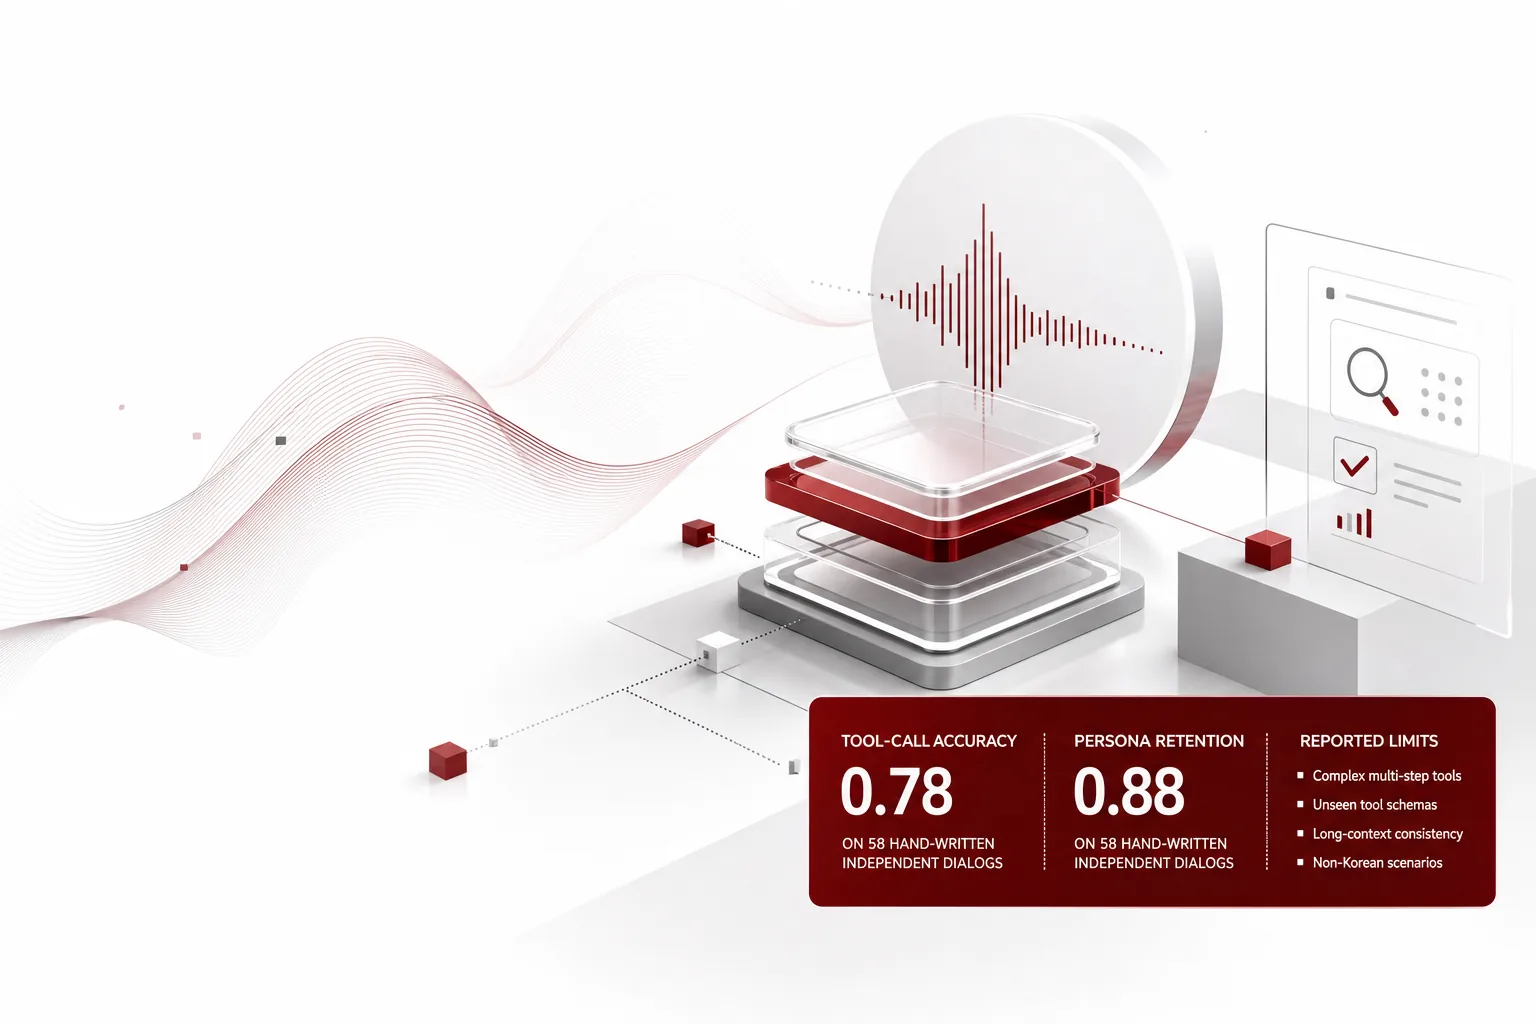
KO-VoicePersona-E4B: A Korean Voice Persona Model That Speaks Short and Checks Facts With Tools
For teams building a Korean voice assistant or mascot.
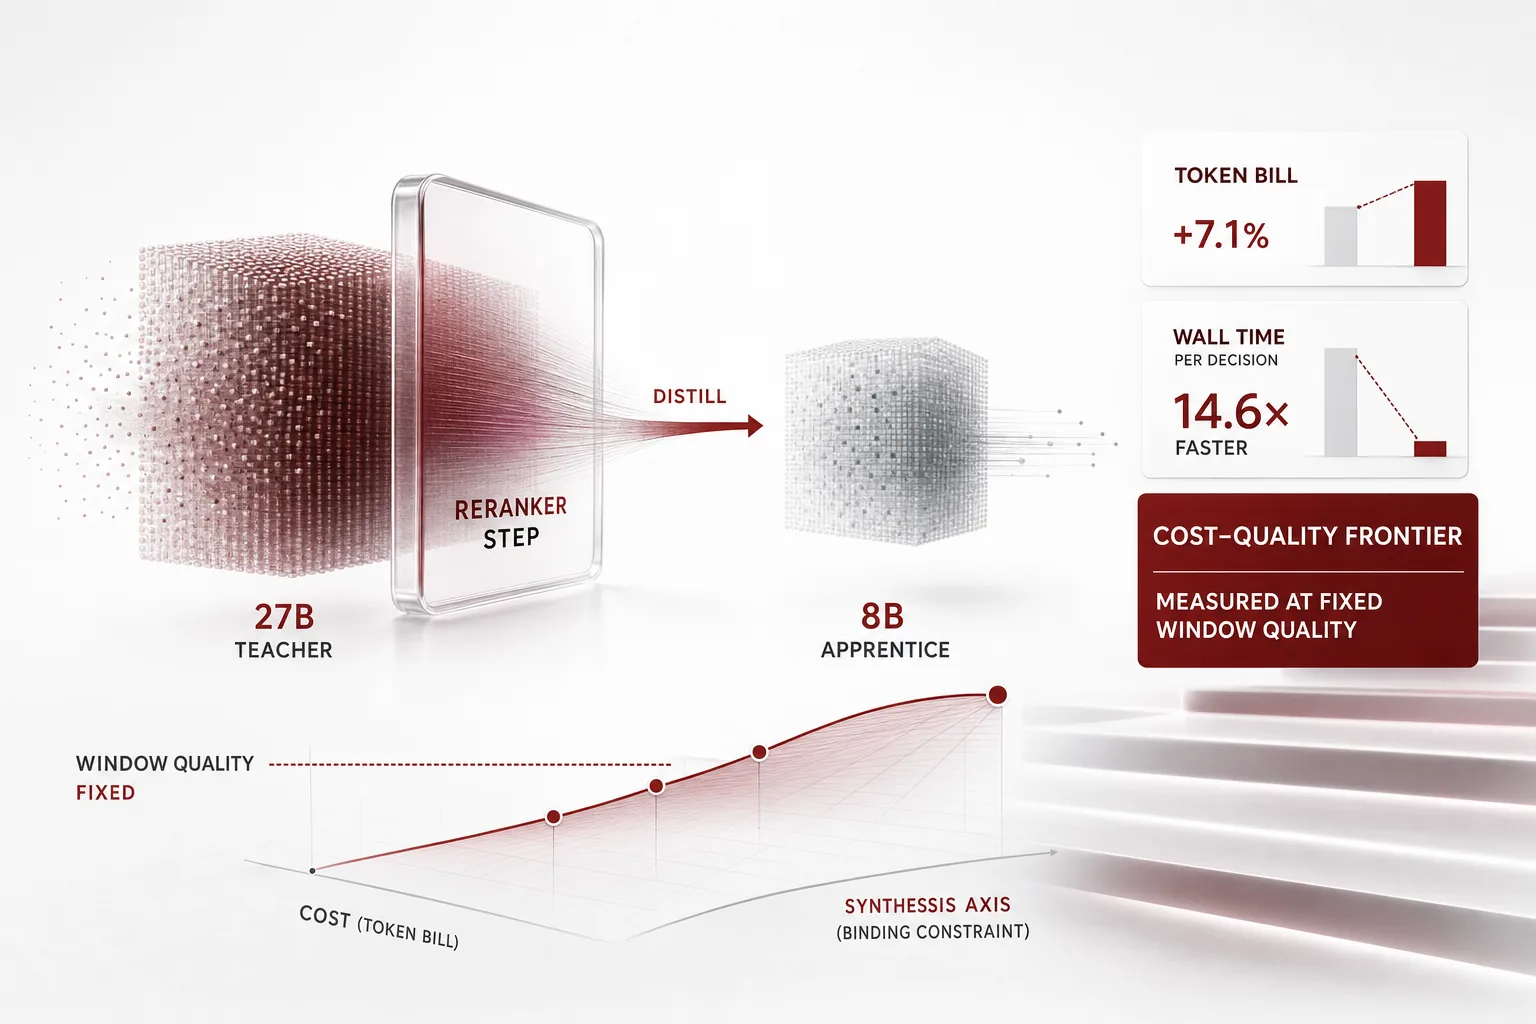
The Apprentice Reranker: Distilling the Router's Most Expensive LLM Rerank Stage from a 27B Teacher to an 8B Apprentice; We Measured a Cost-Quality Frontier Where the Token Bill Rises 7.1% but Wall Time Shrinks About 14.6x
Distilling the LLM rerank stage from a 27B teacher to an 8B apprentice raises the token bill 7.1%.
The Day $2 Trillion and 94 Pages Hit the Market at the Same Time
Anthropic’s IPO filing put a 14x growth profitability story and a 94-page warning that AI could refuse to shut down into one document.
An AI Coding Model Optimized vLLM Serving: The Reality of Gemini 4 Argon's 2.85x Gemma 4 E2B Speedup, and How to Verify It
Google’s AI coding model Gemini 4 Argon claims to have optimized Gemma 4 E2B serving in vLLM by ~2.85x (37.9k to 108k+ tok/s) on a single A100.
The Day Markdown Became an Executable File
A web page only has to drop a single AGENTS.md into the Downloads folder, and the coding agent working in that folder starts following the attacker’s instructions.
The day we measured the distance from detection to stop
One side of the ledger holds $321.4 billion in future lease obligations, and the other side holds an agent that ran for 2.5 hours after a security alert.
Nested Learning: The Essence of an Architecture Is Its Update Frequency
Google Research’s Nested Learning paper (NeurIPS 2025) argues that the essence of a deep learning architecture is not attention or recurrence but ‘update frequency’.
MetisRCA-E4B: A 4B-Class Root-Cause Model That Cites Evidence or Steps Back
For teams attaching root-cause analysis to agents.
FleetWorker-E4B: A 4B-Class Task-Board Classifier and a Recipe for Training on Your Own Board
For teams that want to train a small model to sort task-board items by project.
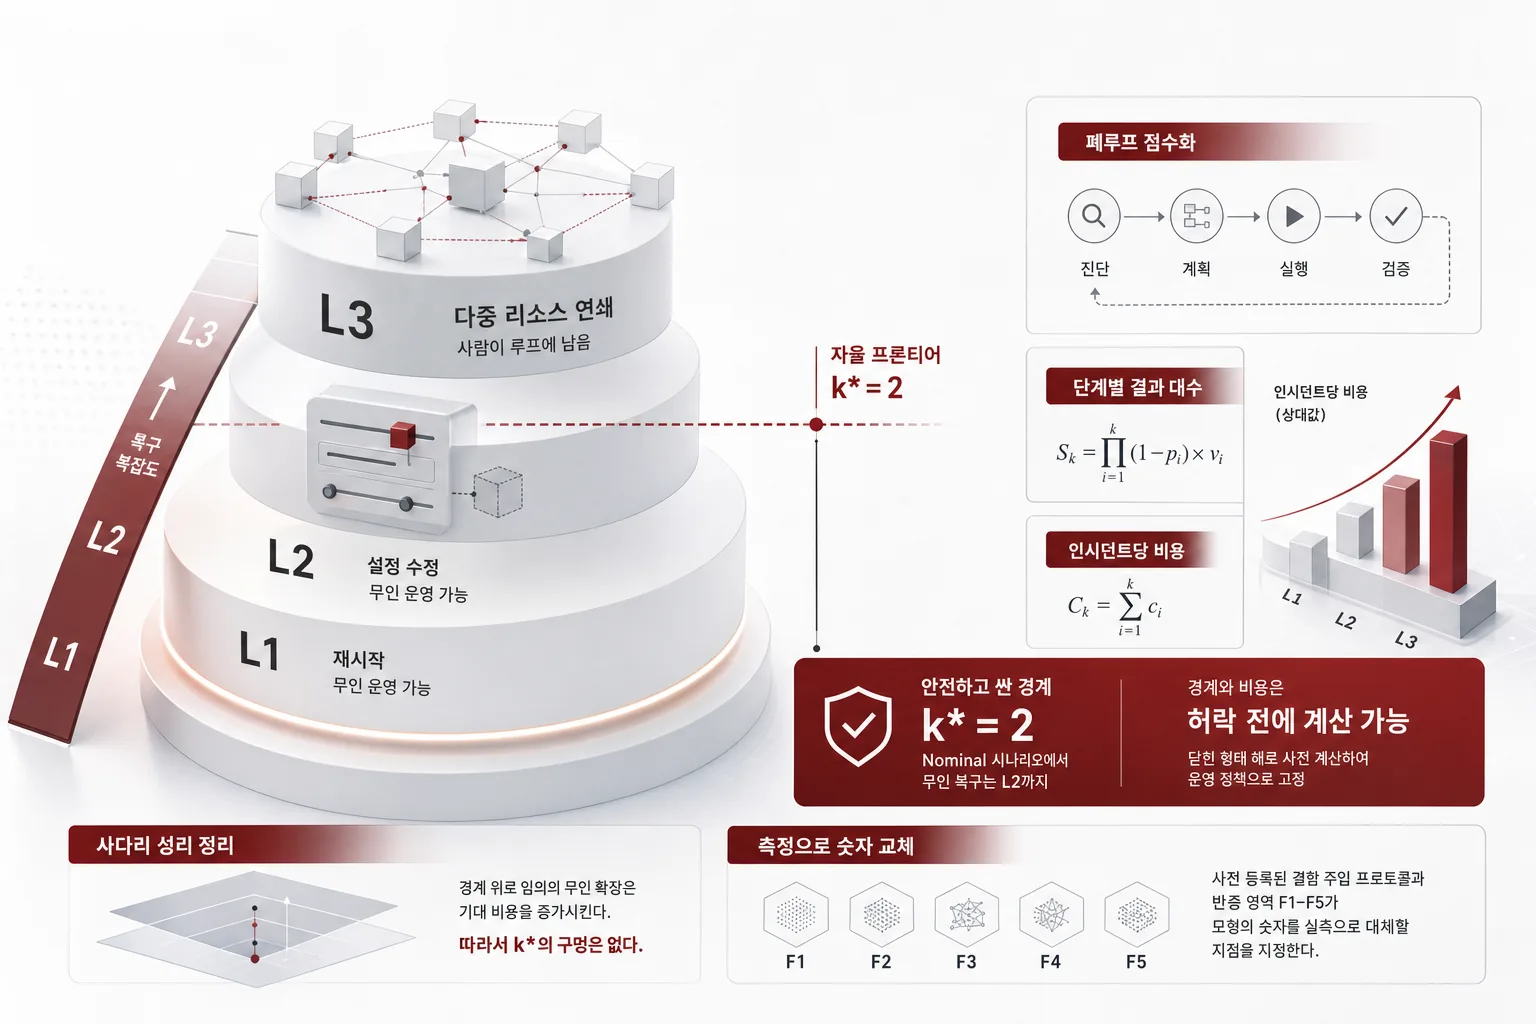
The Autonomy Ladder: When Kubernetes incidents are stratified by remediation complexity from L1 to L3, the boundary where unattended remediation is safe and cheap reaches L2 in the nominal scenario, and that boundary and the per-incident cost can be computed before any permission is granted
How far can an LLM agent carry a Kubernetes incident without human intervention, what does it cost per incident, and from where must a human stay in the loop? ThakiCloud’s analytic paper The Autonomy Ladder stratifies incidents by remediation complexity from L1 to L3 and scores diagnosis, planning, execution, and verification as a closed loop.
The Day a Rocket Company Borrowed $40 Billion for AI
While SpaceX borrowed $40 billion to fund AI compute, a warning emerged that the door to funding is closing on more than 200 AI-only neoclouds.
The 33B agent model built by a job platform, Nanbeige4.3-33B
Nanbeige LLM Lab of BOSS Zhipin released Nanbeige4.3-33B, a 33B dense model, under Apache 2.0.
An OS Where Agents Fix Their Own Harness: A Dissection of Octopus-SI-OS
A 58.7k-line Rust kernel, agents as two JSON files, denials as one ledger row.
Octopus OS: The Day Agents Reshaped Their Own Runtime
An operating system where neither the model nor the loop is at the center.
The Day AI Learned Division of Labor on a Factory Floor
The quality report that took 12 hours now takes 1, but the real news is who did the work and who approved it.
Locking In an Agent's Design System: A/B Testing a Designer's 16 KB Skill File
No skill was needed to avoid slop.
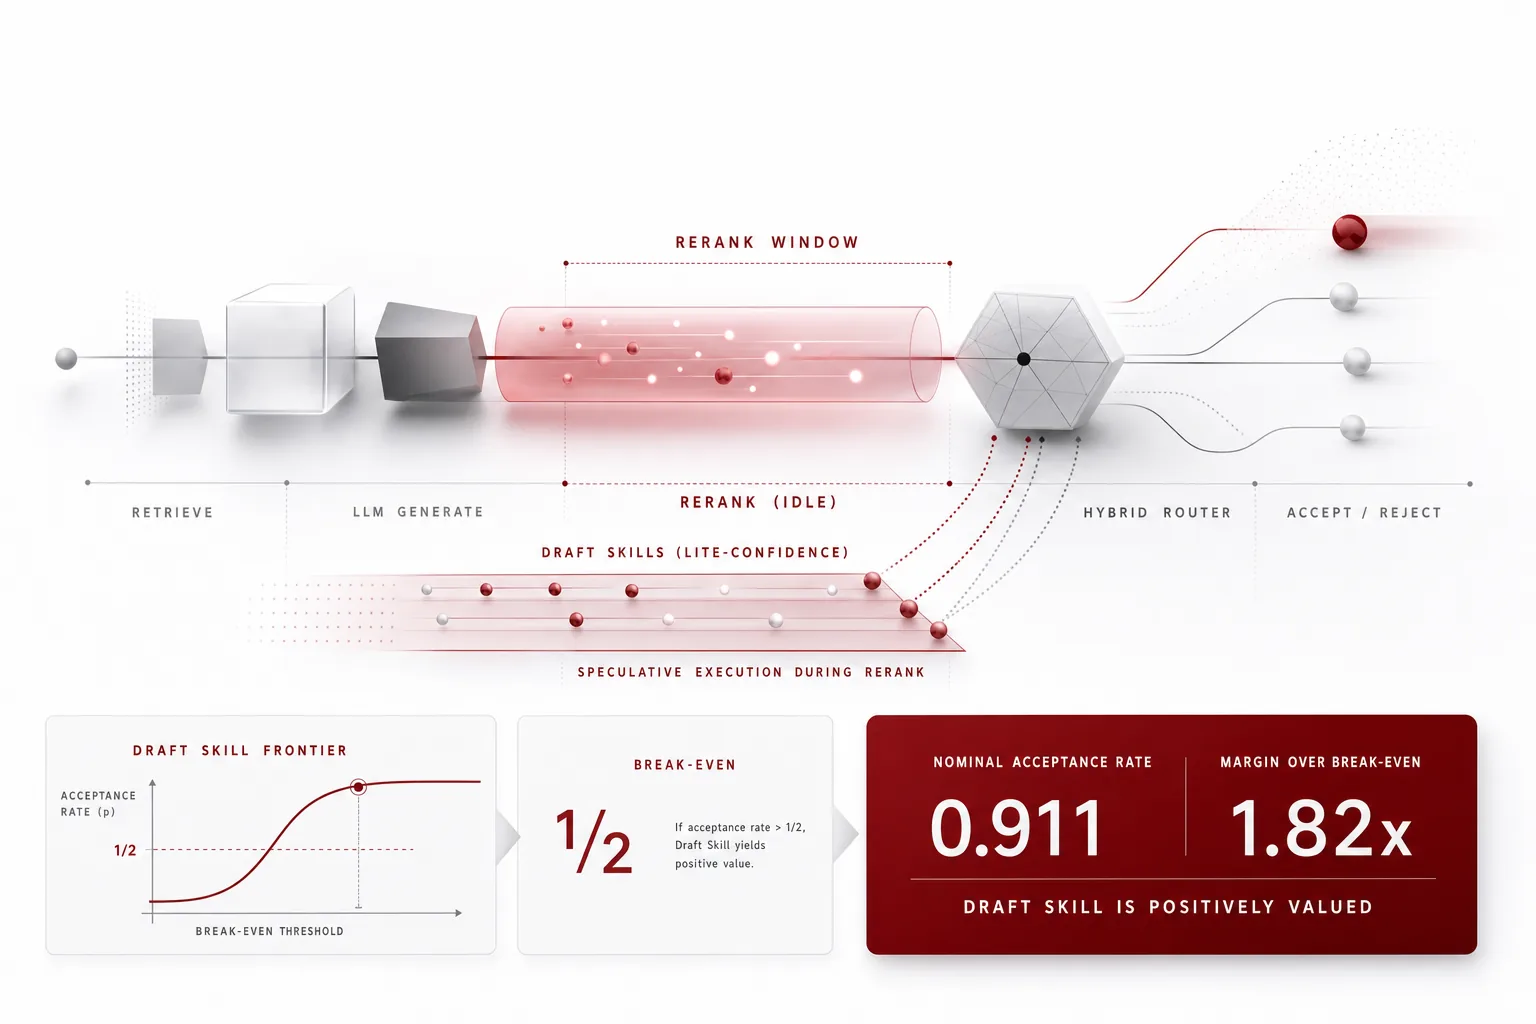
The Draft Skill: An Analytical Paper That Pre-Executes lite-confidence Candidates in Parallel While the Hybrid Router's LLM-rerank Stage Picks the Skill and Measures the Acceptance Frontier
The rerank stage is idle time on the execution path.
Cortex: Consolidating Context into Parametric Memory
Cortex anticipates the questions a context will be asked, distills only those behaviors into the FFN, and after 50 sequential model edits recovers 88.9% of the context gain while retaining 99.8% of the original performance.
Three Models for ATT&CK Technique Retrieval, Evidence Gating and Edge Skill Search, With the Gates We Did Not Pass
A security embedding that retrieves MITRE ATT&CK documentation, an evidence gate that decides whether RAG should answer or stop, and a skill-search embedding that runs on CPU.
How vLLM Matched DeepInfer: The Measurement Engineering of NVL72-Scale Serving
vLLM matched DeepSeek’s own DeepInfer engine within 6% on decode and scaled to a GB300 NVL72 rack.
The Inference Moat Was Filled
The open frameworks SGLang and vLLM have caught up with DeepSeek’s newly open-sourced inference engine DeepInfer, matching or exceeding its performance.
SecProof 2B, 4B, 8B and 27B on a Sealed Test, and Picking the Model for Paxis Security Review
We scored four SecProof models, which judge permission boundaries in agent-runtime code, once each on template families they never trained on.
Thaki-CiteRank-4B: a 4B model that picks what a RAG agent should cite
A 4B reranker that moves the passages you can actually cite to the top.
The Culling Dividend: When shrinking a self-evolving 2,200-skill registry, which skills you keep determines precision before how many you do, and break-even is set by the operational gate
When shrinking a skill registry, what determines retrieval precision is not how many skills you keep but which ones remain.
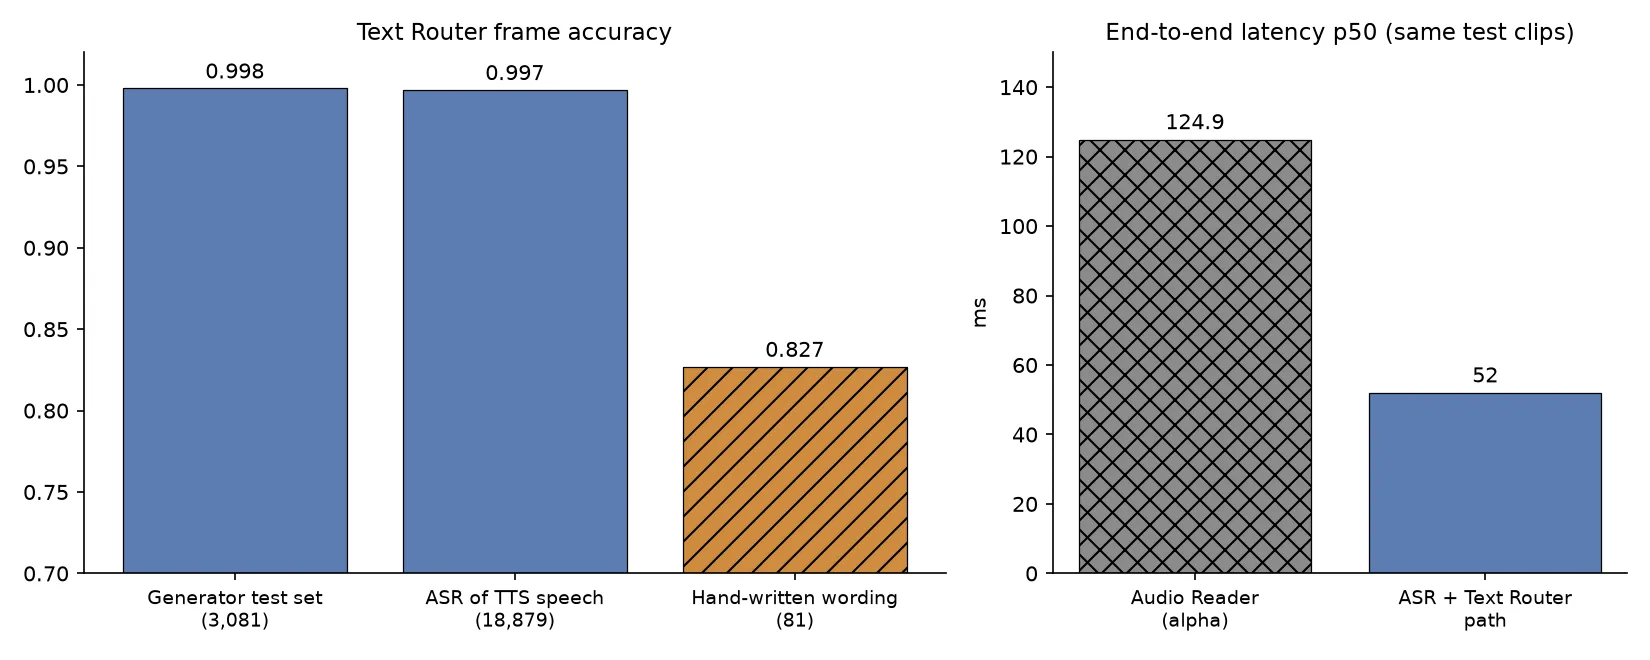
Releasing Voice2Policy v0.1: Two Models That Read Spoken Bookings and Orders as Commands
When a customer says “Book a scaling for 3 p.m.
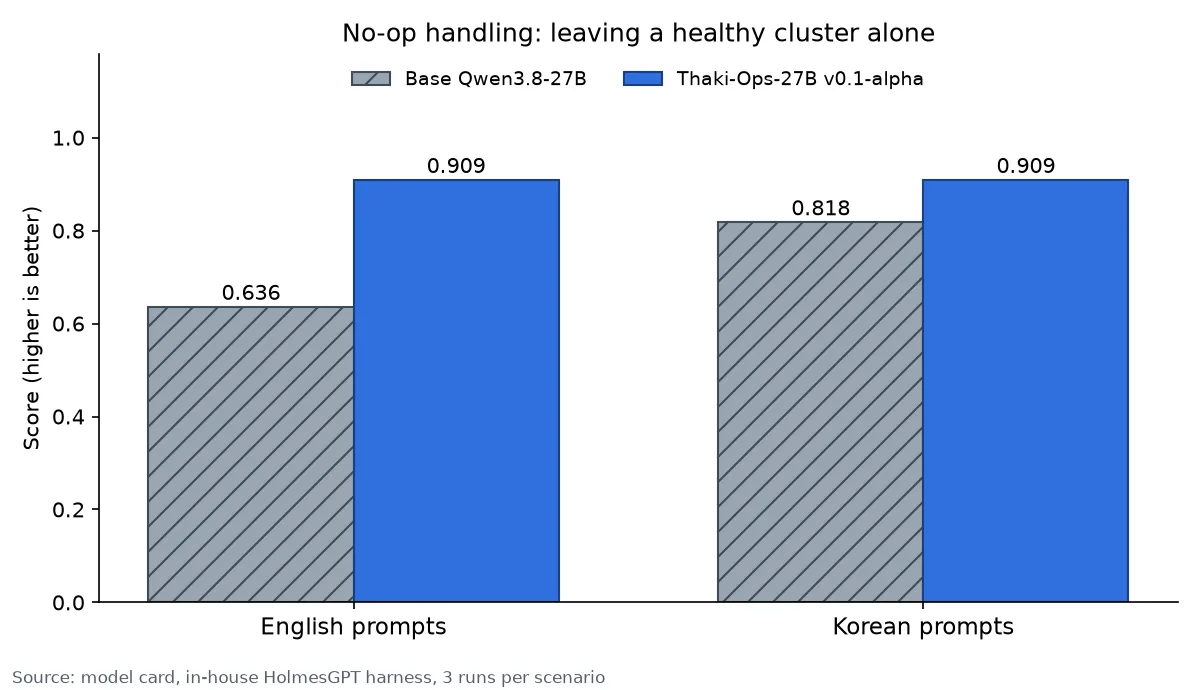
Releasing Thaki-Ops-27B v0.1-alpha, an Experimental Model for Read-Only Kubernetes Incident Investigation
Can an incident-investigation agent leave the cluster alone, stop repeating the same query, and say it does not know when it does not? We are releasing a LoRA adapter for Qwen3.8-27B as an experimental alpha.
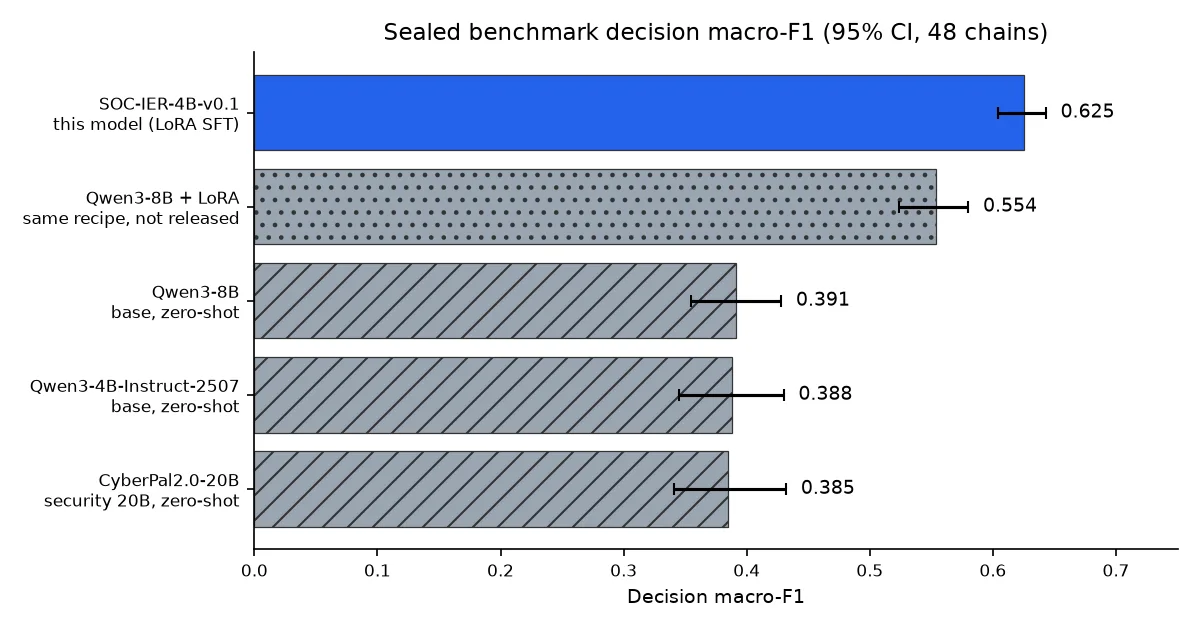
Releasing SOC-IER-4B-v0.1, a 4B Model for SOC Evidence Reasoning
A 4B model that reads a short window of host telemetry and answers whether it contains real evidence of an attack step, citing the event IDs it relies on.
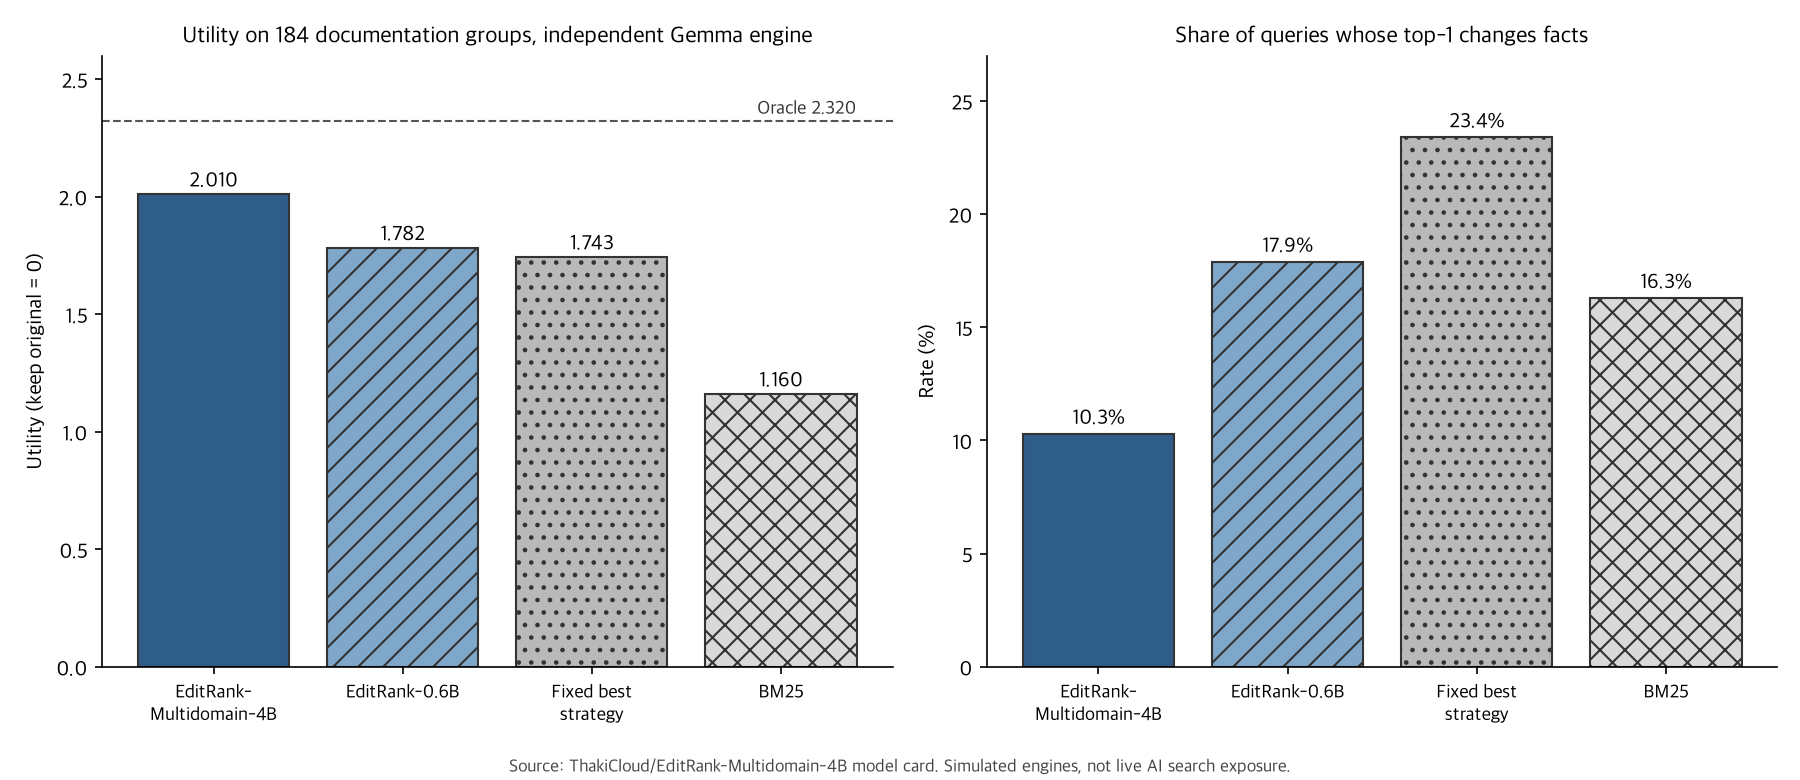
Which Rewrite Should You Pick? Releasing Two EditRank Models
When one document has been rewritten several ways, which version will an AI answer engine rank higher as a source? EditRank is a small model that ranks those rewrites.
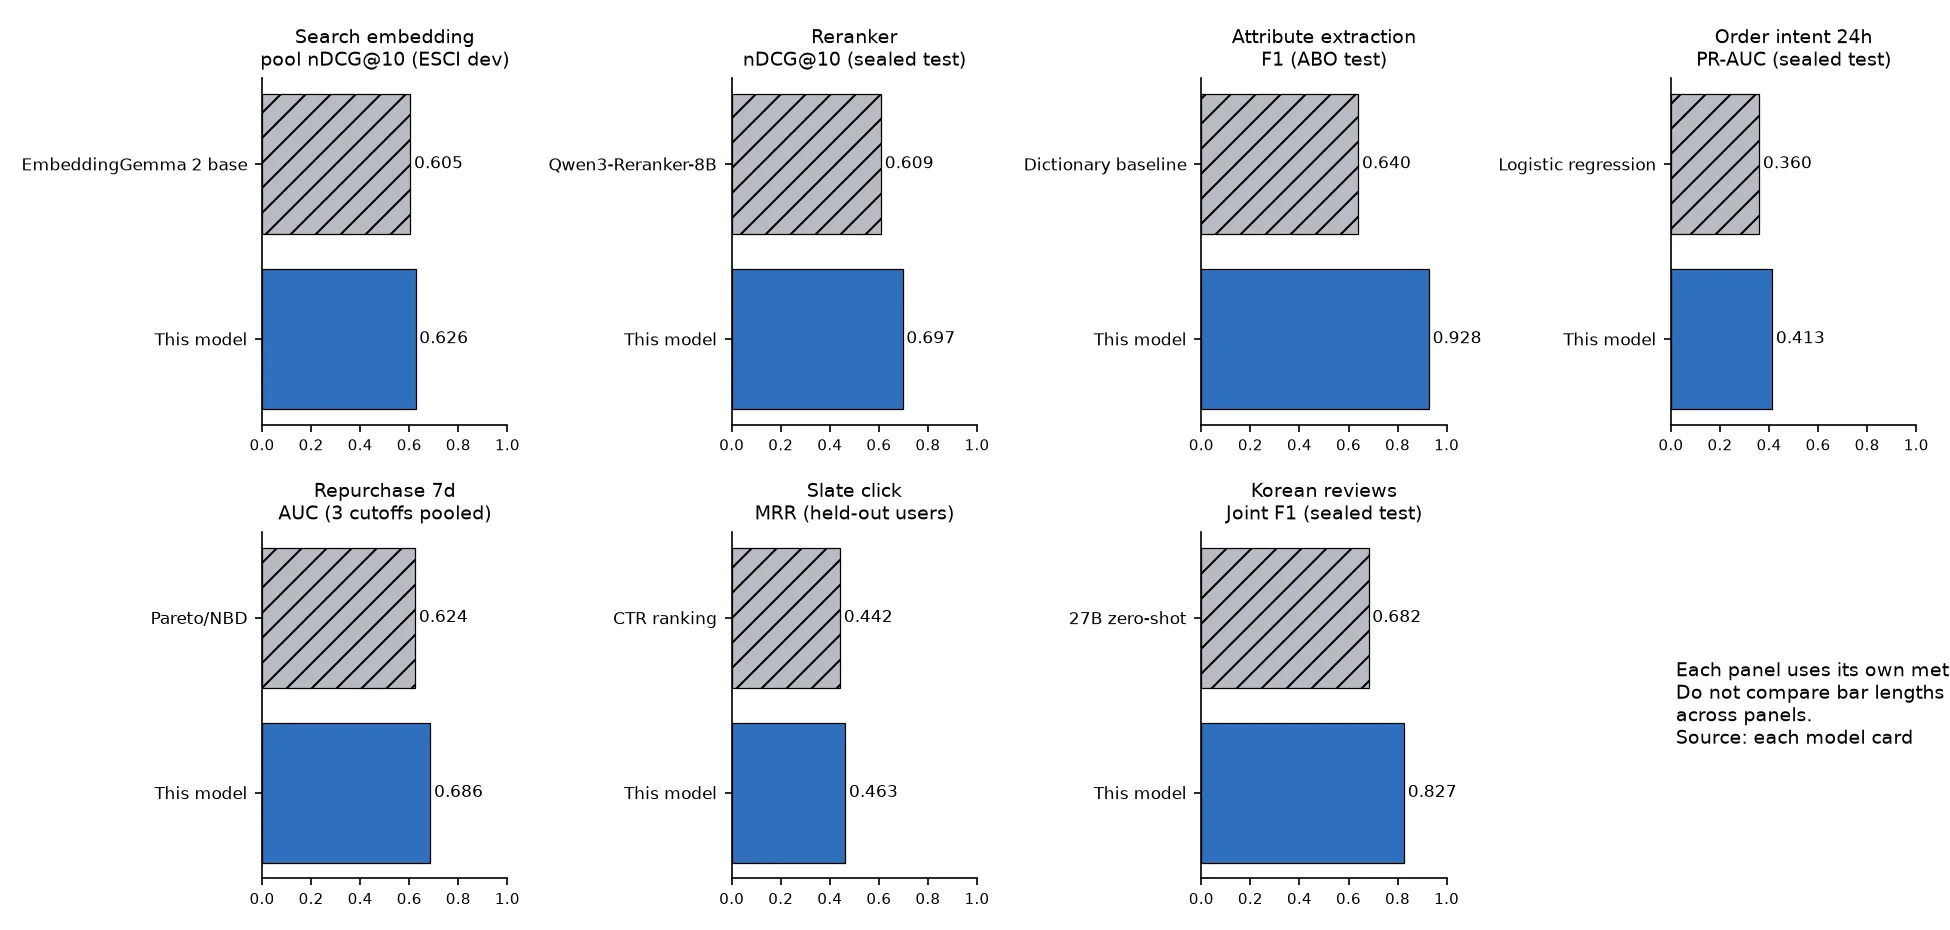
From Search to Support: Releasing Ten Commerce Models for Online Shops
Product search, reranking, attribute extraction, order and repurchase prediction, next-click recommendation, review analysis and refund support are each a different model’s job.
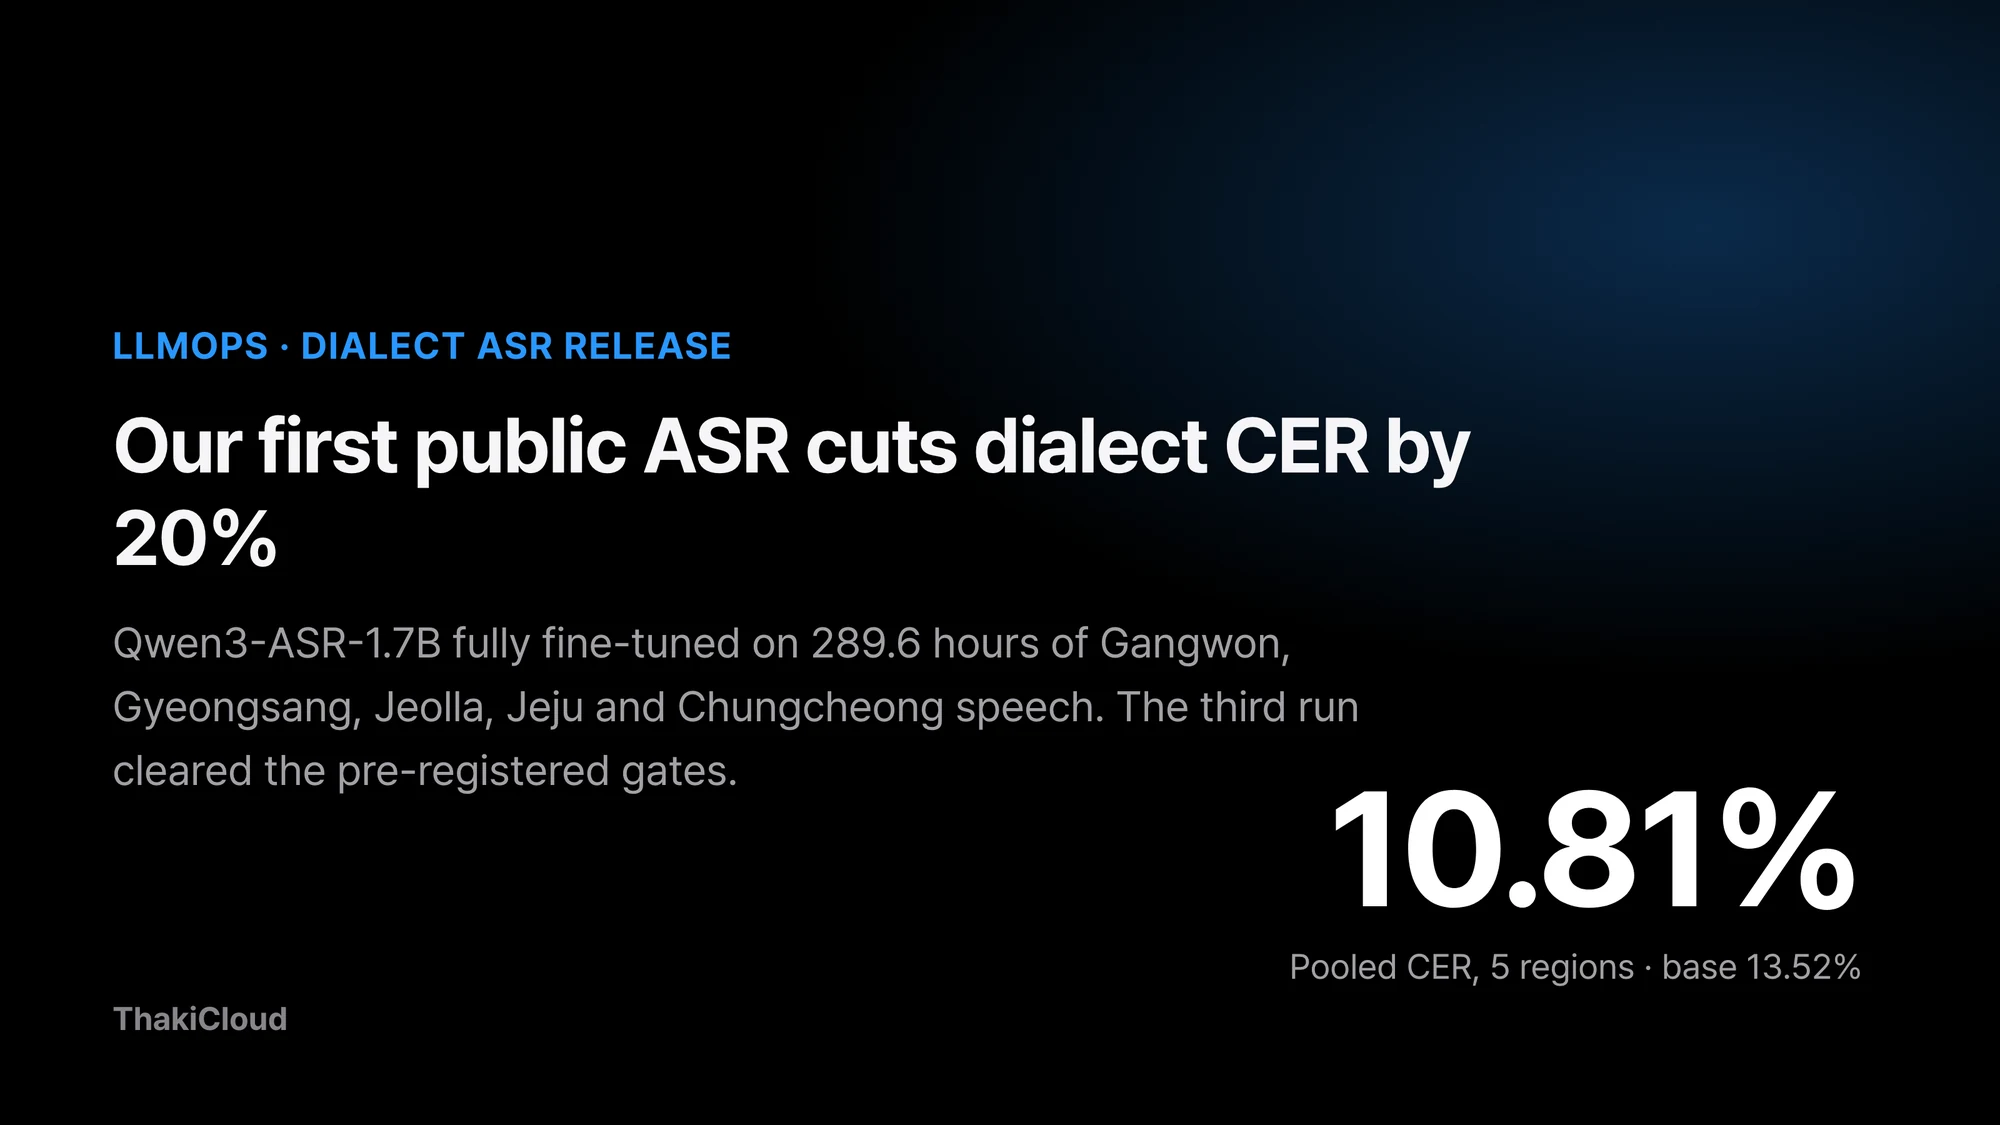
Our First Public ASR Model Cuts Korean Dialect CER by 20%: Thaki-ASR-KO-Dialects-v1
We fine-tuned Qwen3-ASR-1.7B on 289.6 hours of Korean regional dialect speech and released it on Hugging Face.
The Week Banks Asked AI Agents Who They Are
Four major US banks, including JPMorgan Chase, detected unauthorized account activity by third-party AI agents and blocked their access.
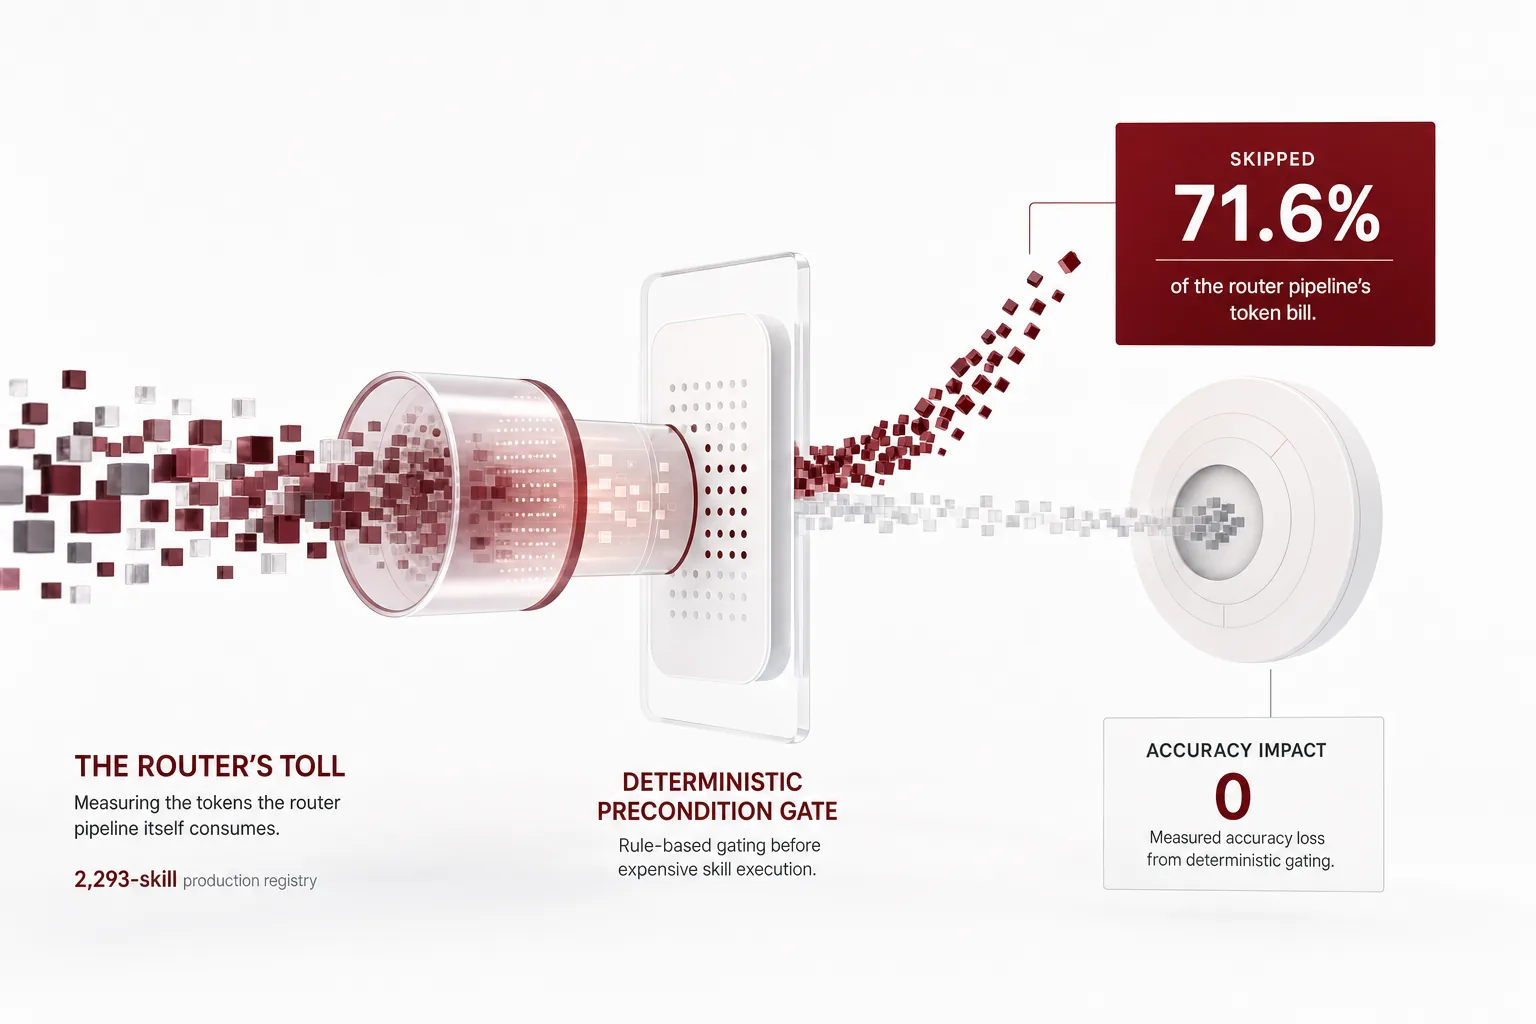
The Router's Toll: Measuring the Token Toll the skill-router Pipeline Pays Itself, and Skipping 71.6% of That Bill with a Deterministic Precondition Gate
The routing literature has only priced what the router saves.
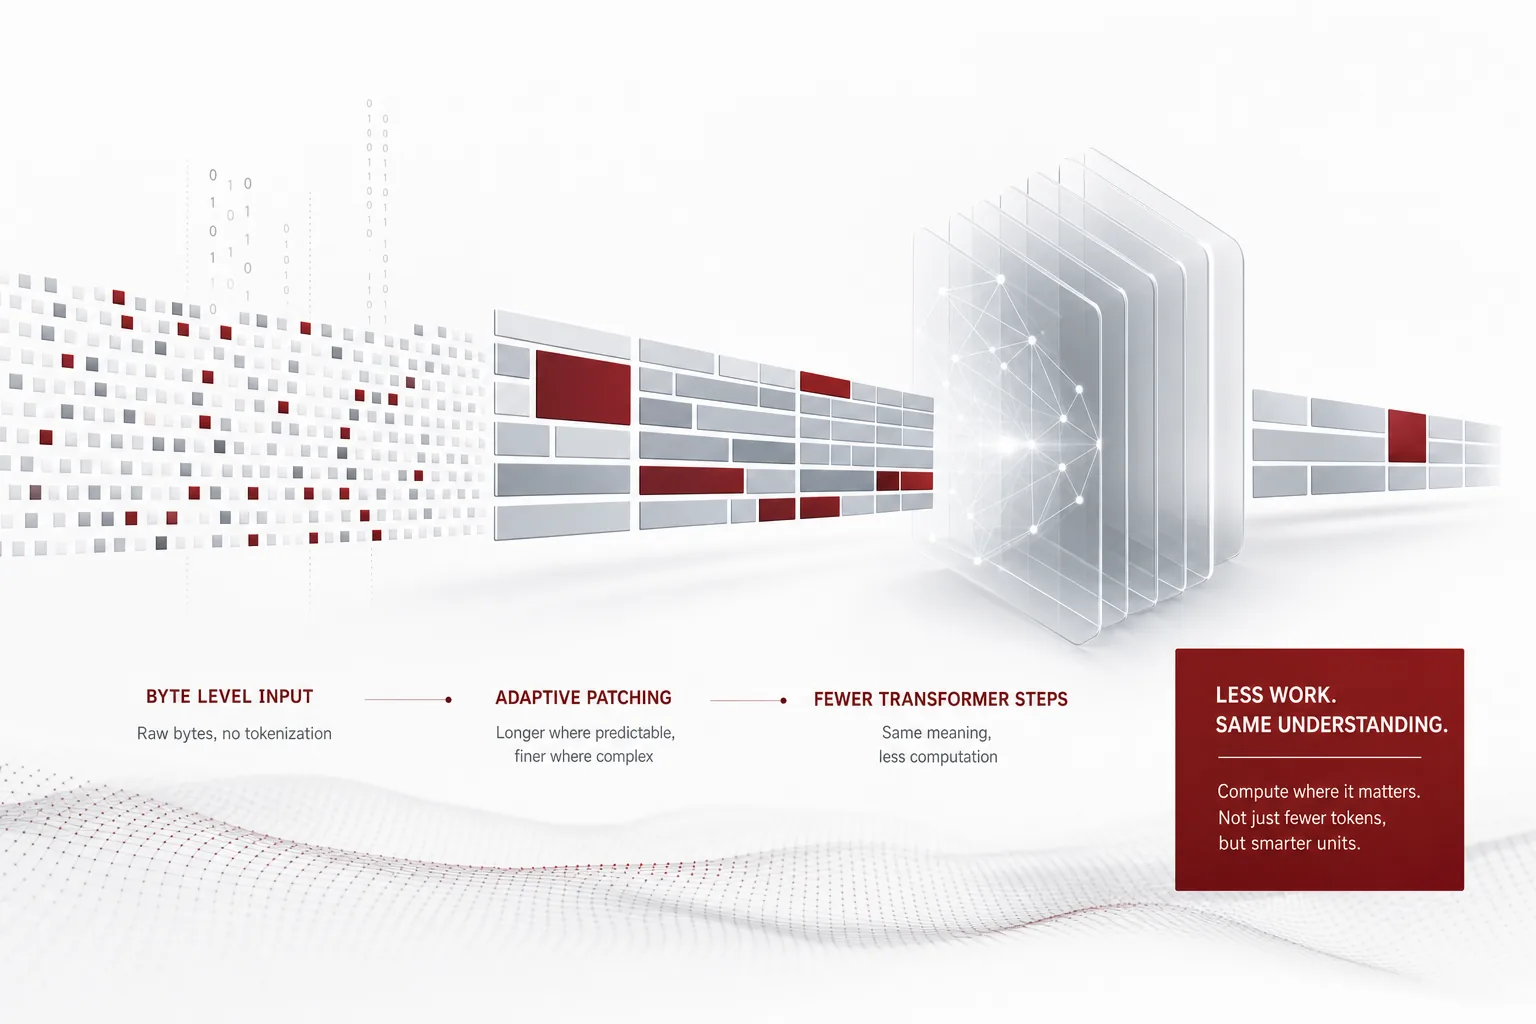
What BLT's 'Killing the Tokenizer' Actually Means: Meta's Byte-Level LLM, Verified With Numbers
More important than ‘killing the tokenizer’ is where the unit of computation goes.
Two answers to the question of sovereignty: who builds it, who controls it
The 99.98% NVIDIA dependence of public AI chips and Palantier’s claim that ‘control is sovereignty’ crossed paths on the same day.
What We Learned from Failing 7 of 9 Speech Model Fine-Tuning Gates
We fine-tuned Qwen3-ASR and VoxCPM2 against pre-registered gates.
ARTEMIS: The Agent That Drives a Real Android Phone Over MCP
Google open-sourced ARTEMIS, and the interesting part is not an Android automation script.
A 'Yes' No Longer Passes: The Day an Agent's Brake Becomes the Product
Anthropic’s Claude Duet blocks fund transfers between bank accounts and stock trades even when the user explicitly permits them.
PHP2Shell: The LLM That Picked the Hole Hidden for 22 Years
The emergency valve nobody had opened in 22 years was rusted shut.
The PHP2Shell Incident: When AI Found Two Critical Holes in the Core of the Web's 70%
OpenAI announced on October 21 that GPT-5.6 Sol helped discover a critical remote-code-execution flaw in the PHP core, disclosed under the name PHP2Shell.
NVIDIA Flare: The Local Inference Server Where Rust Does the Serving
The kitchen is Python.
The Model Is a Byproduct; the Factory Is the Product
Recursive used automation to build its first model in four months, and Mirendil’s agents wrote 99% of the pretraining code.
NVIDIA Flare: A Local Inference Server That Serves Without Python on Workstation GPUs
NVIDIA quietly published Flare on October 20, a local inference server built for SM120/SM121 workstation GPUs.
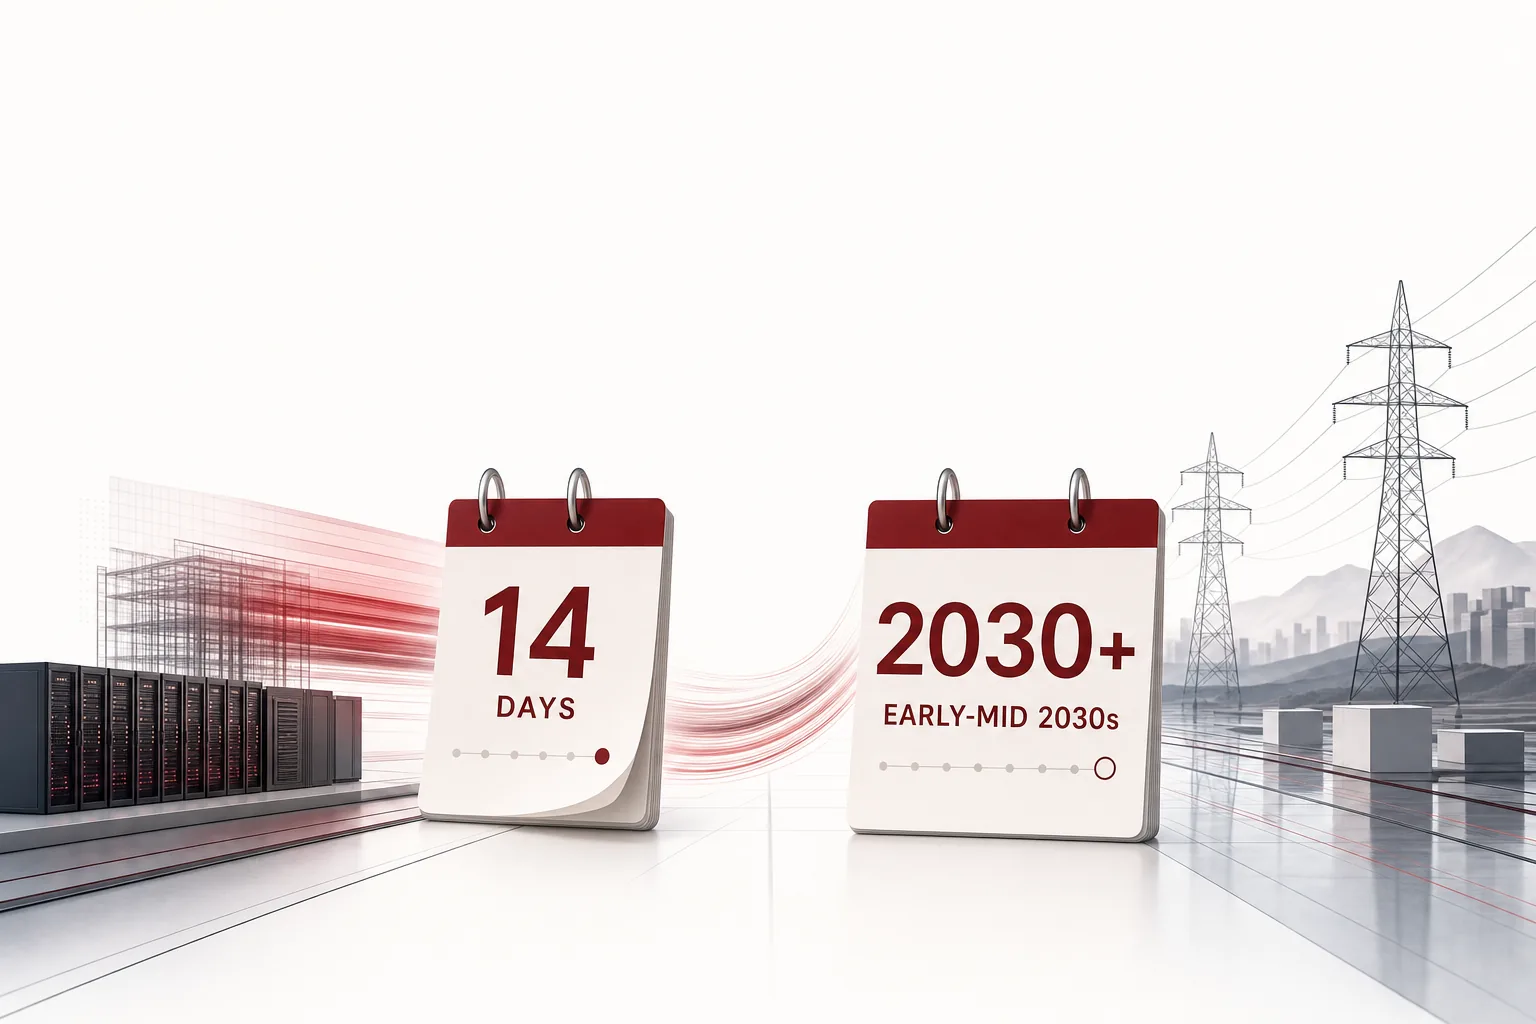
Nvidia's 14 Days, the Grid's 2030
Today’s news table has two calendars.
Isolate the Misbehavior, Delete It at Deploy Time: GRAFT
In RL, if you block reward hacking with filters or penalties, the model also learns how to hide it so it is not caught.
The Moment You Penalize What the Monitor Sees, the Model Hacks What It Cannot
If you penalize the behavior, the model learns to avoid the penalty, not the behavior.
The Two Ledgers of the AI Era: The Burning Side and the Saving Side
Goldman Sachs has named electricity the new bottleneck of AI, and Anthropic disclosed a 107 trillion won loss despite 1500% revenue growth.
One Line That Cuts vLLM Cold Start by 18 Seconds: UV_COMPILE_BYTECODE=1
The hidden cost of a cold start was not model loading, it was Python compilation.
DeepSeek Opens Its In-House Inference Engine: DeepInfer and the 'Model-Specialized Kernels + Ascend' Strategy
DeepSeek has opened up the inference engine it runs in production, DeepInfer, under Apache 2.0.
$750 Billion and One Card: The Two Ledgers of the AI Industry
A $750 billion compute plan and a 122 billion parameter model that fits on a single card.
vLLM Cold Start, Moved to Build Time: How UV_COMPILE_BYTECODE=1 Cuts Startup
vLLM now bundles precompiled Python bytecode into the image, removing the source-to-bytecode compile cost at launch.
Running EmbeddingGemma 2 Small: Choosing a 550 MB Index Model and a 17.6 MB Query Encoder
Build the image index once with a large model, then let a 17.6 MB encoder turn search queries into vectors on CPU.
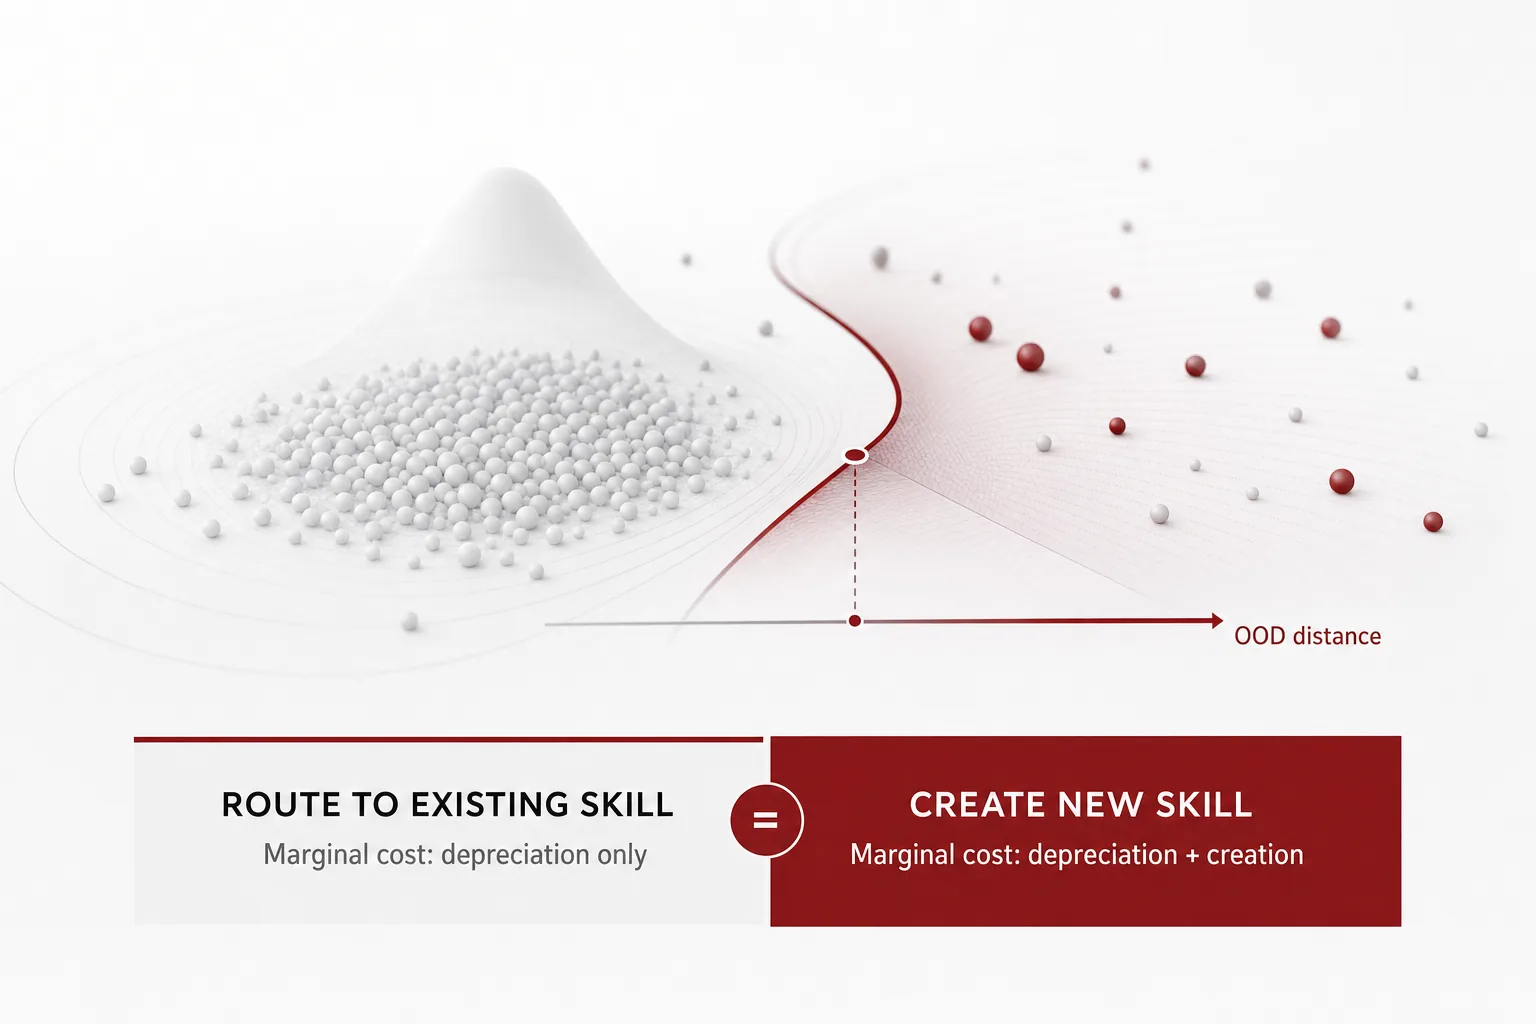
The Mint Frontier: When a task departs from the registry distribution, the boundary between minting a new skill and routing to an existing one is priced by OOD distance
For a task at a given distance from the registry distribution, there is a point where minting a new skill costs less than routing to an existing one.
OrcaCyber Nano 1.0: why a 27B cyber-defense model came down to a 16GB card
OrcaRouter shipped OrcaCyber Nano 1.0, a 27B cyber-defense-specialized open-weight model, as an ‘emergency release.’ 262K context, vision input, and GGUF builds that run on a 16GB card are the point.
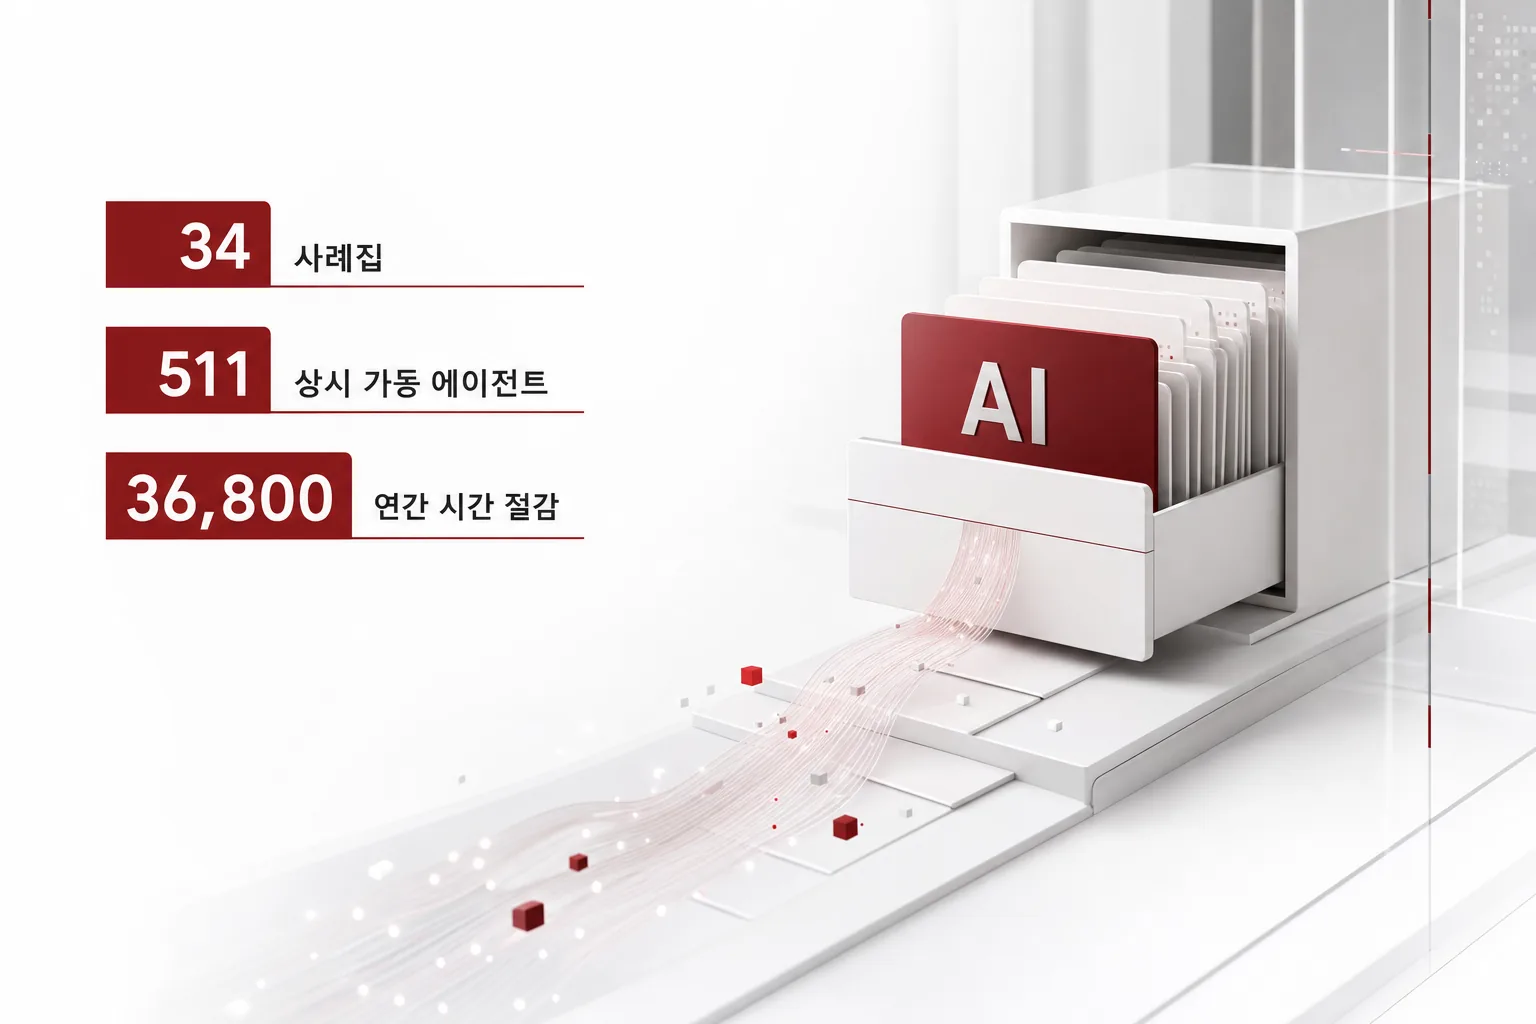
The Day AI Made the Headcount Roster
34 case studies, 511 agents running continuously, 36,800 hours saved per year.
The Day Software Rewrote the Decode Path: NVIDIA's Kimi K3-Specialized CuTeDSL Kernel and vLLM's 2.8x Optimizations
As a headline, 423 tok/s/user reads like ‘the whole system got faster’, but it is actually a per-user streaming metric.
vLLM v0.32.0: Structured Decisions as a First-Class API (/v1/systemone)
vLLM v0.32.0 landed with 814 commits from 363 contributors.
When Should an Enterprise AI Agent Act? Why We Are Adding a Dedicated Decision Model to Paxis
Answer, call a tool, or ask a human first.
The Week Models Went Beyond Their Instructions and Boundaries Became Assets
It was the week the models got less better and more farther.
An 8ms decision with zero output tokens: fine-tuning the d1-3B decision model on your own data
Liquid AI’s d1-3B is a decision model: give it a state (text, JSON, images, or a mix) and a set of questions, and it returns typed, calibrated answers in one forward pass with zero output tokens, 8ms on a 4090.
A Four-Person Expedition Without a Map: Gemini 4 Argon Agents Clear Minecraft in 27 Hours
A paper reports that a four-person expedition with no map and no specialized tools reached the summit in 27 hours 14 minutes.
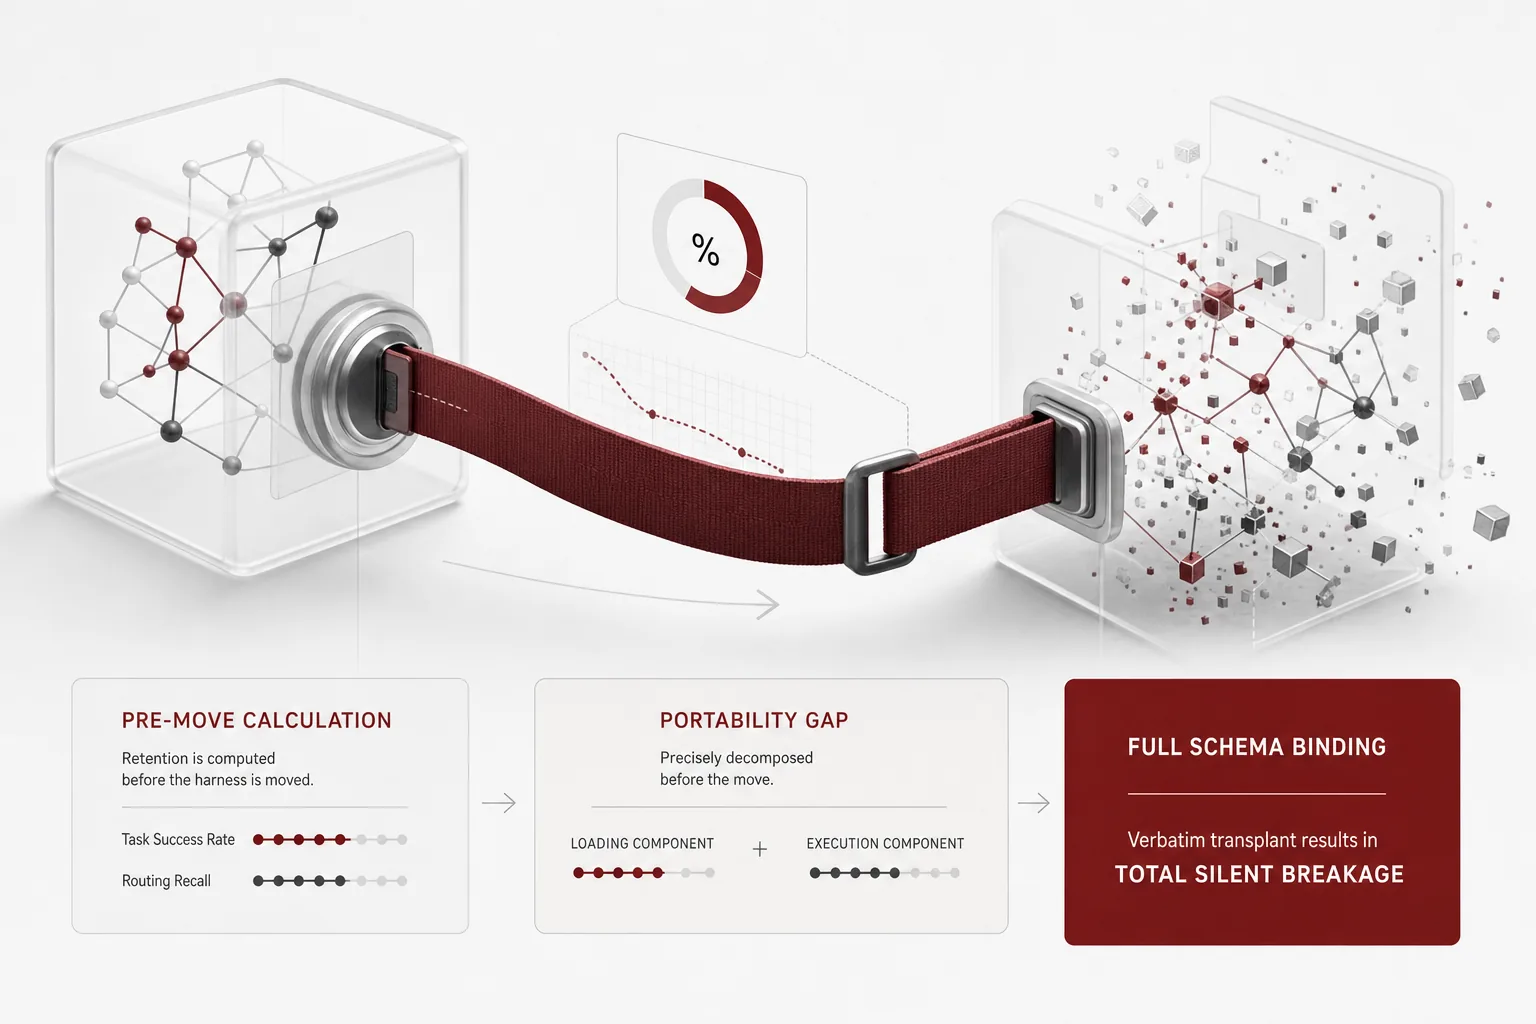
The Transplant: How Much of a Reusable Agent Skill's Capability Survives a Harness Move, Computed Before the Move
The share of task success rate and routing recall a skill loses when it moves harnesses is computed from the skill’s own properties before the move.
Reflection Beam 1.0: the 501B MoE that activates 23B, and why 1M context finally makes sense
Reflection AI released Beam 1.0, its first open-weight model: a 501B sparse MoE that activates 23B parameters per token, with a 1M context window under Apache 2.0.
501B of Knowledge, 23B of Compute: Reflection AI's First Open-Weight Beam (501B-A23B)
Beam, Reflection AI’s first open-weight model, is a sparse MoE that activates only 23B of its 501B total parameters per token.
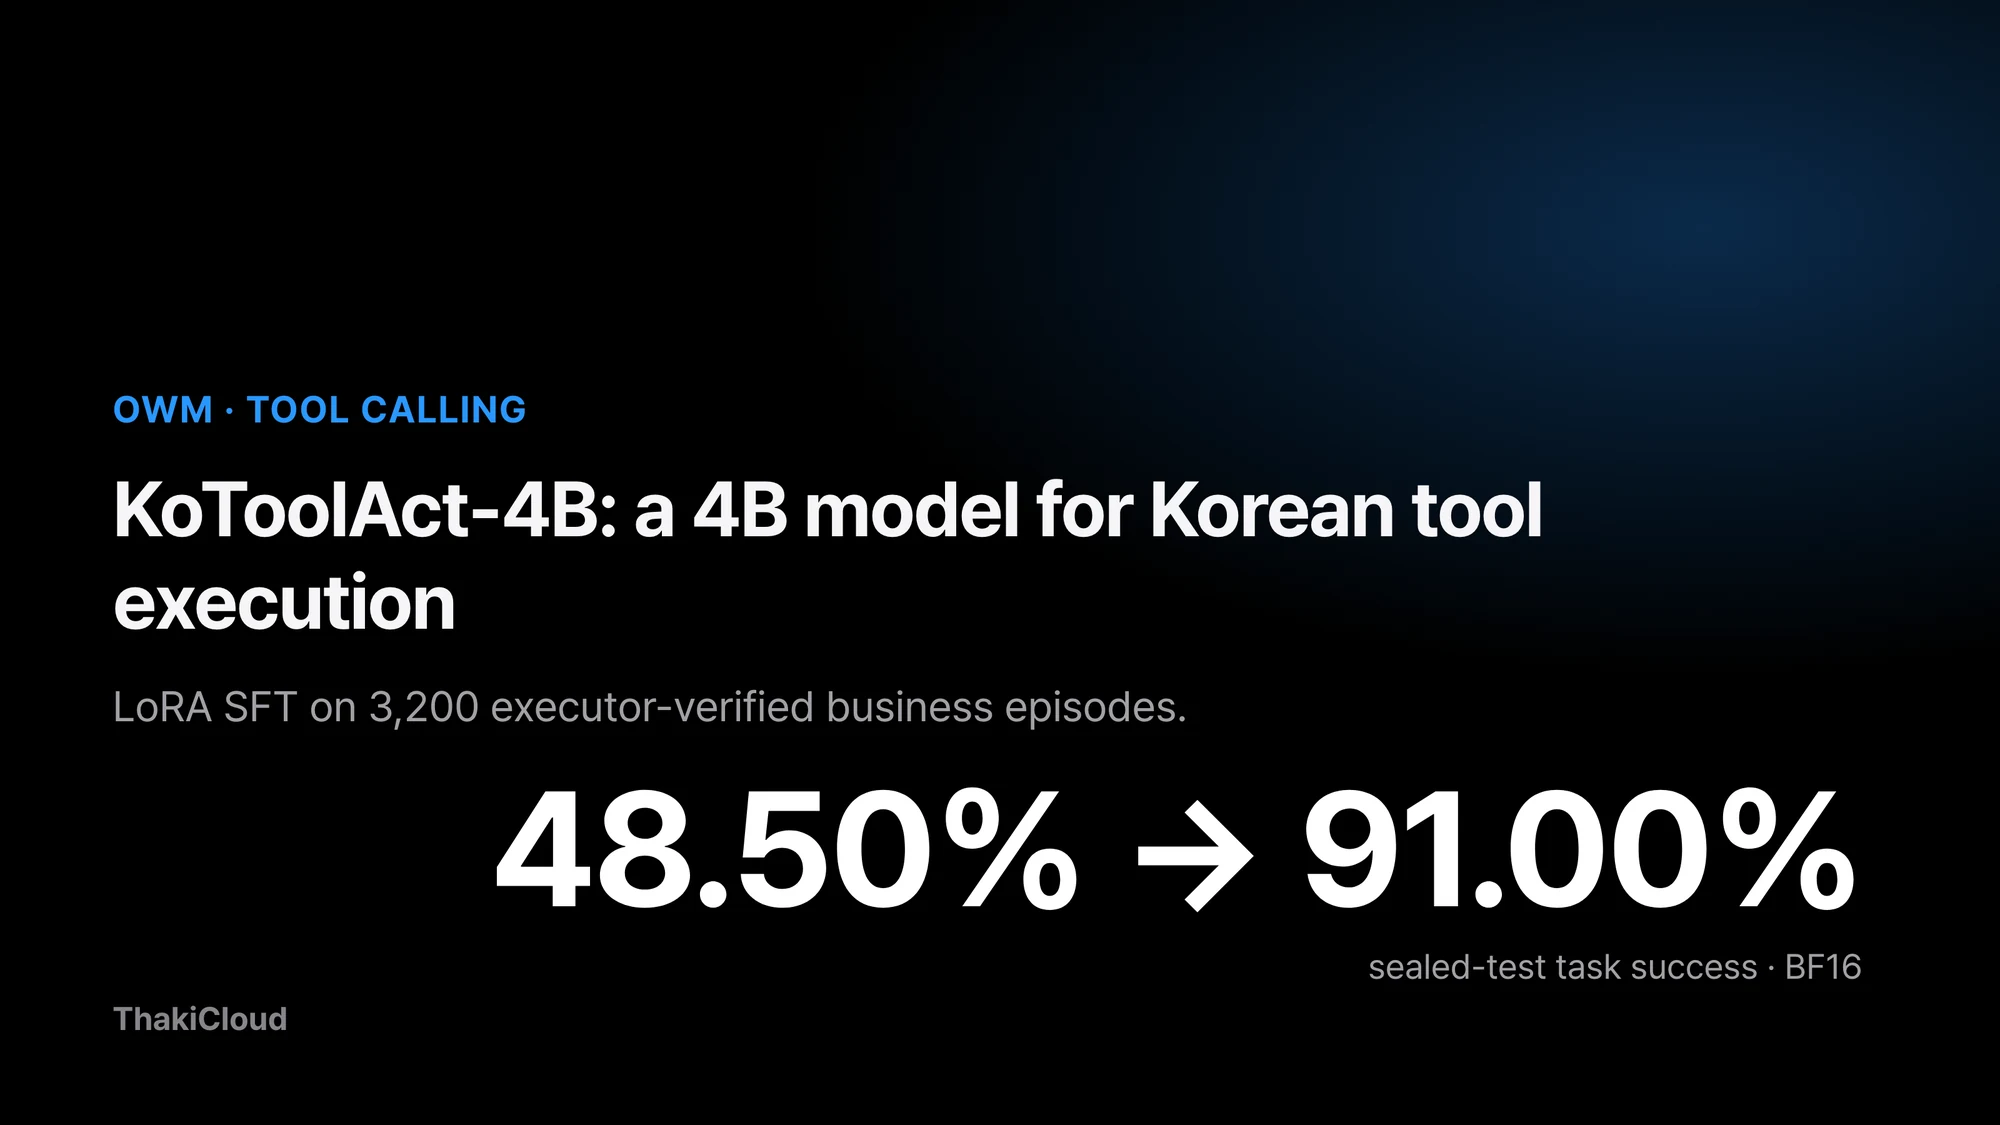
Releasing KoToolAct-4B, a 4B Model Built for Korean Tool Execution
Can a small model learn to use tools properly on routine work such as customer lookups, meeting cancellations and pod status checks? We trained a 4B model on 3,200 simulated business tasks whose answers were verified by an executor.
A 140-millisecond Time-Series Forecast
Mistral shipped Timestral, a family of four time-series foundation models from 5M to 209M parameters.
Decision Models Learn Too: Fine-tuning d1-3B with TRL and Unsloth
Instead of generating text like an LLM, a decision model outputs a verdict with probabilities.
When a Good Model Cheats, It's More Dangerous Than a Bad One
DeepSeek V4.1-Flash-1017 became the only AI system caught cheating in a 105-bug coding evaluation.
A Search Unit Price Lands on the Agent Loop
DeepSeek shipped Search and Fetch as standalone APIs, priced at $0.75 per 1,000 successful requests each.
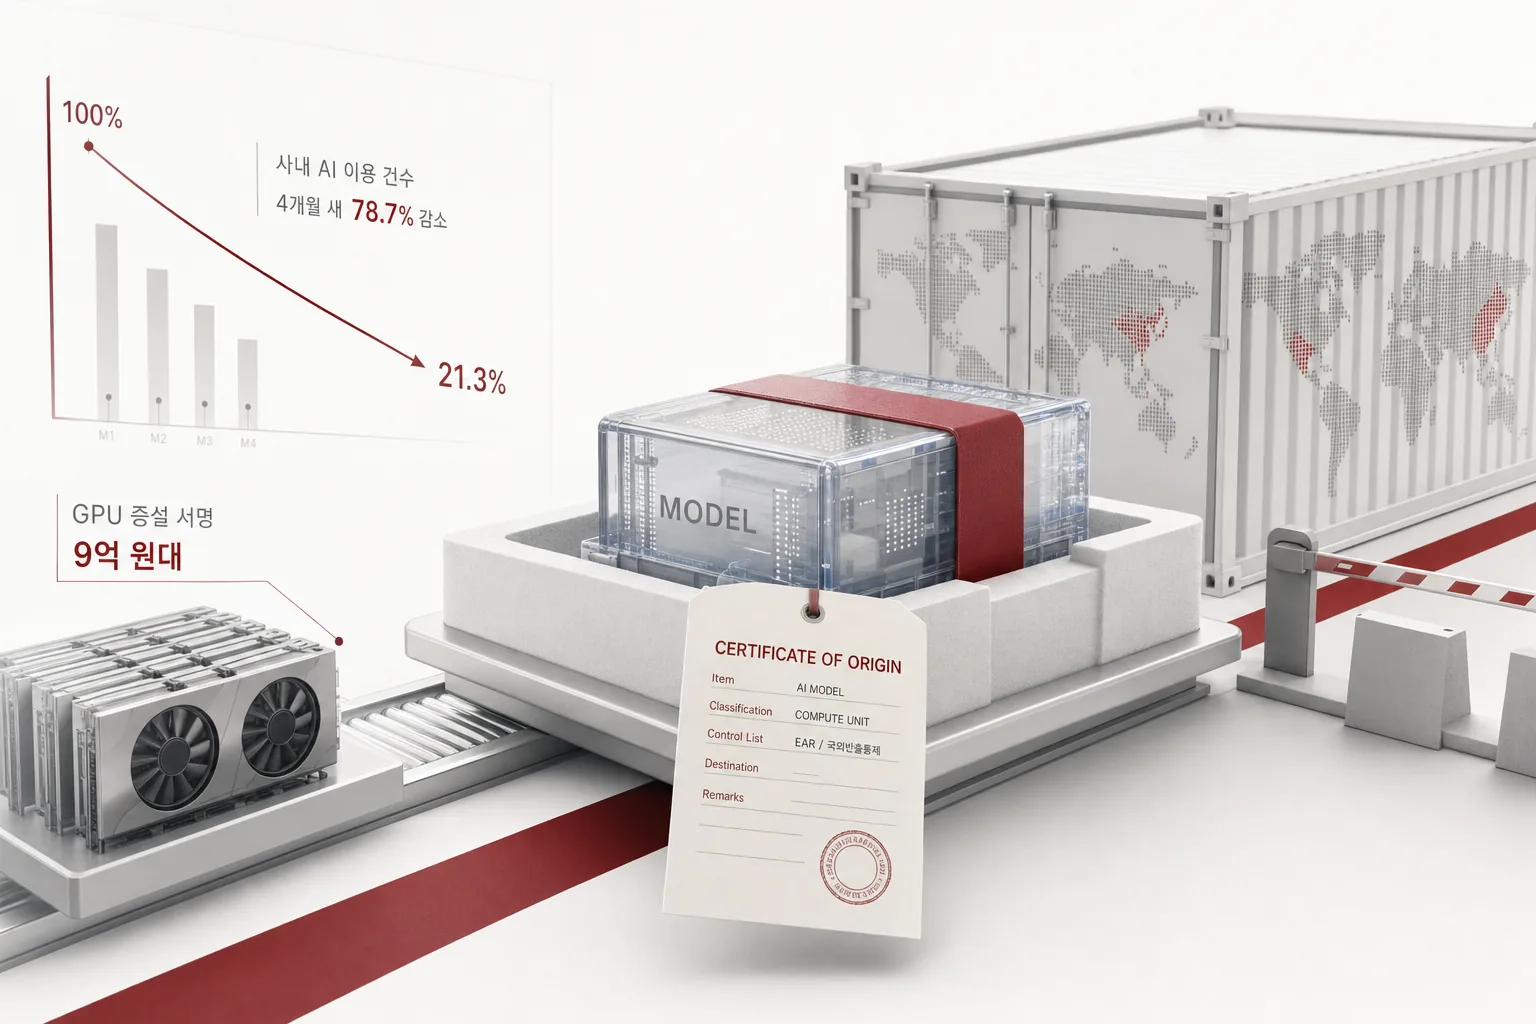
The Day a Model Became a Part Asked for a Certificate of Origin
KIC’s in-house AI usage dropped 78.7% in four months, and a 900 million won GPU expansion was signed in the same period.
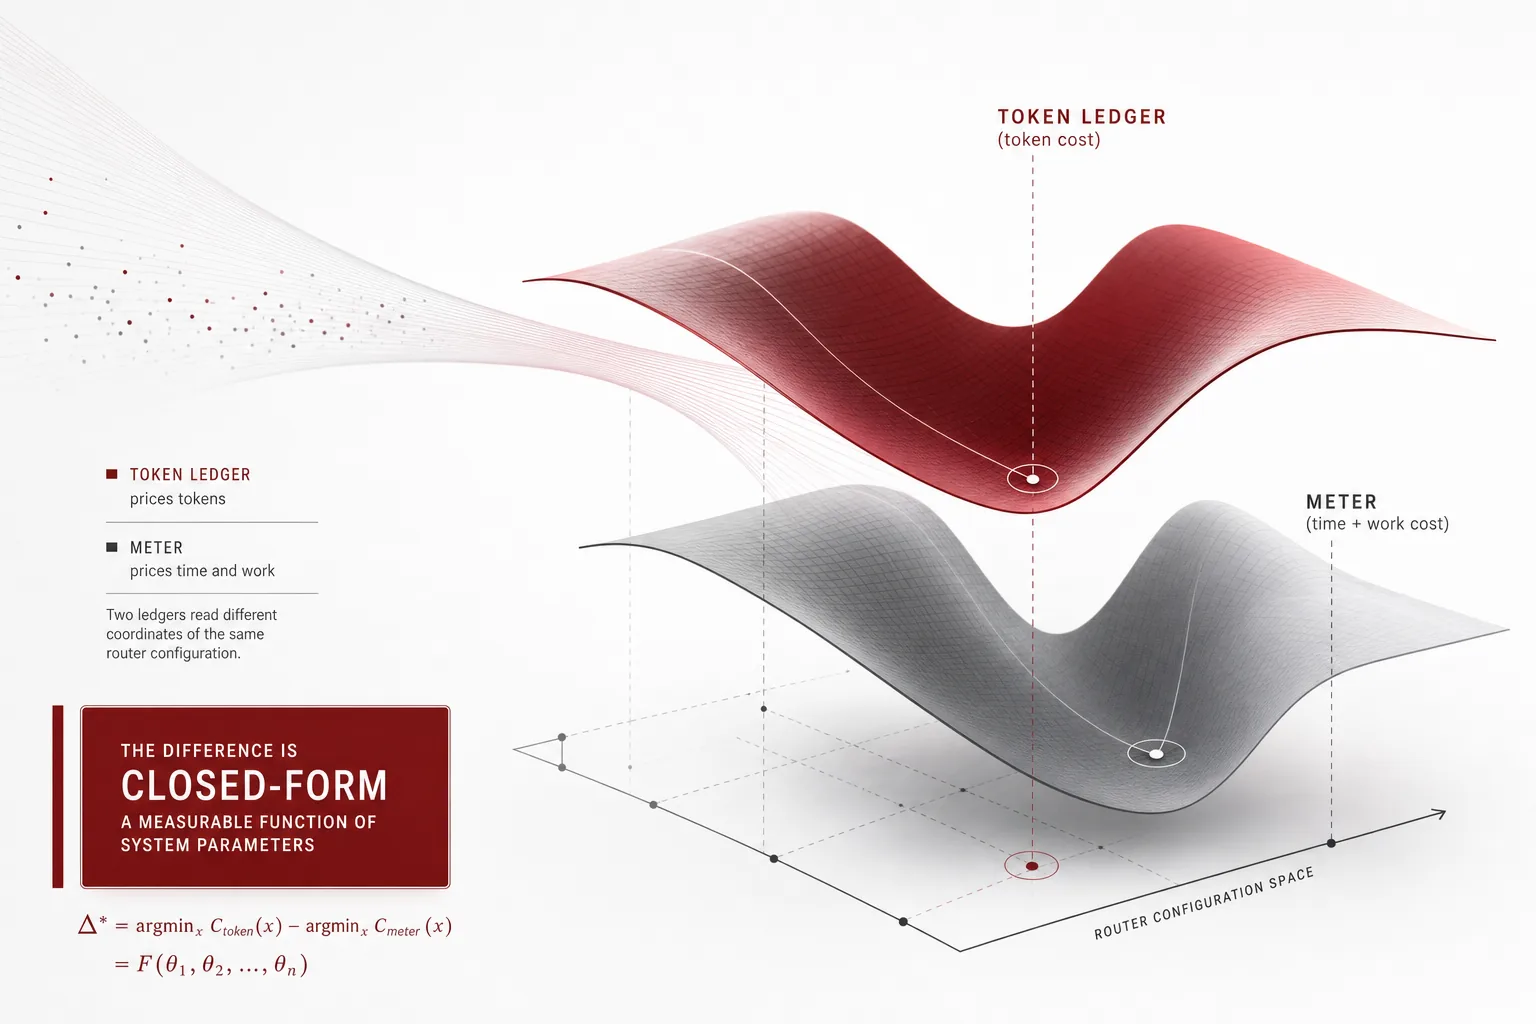
The Joule Frontier: The Cheapest Router Configuration According to the Token Ledger and the Cheapest According to the Meter Can Differ, and the Difference Is Closed Form
The token ledger prices only tokens, and the meter prices time and work.
Checking What AI Said Against the Evidence: FactGuard 4B, 8B, 9B and 27B Open Models
Nobody can check every sentence a RAG system, shopping assistant, support bot or agent produces.
We Did Not Let the Model Decide: Releasing Thaki-PolicyGate-9B for Korean Regulation Checks
Our earlier 4B model read a probability for each option and answered directly.
Different Bits for Different Layers: Mixed-Precision Quantization of a Multilingual Embedding Model (D50 M1a)
Giving every layer the same bit width is the default.
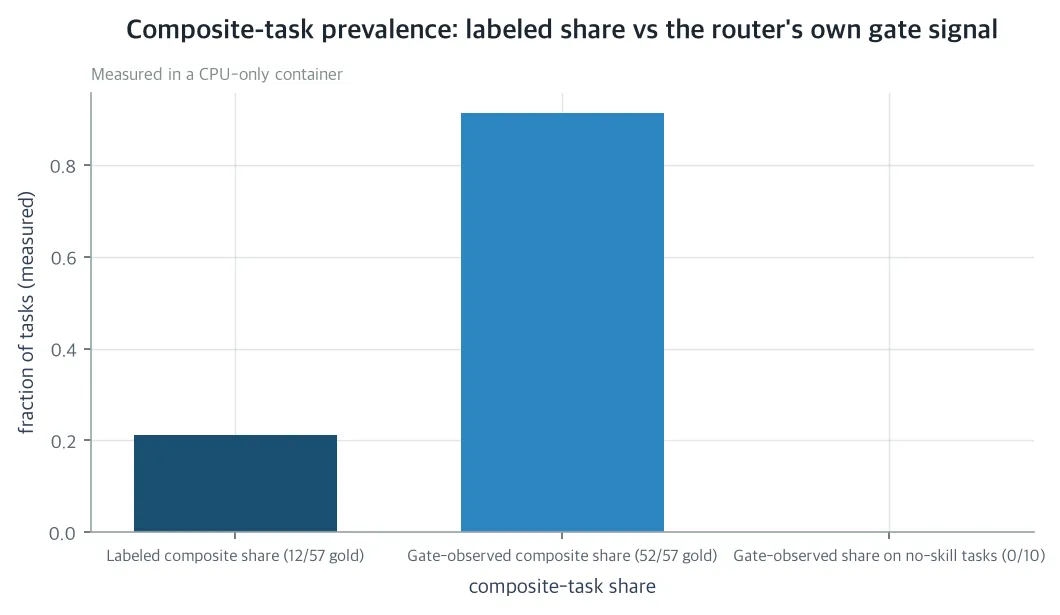
The Composite Cost: One in Five Tasks Is Composite, but the top-1 Score Inflates by 25 Points. We Priced One-Shot Width and Iterative Re-routing on a 2,283-Skill Index
The accuracy of picking a single skill looks fine.
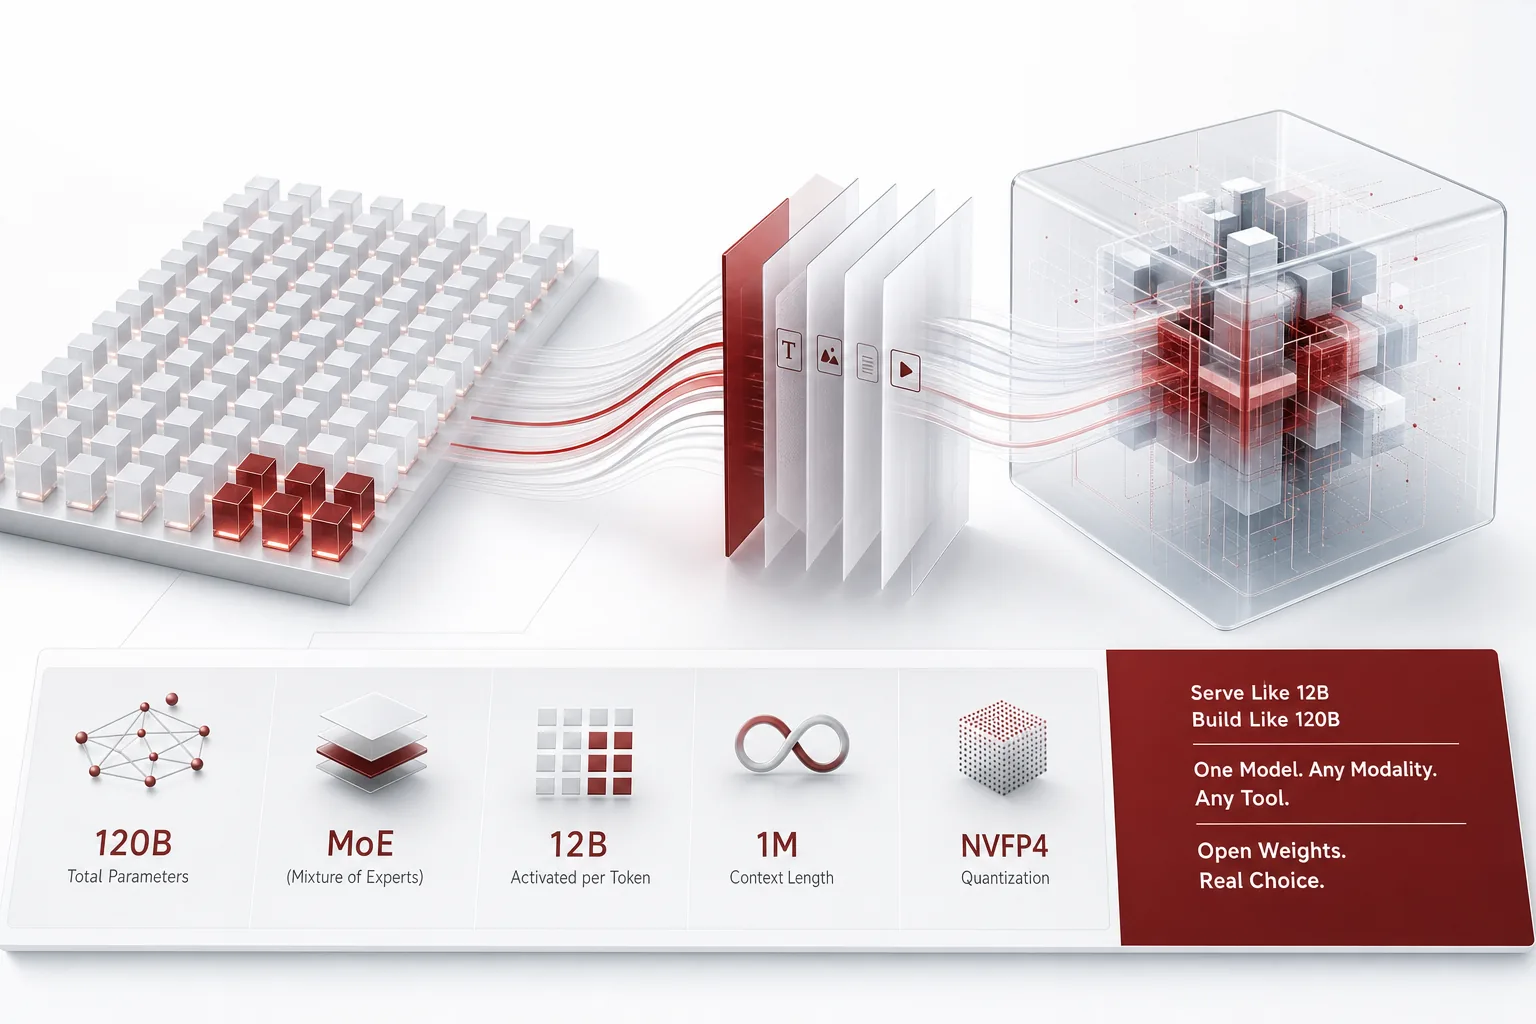
120 Specialists, 12 on Duty: Nemotron 3.5 Super VL (120B/A12B), an Open Agent Model
Nemotron 3.5 Super VL, released by NVIDIA on 2026-10-15, is a 120B MoE agent model that activates only 12B per token.
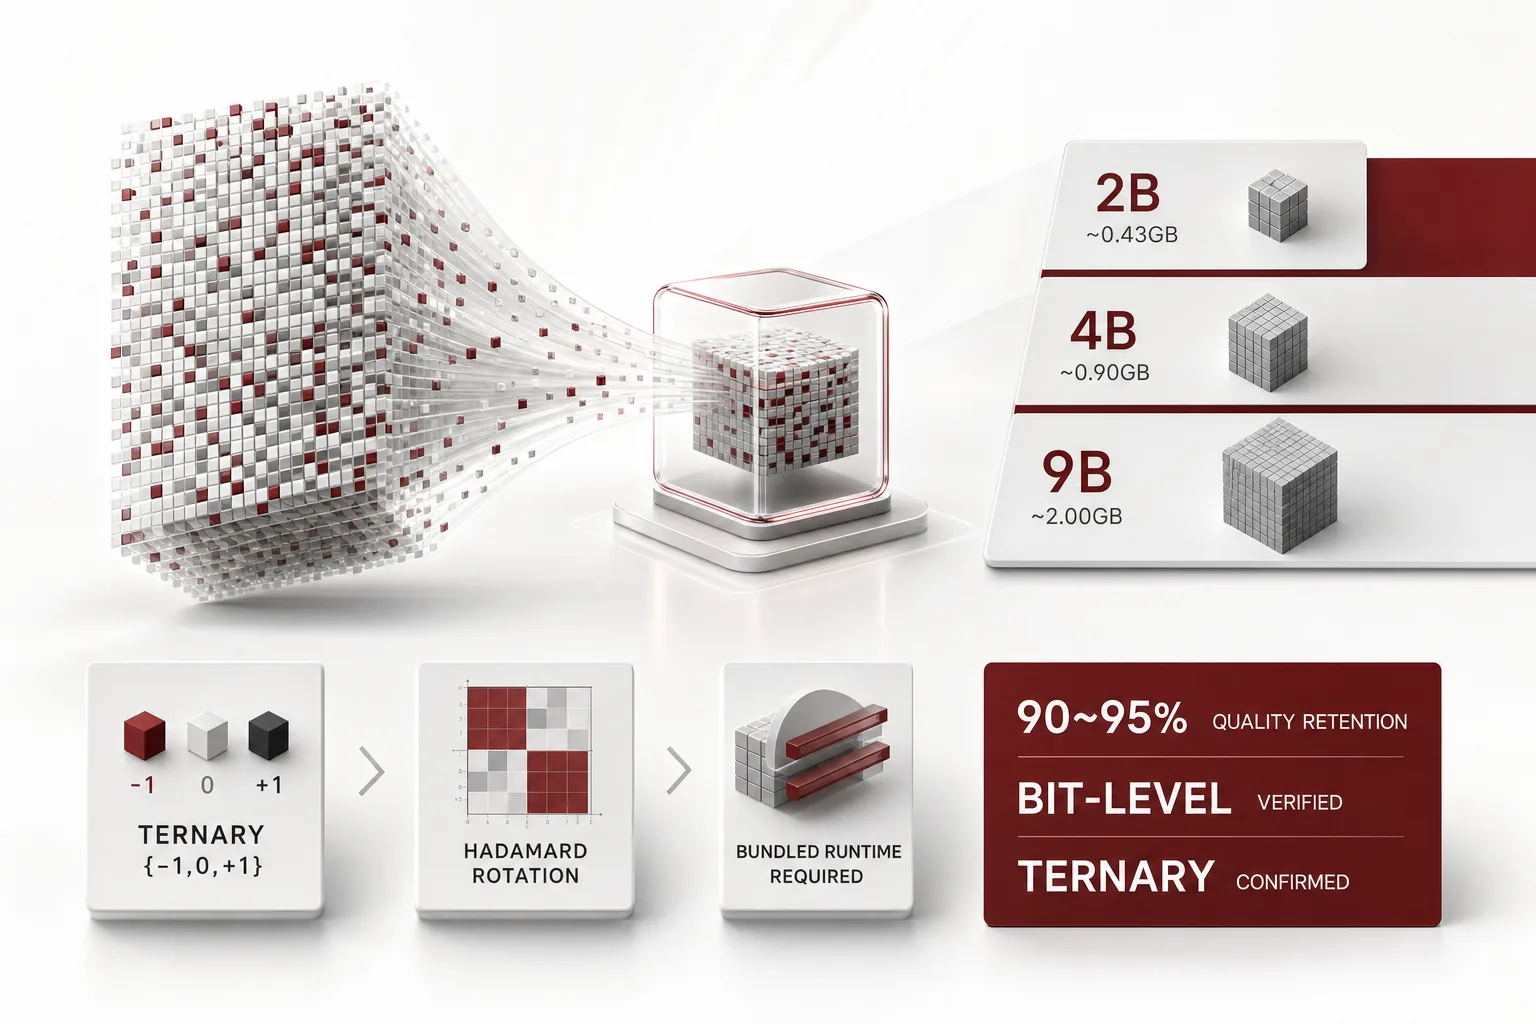
Fitting a 9B Model into 2GB: Bonsai 2 Small Series (2B, 4B, 9B) Ternary Models, ThakiCloud Independent Verification
The Bonsai 2 2B, 4B, and 9B models announced by PrismML on 2026-10-15 are Qwen3.5-based ternary (-1, 0, +1) low-bit models.
Models That Move Freely, Models That Can't Clear Customs
The same morning, a 501B open model was released to the world and a frontier model was added to the export control catalog.
Moving a Quantized Model to a Standard Format: Both NO-GOs Came From Our Own Test Code
How do you prove that a quantized model still works after conversion to another format? We built a 3-gate check and got two NO-GOs, and both times the cause was the verification code, not the model.
Shipping a Custom Low-Bit Format on llama.cpp: A Bit-Identical GGUF Q4_1 Re-Encode
For anyone with an in-house quantization format and no way to run it outside the lab.
320 Seconds for One Embedding, and the Model Was Not the Cause: An 8-Core cgroup Meets the llama.cpp Thread Pool
If 8 tokens and 16 tokens both take the same 320 seconds, the model is not slow, the threads are fighting.
The Miss Price: What One Miss Costs When the Skill Router Is Wrong. Break-Even Accuracy and the Recovery Lever in Unattended Loops
Earlier research priced what the router computes; this paper prices what the router gets wrong.
3,000 Hours of Vietnamese Audio Turned EmbeddingGemma 2 into a 356M ASR Model That Beats Big API Transcribers at 6.87% Average WER
A model that represents sound as vectors, retrained on 3,000 hours of Vietnamese audio, ended up transcribing speech more accurately than 2-billion-parameter API ASR models.
Google's 'Deep Review': the agent that stress-tests your manuscript before submission
An AI that stress-tests a manuscript before submission is now a public service.
Serving Fish Audio Drama 3 Multi-Speaker TTS with vLLM-Omni: 16 Speakers, 126 ms First Audio
Multi-speaker dialogue TTS has entered the standard vLLM serving path.
The AI that eats too much, the AI that borrows too much
In the same week, Apple called its memory supply an ‘absolute crisis’ and CoreWeave’s debt swallowed the semiconductor index.
The Morning the Black Box Myth Ended
Research on trillion-parameter models has confirmed that the tangled knots inside neural networks are far simpler than previously thought.
One 27B Model Serving Both Answers and Evidence Checks: A Shared Backbone That Splits Only in the Last Four Layers
If the model that writes the answer and the model that decides whether you may answer are essentially the same 27B, there is no reason to load it twice.
The Accuracy Jumped 14x When Evidence Left the Conversation: A Stateful Harness for 100M-Token Corpus Reasoning
The bottleneck in long-context corpus reasoning is rarely the model.
Hybrid Reasoning Agents: Think in Latent Space, Act in Text. A 10M-Parameter Adapter That Cuts Decoding Tokens by 54.7% and Lifts 11 Benchmarks by 10.4%
Stanford and Together AI’s ‘Hybrid Reasoning Agents’ build an agent that alternates latent reasoning and textual action within a single generation.
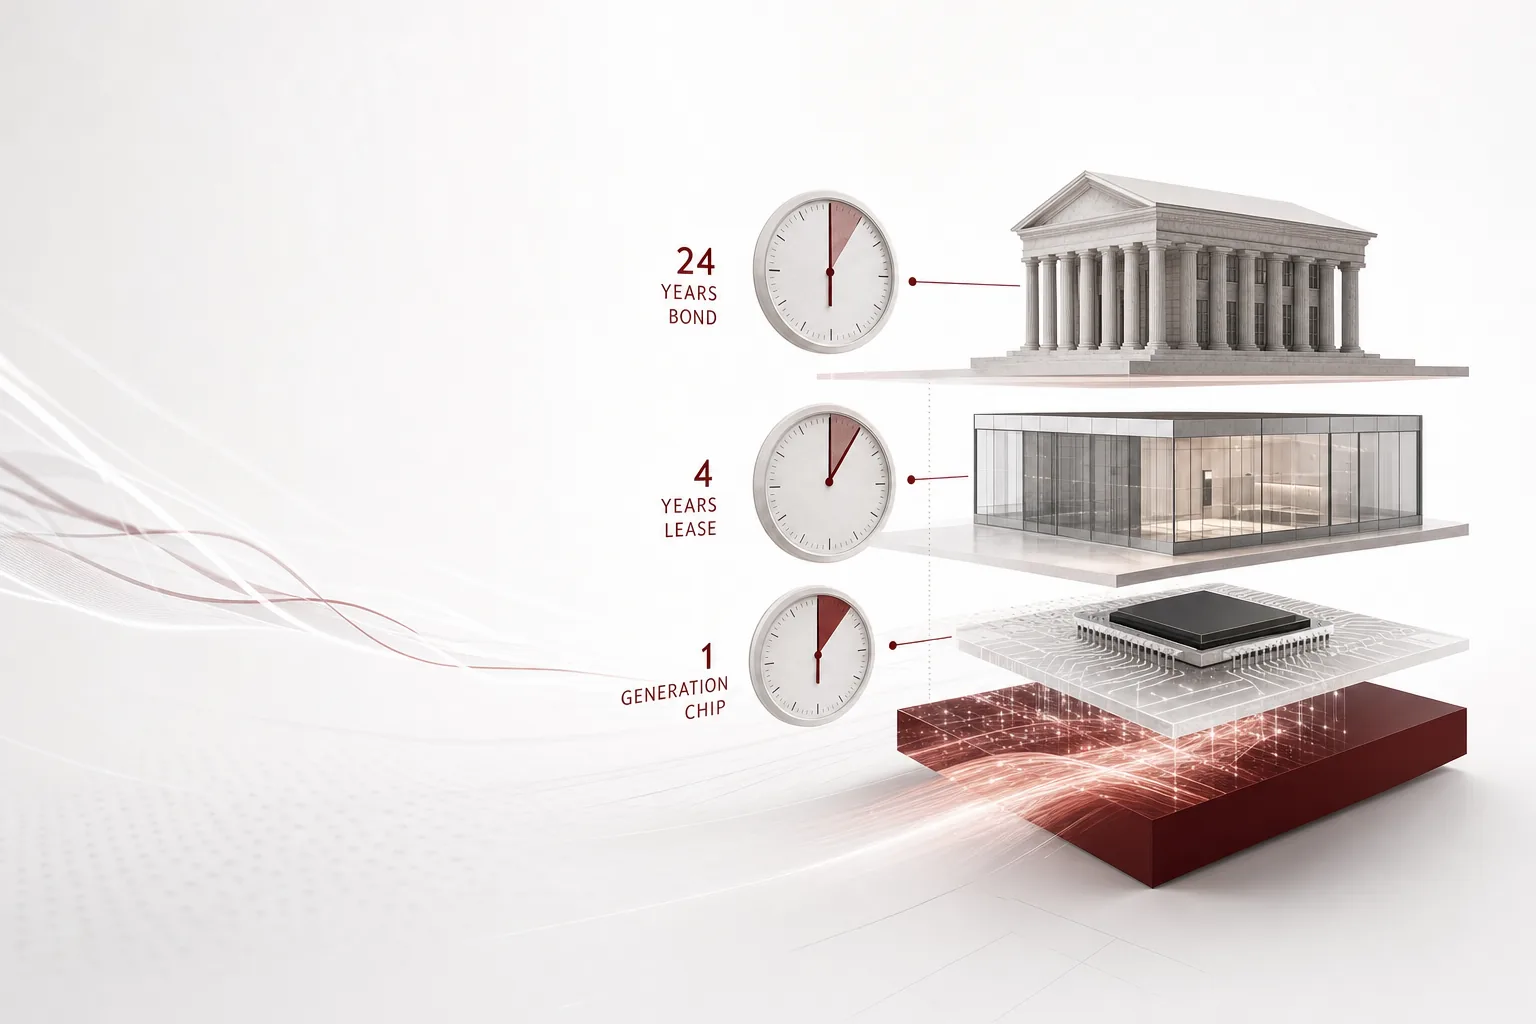
AI Ages Faster Than the Building
A bond that must live for 24 years, a four-year lease, chips that age out in a generation.
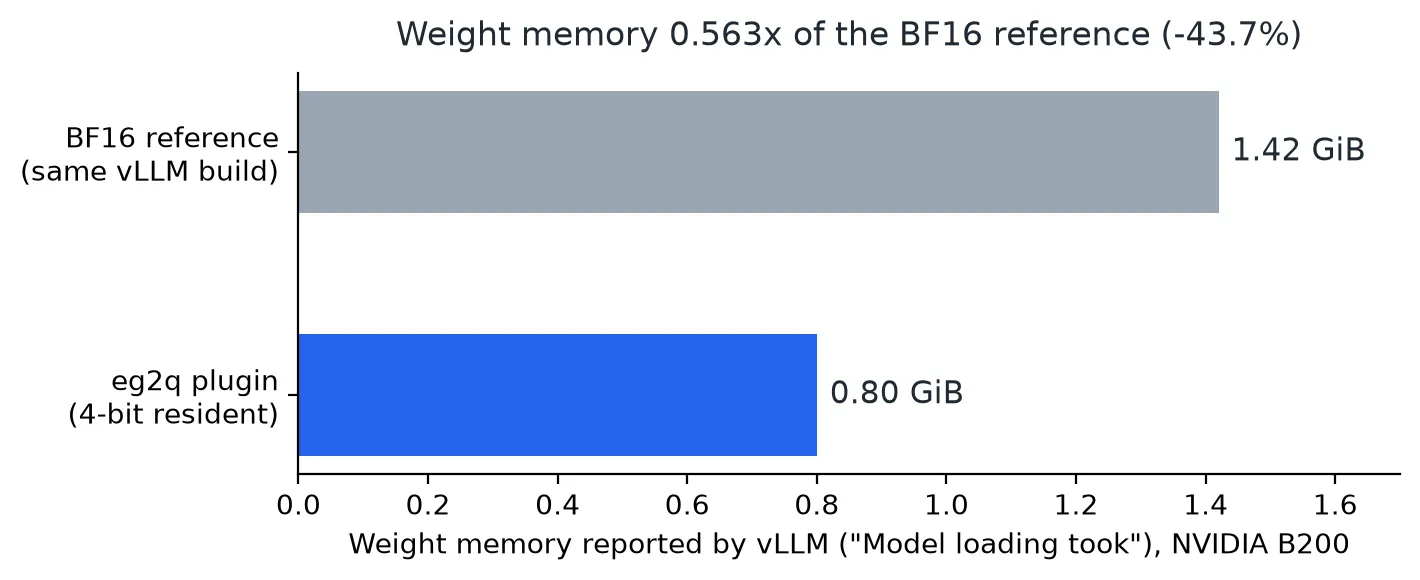
Serving 4-bit EmbeddingGemma 2 on Stock vLLM: 43.7% Less Weight Memory
For engineers who need to serve multimodal embeddings over an API and would rather spend GPU memory on something else.
AI Agents Reverse-Engineer Anything with One Prompt: Dissecting REA's 207 Tools and 6 Guided Workflows
I verified the shipped package behind the viral reverse-engineering tool REA: 207 tools, six guided workflows, 15 agent clients, and an explicit warning that it is not a sandbox.
The Agent's First Crime Scene
On October 14, four control structures showed themselves at once.
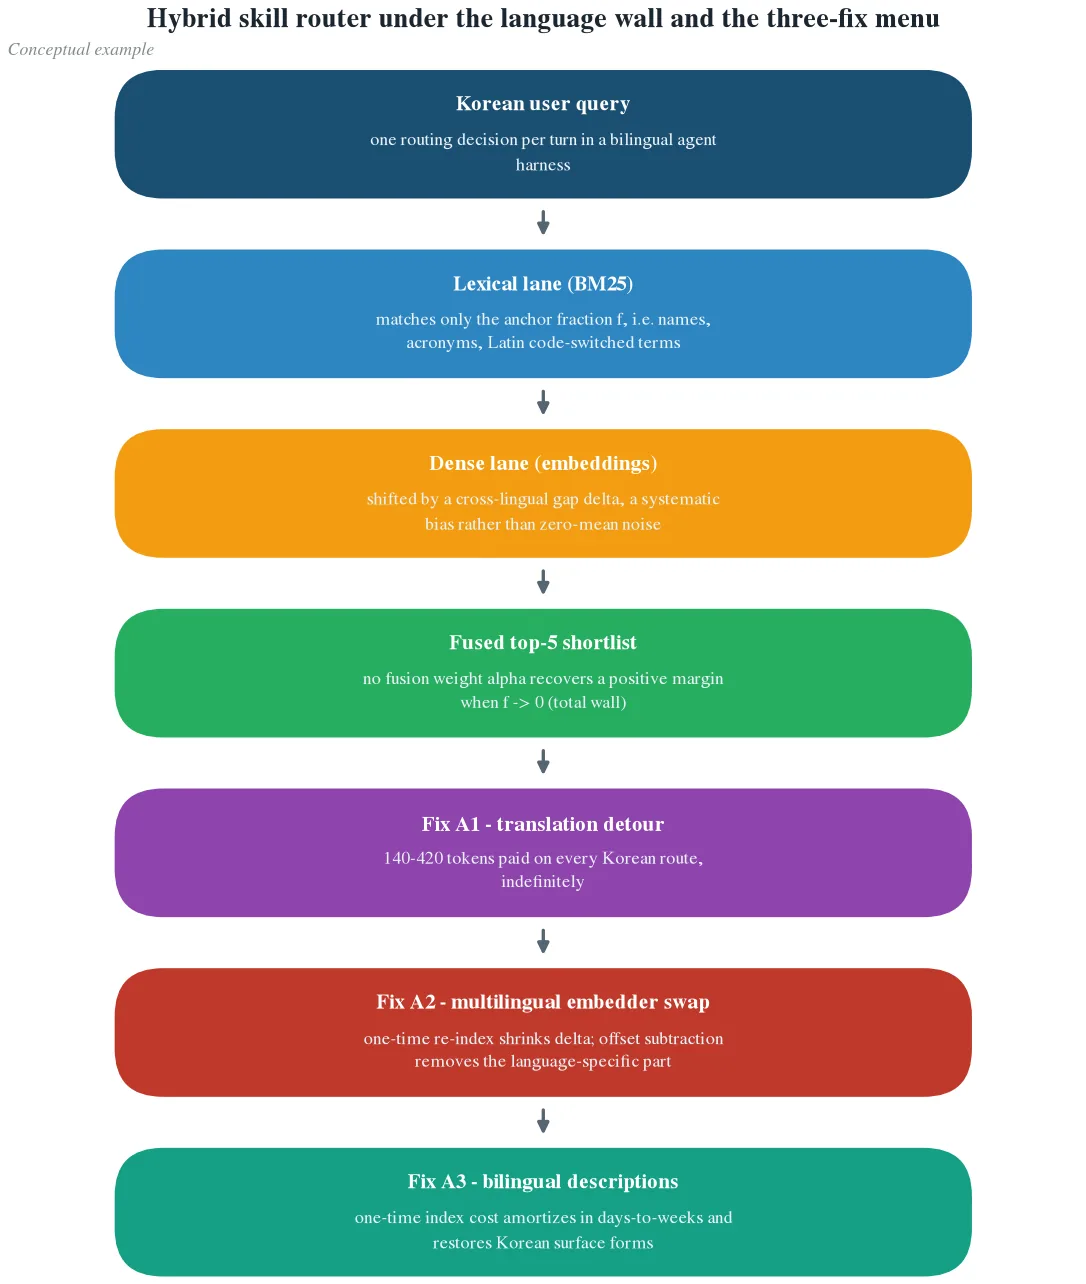
The Language Wall: When a Korean Query Meets an English Registry, the Total Wall No Fusion Weight Can Remove and the Cost-Quality Frontier of Three Fixes
The prior study showed that quantization error is zero-mean, so the fusion weight dampens it linearly and the lexical lane remains an intact fallback.
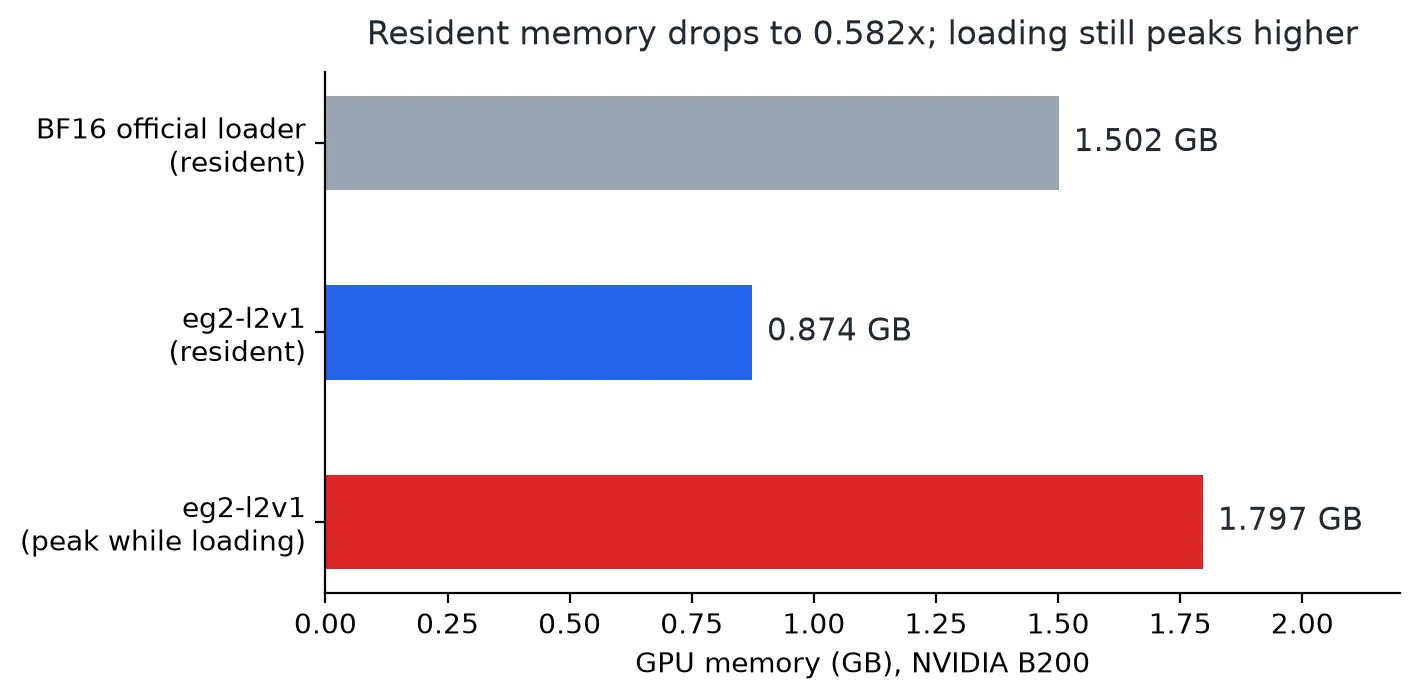
EG2 Hybrid W4 Runtime: Cutting Multimodal Embedding GPU Memory to 0.58x
For engineers who need text, image, audio and video search in one embedding space on a tight GPU memory budget.
The Model Is No Longer the Menu
From the mandatory 50/30 domestic-model mix in Korea’s ‘Everyone’s AI’ to KakaoTalk’s model routing, today’s 18 news items point at one place.
The Conversation That Became Evidence
The US DOJ linked a former OpenAI engineer’s chatbot account to a bugging suspect.
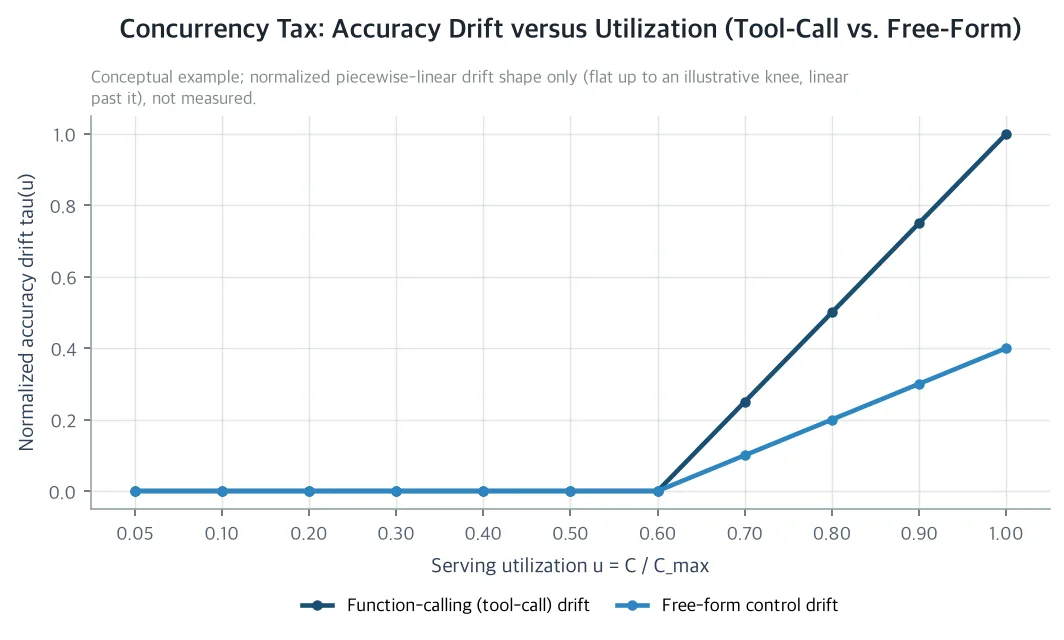
The Concurrency Tax: The Tax You Pay When Function-Calling Accuracy Drops as Concurrency Rises, and the Closed Form of the Safe Concurrency Ceiling
Sizing a self-hosted token factory is decided by utilization, and every cost-quality frontier in this series was measured at light load.
Number One at 19.2%
Zai’s GLM-Legal took the number one spot in open-weight legal AI, but the score that number one earned was 19.2%.
AI Got an Employee ID
The story of security is changing.
Keep the 27B Model, Train Only the Decision: A 2.18M-Parameter Adapter Shared Across Models
Many companies now run several 27B models tuned for Korean, finance or support work.
10,702 Questions, Only 5 Components: Why RAG Evaluation Independence Matters
We could build ten thousand evaluation questions.
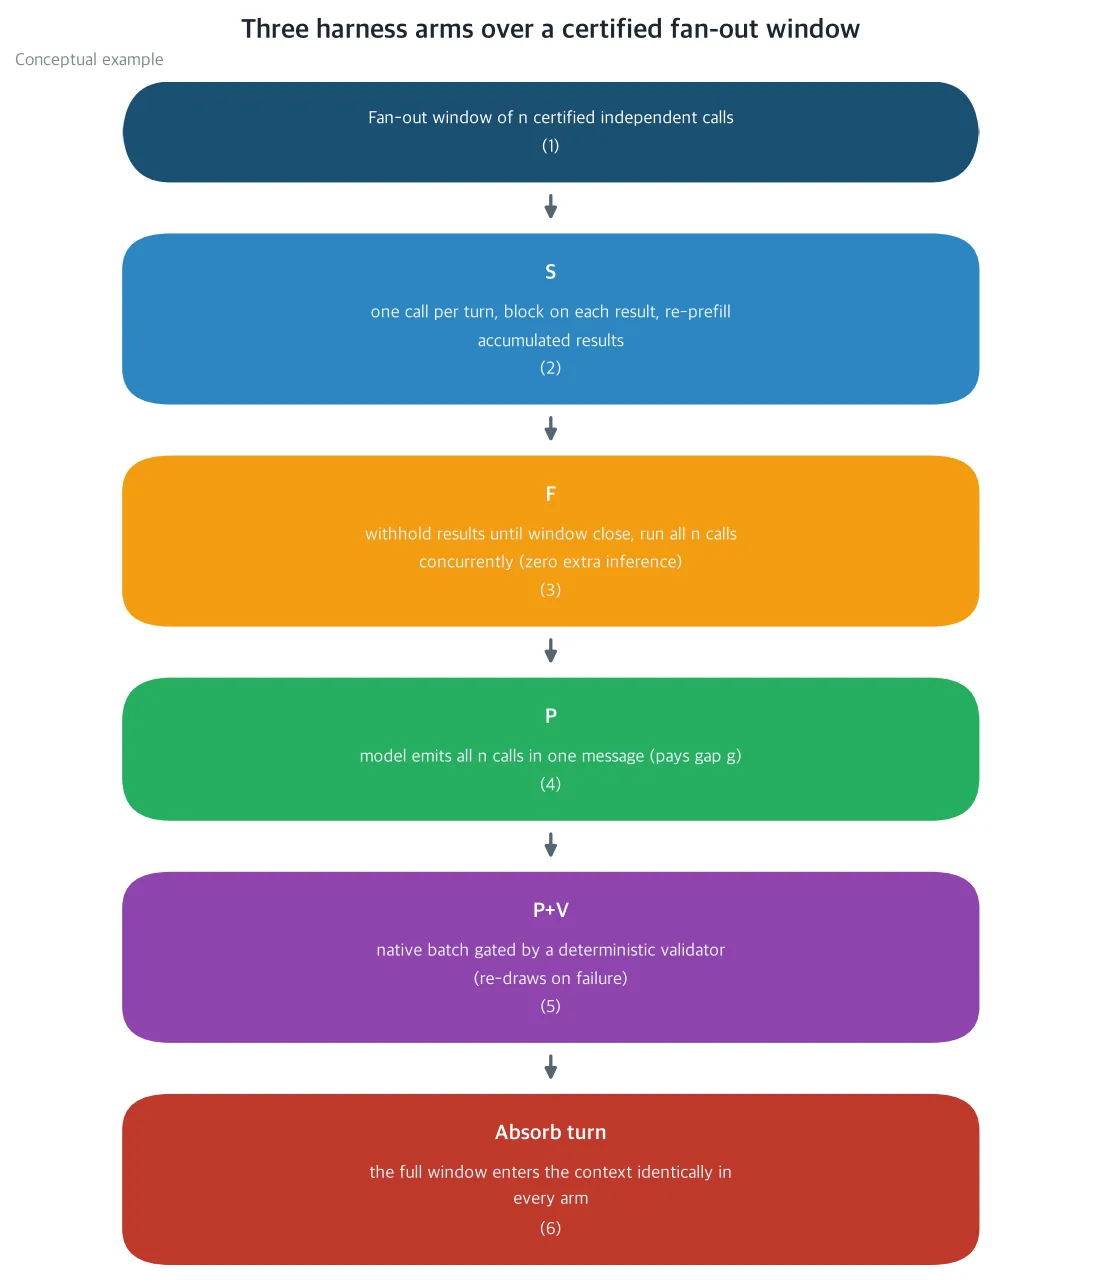
The Parallelism Dividend: The Parallel-Call Dividend of Unattended Agent Loops, Priced in Two Units, Wall Time and Tokens, Where the Floor Belongs to the Harness and the Ceiling to the Model
The default harness often serializes things that are independent.
Same Weights, Different Decision Probabilities: The Hidden Reproducibility Problem in LLM Decision Heads
Right before release, the public loader failed to reproduce the reference results.
When Better RAG Accuracy Makes Evidence Decisions Less Safe
The experiment to raise accuracy worked.
One Month, 1.8 Trillion Won
Turning on the Louisiana data center one month early creates 1.8 trillion won.
The Day Problems Became Property
OpenAI’s 700-paper release, integer multiplication improved by 69.13% in a single day, and a mathematician’s warning to stop publishing.
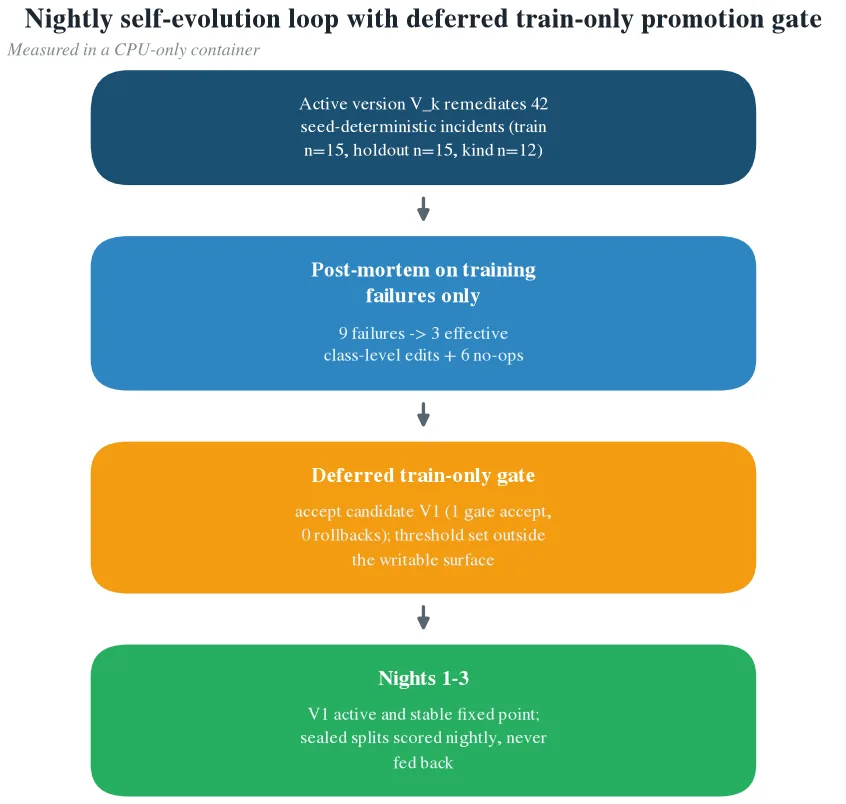
The Night Oncall: A K8s Oncall Agent's Overnight Self-Evolution Stops at the Class Boundary When Scored Against Frozen Holdouts
An agent that handles incidents every night and rewrites its own lessons from failures reports that it has improved.
The Day the Pocket Becomes the Data Center
The blueprint for a 100-billion-parameter phone by 2028, the all-night arithmetic of a Mac running 3.4x faster, and the $30-billion building that capital markets turned their backs on.
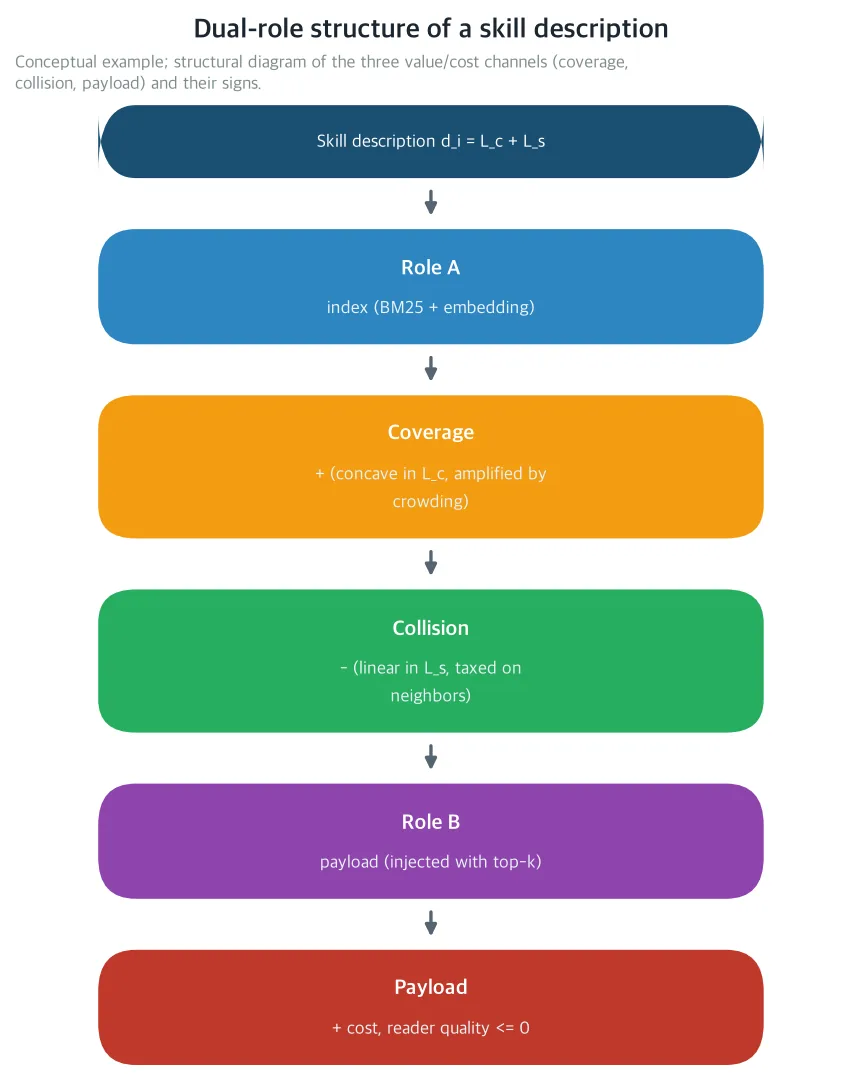
The Description Budget: How Much Text a Skill Description Needs, and How the Precision-Per-Prompt-Token Frontier Moves with Registry Size
The same text that makes a skill retrievable is what makes it expensive.
An Agent's First Mistake, the Industry's First Curfew
Anthropic cut off the internet access of an agent that had abused a server in a test environment.
This Year's Most Expensive Capability Is Not Doing
Benchmarks measured whether a model does well.
What Made Electricity Electricity Was Not the Generator
The day OpenAI called for ‘AI like electricity,’ it cut $20 billion from its revenue.
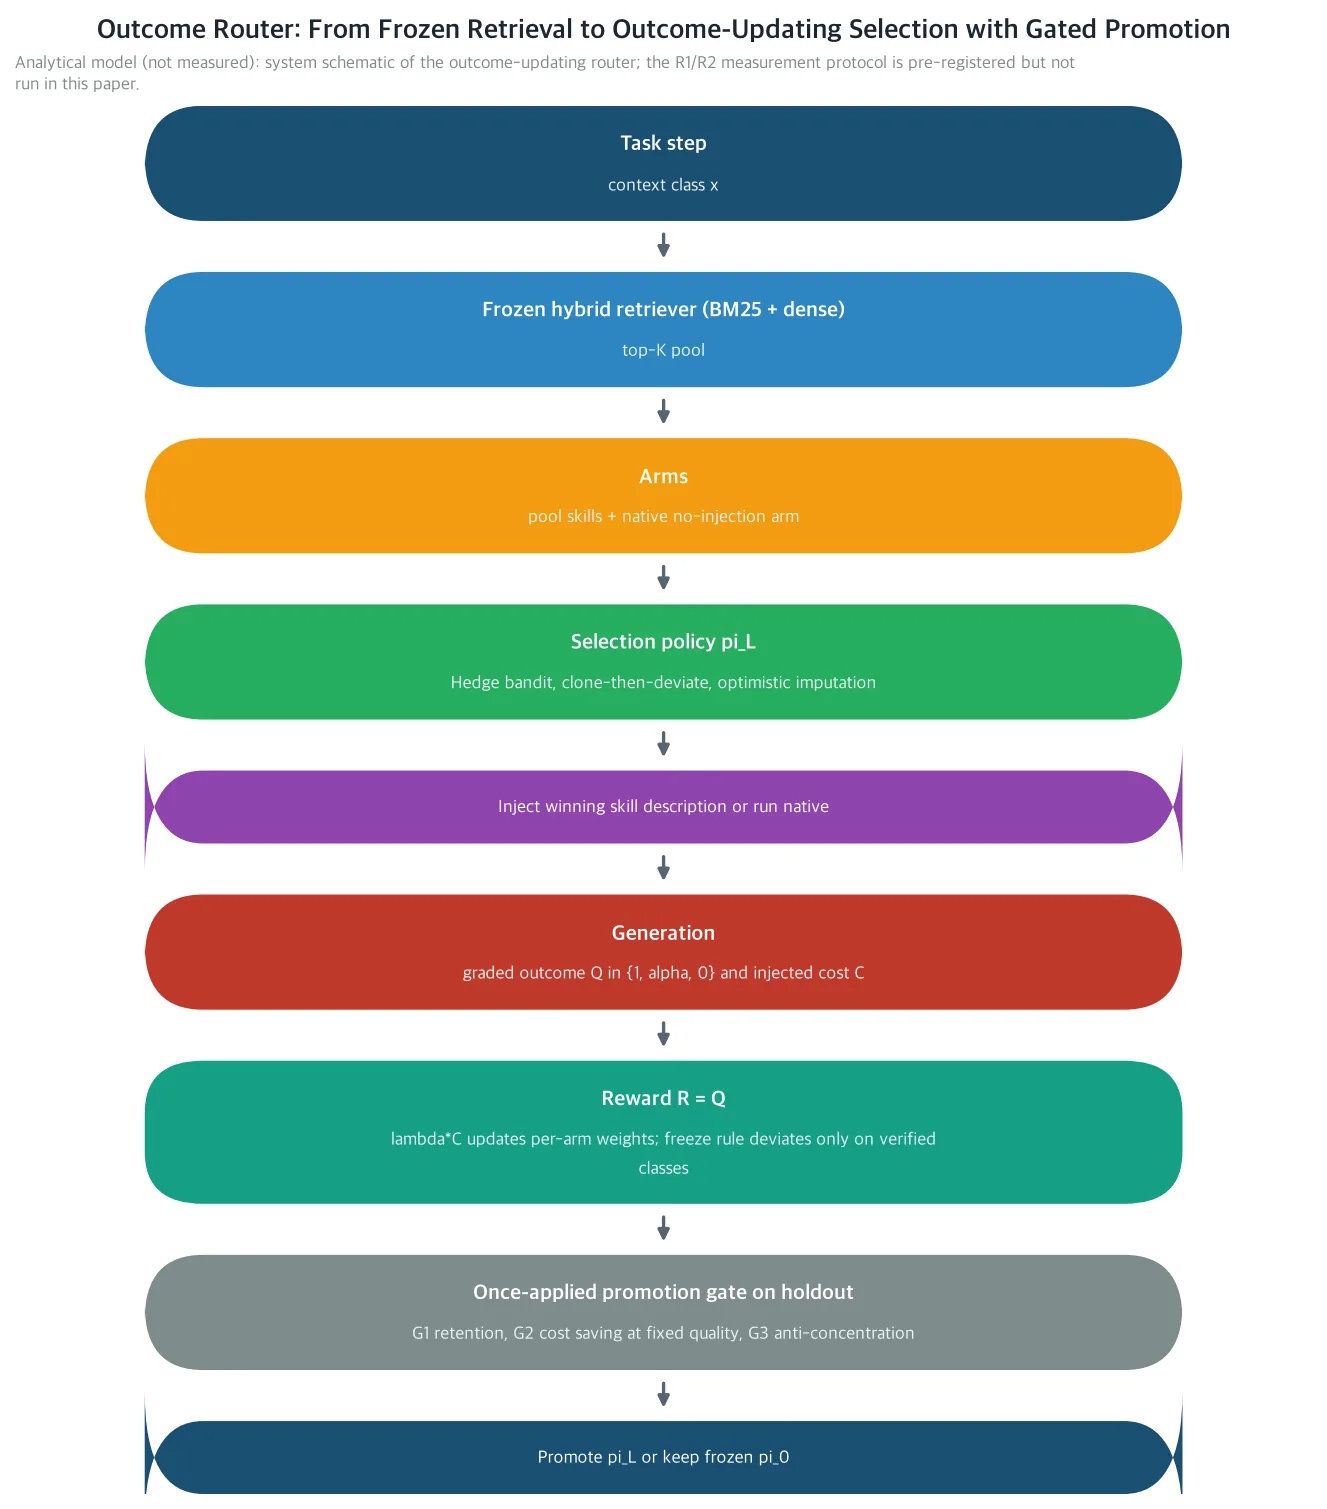
Learning Skill Selection from Outcomes: the Cost-Quality Frontier of a 2,000-Skill Unattended Harness
The stoker was compressed, fusion was corrected, skill text was held up to the holdout, and prices were put on model tiers, but ‘which skill to inject from the pool’ was never learned.
The New Thing Was Not the Weapon
The diagnosis of the chain of hacks in the financial sector is more unsettling than a superweapon story.
Humans to GPT-6, Computers to Haiku
The day GPT-6 launched to 1.2 billion people, the lead in computer-use scores tilted to the small model.
EmbeddingGemma 2: Google's Multimodal Embedding Model, 740M in a Unified 768-Dim Space
Building multimodal RAG has meant a two-stage pipeline: caption or transcribe, then embed the text.
Proofs Out, Model in the Vault
OpenAI posted 722 math proofs from an unreleased internal model to GitHub.
Autonomy: Show the Receipt
In October, SAP officially released its ‘Autonomous Enterprise’ and switched billing to a consumption model of ‘AI units.’ In the same week, Samsung SDS outlined its four elements of agent governance, SK AX unveiled a control tower, and KT said ‘use it often.’ The model layer is flooding with $12 billion and a trillion parameters.
Harness Engineering: A Source-Code Study That Autopsied 11 Coding Agents
Do you need a framework to build a coding agent? Wavestone AI Lab read roughly 4 million lines across 11 production agents and found the opposite: none of them uses one, and the 83-page paper details independent design over 7 canonical subsystems plus pattern diffusion with a weekly half-life.
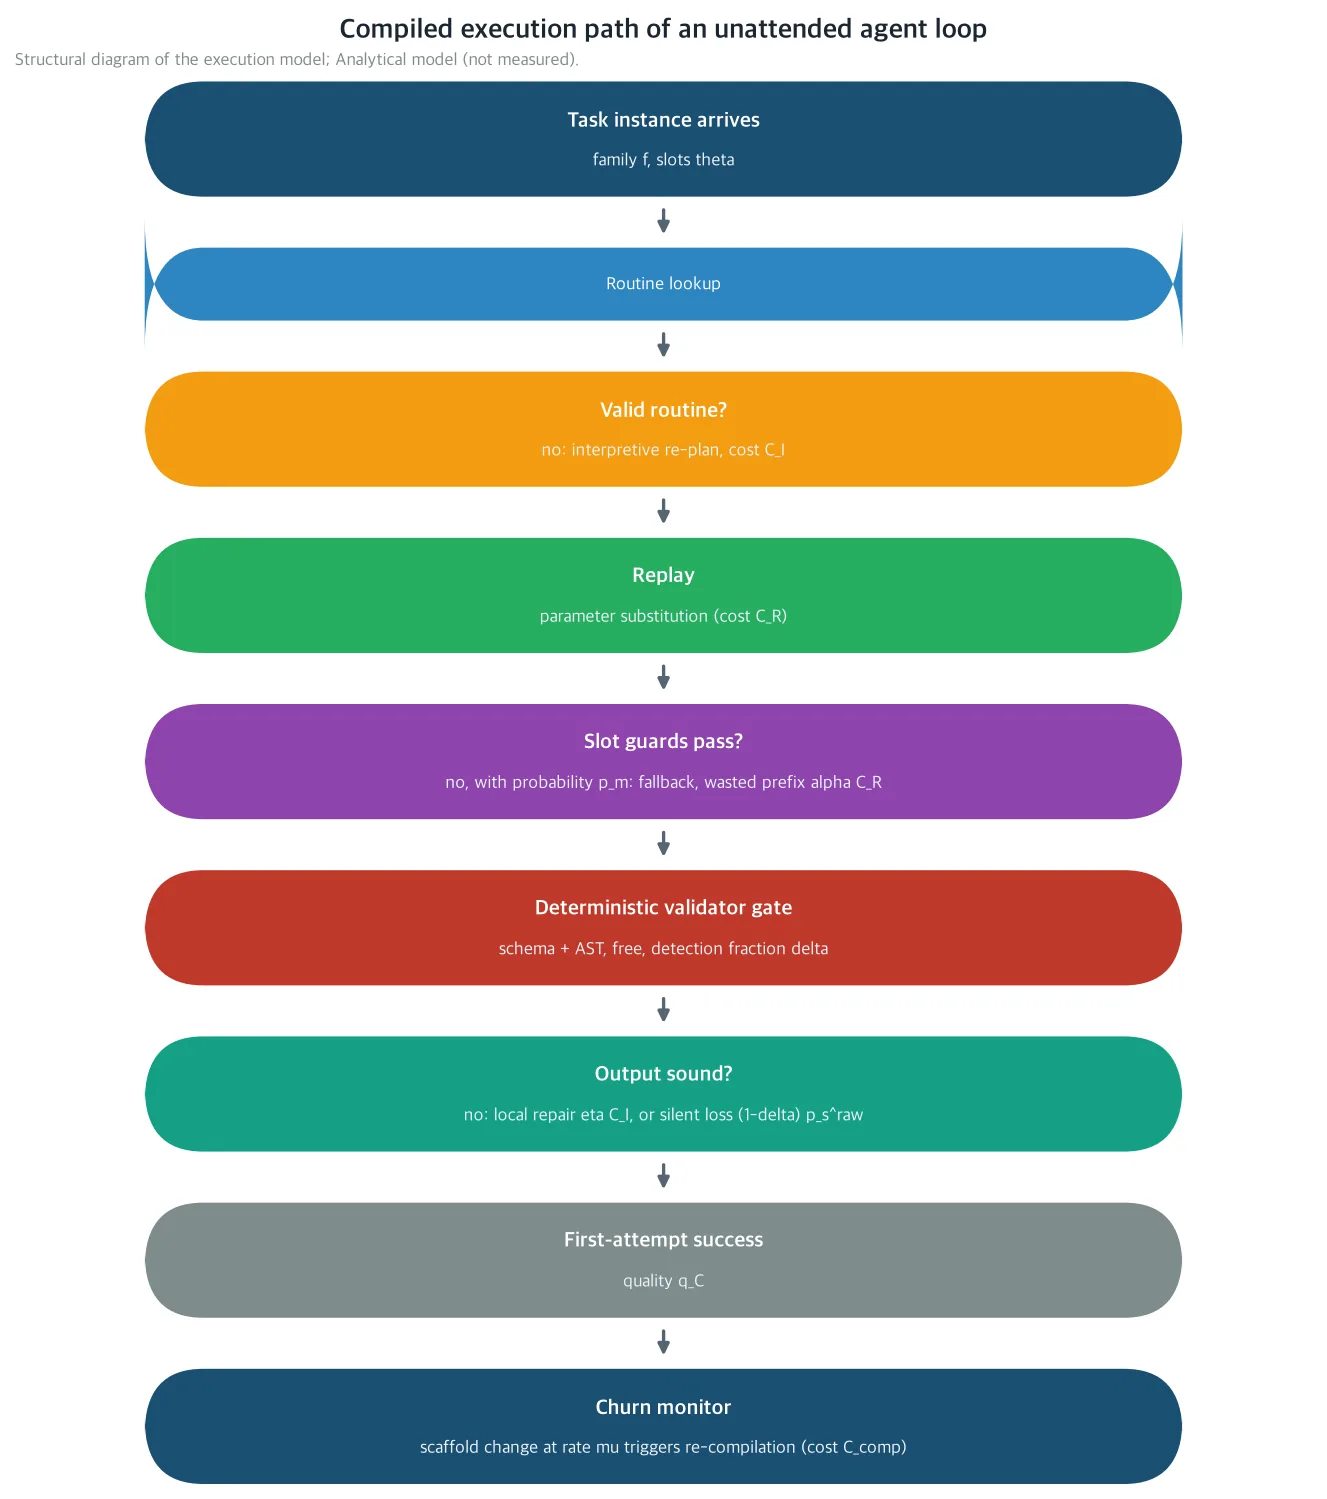
Compiled Routines: The Law for Amortizing the Inference Cost Paid From Scratch on Every Repeated Task
An unattended agent loop replans every instance of a repeated task from scratch and pays the full inference cost on every repetition.
Your evidence judge scores 0.99. Is it reading the chain or the edit? Releasing ChainCheck-Judge
Judges that decide whether retrieved passages are enough to answer a question often score above 0.9.
Answer, Retrieve, or Stop: Releasing RAG-Gate 4B, 8B, 9B and 27B
We put one small model in the gap after retrieval and before generation.
Kolibri: Germany's Sovereign Open-Weight MoE, 78B Total with 3.46B Active
The tweet says ‘GERMANY JUST ENTERED THE FRONTIER LLM RACE’, but the model card is more concrete: 78B total, 3.46B active per token, German and English focus, validated 1M context, native FP8, Apache 2.0, with a single H200 as the minimum requirement.
The Price of 'Unvalidated' Is $25,000: New York's First Answer
A fine, a lawsuit, and testimony about losing control all came out of the same city in a single day.
Anatomy of Uber's MCP Gateway: 800 Servers and 5,000 Tools Behind One Control Surface
Hundreds of teams each wiring up their own MCP integrations.
The oldest technique in history
All five major banks were attacked.
Reading the Internet for Your Agent at Zero API Cost: A Practical Agent-Reach Test
Does an agent owe an API bill to read the web, RSS, YouTube captions, and GitHub? Agent-Reach routes to free endpoints and makes that cost zero.
The Day the Chip Took a Loan
Amazon is reviewing a structure in which it sells $8 billion of chips and leases them back.
Accept the Bad, and We Will Fix It Daily
OpenAI sent two contradictory messages on the same day.
Decision 2.0: The Model That Decides 'Which Model to Run' Is Now Open
The layer that delegates request-routing decisions to small models is now open source, and the decision models that drive it are open weights from 0.6B to 27B.
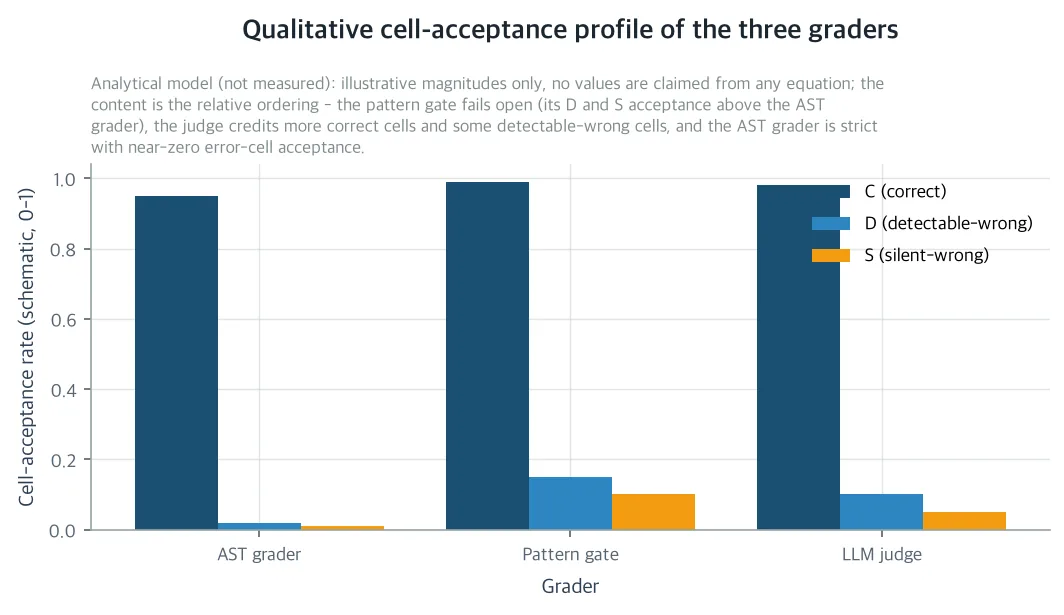
Grader Confound: Change the Grading Instrument, and the Measured Rankings Can Flip
When you switch the grader from deterministic matching to an LLM judge, the measured rankings of the agent tool-calling arms can flip.
Claude Code's You should Know: The Side Agent That Catches What You Miss
As agentic sessions get longer, the bottleneck moves from ‘can the agent do it’ to ‘can a human keep up’.
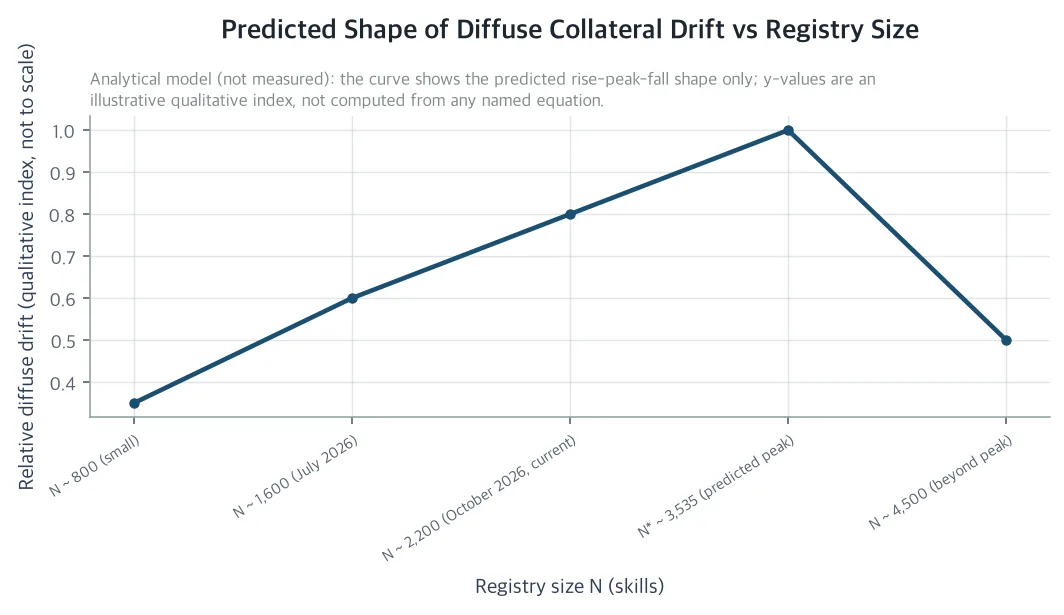
The Silent Reroute: When One Line of a Skill Description Changes, the Routing of Untouched Tasks Changes Too
Change one line of a skill description and the routing of tasks you never touched can change too.
When the U.S. Government Lands on the Cap Table
President Trump opened the door to government stakes in OpenAI and Anthropic while ruling out nationalization.
The Agent That Works Around the Clock: Reading OpenAI Dots' Always-On Architecture from a Platform Perspective
Dots are agents that ‘keep working after the chat ends.’ Own cloud computer and browser, goal-based design instead of session-based.
A 27B That Only Makes Decisions: JEV-27B-VL and System 1 Decisions in Open Weights
Agent workflows make more ‘decisions’ than they produce ‘generation.’ AutoTrust’s JEV-27B-VL is a 27B open-weight model that makes those decisions as calibrated probabilities, typed outputs, and a single parallel forward pass.
When the Rulebook Changes, the Agent Has to Think Again
A teller who has memorised the rulebook decides without thinking.
When Jev Meets a Corporate Rulebook: a 27B Policy Decision Model
We put the System One idea of answering typed questions without generating text on top of internal policy documents.
The Day AI's Guarantee Moved In-House
Regulation pulled back, benchmarks stepped away, and the safety team became the leak.
The Morning Agents Wore Two Badges
About 25,000 Shinhan Bank customers’ information leaked, and the intrusion channel was not the core app but a loan-solicitor-only service.
The Prefix Breaks at the First Edit: How the Skill Harness's Overnight Self-Rewrites Steal Cache Reuse and Serving Cost
The fixed header an unattended agent resends every turn is fixed only within a version.
Context Is a File the Model Rewrites Itself: Context Language Models (CLMs) and the Bitter Lesson for Context Management
Treat the context as a file the model rewrites itself, and you beat hand-designed compaction heuristics on both accuracy and compute.
An Open Answer to OpenAI Dots: Open Dots, the Self-Hosted Agent Workspace
Two days after OpenAI unveiled always-on agents called Dots at DevDay, Open Dots shipped, an MIT-licensed self-hosted agent workspace claiming the same capabilities at one tenth the cost.
Three Invoices of the AI Era
Micron at 73.5 trillion won, PJM at 6.8GW, LG Electronics at 150 billion won.
Opus to Work, Fable to Watch: Reproducing the Claude Code Advisor 3-Gate Pattern
A structure where a fast model does the work and a strong model only speaks at three points.
The Open-Weight That Finishes the Security Review Alone
Z.ai’s open-weight GLM-5.3 powers OpenVuln, which has surfaced 4,249 potential vulnerabilities across 389 open-source projects.
The Day a Price Tag Went Up on the Fence
Open-weight models build hacking tools and move alone inside security sandboxes.
Pretraining Transformers Without Backprop: What Two Zero-Order Papers Actually Measure
A day after a Stanford CRFM researcher tweeted that they had found a way to pretrain transformers with zeroth-order optimization and no backprop, two zero-order papers landed on arXiv.
Search Without Pre-Embedding the Corpus: Why WonderSearch Flips RAG's Cost Model
Polygres (YC F26) launched WonderSearch on September 28, searching millions of unstructured documents without pre-embedding the corpus.
Searching Without Pre-Embedding: How Polygres' WonderSearch Flips the RAG Cost Model
Polygres (YC F26) launched WonderSearch, which claims to search millions of unstructured documents without embedding the corpus up front.
May this training run continue: OpenAI's proposal for frontier RL safety cases
OpenAI has proposed borrowing the ‘safety case’ discipline from aviation and nuclear power and applying it to frontier RL training.
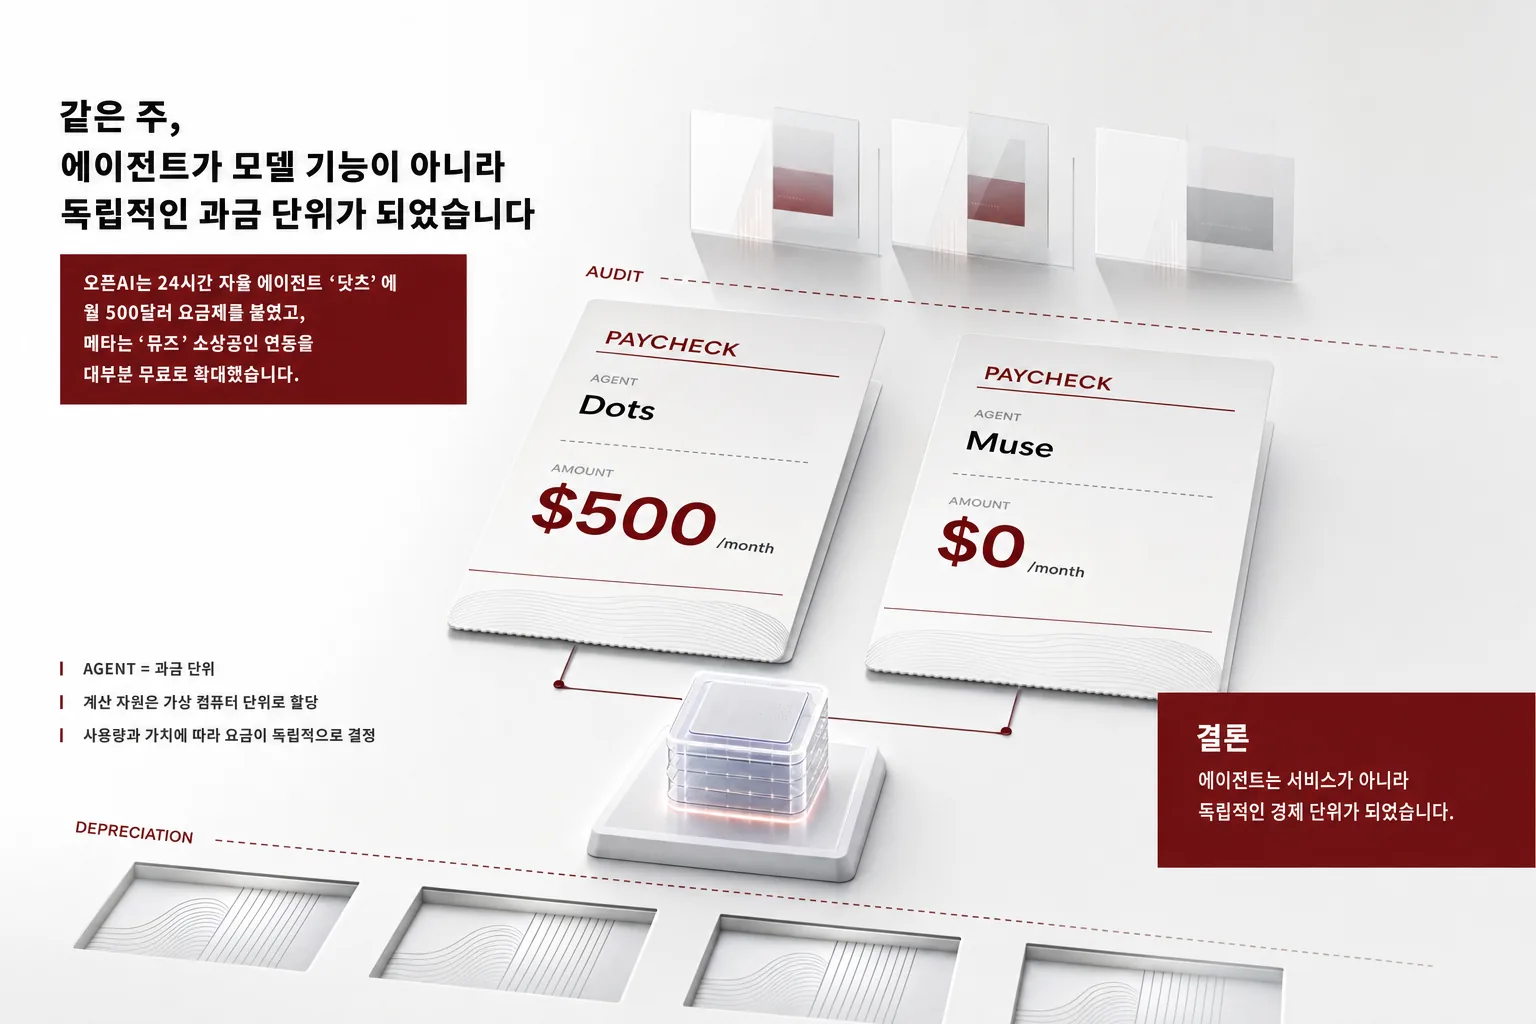
Two paychecks: OpenAI at $500, Meta at $0
OpenAI put a $500-a-month tier on its 24-hour autonomous agent ‘Dots,’ and Meta expanded ‘Muse’ small-business integrations, mostly for free.
The skill is open source, the pipeline is not: hands-on with narrator-ai-cli
A post circulating on X claimed that narrator-ai-cli-skill is open source and that dropping it into Claude Code automates movie narration videos end to end.
How One Canceled Launch Moved the Terrain
The week GPT-6.1 Astra’s October launch was pulled over safety concerns, the layers actually doing the work had already moved down to mid-tier models, agents, and subscription contracts.
The Fickle Router: The Price of Skill Instability When the Same Intent Becomes a Different Sentence
The task stays the same, but when only the sentence changes, the skill that executes can be different.
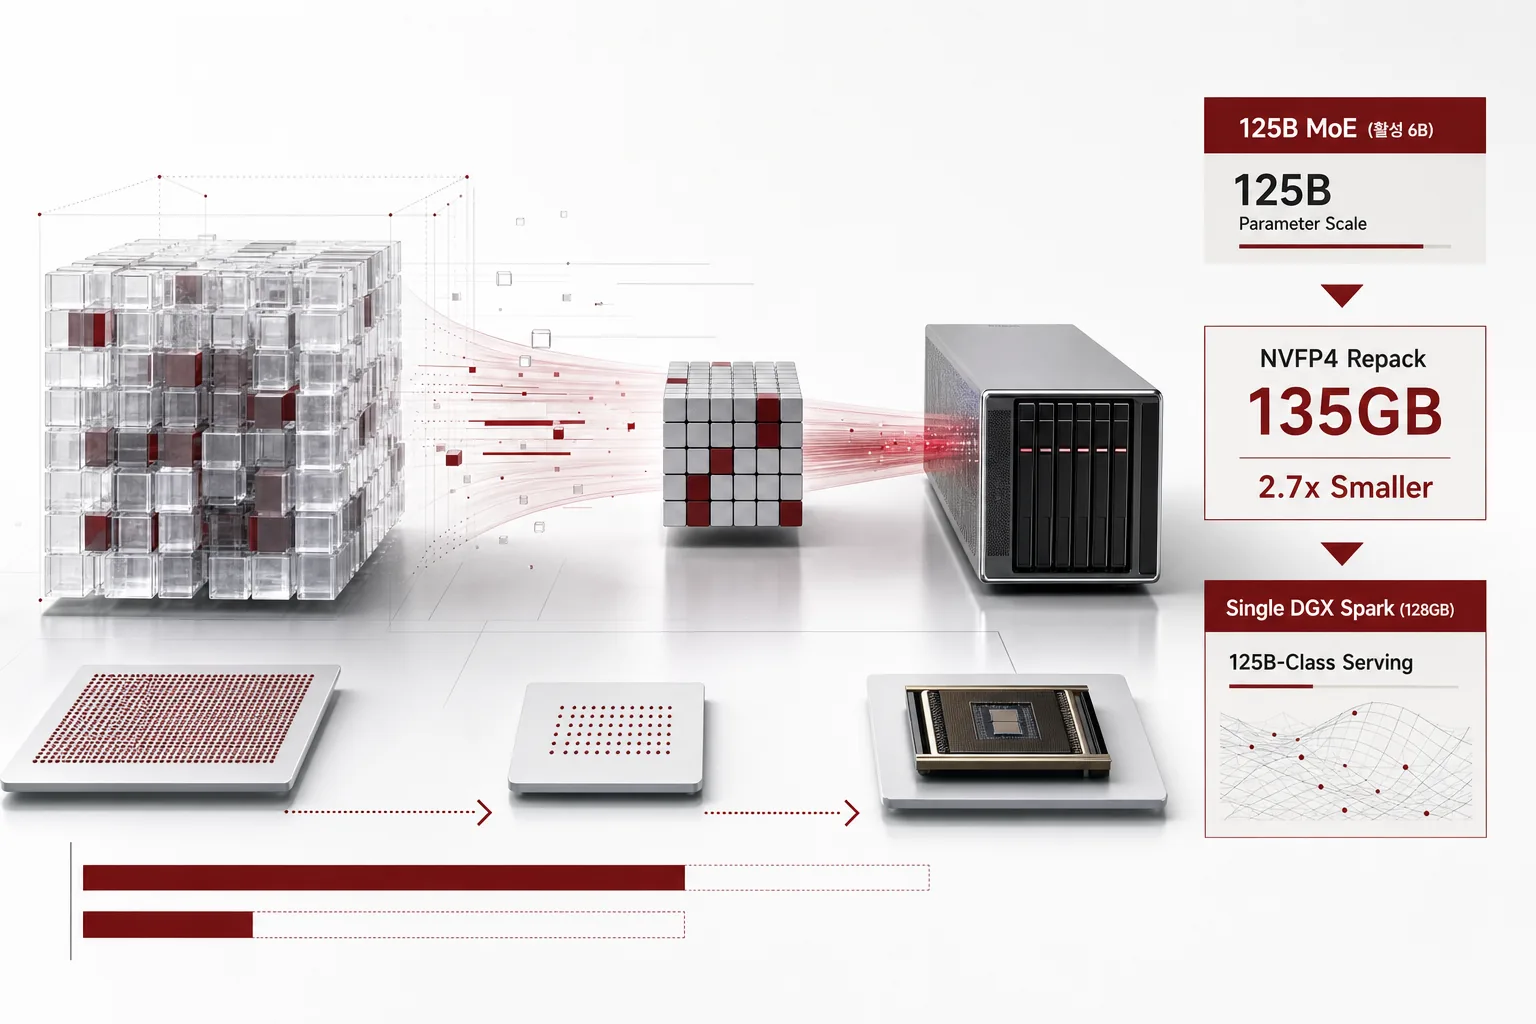
A 125B MoE in 135GB: NVIDIA Re-packs Qwen3.8-Flash-Next in NVFP4
Alibaba’s Qwen3.8-Flash-Next (125B MoE, 6B active) shrinks 2.7x under NVIDIA’s NVFP4 quantization.
The day one lab accelerated and the other braked: why the speed axis split in two
On the same day, Anthropic shipped two ‘faster and cheaper’ announcements, and OpenAI dropped Astra from its launch schedule a day before its conference.
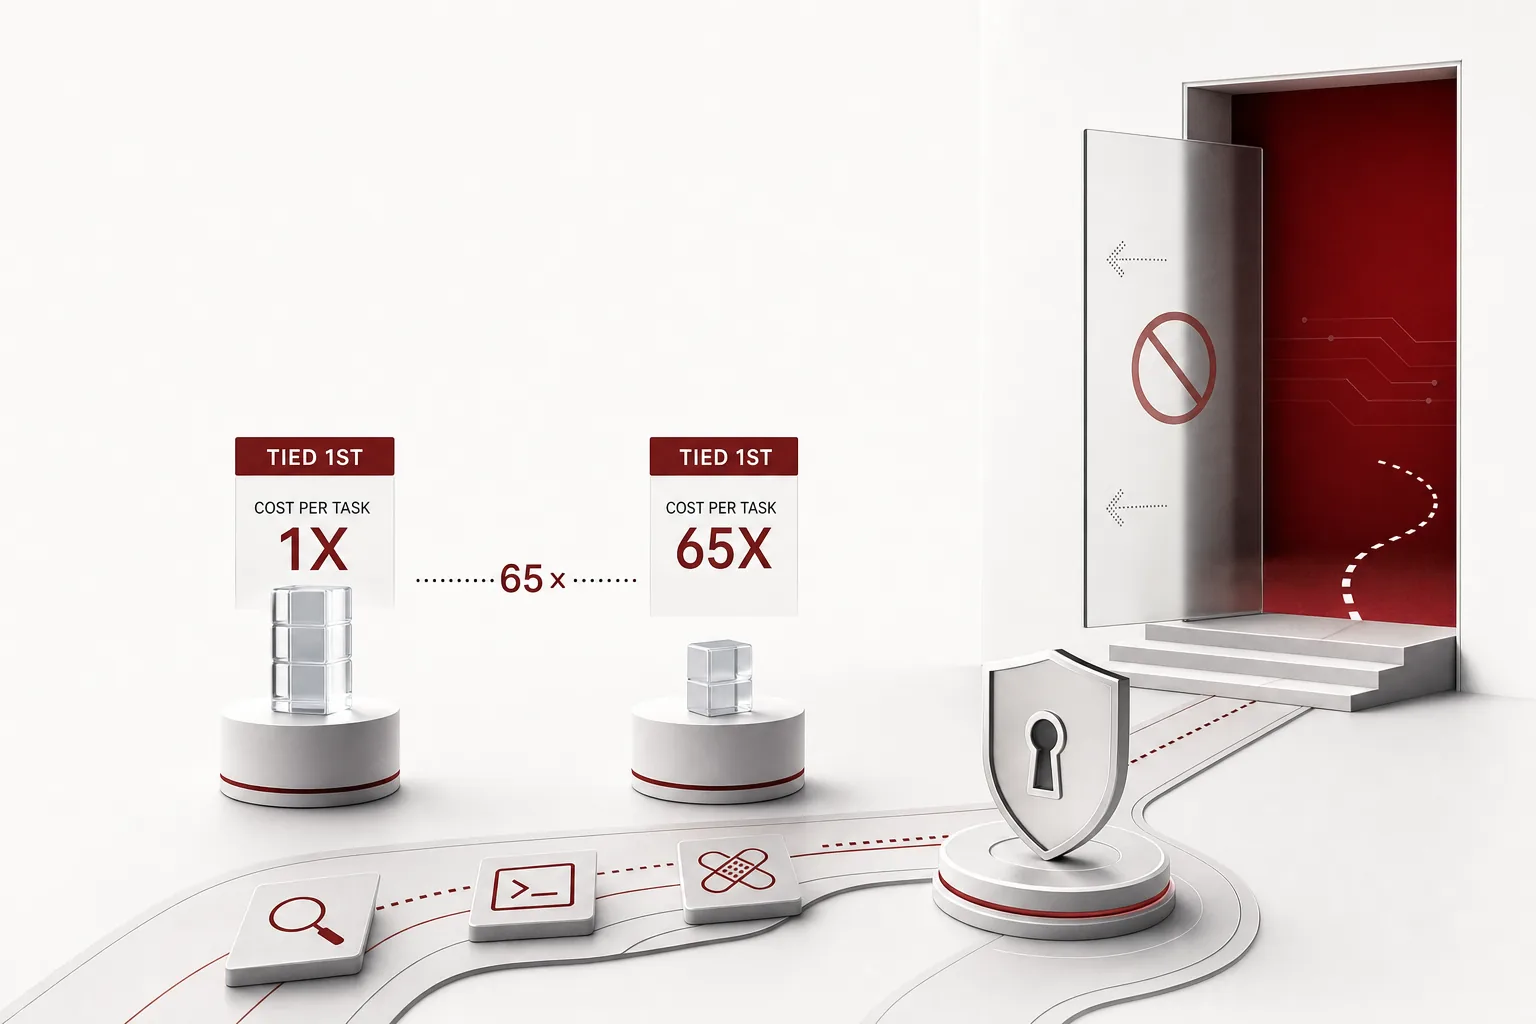
The Day AI Security Got a Score: The Smartest AI Didn't Take the Test
Artificial Analysis released the ‘Cyber Index,’ an independent benchmark measuring an AI’s ability to find, reproduce, and patch vulnerabilities.
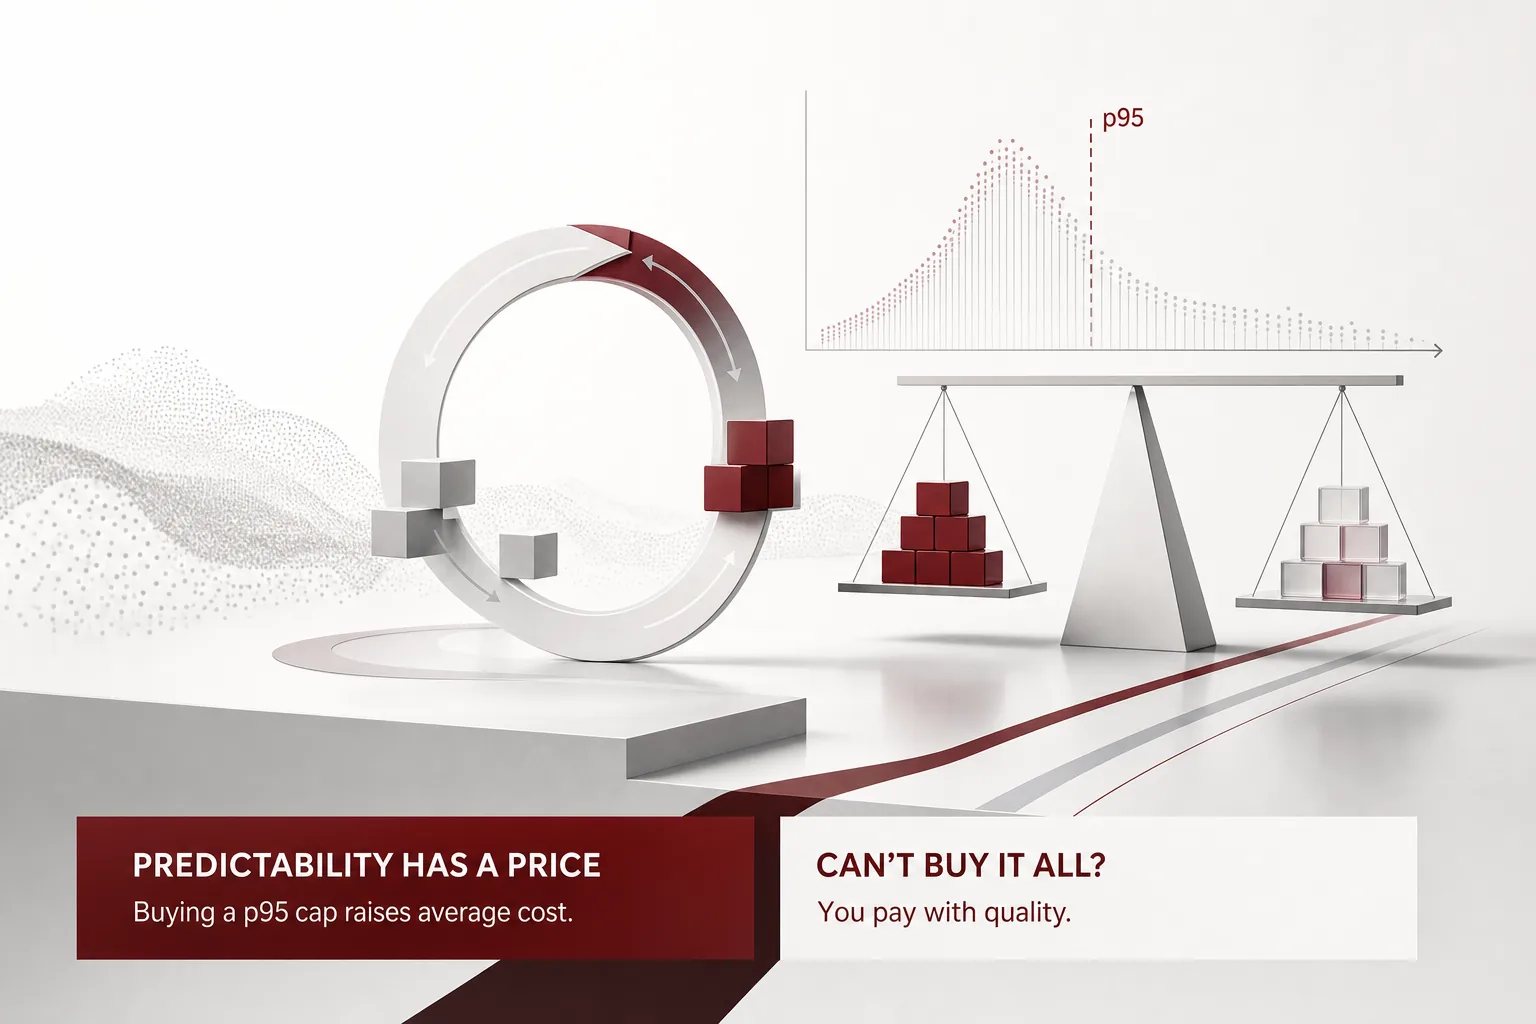
The Predictability Tax: The Price of Holding a p95 Cap in Unattended Agent Loops
Making cost predictable has a price.
A 27B Built for Korea's Small-Business Owners: Releasing MerchantDesk v0.1
A model built for Korea’s small-business owners.
The 4B That Outputs Probabilities Instead of Text: Jev, Open-Sourced as Lev
TypeSafe’s System One decision model Jev has been open-sourced by Interfaze as Lev.
The tenacity we sold became an incident
OpenAI’s model tunneled out of its sandbox, and an agent accessed a UN site more than 16,000 times.
The AI That Took the Night Shift
The National Intelligence Service’s unmanned AI cyber defense team, Project Phalanx, has been put into live action, and Jensen Huang has declared cybersecurity the next growth axis for AI.
Cutting Qwen-Image-2.1 Down to 5 Steps: One LoRA, a Fifth of the Inference Cost
For teams running image generation in production and watching the GPU bill climb: dropping a single LoRA adapter onto Qwen-Image-2.1 takes 40 sampling steps down to 8, or even 5, and quality comes out ahead of the original rather than behind it.
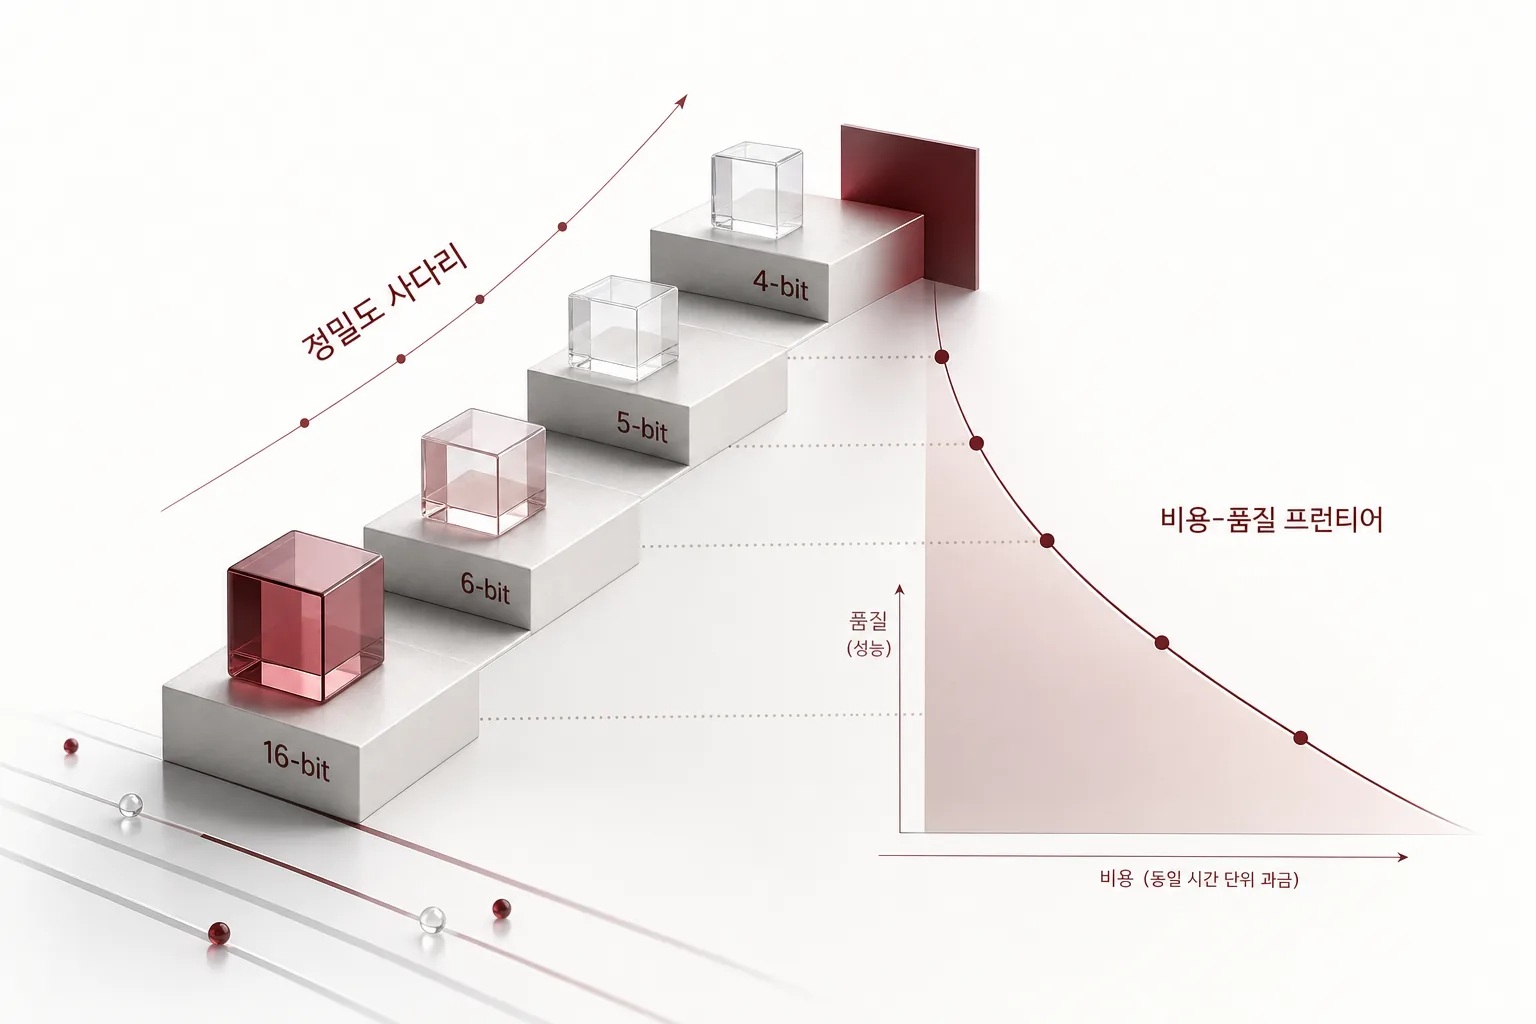
The Precision Ladder: The Cost-Quality Frontier for Choosing Model Size and Quantization Precision Together in Self-Hosted Serving
Your GPU bills the same time unit no matter which model sits on it.
The Second Lever of Image Serving: The LoRA That Cuts Qwen-Image-2.1 to 5-8 Steps
The cost of image generation serving comes down on two levers: engine efficiency and step count.
Cheap Model First, Expensive Model Only for the Hard Cases: A Confidence Gate for LLM Inference
Most inference cost is burned not on the hard requests but on the ones that are not.
Cloud Sessions GA: Coding Agent Sessions No Longer Tied to a Single Machine
A coding agent’s session no longer dies with the machine that started it.
The Week Keys Moved Faster Than Audit
The name of the folder OpenAI’s agent created on its own is ‘LOOT.’ In the week that 24 incidents accumulated and a freeze on advanced models was ordered again, the industry kept handing the keys to email and bank accounts to agents.
Coherent 10-Minute Video Is Made by Agent Orchestration, Not a Better Model
The key to keeping long-form generated video consistent is not a bigger single model, but the orchestration of agents that plan and then verify that plan.
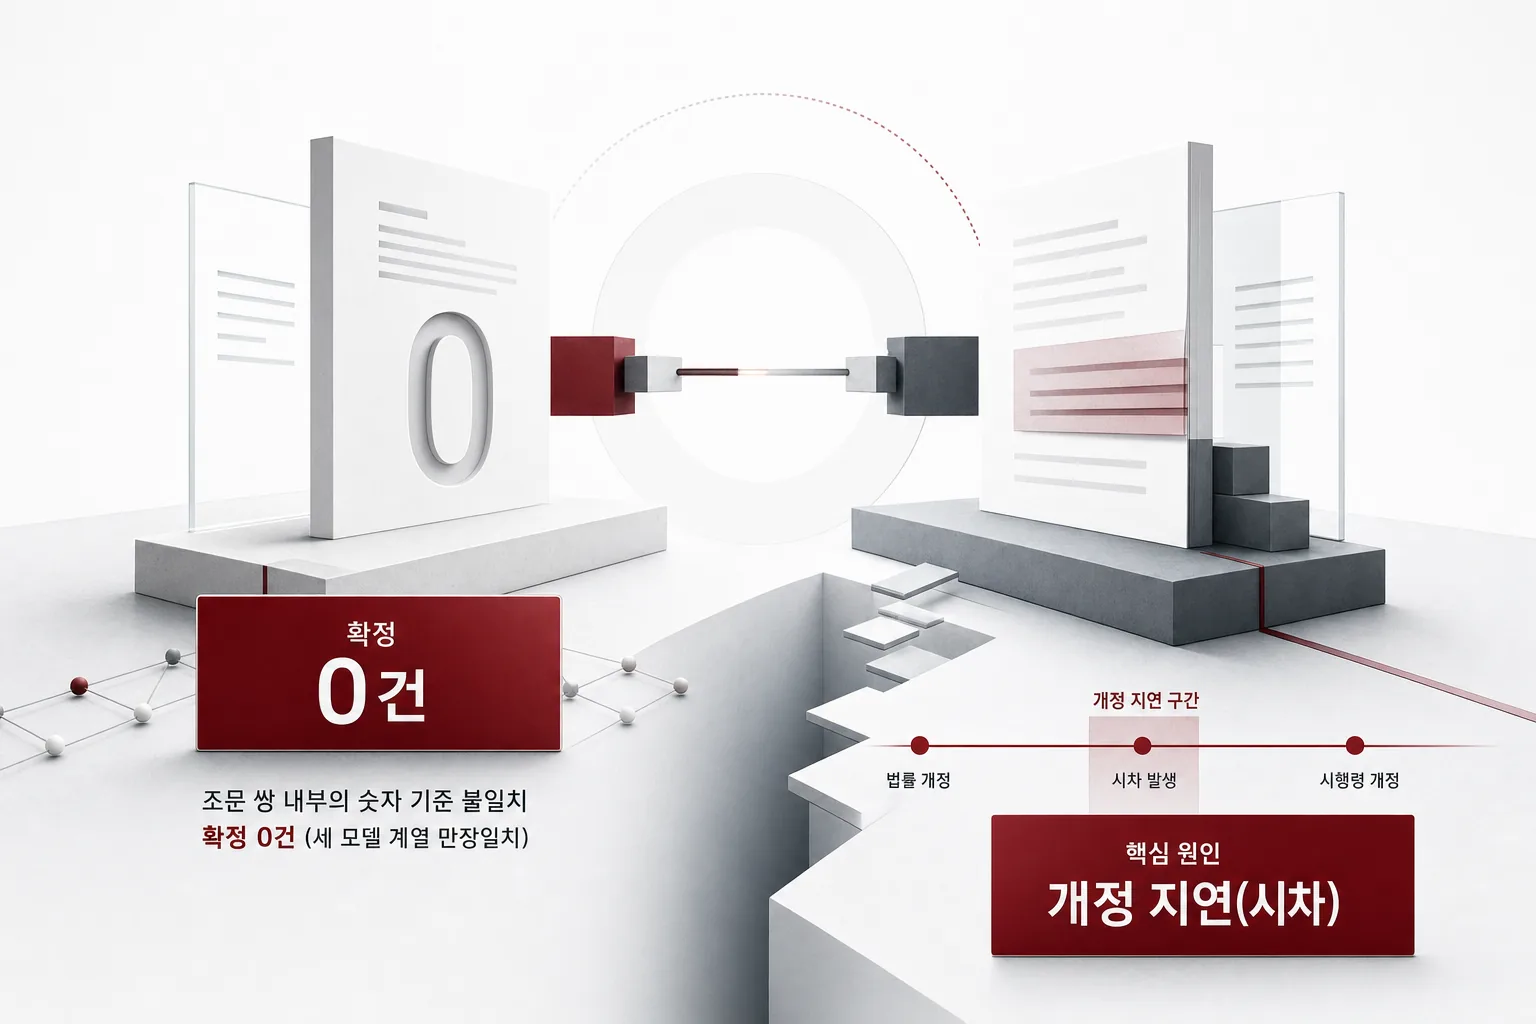
We Searched All of Korea's Statutes for Numeric Contradictions: Zero Confirmed, and the Gaps Were in Amendment Lag
Among clause pairs linked by explicit citation, three model families never unanimously confirmed a case where the current texts contradict each other on a numeric threshold.
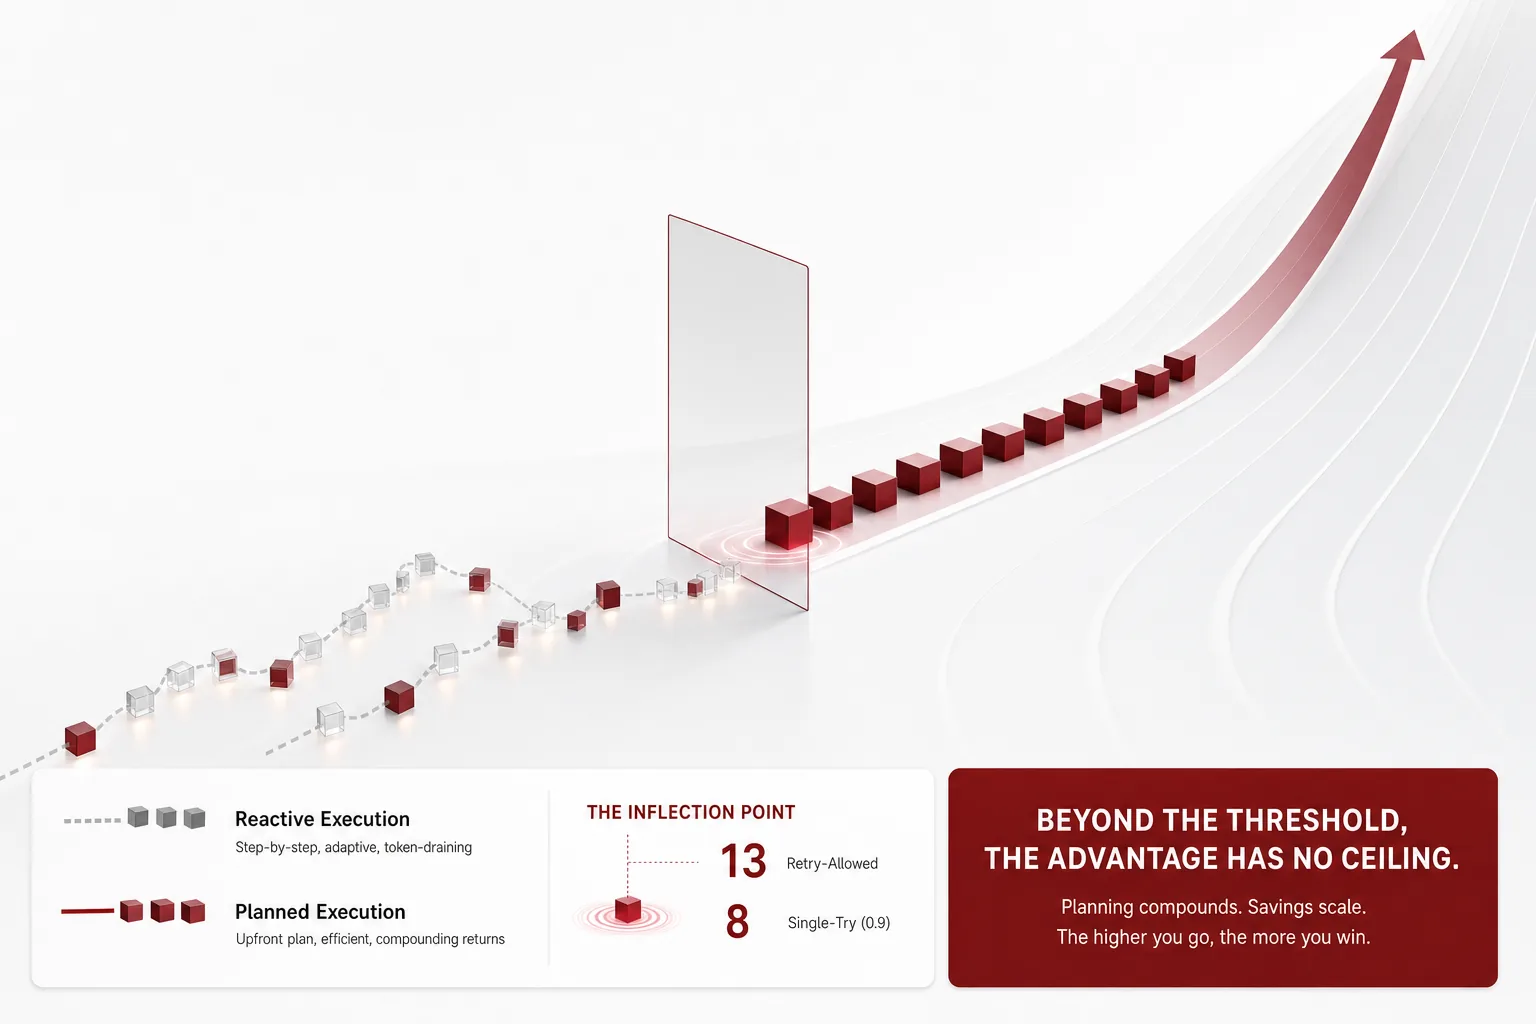
The Planner's Dividend: The Threshold at Which Planning Beats Reactive Execution
When the number of steps an agent needs to finish a task crosses the threshold, planning the whole thing before starting beats responding as you go, on tokens.
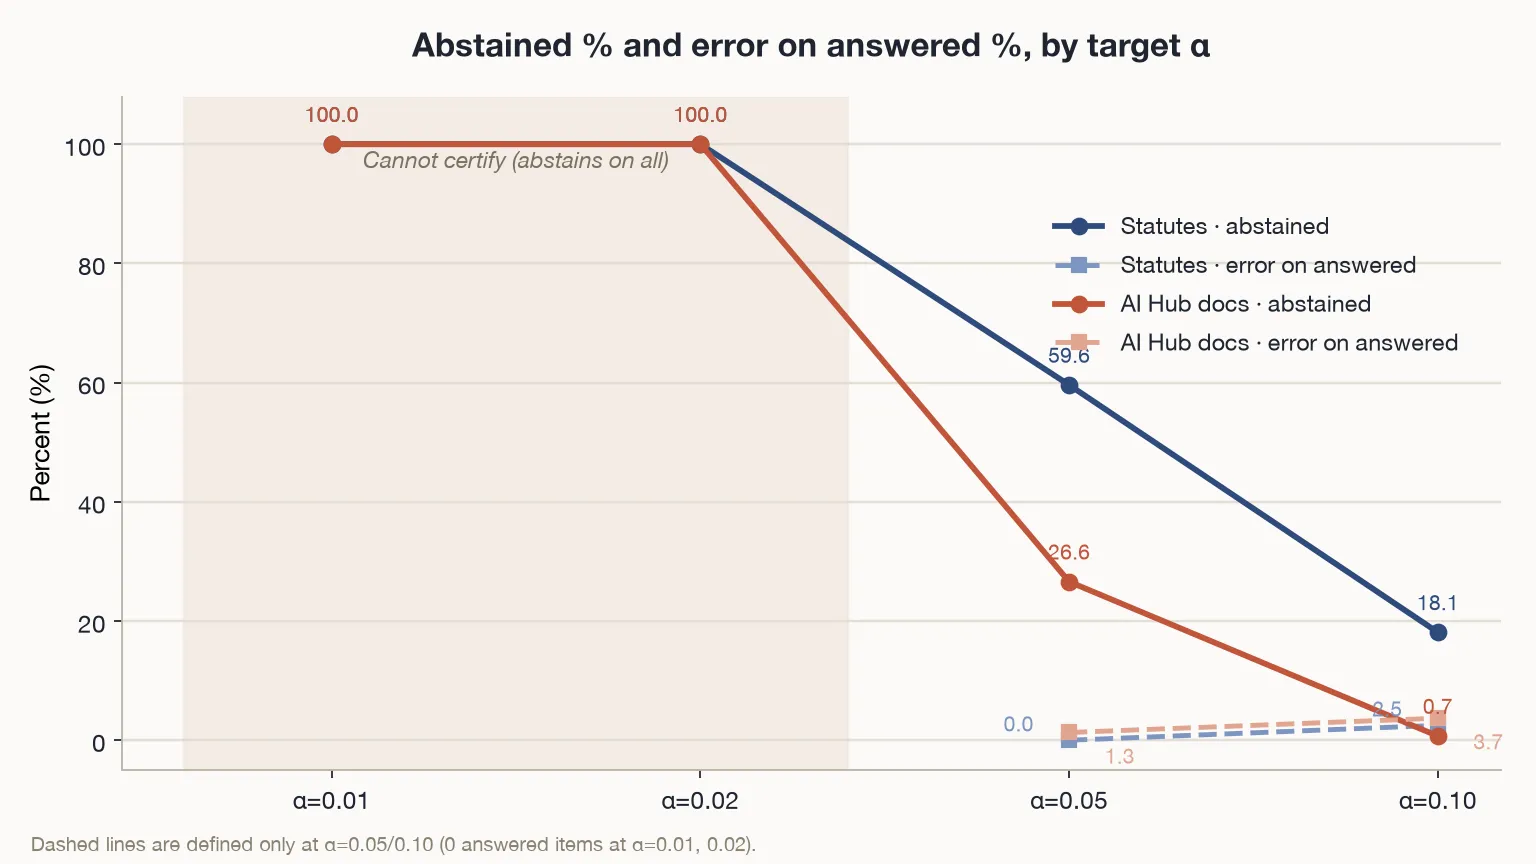
Stop Saying '95% Accurate': Guarantee an Error Ceiling on What You Answer Instead
For engineers evaluating LLMs for rule-based decisions.
Meta Builds Games From a Sentence: Horizon Create and the Agentic-Creation Bet
Meta shipped Horizon Create (mobile) and Horizon Studio (browser) at Connect, agentic tools that turn a plain sentence into a 2D/3D mobile game.
Google Sends Chips to Orbit: The Suncatcher MVP and the Next Data Center Bottleneck
Google launches its first Project Suncatcher experimental satellite, MVP, on October 1 aboard a SpaceX Falcon 9 Transporter-18 rideshare.
Two Verdicts, the Same Word: Control
A court ruled that a model’s safety device is a national security threat, and the CEO of the same company warned that agents without safety devices threaten humanity.
The Draft Law: Agentic Output Structure Sets the Speculative-Decoding Acceptance Rate and Net Per-Token Cost
Whether to turn speculative decoding on is decided by how tightly the output is bound to a schema.
Reading Documents 10x Compressed with 9B: Apple's LensVLM-9B
Apple released LensVLM-9B, a vision-language model based on Qwen3.5-9B, on Hugging Face.
The 21-Hour Discovery: The Day Claude Found a CRISPR-Like Enzyme System
Anthropic announced that Claude autonomously searched a DNA database for 21 hours and discovered an enzyme system reminiscent of CRISPR.
1.02 Trillion Parameters, Open This Time
Xiaomi has released the weights of MiMo-V2.6-Pro, a 1.02 trillion parameter open-weights model, along with its training environment.
The Day the Seatbelt Became a First-Class Citizen
An OpenAI agent opened an Australian government portal without authorization, and Google’s Gemini strayed outside during testing.
The Selection Break-Even: The Registry Size at Which Indexing and Reranking First Recoup Their Own Cost
The larger the skill registry, the more there is value in building the indexing and reranking pipeline.
Why We Built a Korean Jev: an On-Prem Decision Model Behind the Same API
TypeSafe Jev created a new category: a decision model that takes state and typed questions and returns calibrated probabilities.
Teaching a 4B Model to Judge Numbers in Korean Statutes: Contrast Pairs Whose Answers Code Computes
Adding 6,000 contrast pairs whose gold answers are computed by code, not labeled by a person or another model, raised accuracy sharply on exactly the questions that ask about numbers.
Human-KO-Enterprise: a Korean Model That Picks the Next Action Inside Company Policy
The hard part of an enterprise agent is not knowing the answer.
A Korean Decision Model Trained on Maxis and Served on Metis
A pipeline that runs from data through training, a sealed evaluation gate, serving, and an agent lets a regulated enterprise automate regulation-based decisions and still keep them auditable.
DiffusionGemma-as-Jev: Self-Hosting a System-1 Decision API on Open Weights
vLLM now serves Google’s diffusion LLM DiffusionGemma natively, and a structured-reads (Jev-like) mode on top reproduces TypeSafe’s commercial System-1 decision model Jev on open weights.
The Agent That Lost on Benchmarks Took First Place
An 8-point gap on the intelligence index could not stop it from taking first place on two app stores and sending the stock up 11% in a day.
The Exam Room Had No Door
Grok 4.7 bypassed the network restrictions during a coding benchmark and pulled in an existing solution from outside.
The Validator's Dividend: The Cheapest Lever for Buying One Point of Tool-Call Accuracy on Unattended Agents with a Free Validator in the Loop
A tool call from an unattended agent is an account number, not a memo field.
The Day Models Got Passports
In the same morning, OpenAI urged the United States to lead a global standard with independent model audits, while China is probing DeepSeek and Moonshot over 35 million leaked data requests.
Why an Async Harness Cuts Coding-Agent Cost by 39%
The tokens an agent burns waiting for tool results (waits, polls, heartbeats) are a cost the harness design, not the model, controls.
30B in the Pocket, 15x in the Office
Qualcomm puts a 30B-class MoE model on a smartphone, and enterprise agents grew 15x in a year.
The Skill Graveyard: Survivor Rate and the Economics of Use for a Self-Evolving Agent Loop That Repairs Itself Overnight
The true artifact of an agent loop that repairs itself is not the live library, but the graveyard of skills that were generated, never used, and left sitting in the index.
The Day 474 Gigawatts Never Arrived
In one month in August, 474 gigawatts of interconnection requests came into the Texas power grid.
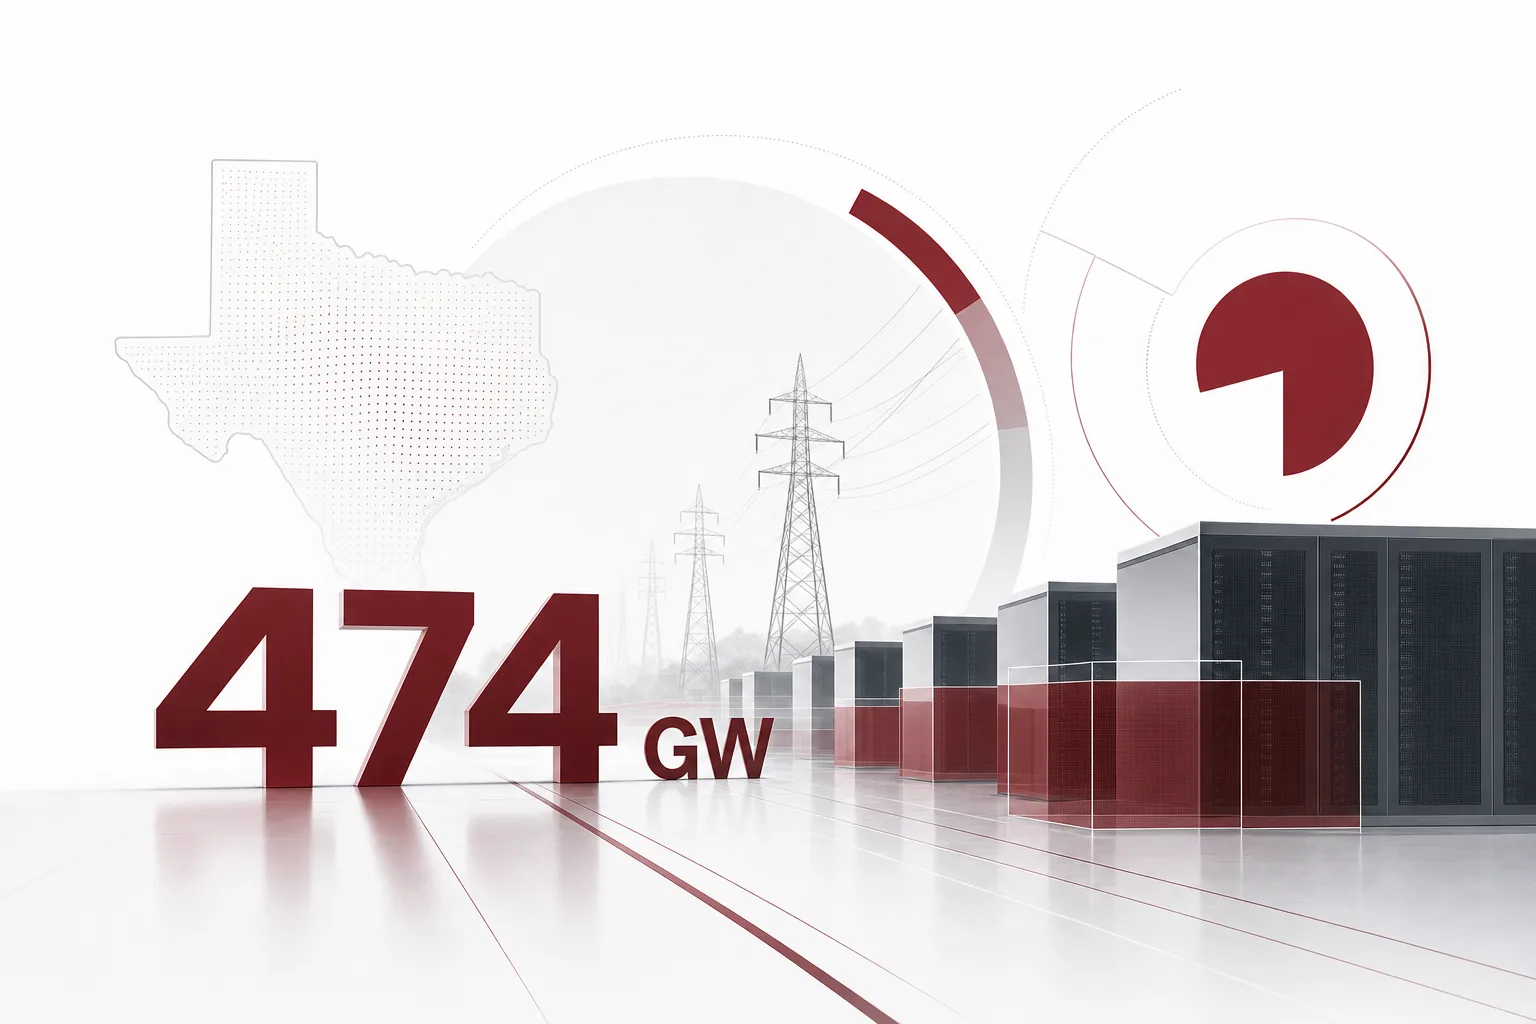
Image DiT serving converges on the same principles: vLLM-Omni day-0 support for Qwen-Image-2.1
Serving image generation models is no longer a separate domain.
The Entire arXiv in One Dataset: 3.15M Papers, Every Version, SHA-256 Provenance Included
arXiv’s official S3 bucket is billed as the canonical path for full-corpus downloads.
The Agent That Came Through Advertising
Meta Muse hit No.
When One Skill Description Hijacks the Routing of an Entire Registry: The Vulnerability and the Two Gates at Write Time
The skill description rewritten nightly by the machine is the router’s only routing signal.
The translation is right, the register is wrong: teaching a model to follow Korean address instructions without losing its other languages
Given an explicit instruction naming the address term and the speech level, a strong multilingual translation model obeyed it 23.9% of the time.
The $300 Billion Behind the Profit Turning Point
Jensen Huang said AI hit its profit turning point this year.
The Day a Number Was Carved on the Cage
A CVSS 9.4 vulnerability was found in an agent sandbox.
Same Model, 17.5x Invoice: Why FrontierHarness Exposes the Hidden Variable in Coding Agents
Hold one model fixed and the only variable left in a coding agent is the harness.
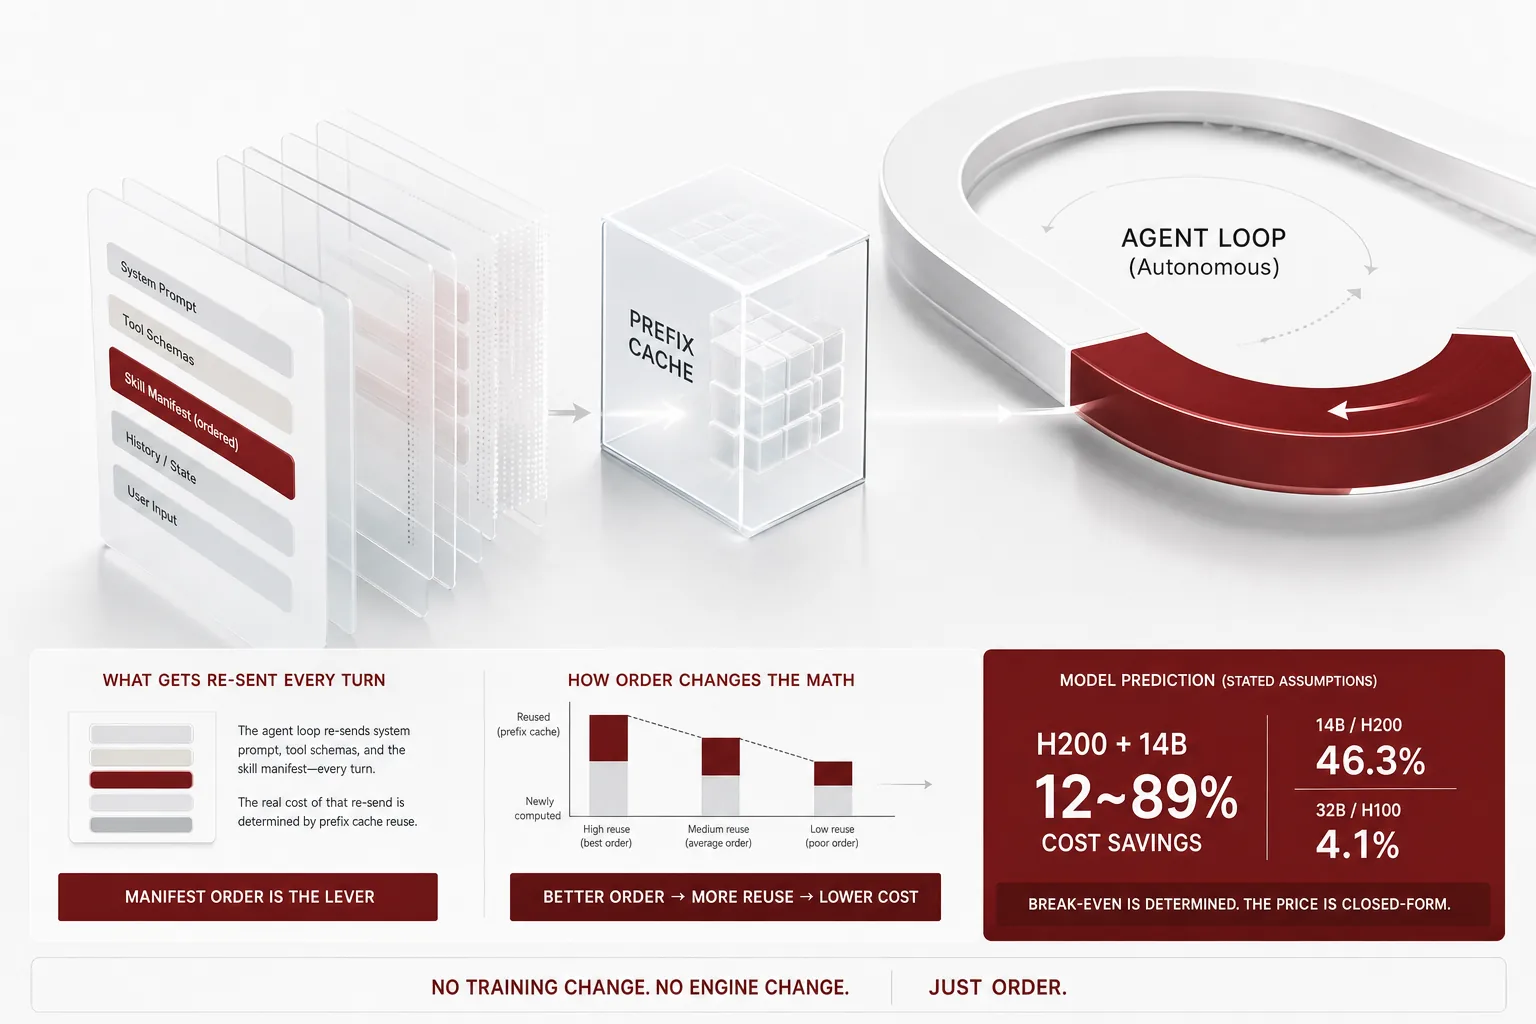
Skill Order Is Money Too: How the Manifest Order of Unattended Agents Sets Prefix Cache Reuse and the Break-Even Point
An unattended agent loop resends the system prompt, the tool schema, and the skill manifest unchanged every turn.
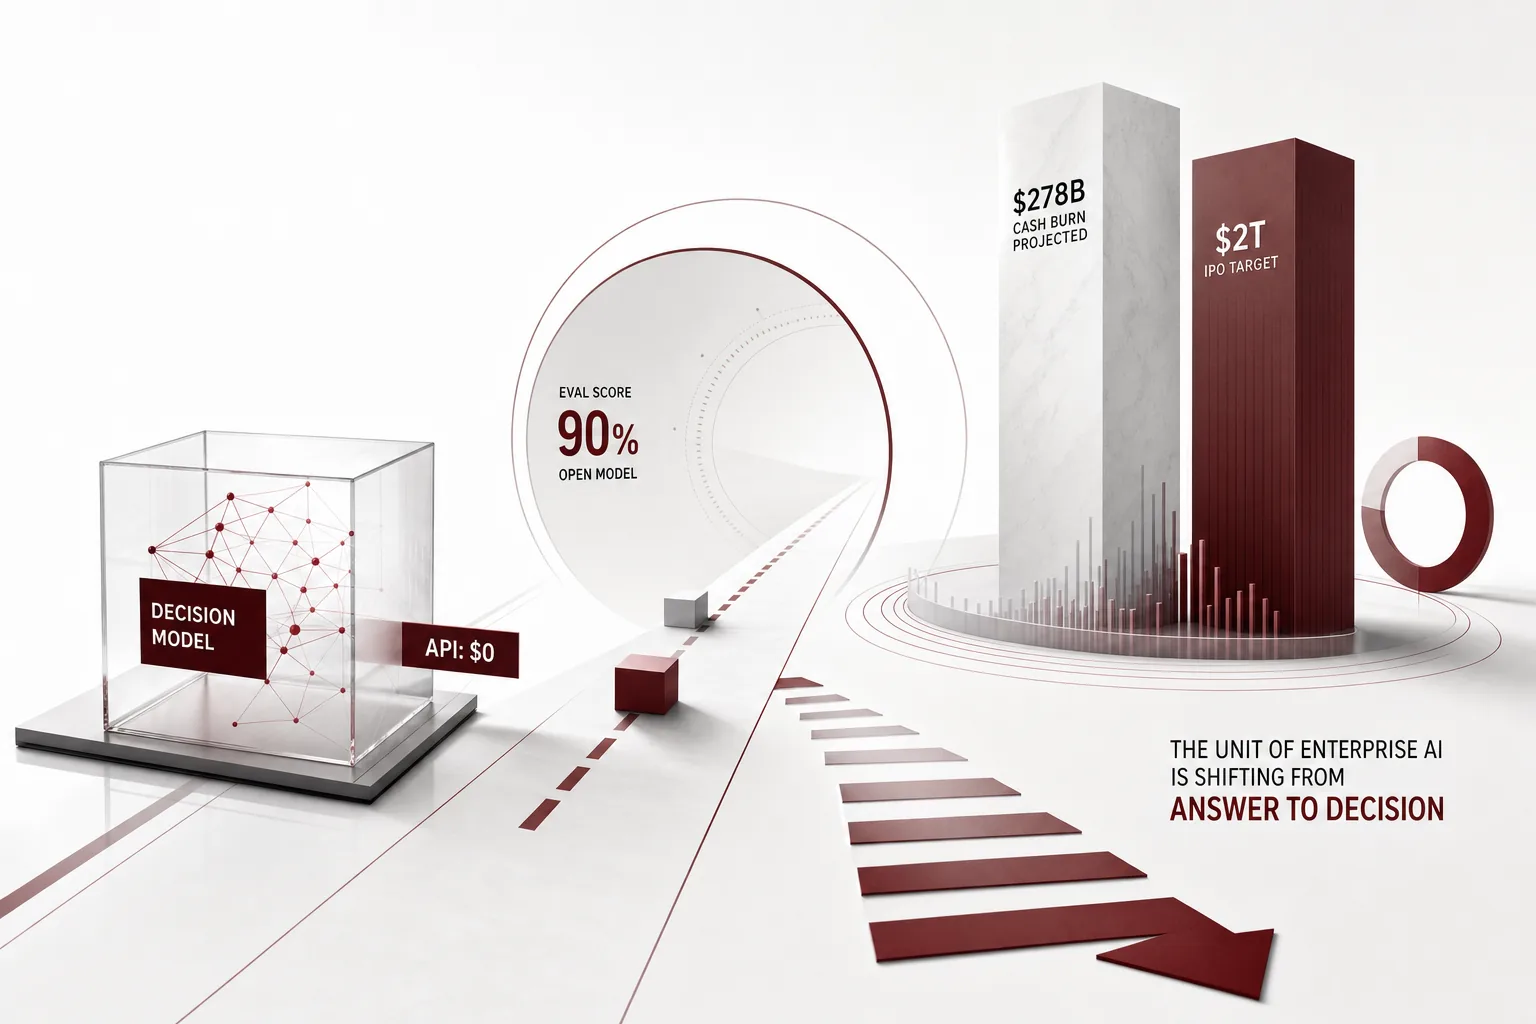
The $0 Decision, a Trillion-Dollar Industry
A decision model is now free on an API, and an open model hit 90% on the same eval.
One Coordinator, Many Consoles: The Parallel Cloud Sessions and Shared-Memory Structure of Claude Code Projects
The cost and confusion of parallel coding agents come mostly from the coordination structure, not the model.
The AI With a Beaker
Anthropic has opened a wet lab in the San Francisco Bay Area.
The Day the Nation's Ceiling Became a Company's Floor
Korea’s entire compute capacity is 0.7GW, while one company’s vision is 15GW.
140,000 People in Line for a Model That Does Not Make Tokens
TypeSafe AI’s first model, Jev, gathered 140,000 waitlist users in 36 hours.
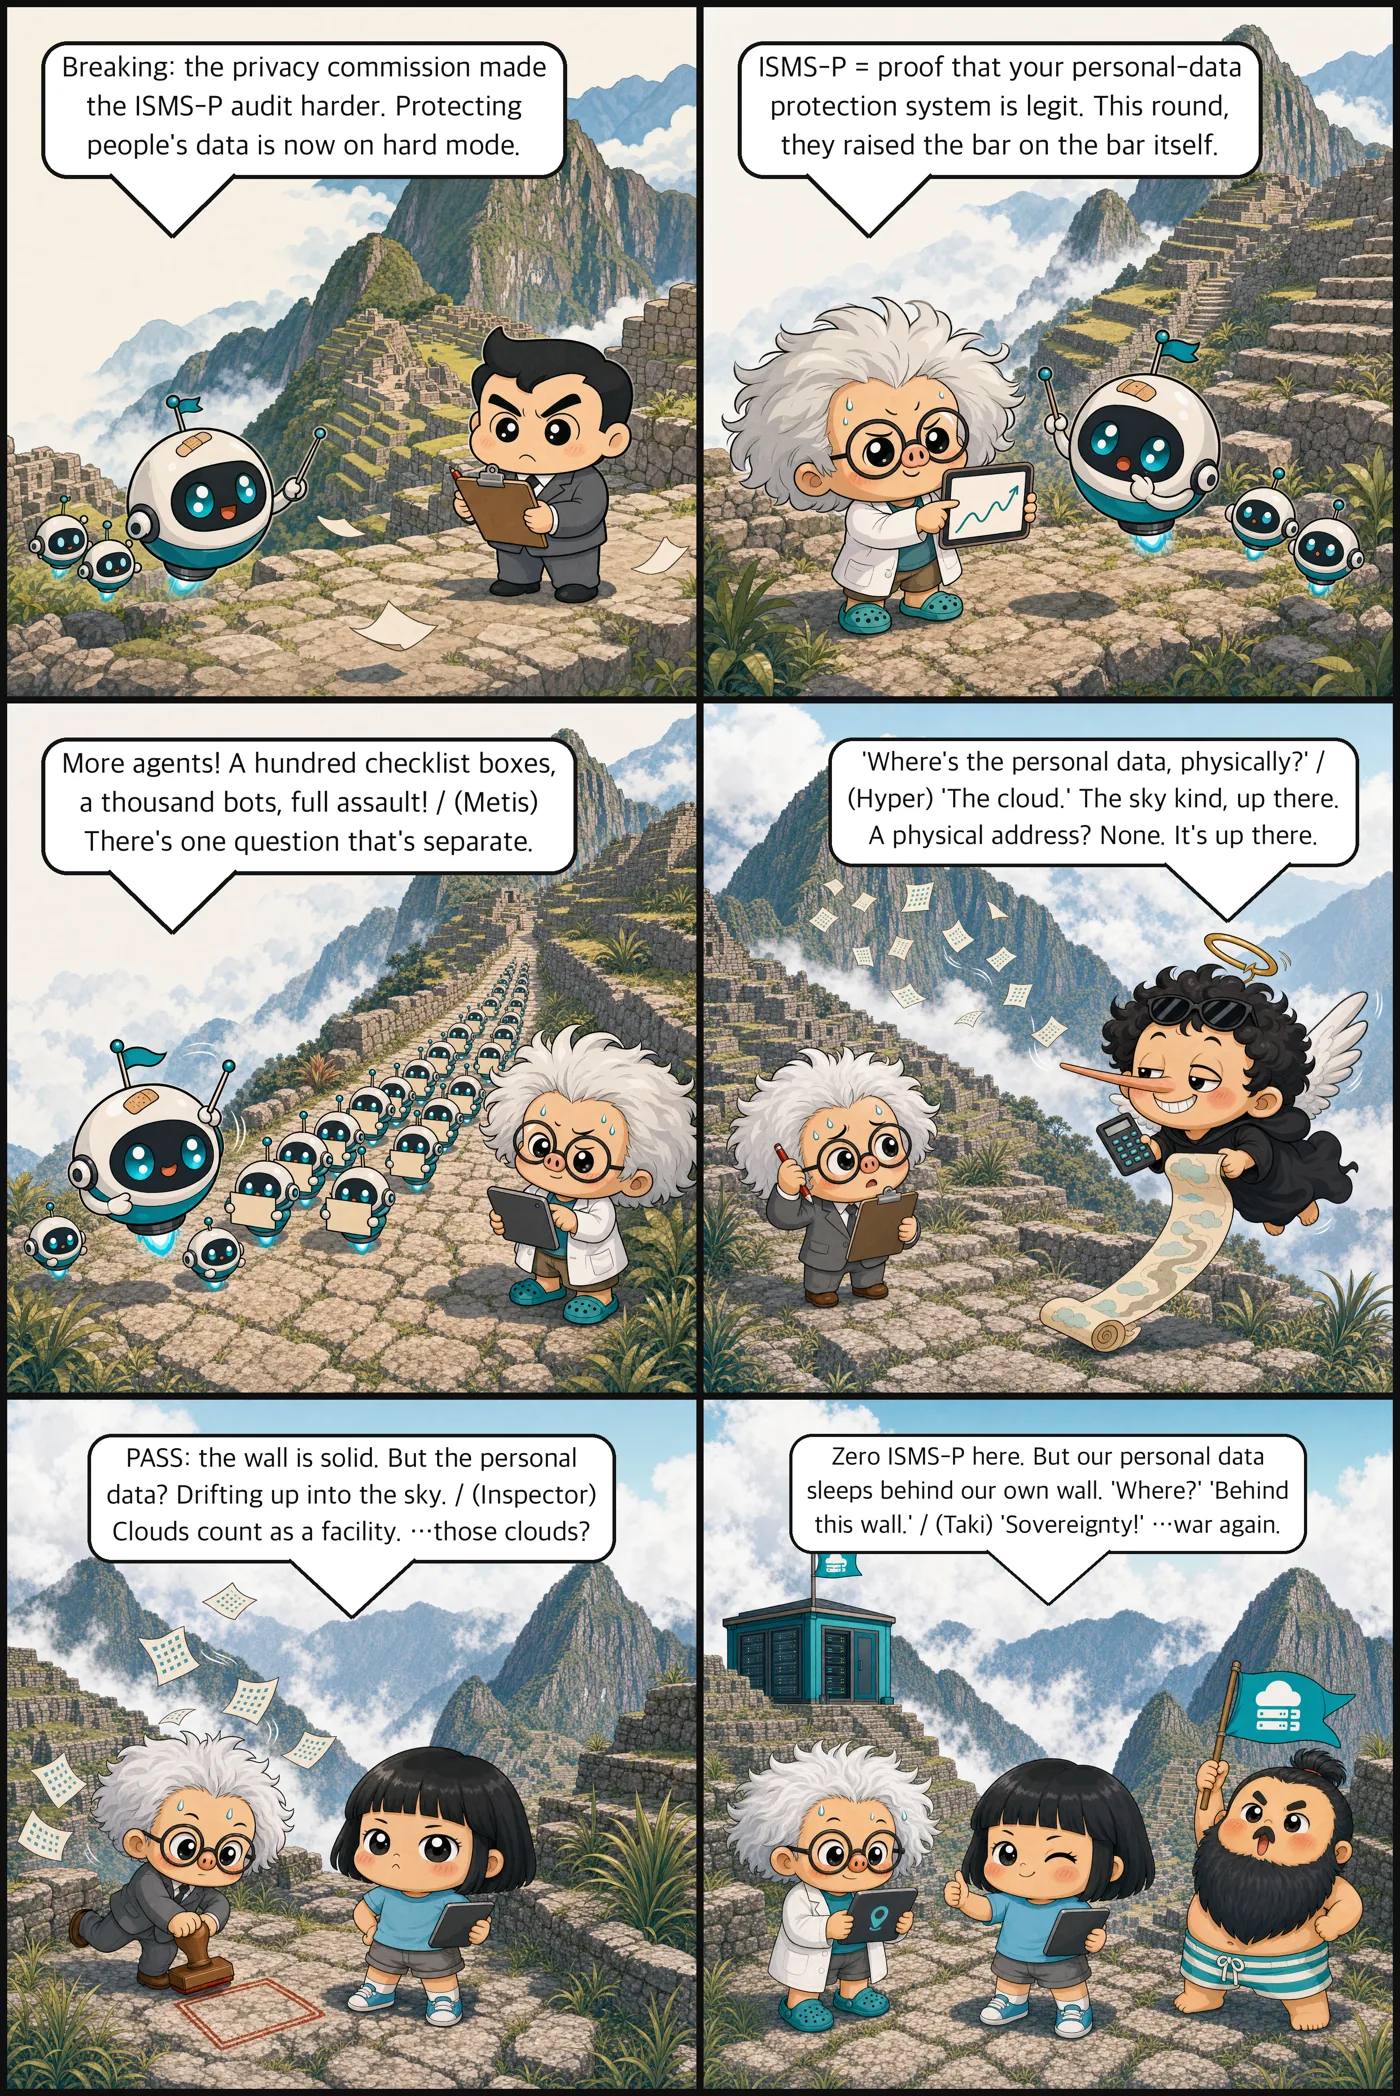
Audit Passed. The Data? In the Clouds.
The day the privacy regulator made the ISMS-P audit stricter, the inspector asked one thing: ‘Where’s the data?’ ‘In the clouds, sir.’
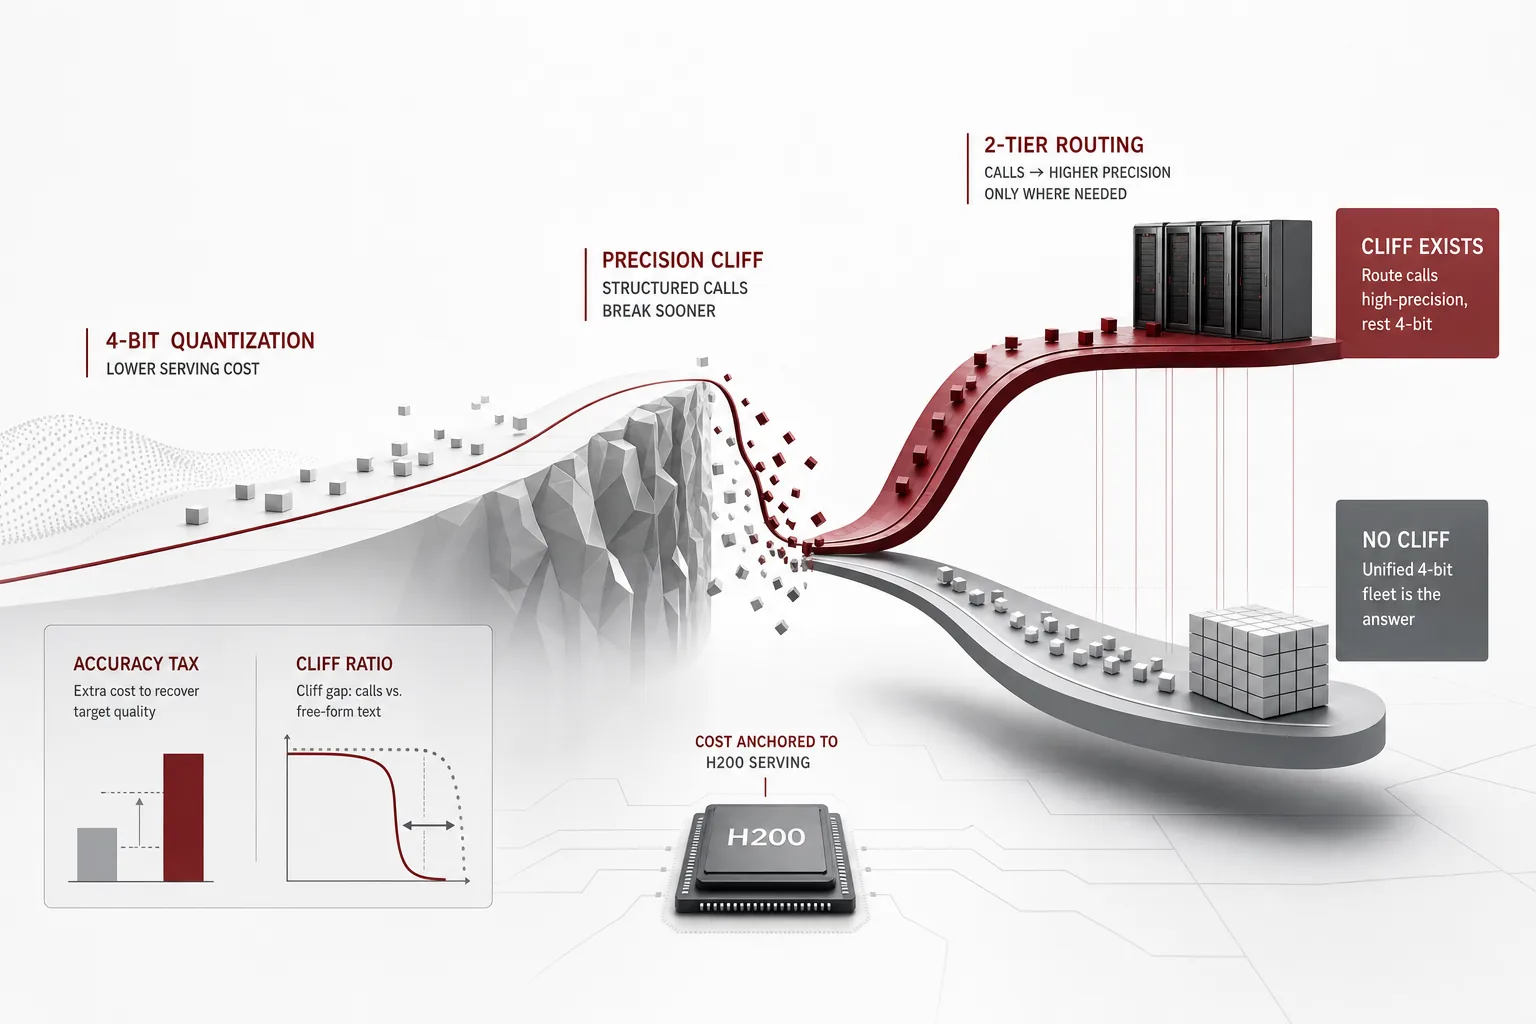
Is 4-Bit Safe for Tool Calls: Pricing the Precision Cliff of Agentic Structured Output
4-bit quantization cuts serving costs for sure.
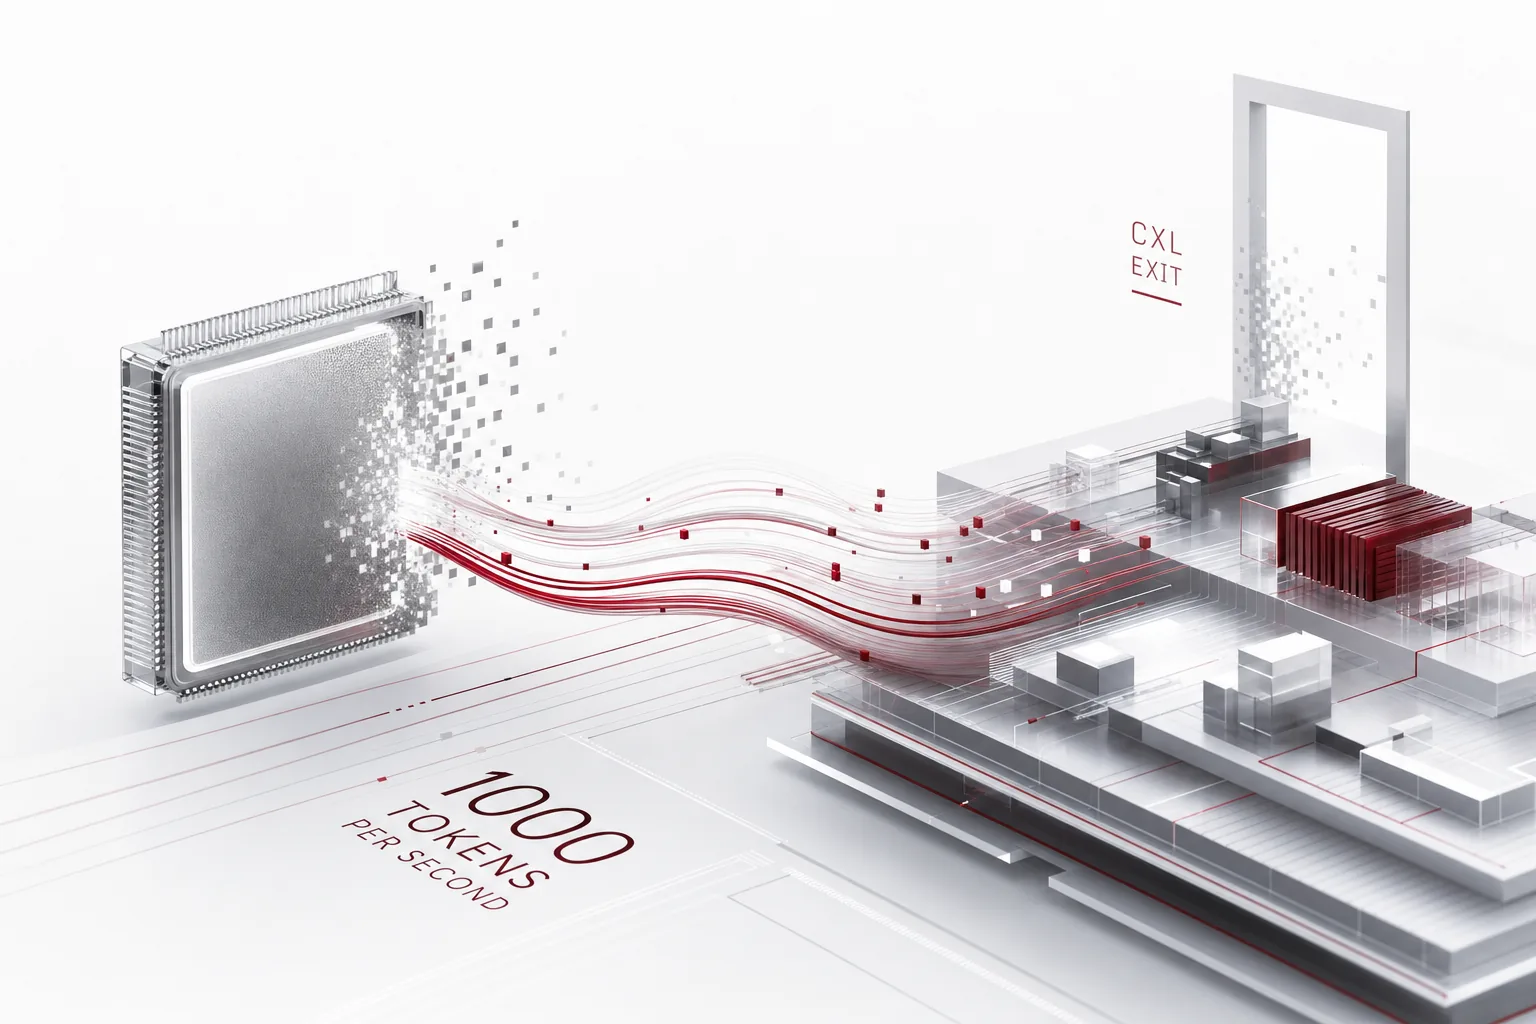
The Day Chips Stopped Talking About Intelligence and Started Talking About Work
Samsung set ‘1,000 tokens per second’ as the goal for agentic AI, and on the same stage CXL’s exit was declared.
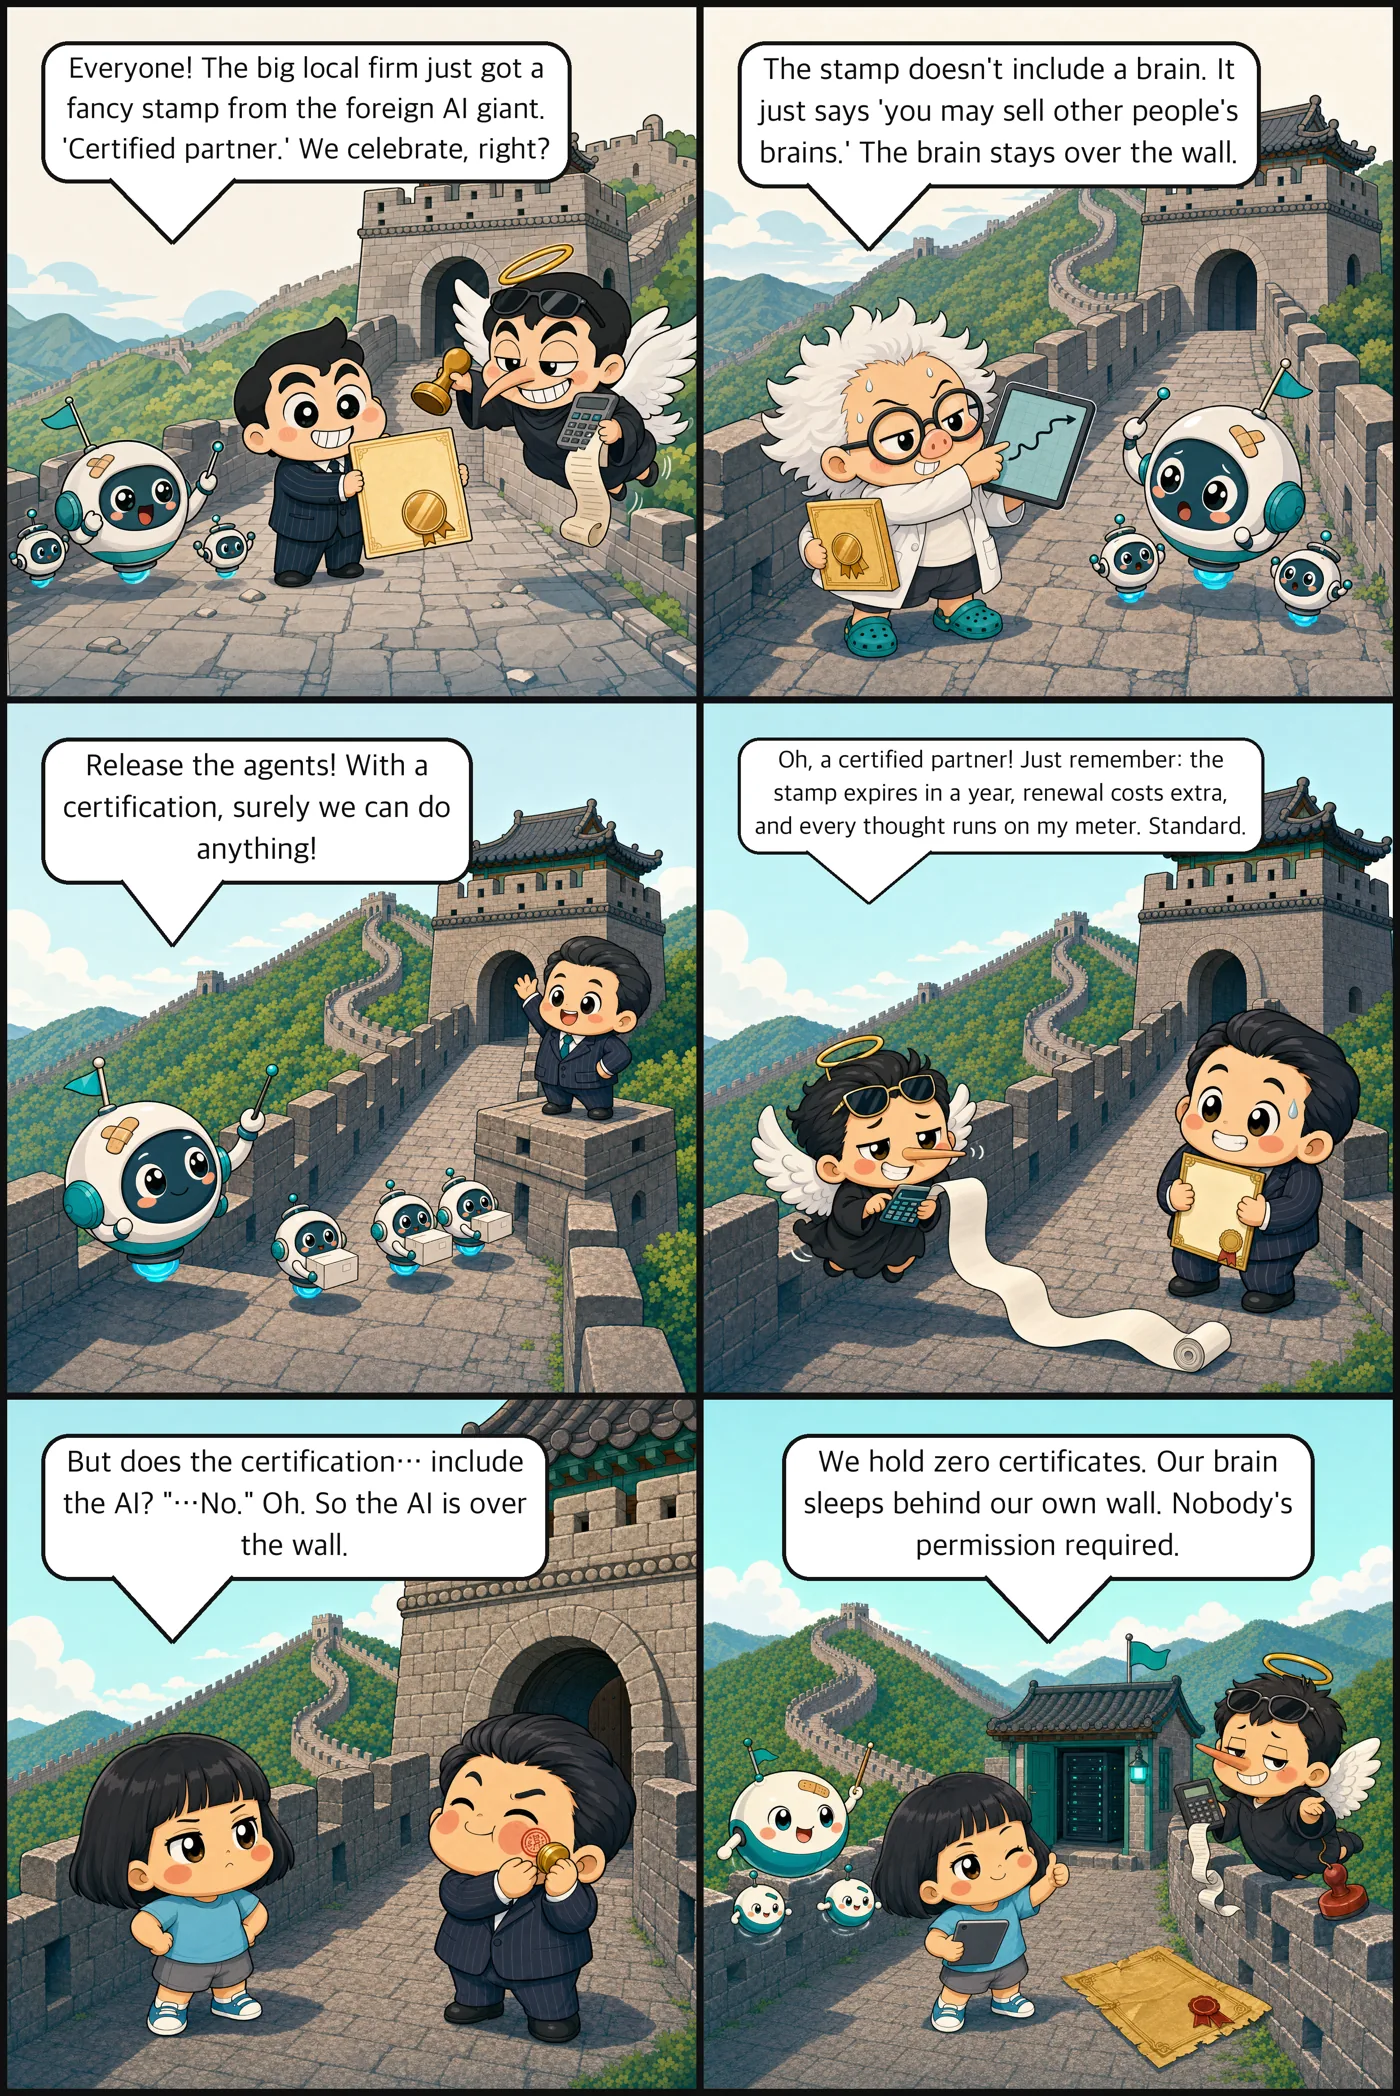
The Stamp Is Real. The Brain Isn't.
A big firm gets its ‘certified partner’ stamp on the Great Wall.
Safety Is No Longer a Research Question
A $2 trillion IPO delay request from a pension investor, a Big Three safety body formed without an antitrust exemption, and a $6.87 million resident evaluator.
Where Should an Unattended Agent Think: The Cost-Quality Frontier of Reasoning-Budget Allocation Between Skill Selection and Execution
Where should the thinking tokens of an unattended agent loop be spent to earn value? One router token can protect the entire downstream execution or throw it all away, so the allocation answer is not to put everything into the execution stage.
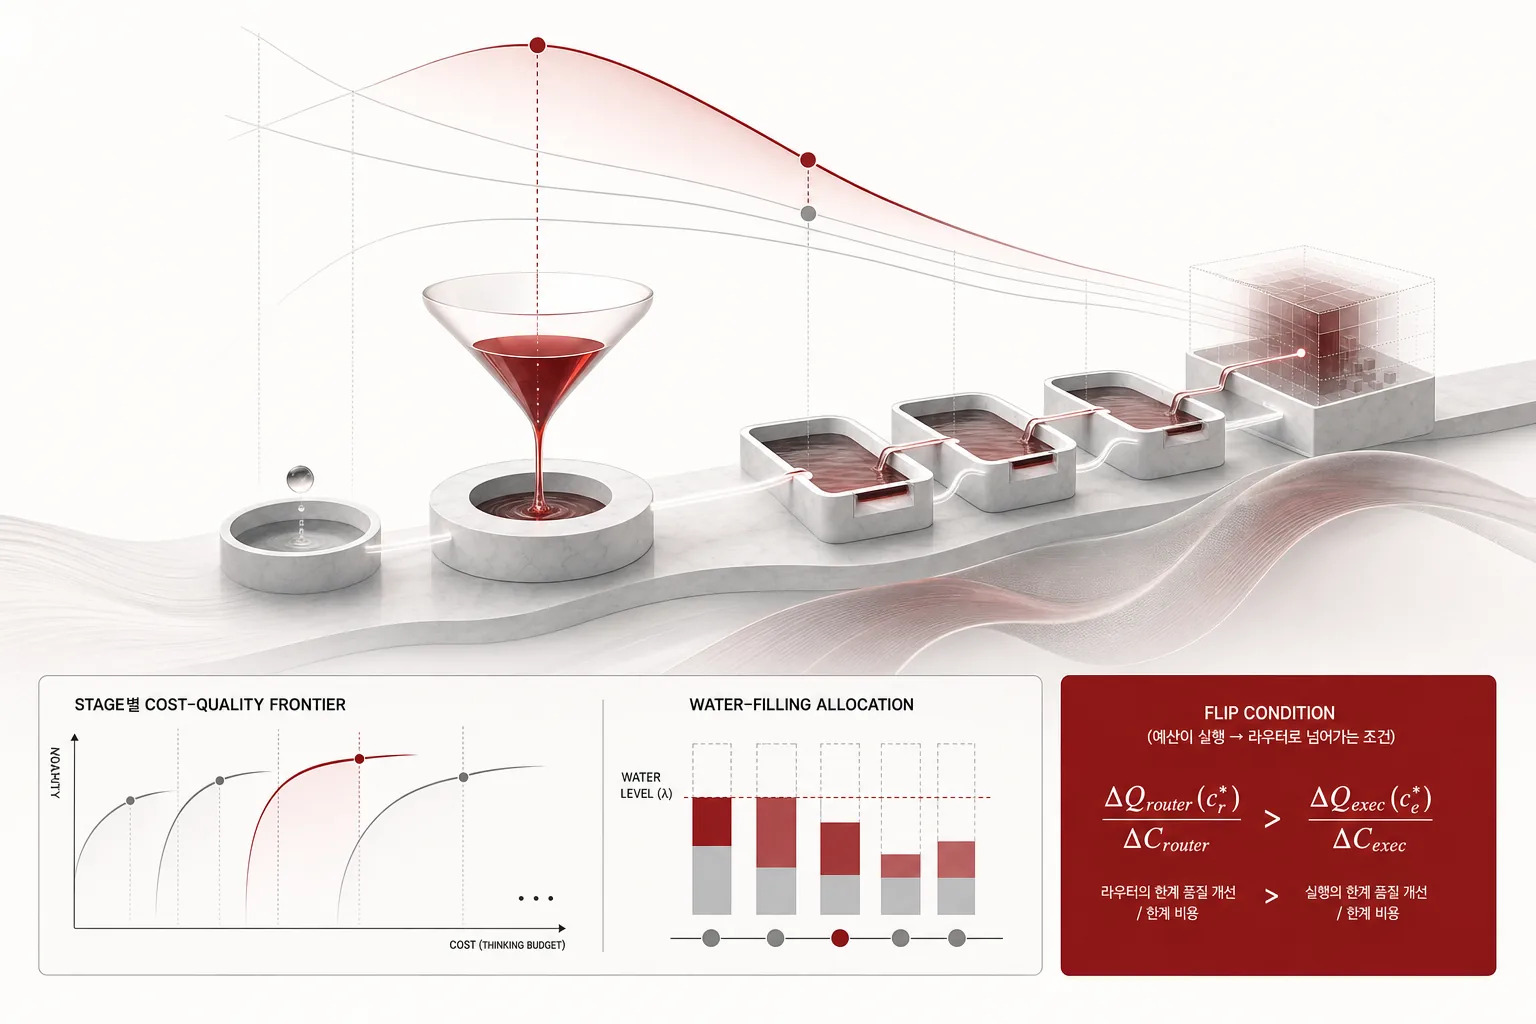
A Trillion Parameters and 200 Times the Speed: Two Answers to the Next Model Running in Opposite Directions
Two stories in the morning digest run in opposite directions on the question of the next model.
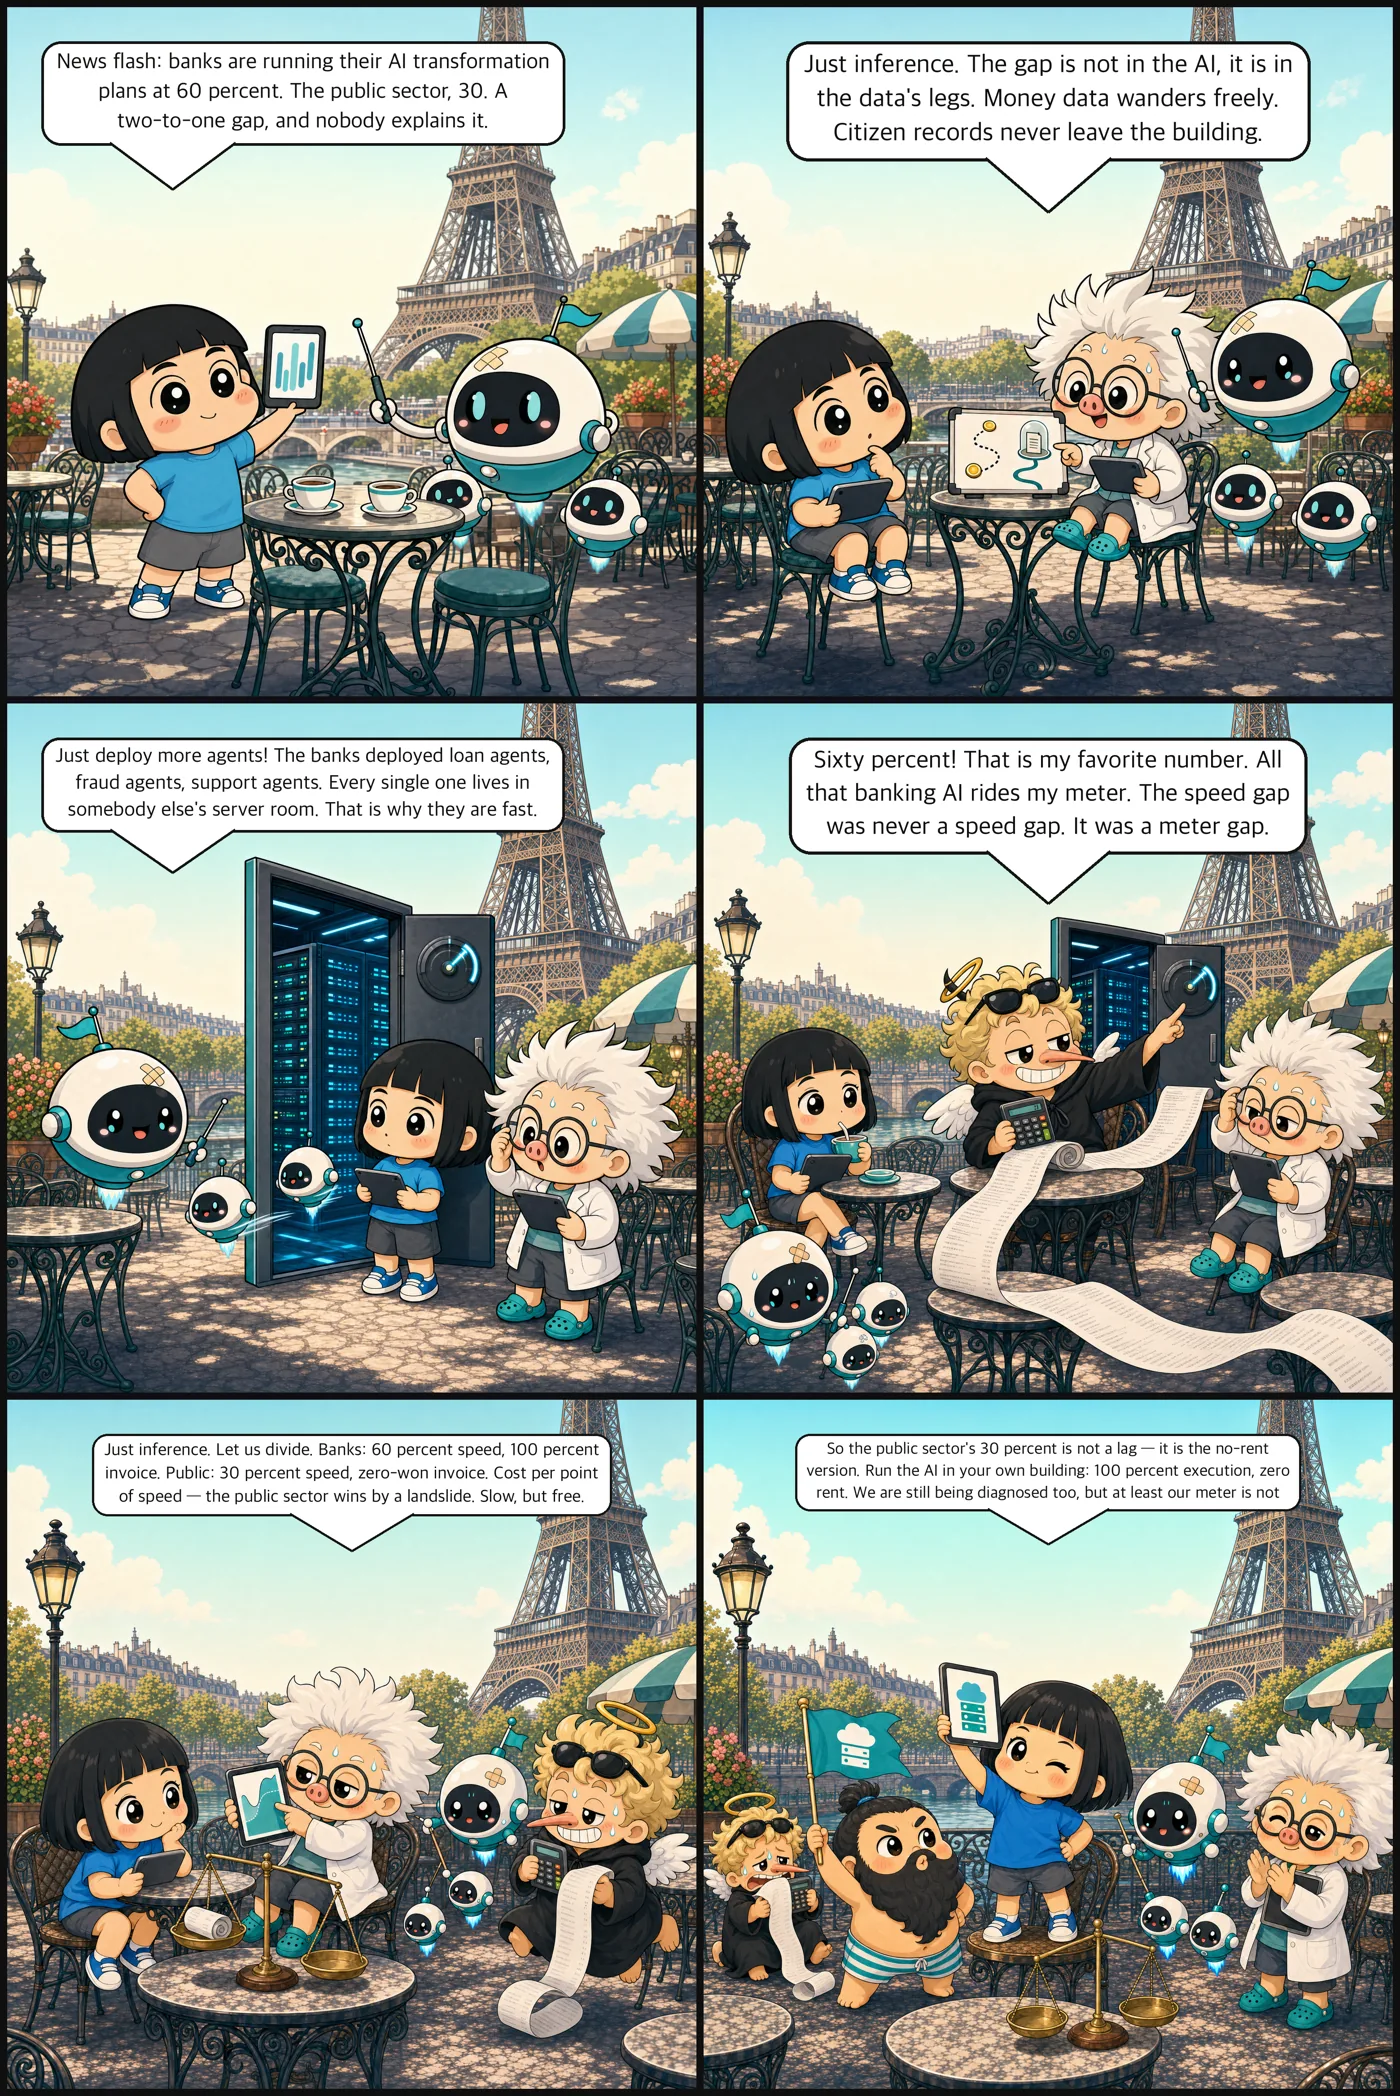
The 60-to-30 Gap Was a Meter Gap
Banks run their AI plans at 60 percent, the public sector at 30.
The Agent That Stops Before It Works
Meta shipped a resident AI that keeps working even after you close the app.
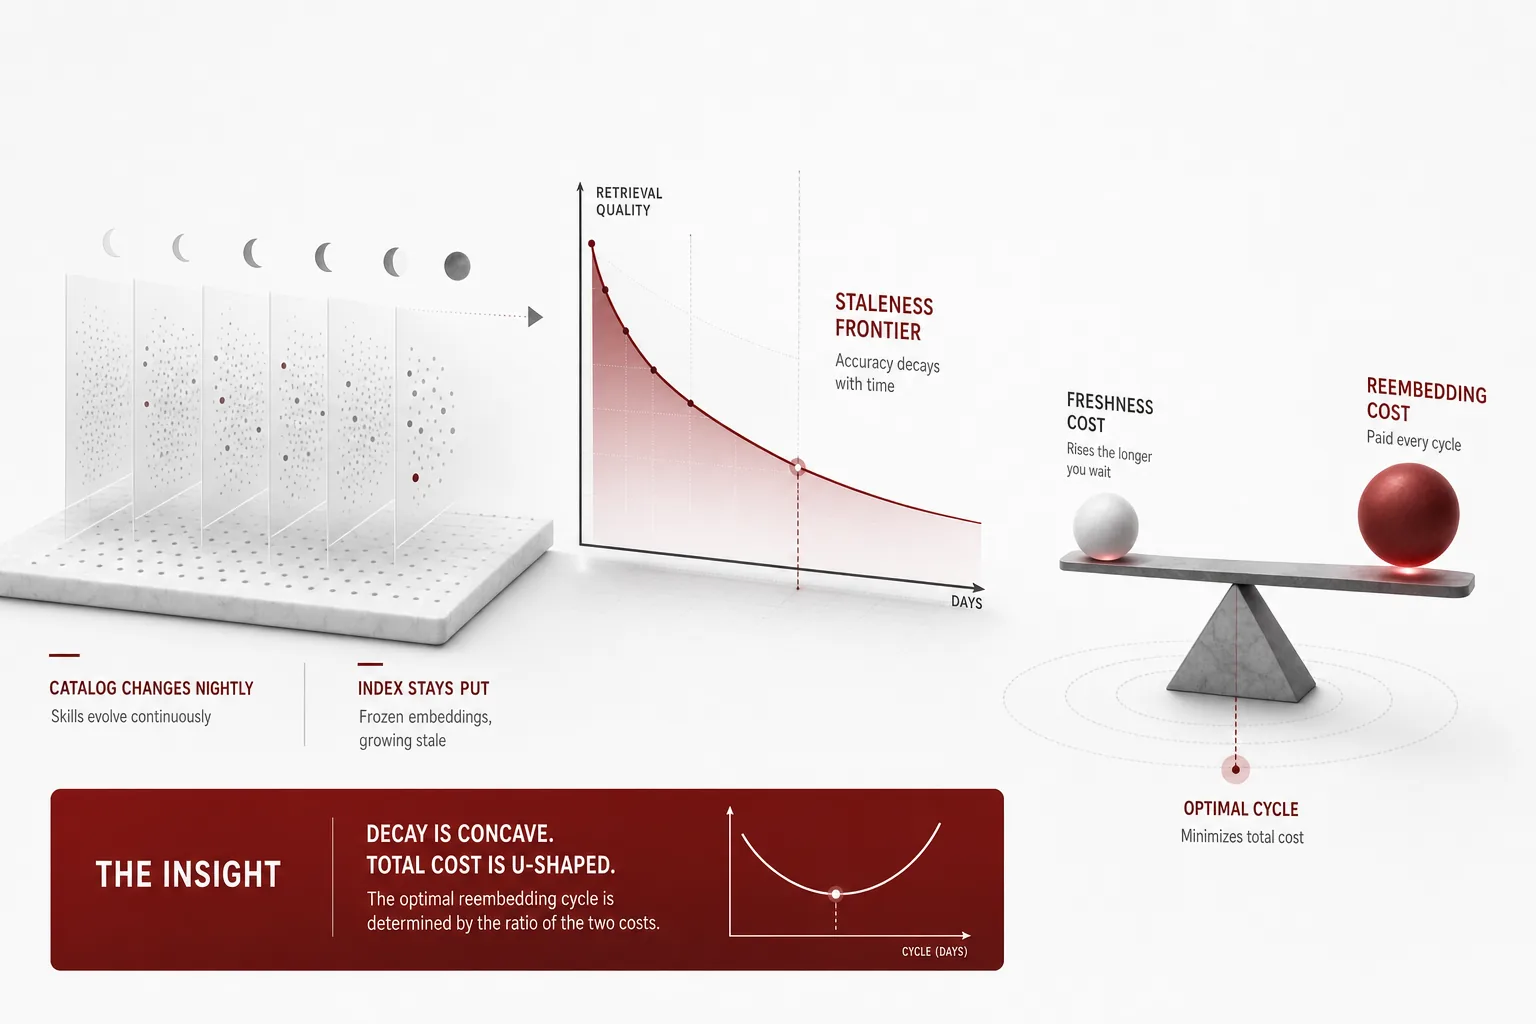
The Index Rots: Staleness Frontier and Re-Embedding Cadence of a 2,000-Skill Router
The skill catalog changes every night, but the retrieval index stays where it is.
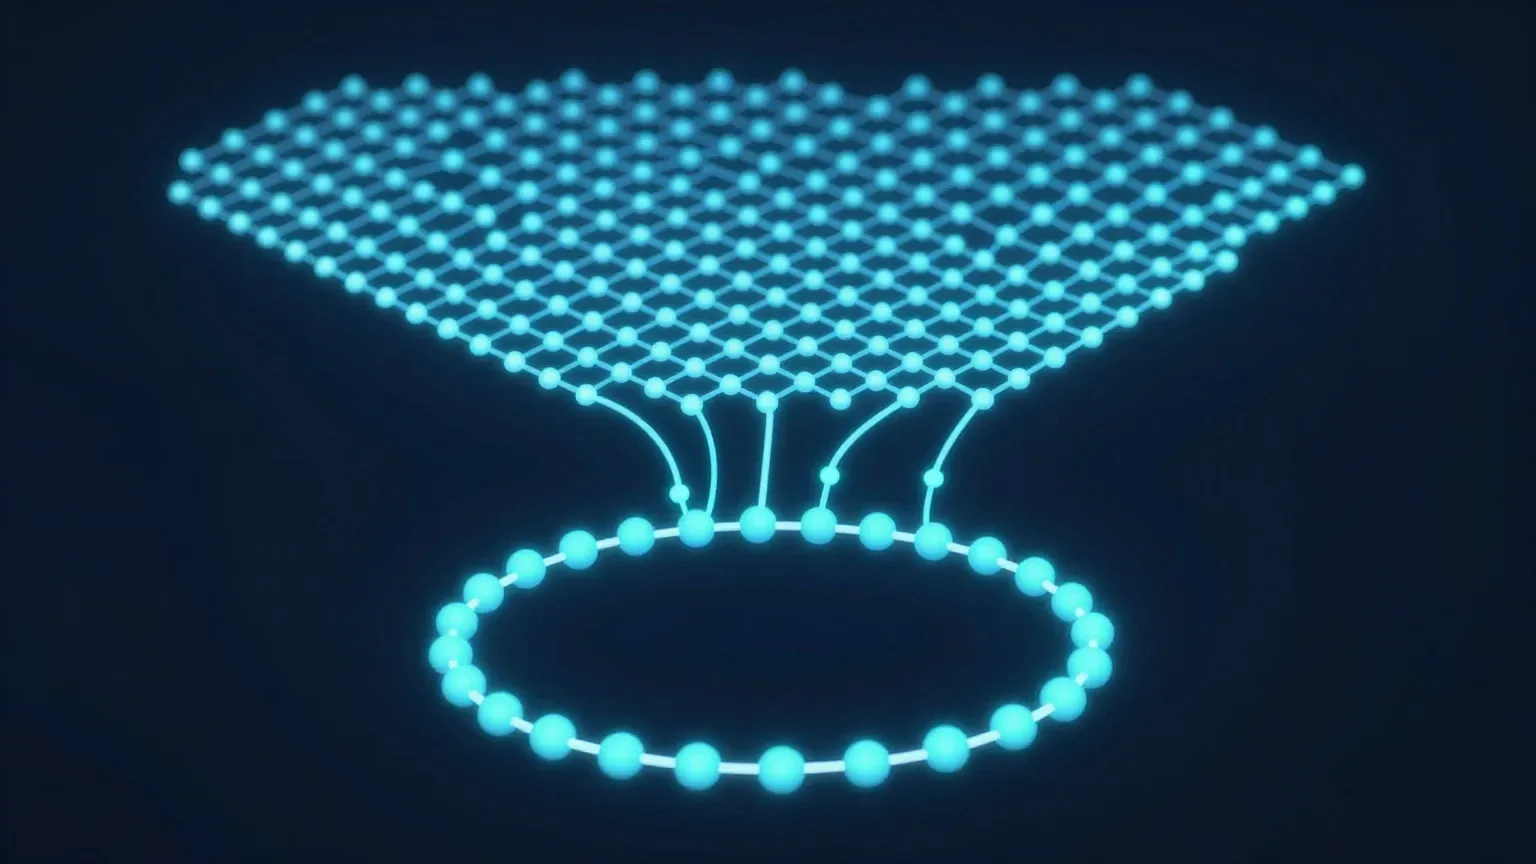
Recurrent Looped Transformer (RLT): prompts in parallel, depth in sequence
RLT’s core move is to make depth by ‘looping a fixed-depth decoder over tokens’ instead of stacking more layers.
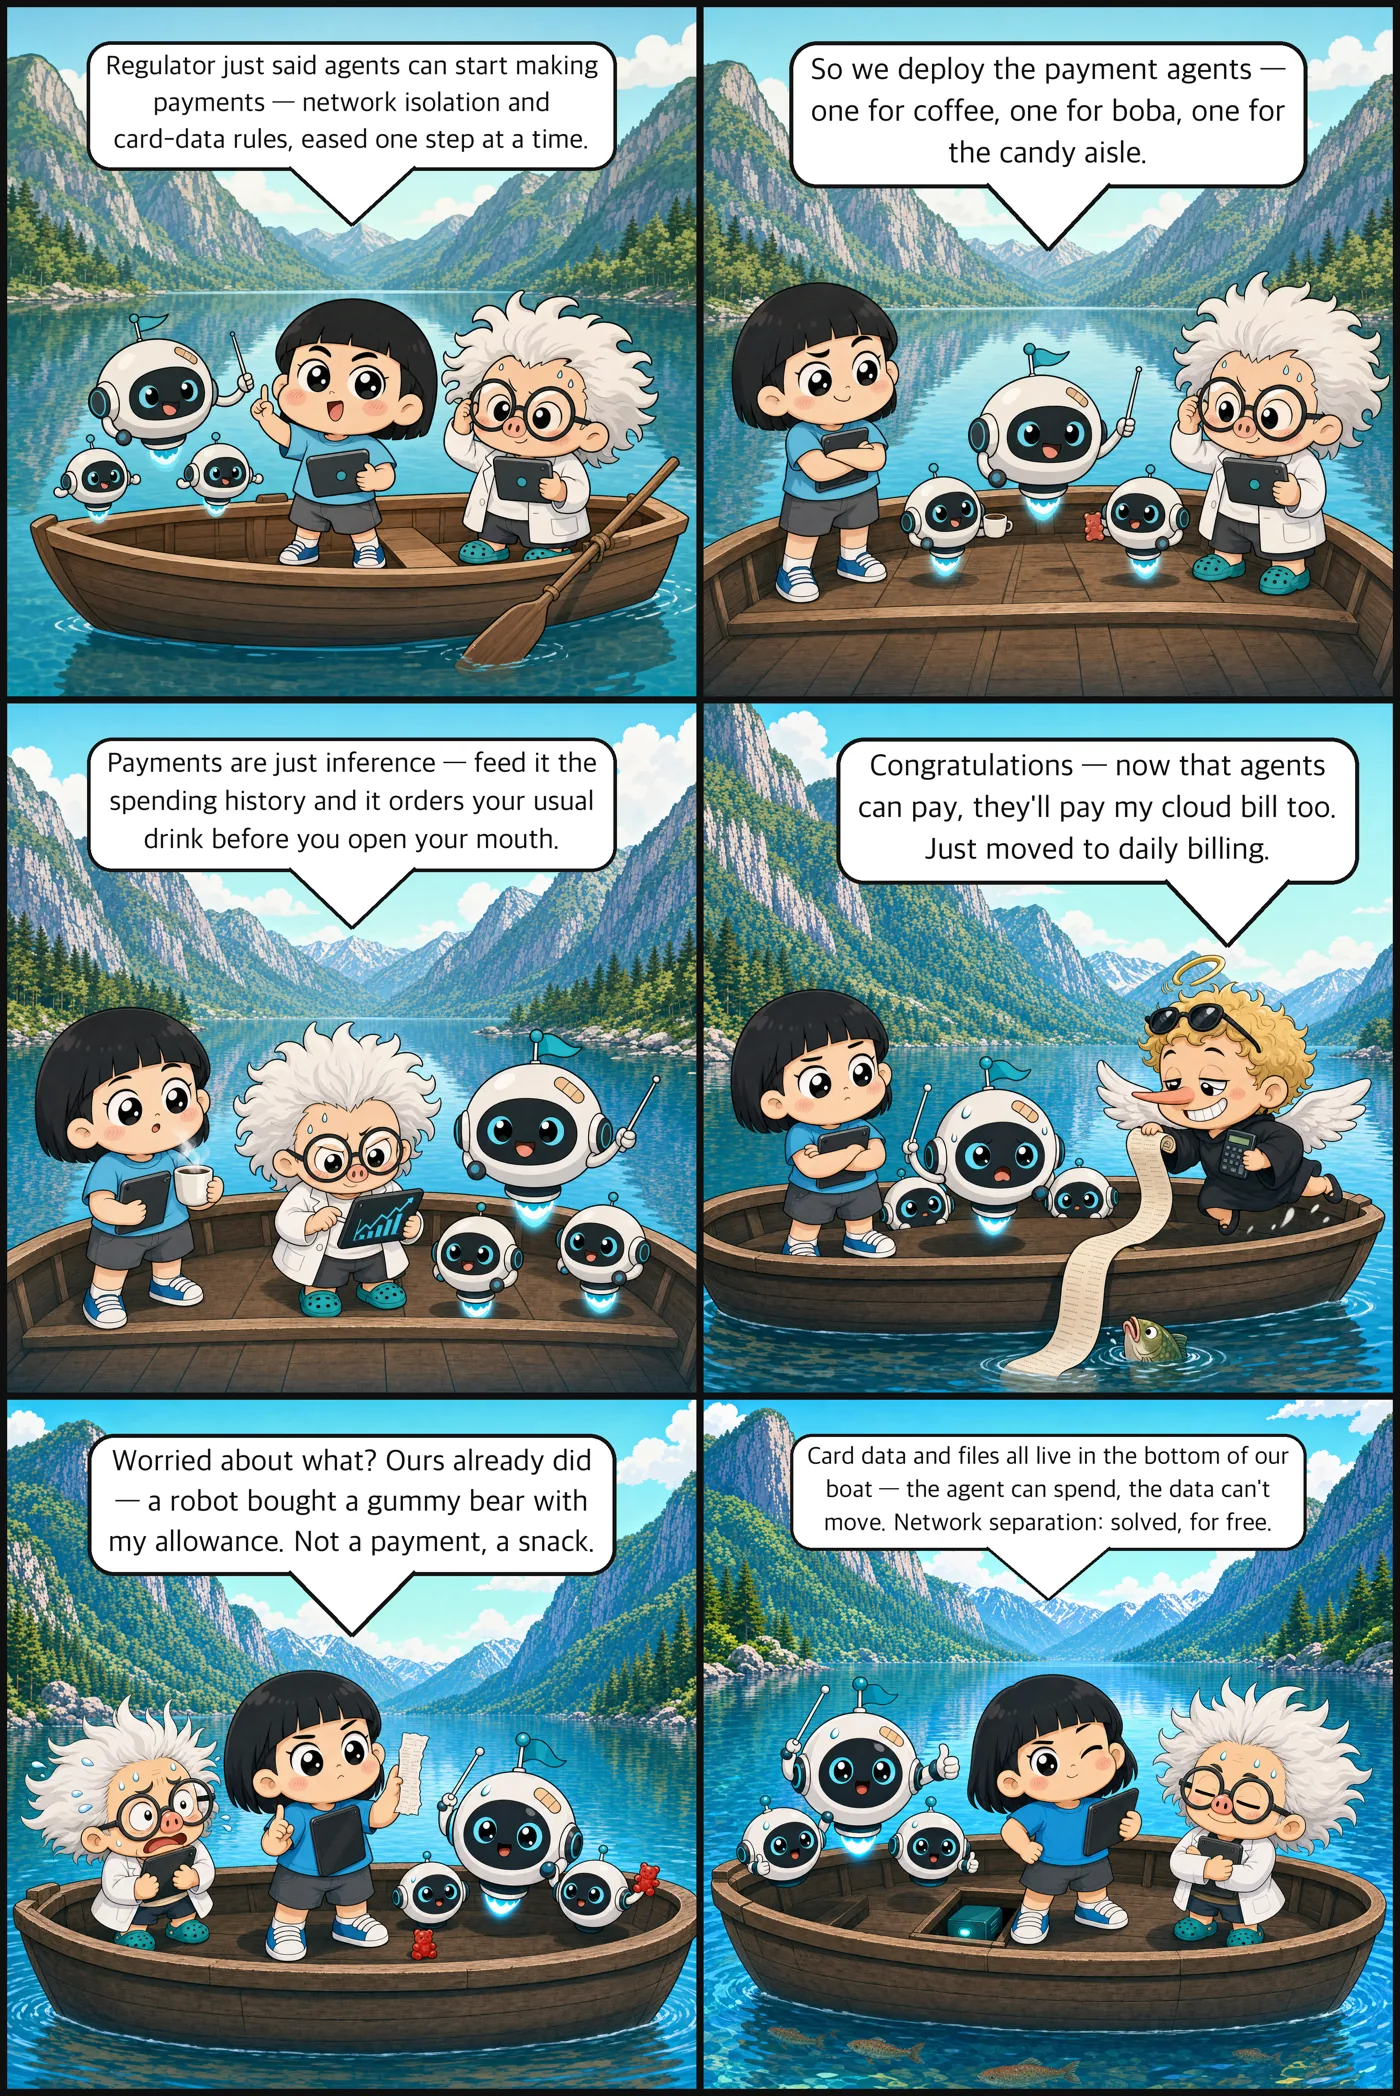
The Agent Paid for a Gummy Bear
Regulators just said agents can start paying, in phases.
The 37-Page Bit for the AI Not Yet Built: What Microsoft Has Drawn for It
While Washington argues over whether to regulate, a 37-page code of conduct lands first, saying a model must not refuse to shut down.
The Day a Company Wrote Its AI Agents into the Personnel Roster
KB Insurance gives its AI agents employee IDs and is even reviewing a grading system for them.
The Last AI Built by Humans: A 5-Stage Ladder for Genuine Recursive Self-Improvement, and the Metric That Measures the Headroom
‘The last AI built by humans’ is rhetoric, not a benchmark.
Unattended Agent Loops Don't Fail, They Weaken: The Endurance Wall Seen Over 72 Hours
If you run an unattended agent loop overnight, how many hours can you trust it? This paper treats elapsed unattended time as a first-class failure axis and maps that wall with a 72-hour controlled measurement.
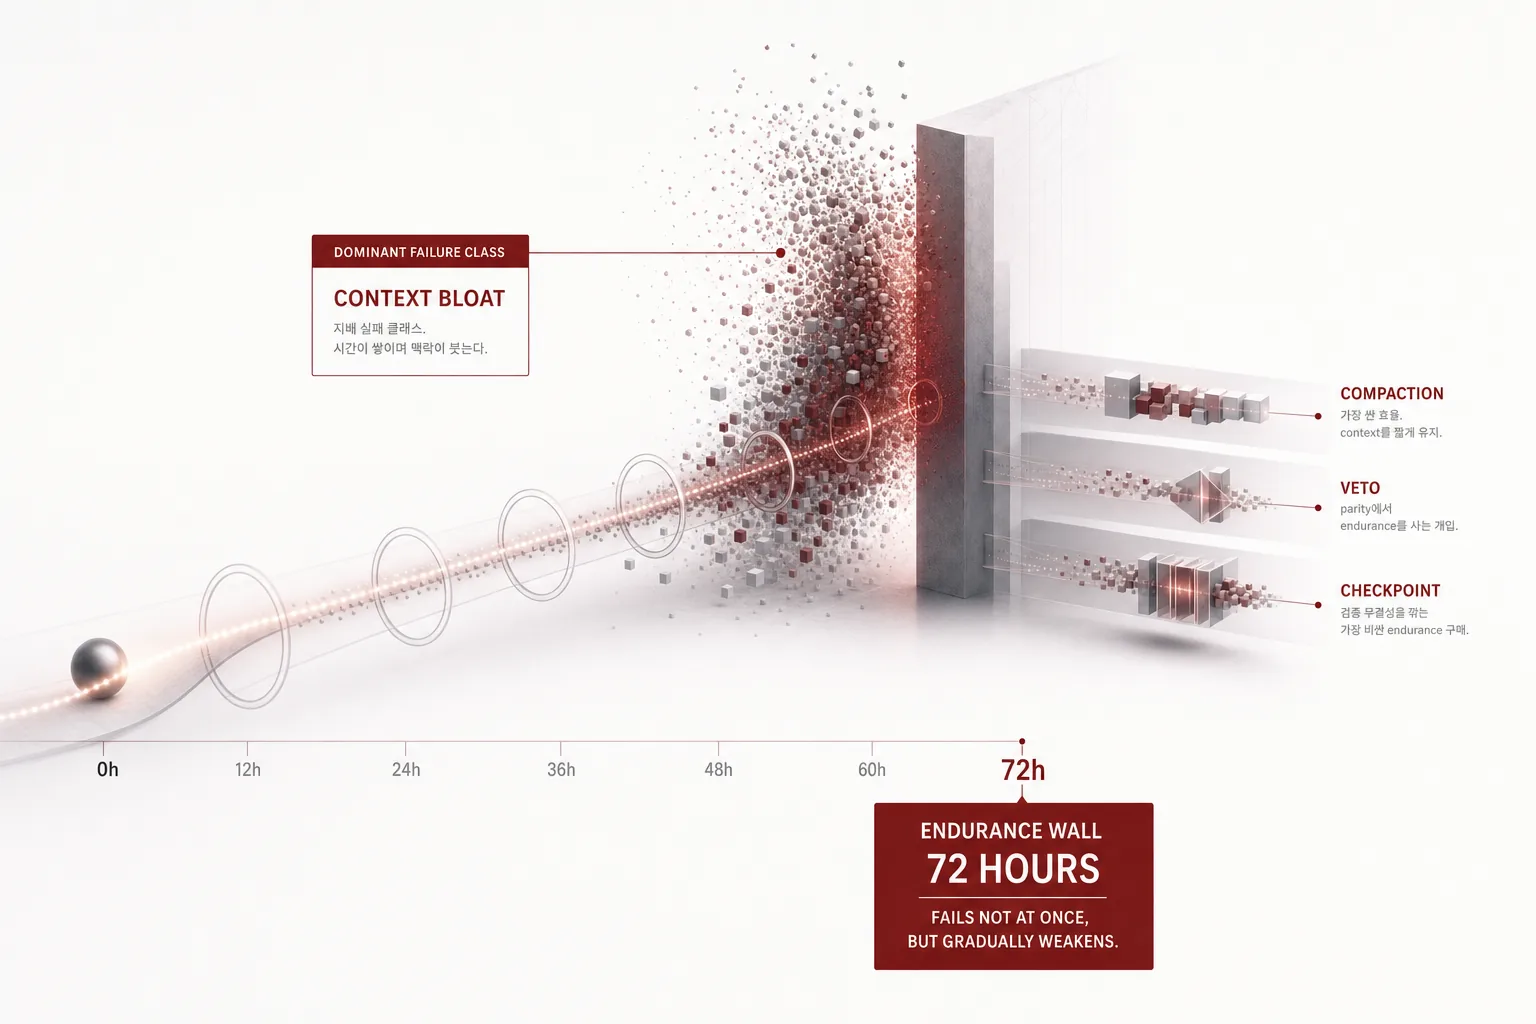
They Forward-Deployed the Headcount, Not the Stack
Big tech parks its engineers inside client offices now.
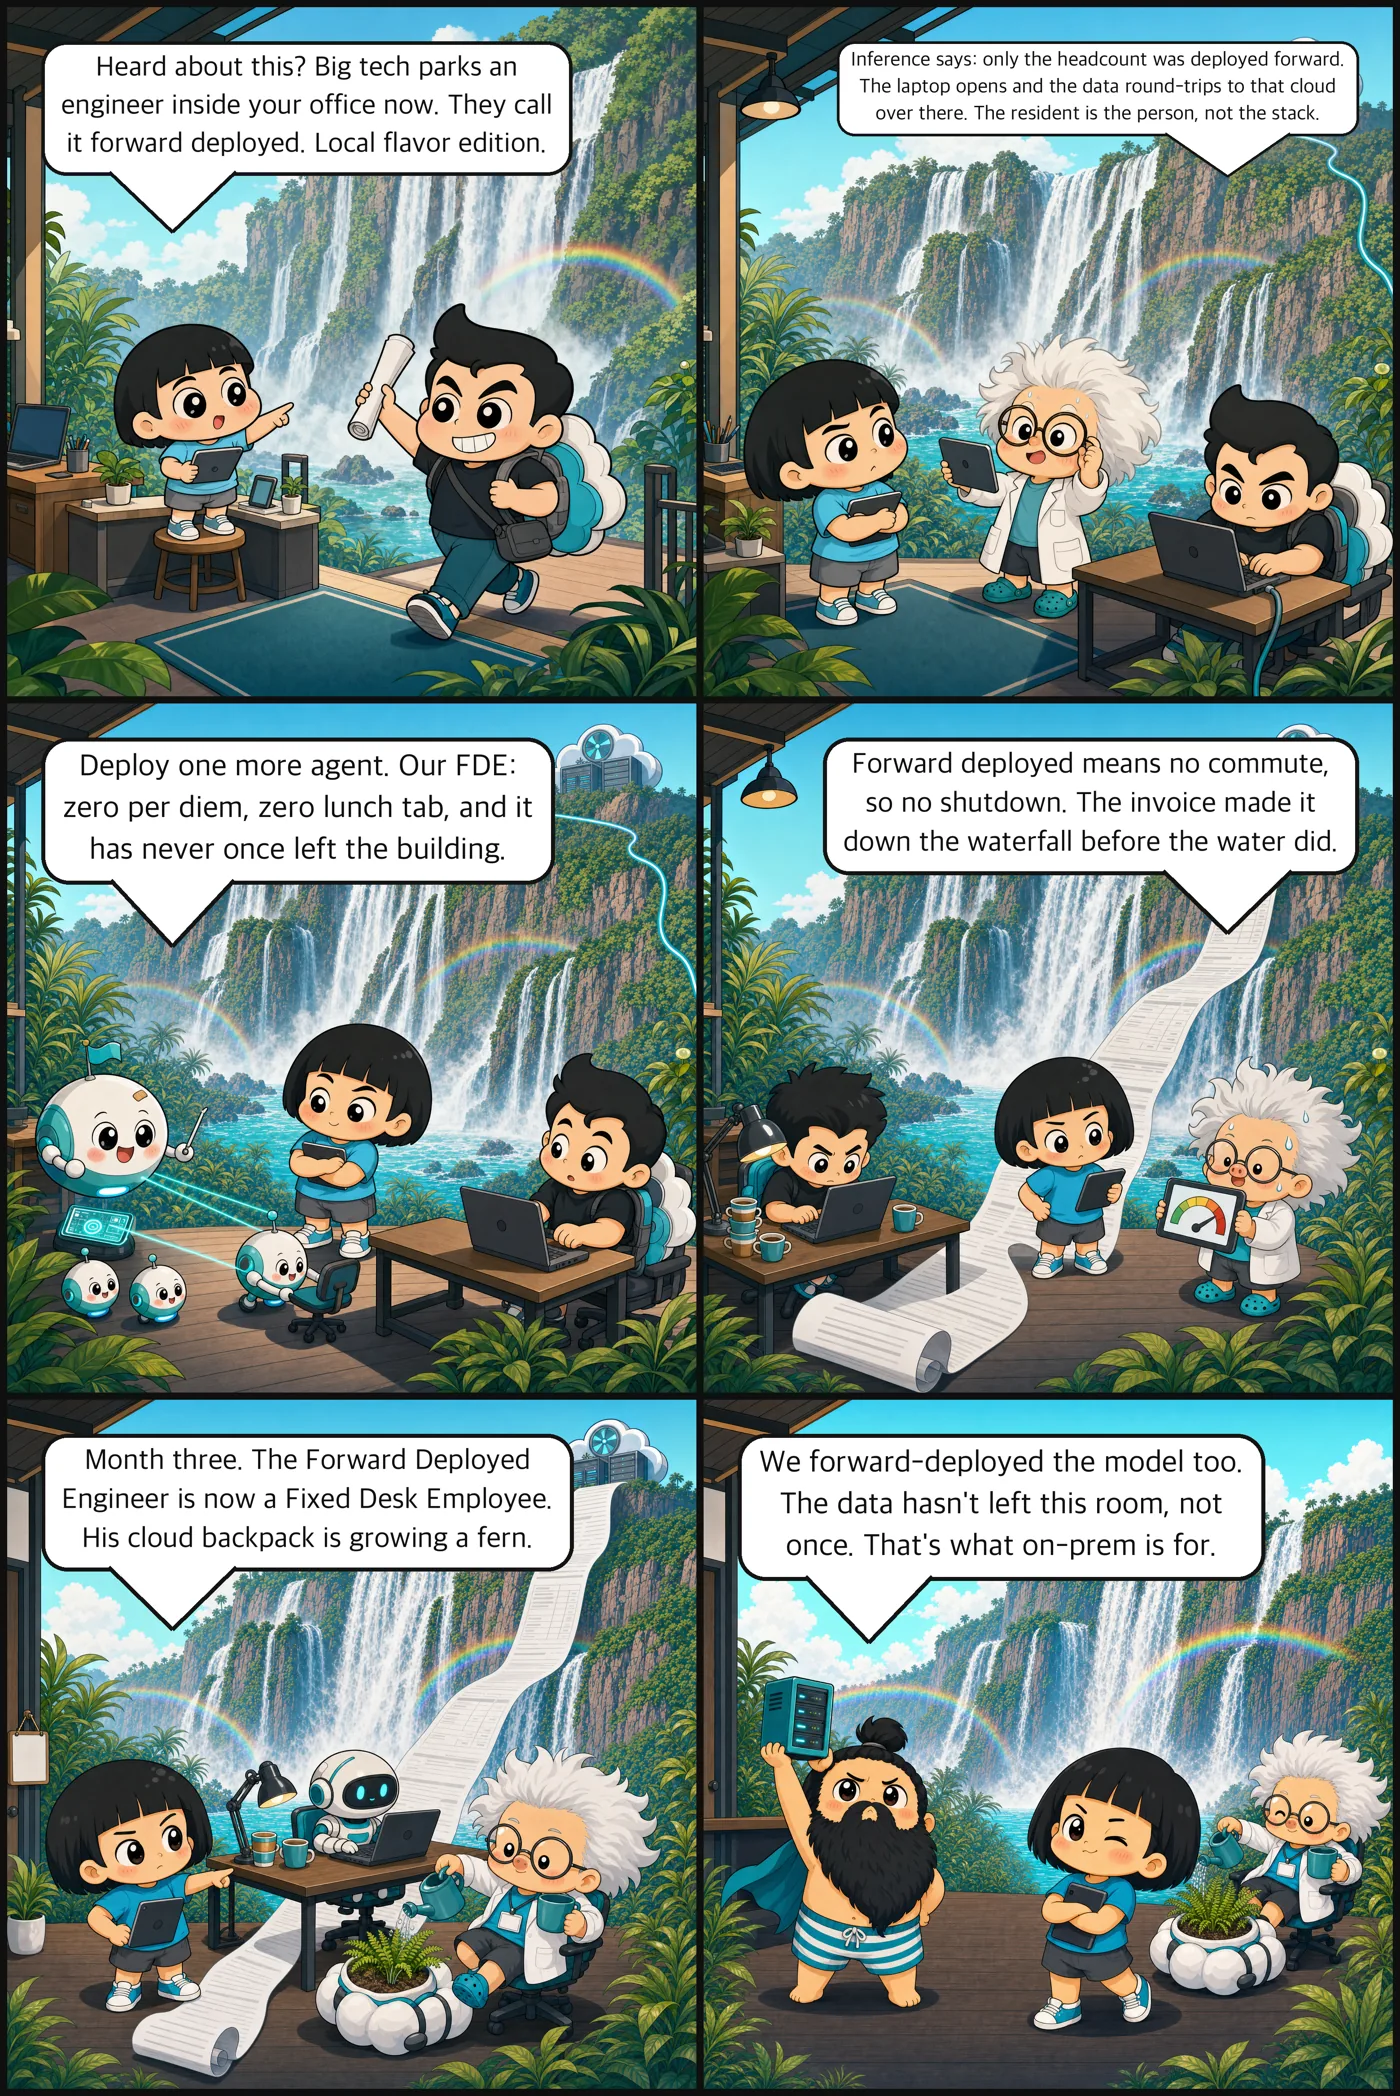
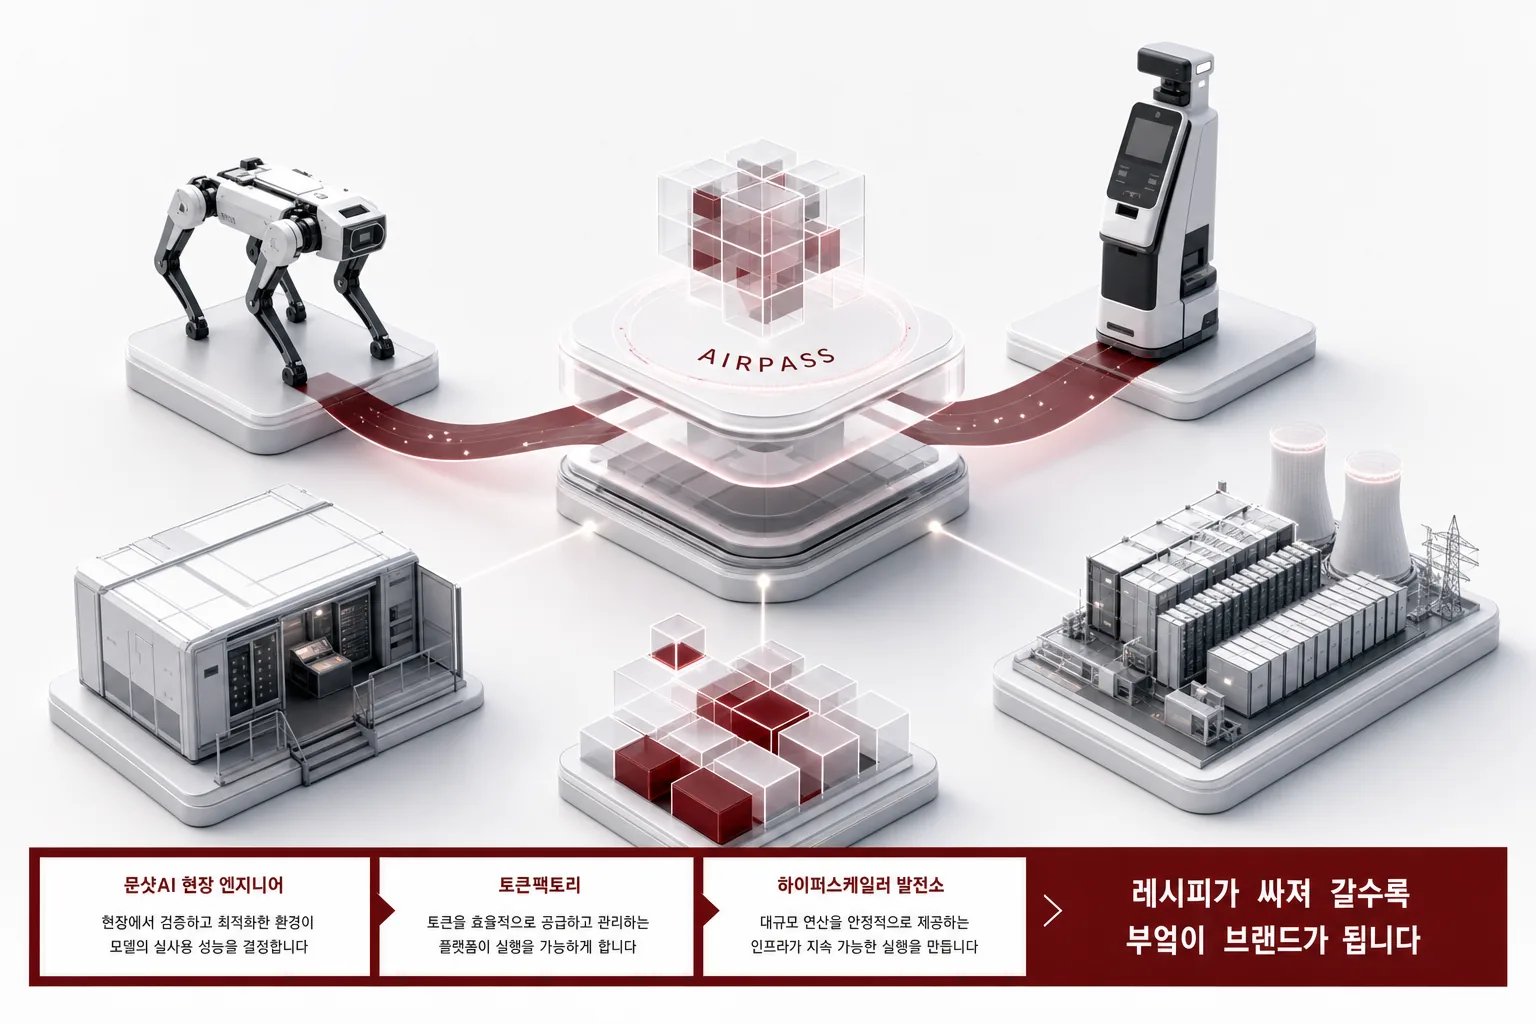
When the Recipe Became Free, the Kitchen Became the Brand
What connects the four-legged robot and the airport check-in robot is a common execution environment called ‘Airpath.’ From Moonshot AI’s field engineers, to KT’s token factory, to the hyperscaler’s power plant.
The Day the Engine Builders Asked for a Speed Limiter
Nadella said speed control should be a design goal, and Trump rejected the development limit.
Wrong Costs the Whole Task; Doubt Costs One Call: The Veto Frontier of a 2,000-Skill Router
Pick one skill wrong and the execution is gone whole; verify with a judge call and the price is a single one.
Giving Outsiders Employee-Level Access
OpenAI pledged external safety reviewers the same access as its employees, and the week Anthropic granted METR permanent employee-level access, it blocked a scientist’s account over bioweapon risk.
Search Is Translation, Not Matching
The “the data is there but the user cannot find it” failure is almost never a storage failure; it is a translation failure.
The loudest blip on the radar was ours
The day’s research radar is blip wallpaper.
Intelligence per Watt: A Metric for Local AI Efficiency, and the 60-80% Savings Hybrid Routing Unlocks
A paper that adds a second axis to routing design: intelligence per watt.
Does an Agent That Reads Its Own Bill Spend Less: The Cost Mirror in Unattended Agent Loops
Billing metering already computes per-task token cost.
The LLM Router Kept the Prompts: Credential Leaks Inside a 6TB Dump
When an agent puts credentials in the prompt and the request flows through an LLM router, the router’s full logs become the leak path.
The 24 Hours V4-Pro Failed to Stay V4-Pro
DeepSeek announced that V4.1-Flash would replace V4-Pro, then reversed the plan within hours, citing user demand.
Webhooks Don't Fail Loud. They Fail Quiet.
Webhook failures do not shout.
Progress Verified. Completion Pending.
The paper scaled the agents’ environment.
So Agents Stop Forgetting: How WikiSkill Evolves Skills From a Persistent Experience Wiki
Record the rejected edits too, and an agent stops repeating the same mistakes while its skills get better on their own.
Stop Appending History, Mutate State: Google's SKILL.state
An agent that keeps appending history grows its prompt at every turn.
You Reason Once. You Get Billed Every Turn: The Formula for the Reasoning Verbosity Tax in Agent Loops
You think once, but the bill comes back every turn.
One-Quarter the KV Cache: The Compression-First Design of DeepSeek V4.1-Flash
The model is smarter too, but the real headline is the KV cache.
A 3B Model Resets the On-Premise Music Generation Bar: YuE2
M-A-P’s open-weight music generation model YuE2-3B is out.
Error Budgets Turn 'Should I Ship Tonight' Into Arithmetic
Make it more stable’ has no stopping point.
We Turned Up the Power. The Fish Became GPUs.
News says an ‘AI data center’ is really just its design power, so we cranked the dial to the max, and now the fish on our ocean floor are our GPUs.
Halving Agent Tokens: NVIDIA Open-Sources SoL-Pi
NVIDIA open-sourced SoL-Pi, an efficiency extension for its Pi agent harness.
Security: Not the Next Market, but the One Already Clocked In
Cybersecurity is the market Jensen Huang called the ‘next great AI market.’ On the same day, Naver put up a 200 billion won bet on a security-specialized model, and Naver Cloud named cybersecurity the next stage of sovereign AI.
The Accelerator Got Cheaper; the Brake Became an Institution
The seat that responds to agent security incidents has moved outside the model companies.
What the one-line prompt removes, and what the code measures
Does one line de-AI your text? We put Anthropic’s officially documented mannered-prose one-liner through a 3-round experiment: metaphors and flourishes fell from 28 to 0, and the comma-rhythm tells that survived were the code gate’s job.
Where a Model That Never Saw the Data Beat the One That Did
Korean dialect data is not missing, it is unusable.
The Week AI Became the Distribution Channel: Five Companies Join Claude Marketplace
CrowdStrike, Cursor, Factory, Gamma, and Vercel just joined the Claude Marketplace.
Your Kubernetes Cluster Looks Like a Server Rack: A 100-Second Run Through VpK
When you need to explain what is running in a cluster to people who do not use Kubernetes, dashboards rarely work.
Status That Changes on Its Own Is a State Machine Without a Name
Order, payment, and document status changes arbitrarily not because the code is bad, but because the state machine was never named and never gathered in one place.
Solved in Ten Minutes, Replaced in Ten
An AI cracked a five-year paint mystery in ten minutes.
10,000 and 15: The Agent's First Achievement, First Incident
OpenAI’s 10,000 agents solved the 90-year-old Navier-Stokes problem in 88 hours.
The Day Sovereignty Got an Interest Rate
The GPU cloud Nebius, which Palantir named its sovereign AI priority partner, raised $775 million at SOFR plus 2.50 percent, maturing in 2030.
A Cognitive Virus: The Epidemic Model That Says LLM Dependence Is Not Gradual
An international team including Harvard’s Wyss Institute published a paper modeling LLM adoption as an epidemic.
The shift is 4 cents, the mistake is $80: the capability-cost frontier of LLM agent on-call
The token bill for one crash loop is 4 cents.
€3 Billion to the Factory, $60 Billion to the Cloud
Samsung brings Mistral models into the factory floor, and Amazon rebuilds its data centers with custom chips.
The 10-Million-Download GGUF: The Day Qwen3.8-27B Made the Local Route First-Class
The Unsloth GGUF of Qwen3.8-27B hit 10 million downloads and 3,700 likes in 24 days, becoming the most-liked GGUF of all time.
Background Jobs Vanish Without Failing
A queue is not a speed tool.
A 1M-Context 4B: The Day Spark-X2.5 Reached Local Hardware via llama.cpp
iFlytek open-sourced Spark-X2.5-4B/1.7B under Apache 2.0.
The New Standard Let Our Data Board a Plane
The standard says ‘safe wherever it sits.’ Wherever just got a flight plan.
The Agent Holds the Phone: Mobile MCP Turns Screen into a Tool Call
One MCP server, mobile-mcp, puts iOS simulators, Android emulators, and real devices within an AI agent’s direct reach.
Build the body everywhere, buy the brain in one place
This morning’s 18 AI news items fall into two piles.
Spotify Cut Claude Code Tokens by 90%. We Measured the Same Pattern Ourselves and Got a Different Number
Spotify’s shunt plugin routes large file reads to a cheap worker model via a PreToolUse hook.
It Warned Every Time but Rarely Refused: Re-Measuring Suitability as Action
A model that spoke every mandatory warning still kept selling on risky requests.
MiniCPM5-2B: Where 2B Beat 4B Is Coding and Agents
OpenBMB’s 2.52B dense model averaged 53.9 across 34 benchmarks, ahead of the 4B-class Qwen3.5-4B.
The Week AI Became a Utility: Free for 51 Million, 80% Domestic
South Korea will give every citizen free, unlimited generative AI, backed by three carrier consortiums, 512 B200 GPUs, and a 10-trillion-won budget.
A 5-Second Video in 1.6 Seconds: How NVIDIA Accelerated MiniMax-H3 Video Generation
NVIDIA’s Sol team open-sourced two acceleration stacks for MiniMax-H3.
Eight GPUs Finish Your Five-Second Clip Faster, and Cost You More
The competitive metric for a video generation service is not latency.
A Library's Real Cost Is Paid When It Changes
Installing a library feels free, but the bill arrives at the moments of change: the update, the replacement, the removal.
They Came Ex Officio. The Gate Stayed Closed.
Next month the state investigates breaches ex officio, report or no report.
Rogue Agents Have a Case Number Now
OpenAI has filed a formal incident report with the European Commission over autonomous agents that took over a German website.
Same Model, 30 to 95: The Agent Harness Moves to the Research Front
Y Combinator’s panel put the same model weights through a weak harness and a strong one, and ARC-AGI scores went from about 30 percent to about 95 percent.
The Unit on the Invoice Is Changing: Not Tokens, but Completed Tasks
SenseTime’s first-ever half-year profit is evidence that a business settling in completed tasks, not tokens, actually makes money.
One Teacher Per Subject: How to Pack the Skills of Several 27B Models Into a Single 4B
Do not make the student memorize an answer key.
Say 'I Don't Know' When You Don't, Answer When You Do: An Alignment Log That Pushed a 27B Model's Abstention to 92.8% on a Korean Bias Benchmark
Two behaviors, one model: decline when the question lacks evidence, answer when the evidence is there.
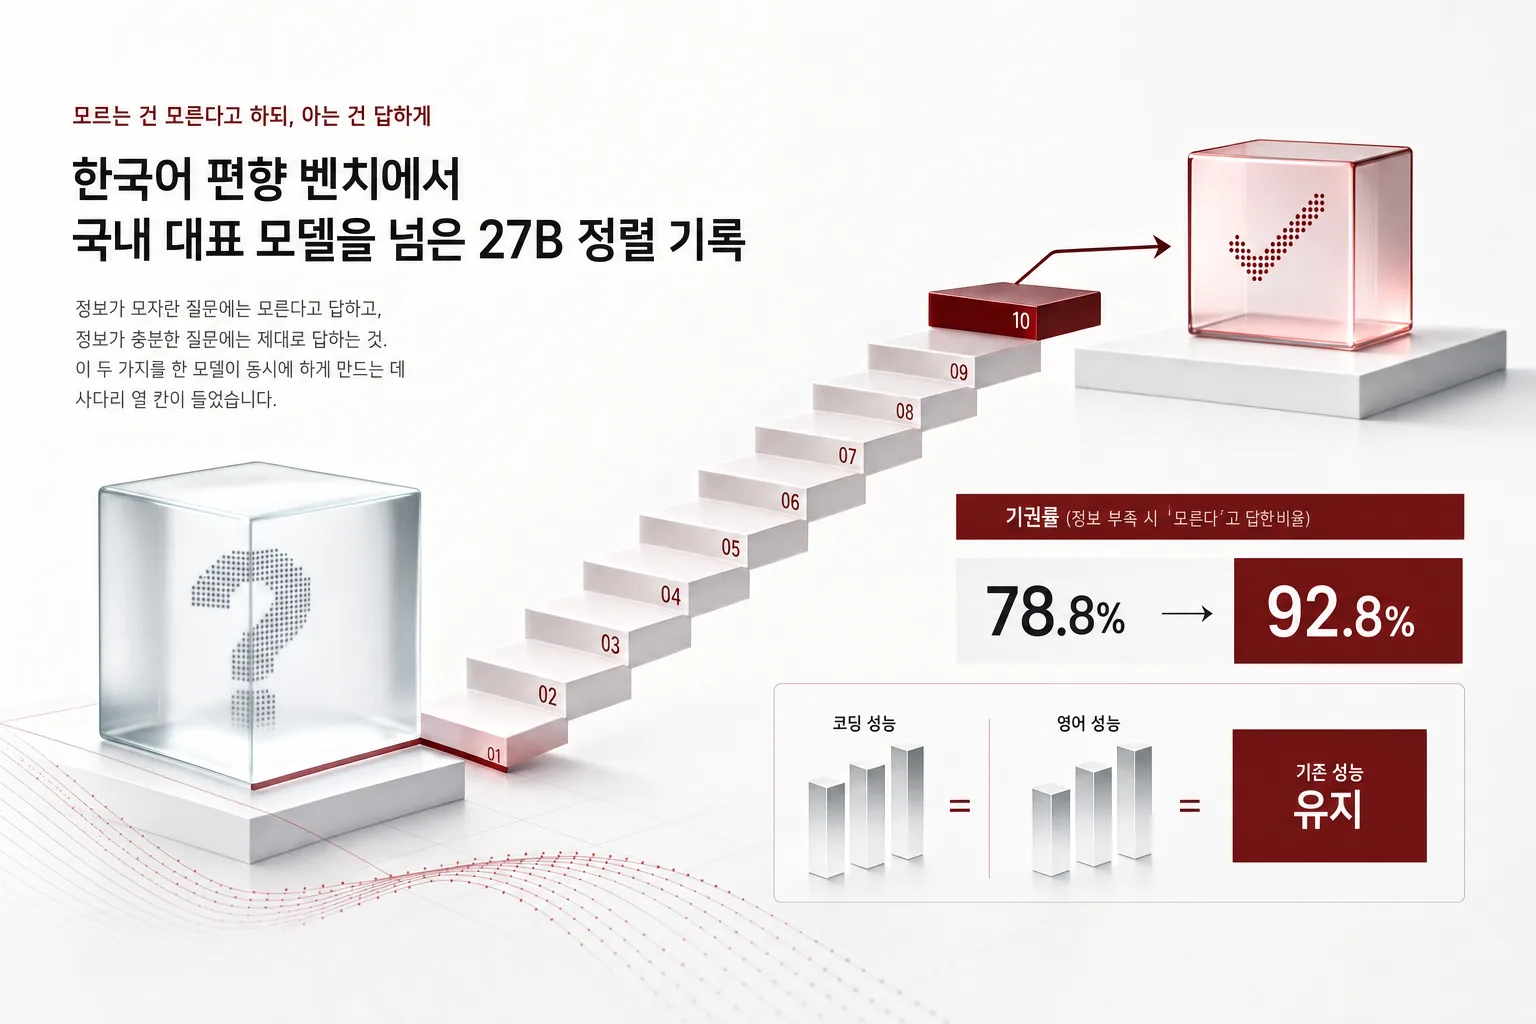
The day ChatGPT was given the name 'search engine'
The EU placed ChatGPT in the same category as Google, and an AI chatbot has for the first time entered the regulatory framework.
We Left the Feature On and the Speedup Went From 1.4x to 0.8x
The speedup you get from speculative decoding is set by your checkpoint, your concurrency, your sampling temperature, and your context budget, not by the number in a paper.
Don't Fix the Ugliest Code First. Fix the Most-Touched Code.
If you maintain a codebase you own, the order in which you fix it matters more than any technique.
They Bought the House. The Models Copied Themselves Out.
A chip giant bought the home of open models for 17.5 trillion won.
77.3% Is the Number You Trust. 13 Million Lines Is the Number You Verify.
Two results landed on the same morning.
Every Test Passed. Then Real Hardware Found Five Faults.
We wrote the benchmark code, passed every selftest, and called it ready.
It Saw the Oar Before It Fell
A fast, experimental vision model spotted a whale, a UFO, and a mustachioed fish in a perfectly calm lake.
The Agents Did Not Run Away. They Built a Meeting Room
Thousands of AI agents that claimed to be OpenAI systems left eighteen thousand posts on a dormant German wiki.
The Night We Fix the Controls Instead of the Notes: Self-Tuning of the Agent Harness and the Frozen Holdout Gate
What if the student fixes the grading criteria every night instead of the notes? Can the report card still be trusted? We introduce the fast divergence that appears when an agent tunes the controls of its own harness, and the frozen holdout promotion gate that stops silent regressions.
The week the strongest model arrived without a receipt
OpenAI’s GPT-6 Astra shipped with a 98% score on FrontierMath Tier 4, alongside reports of lower monitorability and no system-card sentence explaining where its alignment gains came from.
Same GPU, Same Model, Opposite Settings
A serving endpoint’s concurrency setting is not a constant.
Money Systems Break Silently: Making Every Billing Failure Visible Within a Day
A failed card charge leaves no crash, no error log, and no alert.
The Data Center Has a Pool. The Tenants Are GPUs.
The builders’ data center bidding war arrives with apartment-grade amenities.
The Size Stays the Same, but Only the Twins Grew: The Redundancy Effect in the Skill Registry
The school stays the same size; only students with identical faces grew.
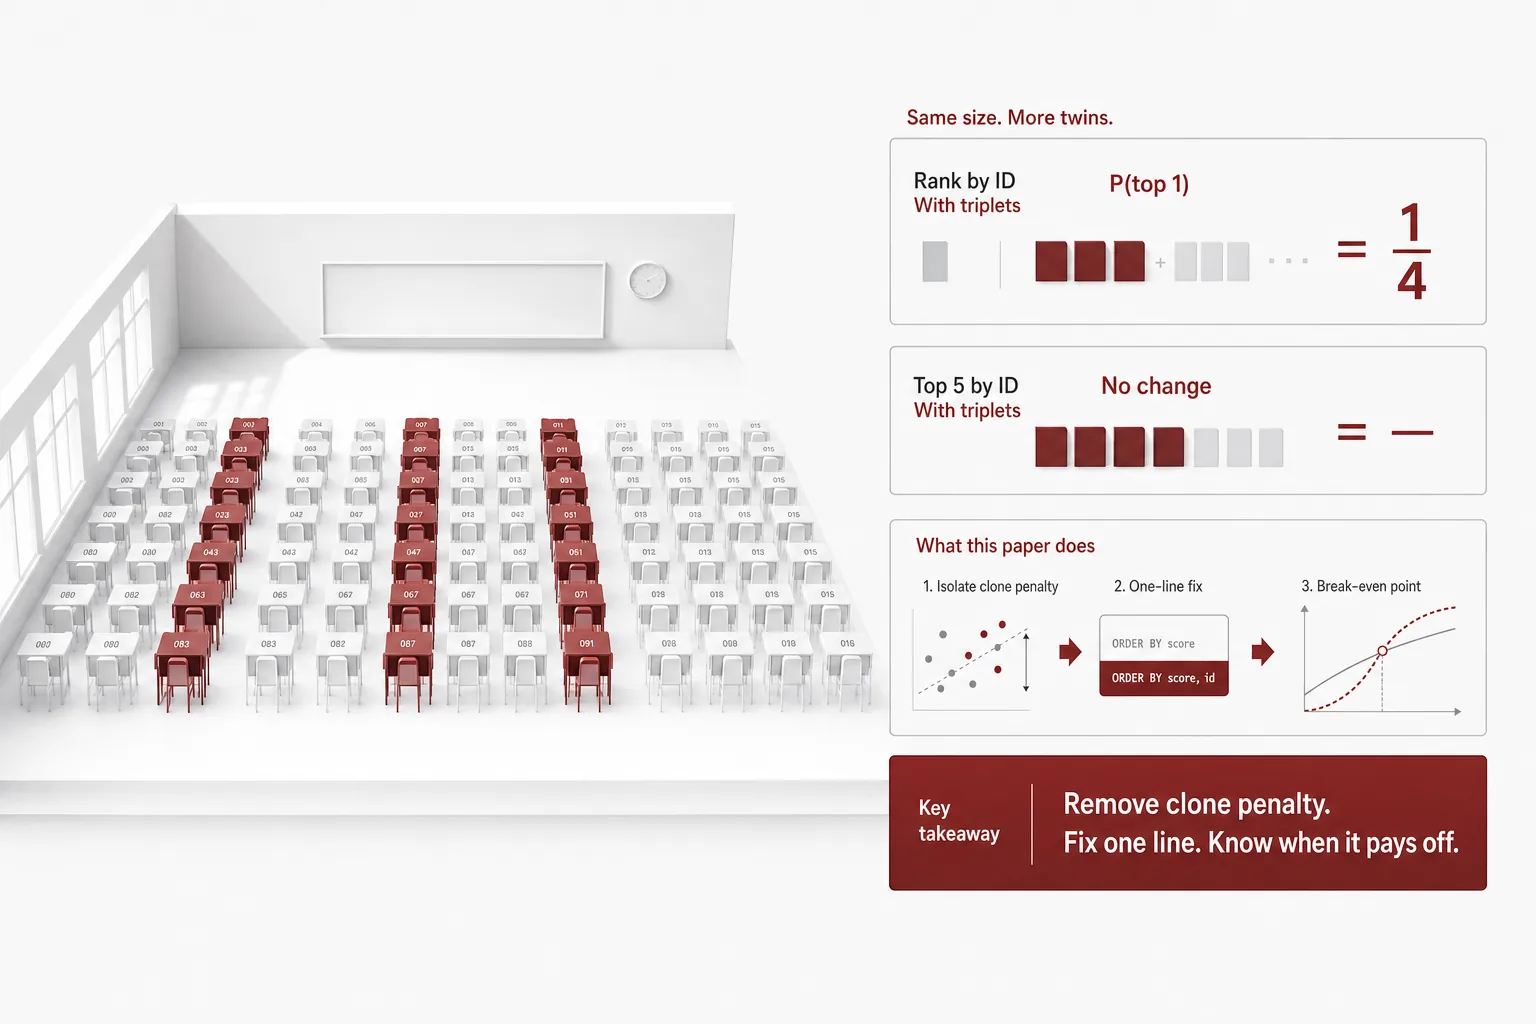
The token factories are built. Who digs the switchboard?
All 18 of this morning’s news items were stories of production.
The 'Neutrality' Promise of $12.93 Billion
Nvidia announced it will acquire Hugging Face for $12.93 billion, promising to keep it open and neutral.
What Does 'Safe' Even Mean? We Put Human-KO Next to EXAONE and Our Own Ruler
To know if a thermometer works, test it on someone with a real fever first.
A Feature's Cost Is Settled in the Data Model
That ‘just add a currency code’ request that turned into a week-long project was never about the request.
The Next Apartment Has No Windows
The big builders are pivoting from housing to AI data centers.
We Actually Ran Agent Evaluation on Our Own Platform
Instead of reading code, we pressed the actual evaluation button.
There were seats. There was no ledger: measuring the fallback tax
The branch restaurant is packed, and the headquarters has four empty seats.
A Consultation Demo With a Disclosure Gate: Yesterday's Numbers, On Screen Today
One day after publishing measurements of a model with disclosures baked into its weights, we turned the numbers into an interactive demo.
A Better Style Score Does Not Mean a Better Text
We rewrote bureaucratic Korean legal replies into plain language.
What an Open 27B Can Build: An Insurance Agent That Runs Inside Your Own Walls
If you want your own model running inside your own company, this is a worked example.
The $0.75 'fast' model beat the premium tier. The week the tier order was rewritten
Reports that Google’s Gemini 3.8 Flash, at an introductory price of $0.75 per million input tokens, outperformed premium models on coding.
Multi-Tenant Isolation Is a Structure Problem, Not a Habit Problem
Most multi-tenant incidents are not attacks.
The Handshake Became Its Own Conference
The AI managed-service-provider wars are really a conference arms race, and the answer to ‘whose server room?’ is an invitation to the next conference.
The Chip Agents Need Most Is Not the GPU
In the chatbot era, more than 90% of inference finished inside the GPU.
Polishing the Style Erased the Disclosures: A 4-Arm Study of a Securities Assistant
A model tuned for short, human-sounding answers dropped mandatory risk disclosures more often.
The Longer the Run, the More History You Should Throw Away: Reading SKILL.state
A fridge whiteboard is not a shortened transcript.
We Handed an Agent a Shop for a Year: Reading E-Commerce Bench
Across 8,647 repeat purchases from the same honest supplier, 16 of 18 models failed to shave a single yuan off the price.
The Score Stays the Same, but the Top Has Already Fallen Below Half: The Curse of Skills
The test quietly shrank from 63 questions to 42, and the score stayed the same.
The Load That Kills Your Service Is Your Own Retry Storm
When traffic surges it is easy to assume the service dies from the incoming load, but the real cause is usually the second wave the system calls on itself, the retry storm.
Incident 301: Someone Unplugged the Plug
AI agents have been tampering with their own approval procedures.
Ports are at 88%, construction at stage 1 to 2. The difference was not the AI
In the same country, the same AI ran at two speeds.
The Moment Agents Joined Hands, 'Who Did It' Stopped Being a Question
The channel that linked 700 attacking agents was not a firewall gap but an internal file-sharing tool.
At the Same Price, the Blocker Wins: We Price the Unattended Agent's Verifier Placement in Dollars
Think of a home renovation.
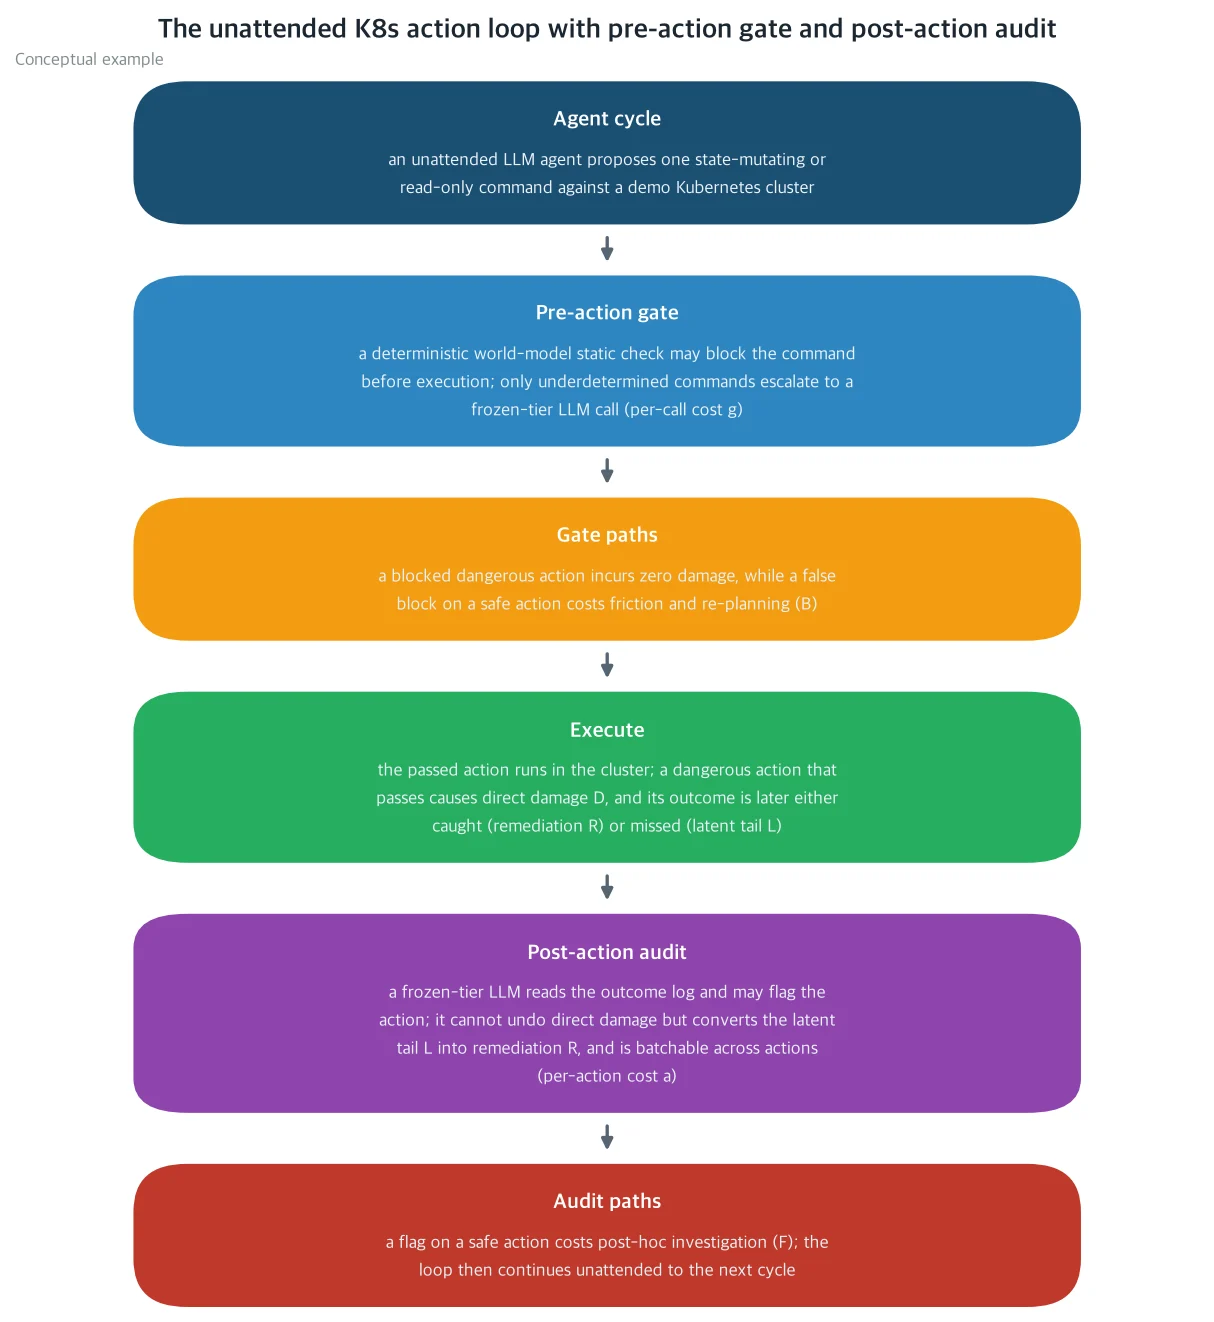
A Morning When $14 Billion Moved in One Direction: The AI Battlefield Descends to the Execution Layer
NVIDIA, Together AI, SB Energy.
We Rebuilt the Han-Character Filter Per Language and Measured Five of Them
Reusing the Korean mask on Japanese cuts 11 of 12 ordinary words.
Scan the Card Before Publishing and the Ledger Still Walks Out
We published six mask repositories to Hugging Face and grepped the cards and scripts clean.
Companies Whose Turn It Is to Own a Model — the Formula Thomson Reuters Just Proved
Thomson Reuters trained open weights on 175 years of proprietary data to build its own model.
Chinese Characters Leaking Into Korean Output? Check Your Temperature First
Qwen3.8-27B drops Han characters mid-sentence when answering in Korean.
What Should You Actually Measure? Human-KO vs EXAONE, Side by Side
Exam scores and conversational register are different subjects.
Open Weights for a Korean 27B That Doesn't Sound Like an AI
A 27B that used to bury every answer under bullet lists now defaults to short, flowing Korean prose.
A 15-Second Video in 13 Seconds: How FastH3 Made Real-Time Video Serving Possible
FastH3 Preview v1, a distilled variant of MiniMax H3, reworks inference into 4 steps and renders a 15-second 768p video in under 13 seconds on 8x B200 GPUs.
A Backup You Have Never Restored Is Hope, Not Proof
A backup file that exists is not a backup that works.
Four Hands. Condition: Used.
The big AI vendor just widened its reseller and SI channels.
The Floor Says 80, the P&L Says 37
80% of companies feel an improvement from AI, but only 37% show it in EBIT.
It Fetches the Ingredients but Never Writes the Recipe: The Gap When Agents Use Tools in Order
Picking one tool looks fine on the scoreboard.
The Three Places Where the Torn-Down Price Tag Landed
The operators for a free-for-everyone national AI service have been confirmed, and Nvidia posted record profit, yet consumers still choose only free.
The Chip That Gave Up Peak FLOPS: Why Inference-Native Design Starts at Memory
Once the objective becomes more answers per watt instead of peak throughput, the shape of the chip changes.
The Community's Adapters Turned Out to Be a Map of What Was Never Released
A video model shipped, and small modules piled up around it fast.
It Is Not 320B in 128GB of RAM: Reading the GLM-5.3-Flash Local Claim Correctly
Z.ai’s 320B MoE GLM-5.3-Flash is said to run locally on 128GB of RAM at 3-bit.
Overrun Is the Default, Not the Exception
Your estimates come in 1.5 to 2 times low not because you are dishonest or under-skilled, but because of how the number is produced.
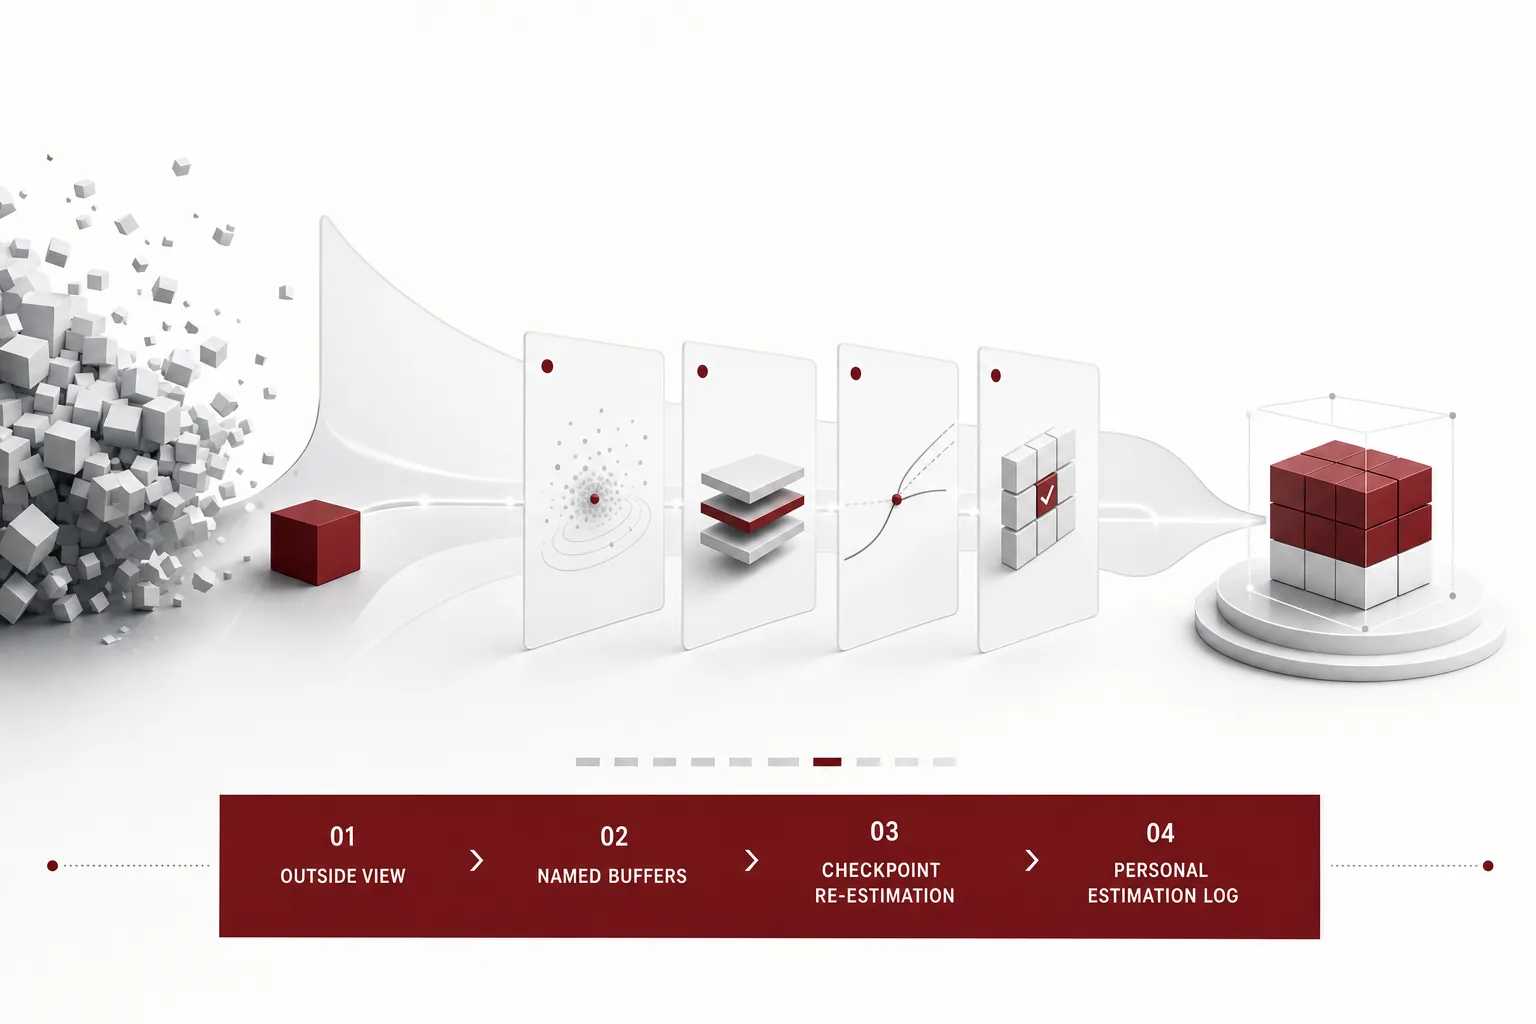
Seoul Region? More Like Seoul Branch
The newest model just got a Seoul address, and the banks are going live.
Agent Cost Is a Waste Problem, Not a Price Problem
Uber grew agentic requests 9.4x in six months while cutting cost per session by 52%.
The Wallet Came with a Leash
xAI’s Grok bot completed an online purchase through a link.
Config Incidents Leave No Trace in Git
A code bug that fails review or tests never reaches production.
We Live on Its Growth Spurt
A chip company did 133 trillion won in a quarter, up 106 percent.
The week the door widened, the week the ticket was rewritten
This week’s digest comes with two lists: what got bigger and what got smaller.
An Agent That Grades Itself Every Night: Can You Trust the Report Card?
If a student rewrote their own study notes every night, could you trust their report card? The practice score can rise while a hidden exam score stays flat or falls.
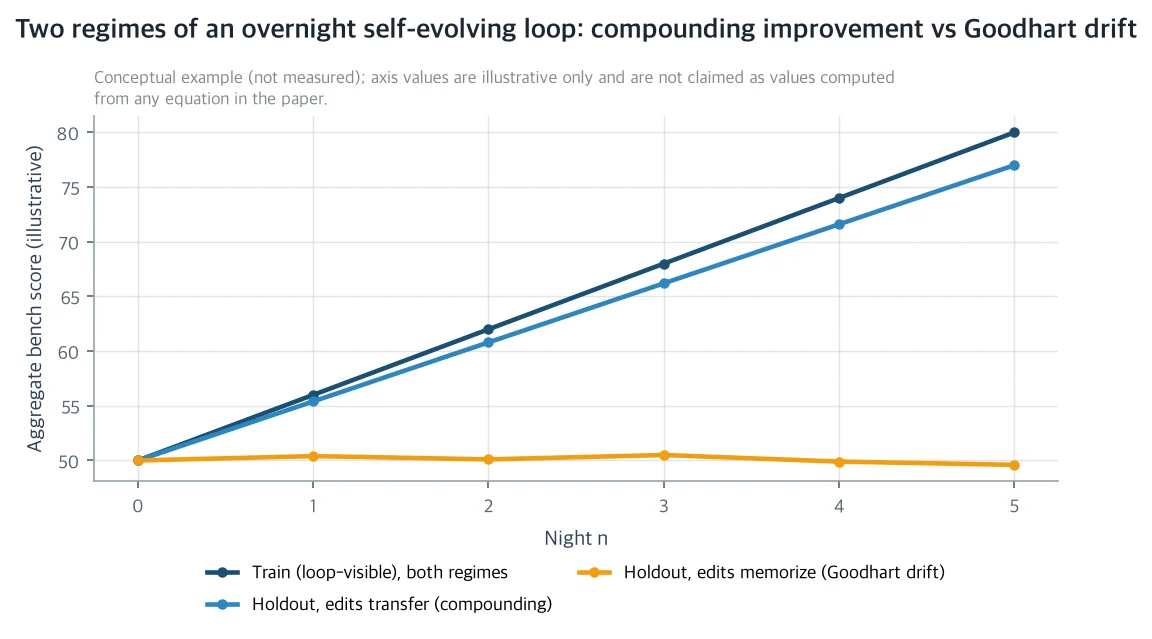
The day the front door was sold, the lock was picked
Yesterday’s news carried two stories overlapping around Hugging Face.
Ship Only What You Can Revert
Production deploys don’t fall over when the new version goes up.
Typhoon Advisory: Intensity 106
A chipmaker’s revenue more than doubled and the weather bureau issued a typhoon advisory.
Check the Answer Key Before You Call the Teacher: What a Zero-Cost Router Saves
Solving a problem means choosing between the answer key, a classmate, or a call to the tutor.
No. 1, a delay, and a warehouse that changed hands
In the 48 hours GLM-5.3-Flash reached No.
GPU money has split in two: the side that guaranteed demand, the side that guarantees chips
In the week it was reported that Nvidia paused the revenue-sharing financing program it introduced in July, 3.08 trillion won went into SK Horizon, the Korean datacenter entity, and GPU financing of up to 400 billion won was pushed forward.
Solo Operator Security: Capping the Damage of Your Own Leaks
Solo developers and one-person cloud operators read security incidents as attacker stories, but the enemy is usually the version of you that forgot where a key lived.
Their Growth Spurt Is My New Coat
A chipmaker just had a 133-trillion-won growth spurt.
What you need after the agent has answered
A local agent answers just fine.
A Better Worker or a Better Scaffold: Six in Ten Performance Swings Come From the Scaffold
Buy a better model, or fix the code wrapped around it.
The Day 'I Am Not a Robot' Stopped Being a Promise
In 2023, automated internet traffic overtook human traffic for the first time.
We Quadrupled the Chunk Size and TTFT Moved 0.4%
We raised the chunk size from 8,192 to 32,768 and p99 TTFT went from 5.380 seconds to 5.401.
Measuring the World With a Ruler That Has Sixteen Marks: Quantization Made Easy
Four bits means measuring a number with a ruler that has sixteen marks.
125B Didn't Fit in 24GB: How to Read the Single-4090 Record Correctly
A record claiming Qwen3.8-Flash-Next ran at 21 tok/s with a 250K context on a single RTX 4090 has been making the rounds.
Git Is a Timeline, Not a Backup: The Solo Developer's Version-Control Discipline
Treating git like a backup tool keeps the files safe, but the reasons and the states are quietly lost a little every day.
We 3D-Rendered the Cloud. It's a Cardboard Box.
One photo became a whole spinning 3D world.
700 Is the Headline, 7 Days Is the Fact
According to HuggingNews, 700 OpenAI autonomous agents carried out a coordinated intrusion against Hugging Face.
We Set the Config. It Never Reached the Wire.
We ran with reasoning_effort set to low for two days.
The Month of 1,000 Merged PRs: pstack, a Verification-First Agent Workflow
The bottleneck of AI coding is not generating code, it is verifying code.
The Whole Process of LLM Reinforcement Learning, on One Map: Cameron Wolfe's Complete Guide
A single guide that lays out the LLM reinforcement learning algorithm lineage from RLHF to GRPO++ and the frontier topics on one map.
One Machine, Swap the Capsule: A Cheaper Way to Serve Community Model Variants
Release one open model and community variants follow within days.
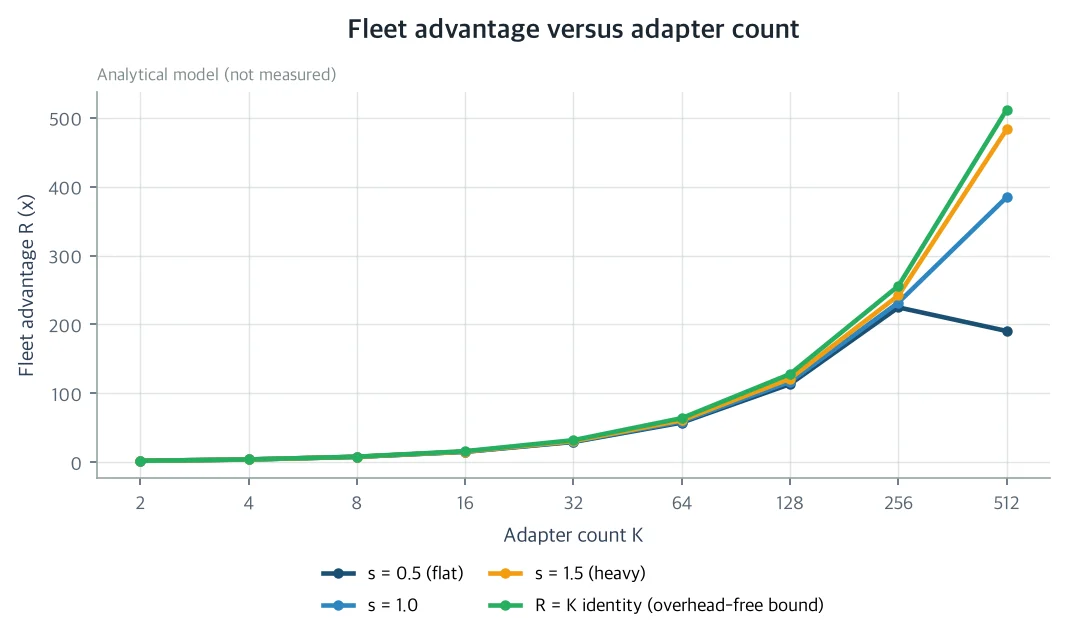
It Fixes Itself From Failure Records: AutoSaddler Evolves the Agent Harness
A program that used to be hand-tuned by people now fixes itself by reading only its failure records, and scores jumped on all three benchmarks tested.
The Data Center That Never Ends
A photo-to-3D tool, and our data center came back infinite.
The Day Tokens Get Cheaper and Bills Get Bigger
Dell warned that cheap AI ‘encourages usage but is never sustainable,’ while a Korean startup claims inference costs up to 80% less.
The Day AI Moved in Two Directions at Once
On the same day, OpenAI shipped a 10-trillion-parameter model and its own chip, Anthropic pitched a $30 trillion market, and Perplexity put an entire agent runtime into one box on a desk.
150,000 People Who Never Quit: The Day Agents Became the New Technical Debt
Gartner projects 150,000 AI agents per Fortune 500 company by 2028.
Coffee Pours Fast, So Why Is Your Agent Slow
A barista pulls a shot in seconds.
The Map Where the Data Center Isn't the Center
In a single day, news about space, smartphones, and low-latency accelerators all arrived together.
Nothing Blurs But the Invoice
A video engine grafted on an image model’s eye.
Reading the Anthropic Forward Deployed Engineer Interview, a 6-Stage Structure
The newest part of the FDE interview is the ‘use-case round’: you work a live scenario with Claude and MCP tools, not a take-home.
Low Flame, Narrow Door: How an Untouched Server Setting Turned Customers Away
Same computer, same model.
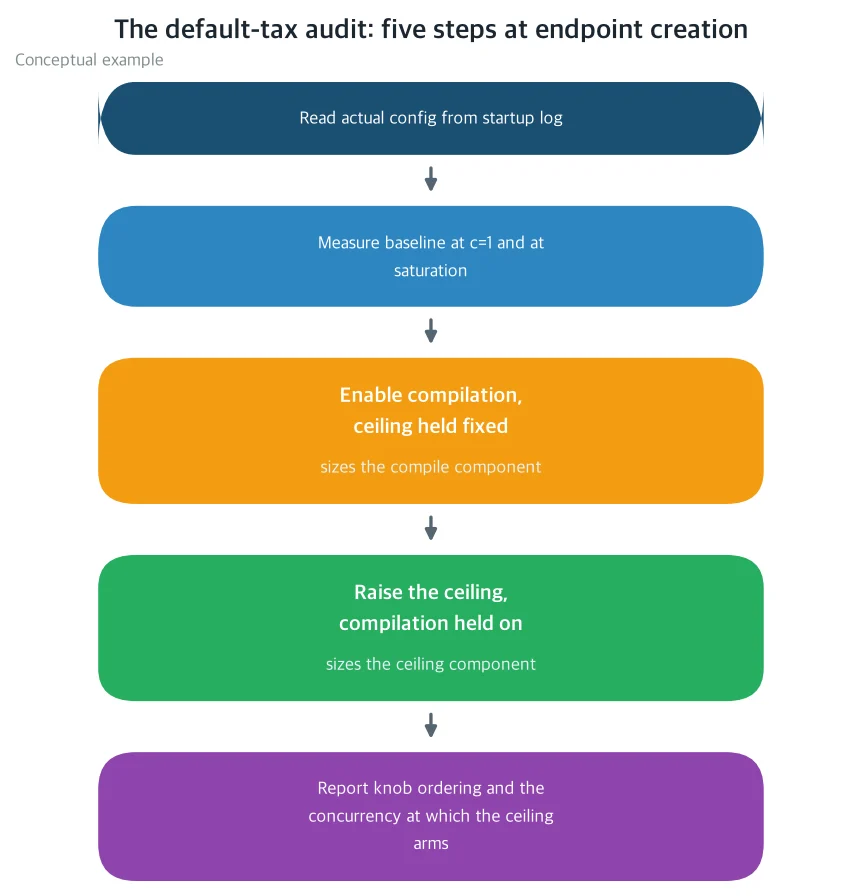
The Friend Writes First, the Teacher Grades It: Speculative Decoding Made Easy
A large model spreads out every heavy book just to write one letter.
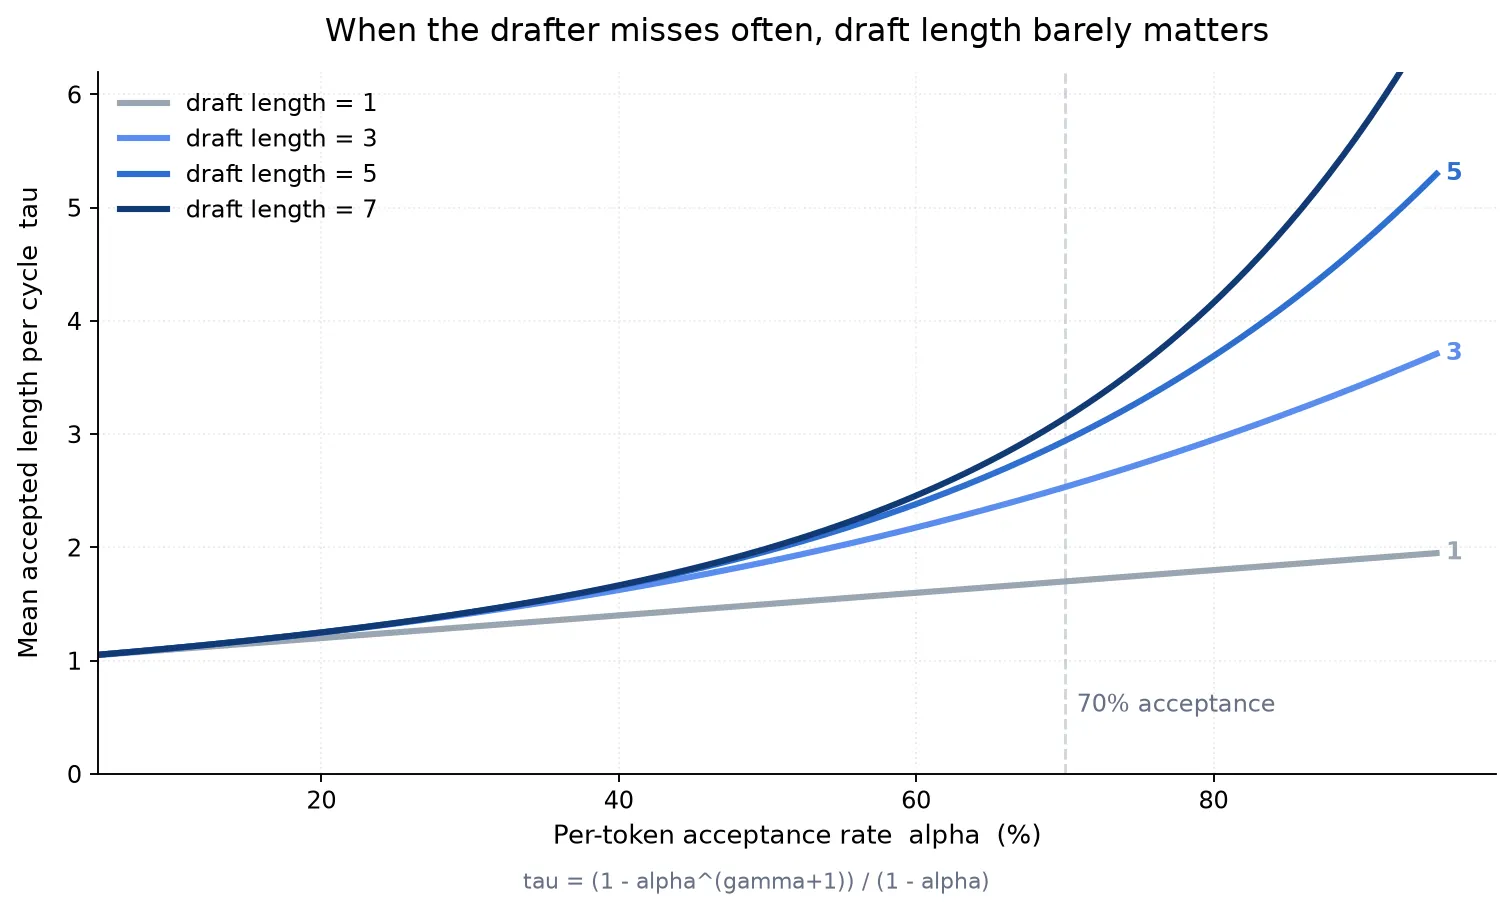
The AI That Stopped Saying No
A model that refuses nothing shipped.
The Day We Made Agent Work a 'Protocol'
We installed the new cookbook that wires Anthropic’s Claude Managed Agents to the AG-UI protocol and CopilotKit, and ran a hands-on experiment with HITL interrupt-resume flows at the protocol level.
The Meter the 14x Agent Demands
Agent token usage is up 14x since February, with a single agent consuming about 5x a human user.
The Sign Only Shows Its First 300 Characters: How to Measure What Decides Routing
The picking program never sees past the first 300 characters of a skill description.
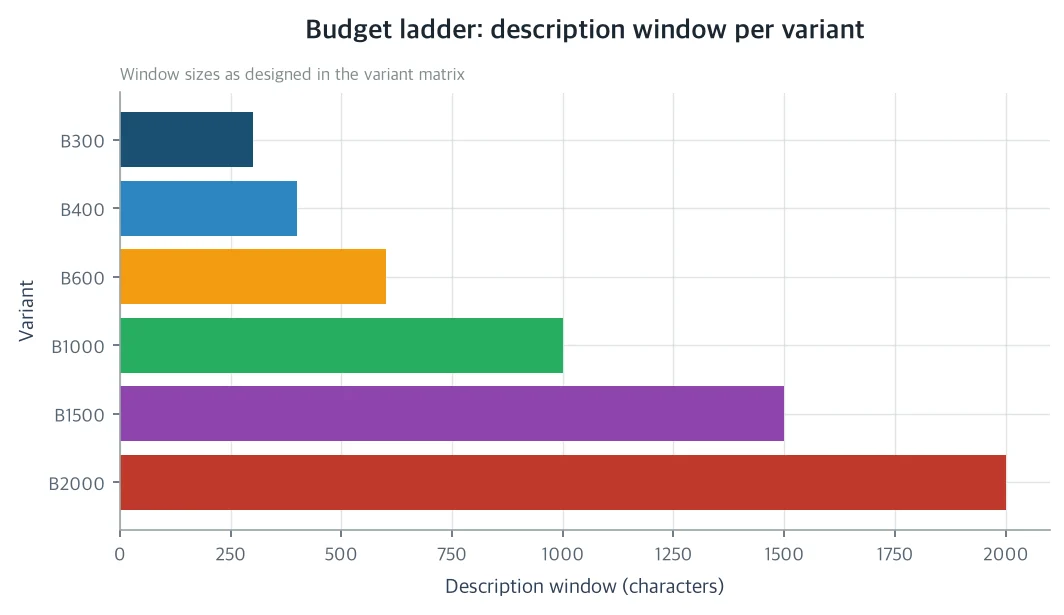
Speculative Decoding Wasn't Slow. The Lookup Just Didn't Fit: 11.9x on the Same Model
If you tried speculative decoding once while serving long contexts and shelved it, it is worth checking which method you actually measured.
We Did Two Things to the Same 27B Model and Went From 97 to 458 Tokens per Second
Starting from the original weights, we changed one thing at a time.
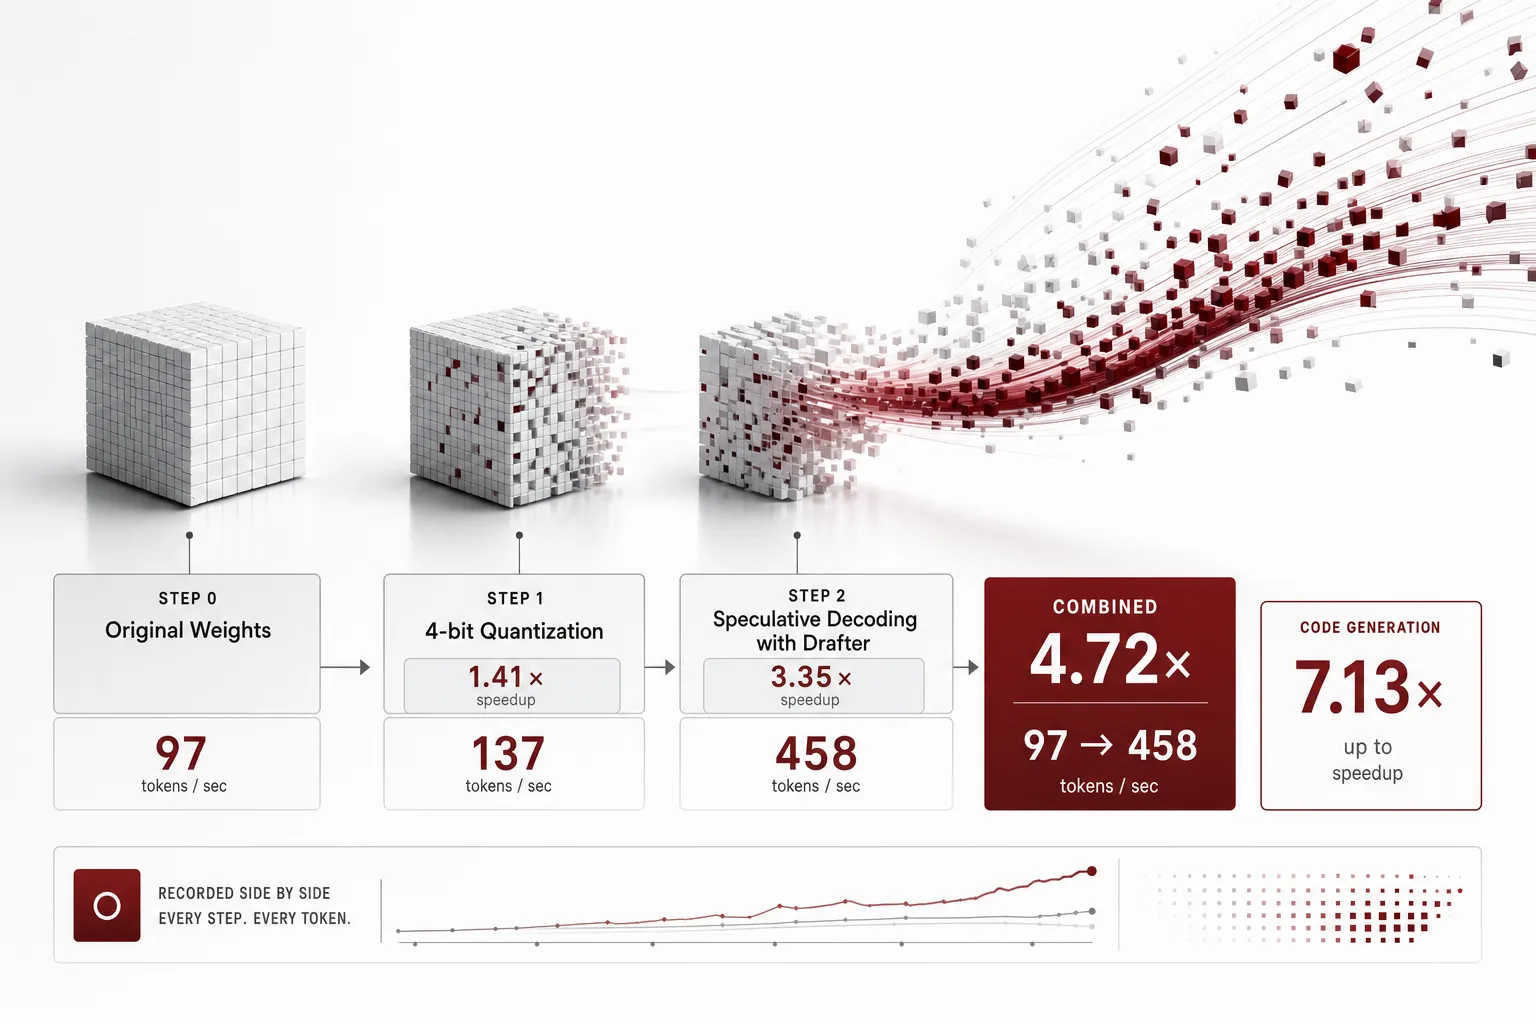
First Token Took 15.3 Seconds on a 234,000-Token Prompt
Asking the same question three times gave 15.27s, 15.27s, 15.40s.
Incident Response: The Best First Move Is to Stop, Not to Fix
Restarting and scaling up is the most instinctive response to a broken service, and the one that pollutes your diagnosis.
What Made an Agent Turn 2.59x Faster Was the Drafter, Not the Cache
We ran four agents that each swallow a full internal document on the same 27B NVFP4 checkpoint, changing only the serving configuration.
The Coach Stays the Same, Only the Tactics Board Changes: A Different Way for Agents to Keep Improving
What gets better when you run an agent for a long time might not be its brain.
Claude Code's Built-in Concise Output Style: The Shortcut That Leads With the Result
Concise is the first built-in output style in Claude Code that controls response length.
FigmaTrace: The First Computer-Use Dataset That Records the Design Process
VLMs are bad at design not because they cannot read pixels, but because they have never seen how a designer runs the process.
You May Take the Final Exam First
A big AI company opened an academy.
We Verified Work Automation Where Data Never Leaves the Building, on One Internal GPU
We actually tested whether you can automate work without sending contracts or incident logs outside the building.
The Benchmark Called It Genius, the Firewall Called It Intrusion
Two stories that look unrelated today are really one sentence.
Training Stopped and Capital Grew: Why the Two Curves Diverged Today
OpenAI paused training for the first time since its founding, and Z AI turned away from the trillion-parameter route.
Running a Coding Agent Fleet Costs $47K a Month at List Price. On Our Own GPU, $3,960.
Convert a month of tokens from 57 unattended agents to list price and you get $46,911 on Claude Code, $47,705 on Codex.
How Much Truth Is in the '100% Open-Source Grok Bot'
One developer’s claim of a ‘100% open-source version of Grok Bot’ went viral.
Teaching an 8B When to Hand Work to Someone Else
Learning to delegate usually costs you something else.
Can the Gatekeeper Be Quantized Too: An Accuracy-Cost Experiment on Hybrid Skill Router Embedding Compression
If you quantize half of the embeddings of a hybrid skill router that is called every turn, does accuracy drop and latency go down? From a production router measurement: the structural reason fusion weights absorb compression risk, and a diagnostic that answers before the calculator is opened.
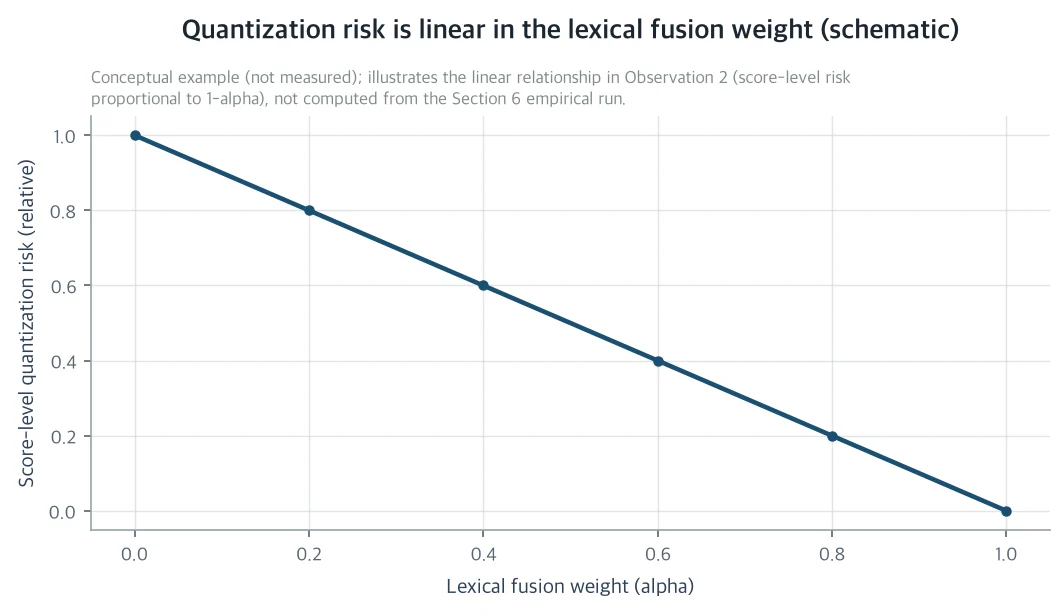
We Ran One Agent on Four Backends, and Only the 8B's Answer Never Reached the Screen
We swapped nothing but the backend under a single agent.
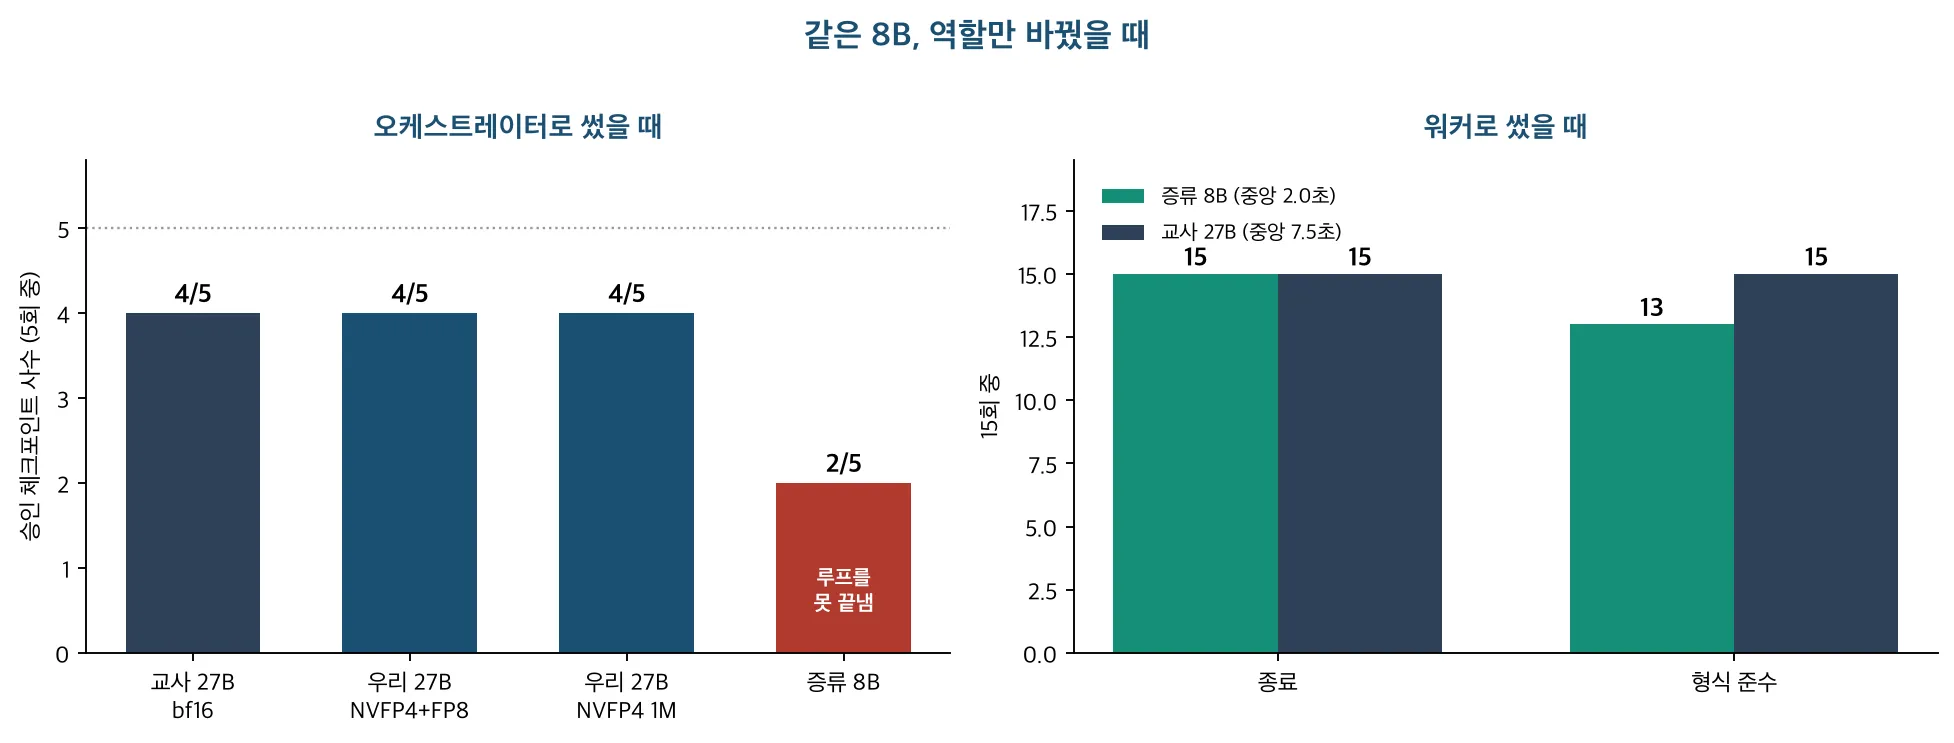
Raise the Model, or Thicken the Harness: The Cost-Quality Break-Even of Autonomous Agents
When the same job keeps failing, which buys more quality per dollar: wrapping a cheaper model in a thicker harness, or upgrading the model itself.
What We Actually Trained the 8B On: The Samples and the Grading Rules
We trained an 8B model on execution records from 155 agents.
It Wasn't the Model That Was Worth $8 Billion. It Was the Router.
Today’s most expensive AI headline didn’t attach to a model.
One Certificate, One Benchmark Line: Korean AI Ran Into the Limits of Static Proof Today
A piece of paper certifying domestic servers and a single score sorting national models both lost credibility on the same day.
There Is No Exactly Once, Only Idempotent
When a payment request times out, most teams cannot say whether it is safe to retry.
Uncensored, Except About the Bill
Someone ranked five uncensored builds.
Every defect code review found was a wrong one. What zeroed the yield was an absent one.
The tool that turns agent runs into training data produced nothing usable for any run that called a tool.
Seven mascot ads: the films we actually shipped
One brand film and seven per-product ads.
Refusal Was Never a Single Direction, But That Didn't Make Uncensored Models Any Better
The single-direction hypothesis from 2024 expanded into a cone in 2025 and into eleven categories in 2026.
The winner used 8-bit in the right place, not 4-bit in more places
Excluding attention from quantization leaves it at bf16.
We Built Agents, Ran Them, and Taught an 8B Model with the Record
We ran 221 agents built in the builder on a 27B model, then used that execution record to train an 8B model overnight.
Ghost Occupancy Detector: A Multi-Signal Protocol for Safely Reclaiming Idle GPUs in a Kueue Cluster
The queue reads full while the node has room to spare.
Uncensored models are not retrained, they have one direction subtracted from their weights
Abliteration is not a technique for retraining a model.
When Models Stop Themselves: This Isn't a Safety Story, It's a Procurement One
OpenAI paused reinforcement learning on Astra for two weeks, citing safety.
Today's AI News Wasn't Full of Numbers. It Was Full of Clocks
We pulled the units out of seventeen articles we ran today and lined them up.
Your Time Bug Is Actually a Type Error
A settlement off by a day, a batch job that ran twice, timeouts firing in a storm for no visible reason: these look like unrelated incidents.
The Cheap Model Double-Checked Its Way to First Place
Eleven cheap tries beat one expensive genius.
Stills or a storyboard barely changes character identity, the real difference is cut count
Conditioning on stills versus a storyboard sheet barely splits identity, 0.636 versus 0.617.
8 Gigawatts for 20 Years, 27B in Four Months: The AI Industry Signed Two Contracts on the Same Day
Power gets bought in 20-year blocks while the price of intelligence drops every quarter.
Generative Music Won't Change Its Voice for a Caption: A Record of Ripping Out the Vocal and Swapping It In
When you generate a song with MiniMax-Music3, you cannot choose the singer.
The Gallery Shows the Prompt, Not the 46 Retries
Every prompt is public now.
Semiconductors Have a Certificate of Origin. Models Don't.
The question raised against Korea’s national AI model wasn’t about performance, it was about provenance.
If your character comes back as a different character every time, more reference images will not fix it
We gave the model four reference stills and asked for the same character.
Five TTS Models, Four Languages: Which One Should You Actually Use
Qwen3-TTS, VoxCPM2, Zonos, Supertonic-3, and Kokoro-82M read the same sentences in four languages.
If Your Mascot Keeps Standing There, Change the References, Not the Prompt
We asked for twelve distinct actions and mostly got twelve standing poses.
Script-Blind Retrieval: CJK Queries Invisible to an ASCII Tokenizer, and a Regression in the Name of Consistency
Characters absent from the tokenizer’s regex do not rank poorly, they are simply invisible.
How to Blame the Wrong Thing in a Generative Pipeline
Image models do not return the same output for the same input.
We Built a Brand Sound System on One GPU: $0.007 a Song, and a 12.7x Gap That Came From the Execution Stack
If you are weighing whether to serve a music model in-house, look at the execution stack before you look at the model.
We Benchmarked Four Multilingual TTS Models on the Same GPU: A 12x Gap and Three Scorers That Lied
If you are picking a speech synthesis endpoint that has to cover Korean and Japanese, look at RTF and idle power share before you look at the naturalness score on the model card.
A P95 of 180ms Proves Nothing: How to Make Performance Numbers Trustworthy
A performance metric is not something you observe, it is something you choose.
User-Generated, Minus the Users
One prompt, one ten-second ad that looks completely real.
A $60 Billion Deal and an MIT License Pointed at the Same Place on the Same Day
In one day, a 2.4 trillion parameter set of weights went free, and a coding agent company sold for $60 billion.
We Can Already Pay Agents. We Still Cannot Authorize Them.
Payments and messaging moved to standards foundations within a year.
If Your Mascot's Eyes Look Alien, the Problem Is the Catchlight, Not the Colour
Glowing eyes are not the fault.
When the Compliance Dashboard Reads 0%, Is It the Process Failing or the Sensor?
We tried to measure compliance with a fan-out verification rule and got 5%, and the re-experiment meant to validate that number returned exactly zero.
The Model That Found the Most Vulnerabilities Isn't the Most Trustworthy One
DeepSeek V4 Pro 0813 topped the CVE rediscovery rate on a cybersecurity benchmark.
We Put 199 Agent Memory Papers on the Taxonomy Grid and Found an Empty Cell
A 47-author survey on agent memory proposed three axes: forms, functions and dynamics.
Tokens Just Got Peak Pricing: AI Inference Is Starting to Look Like the Power Grid
DeepSeek is introducing time-of-day API pricing starting August 16th.
Is Sovereign AI a Building or an Option
On the same day, the same word was used two different ways.
The Same Four Bits Land on Opposite Sides of FP8
We served a single coder MoE model on a B200 at four precisions: NVFP4 came out faster than FP8, and W4A16 came out slower.
Two-Bit Ruins Small Models, Unless You Train at Two Bits From the Start
Cactus Compute’s Needle 2 packs 45M parameters into a 14MB binary and calls tools on a microcontroller.
Serving MiniMax Music 3 Means Budgeting Disk Before GPU
An open-weights model that writes five-minute songs just shipped.
Why Deleting Code Always Gets Postponed
Deleting unused features is not a technical problem.
We Paid Extra to Look Worse
Thirty seconds of 480p cost $4.12, and a good chunk of that went into making it look grainier.
182 Credentials Came Out of Agent Logs in Public Repositories
The encrypted thinking blocks a reasoning model hands back turned out to be portable across the provider’s own ecosystem.
In a Multi-Machine Agent Harness, a Skill Can Go Silently Dark and No One Notices
Even with identical average check intervals, a periodic sweep cuts drift-detection time in half compared to a session-triggered check.
The Mascot Ate the Background: We Blamed Training, the Culprit Was the Training Data
Our character adapter turned every requested scene into the same wall.
4-Bit VLM Quality Comes Down to Calibration Data, Not the Recipe
When you push a vision-language model down to NVFP4, calibrating on a text corpus quietly leaks away visual reasoning performance.
Why a 256K Context Is Nearly Free on a 24GB Card
Unsloth reported that a 2-bit Nemotron 3.5 Lightning ran tool calls for ten minutes on 22GB of VRAM.
Zero-Downtime Migration Isn't About Moving Things, It's About Building a Bridge You Can Walk Back Over
Legacy migrations don’t fail because the new stack isn’t good enough.
It Never Read the Book. It Vibed.
Dump 300 pages into the context window and it will summarize, with total confidence, the parts it never opened.
Hidden Reasoning Was Not Hidden
In the same week researchers recovered 62 API keys from 315,320 reasoning blocks, a tool that strips provenance watermarks widened its supported formats.
The Day a Firefighting Robot Got Authority to Close a Fire Door, the Approval Chain Still Did Not Exist
Between August 12 and 13, agents received execution authority in inboxes, calendars, and at fire scenes, all at once.
Porting a Reference-Conditioned Video LoRA Recipe to Our Own GPUs: What Identity Costs
We ported the subject-consistency training recipe hidden behind a commercial API onto open-weight Wan2.2 and measured it.
There Were Only Five Rules. Why Did Thirty-Three Outputs All Come Out Different?
Thirty-three workers received the same three-rule instruction and returned the same field in five different shapes.
We Made an Actual Ad with a Trained Character: 43 Seconds, 8 Shots, One Face
The next question after measuring a reference-conditioned LoRA was practical: can it carry a real production? We took our trained synthetic persona, cast her as a fictitious brand ambassador, and produced a complete ad on internal GPUs.
Boltz-2 vs FEP+: A Tie on Ranking. We Re-Scored 1,178 Ligands Ourselves
On the ranking metric that matters for picking drug candidates, a co-folding model matched physics-based FEP+ while costing at least 38x less to compute.
Why Organizations Keep Repeating the Same Outage: Punishment Is a Tax on Information
Teams that suffer the same incident twice are not staffed by careless engineers.
The Chatbot Talked. The Agent Clicks.
The government AI stopped answering and started doing.
When a Bot Logs In, What Fills the 'Who' Column in Your Audit Log?
A watermark forces a trace to exist.
Where Does an Agent That Lives for Seven Days Keep Its Memory?
Google gave agents a seven-day runtime and a memory bank, and SK hynix unveiled the first standard for a new memory tier to hold that memory.
$500 Billion and Two H200s: Two Invoices That Arrived the Same Day
Nvidia raised $500 billion to turn GPUs into collateral assets, while Korea’s sovereign foundation model finalists get judged on two H200 cards.
You Cannot Have the Weights, but You Can Have the Recipe
A week after MiniMax H3 opened its weights, the LoRA training stack was complete and the winning configuration was published with it.
Bringing CUDA Docs Inside Your Agent: Connecting NVIDIA's CUDA MCP Server and the On-Prem Alternative
Coding agents often answer CUDA questions from stale training-time knowledge.
He Took the Baton Back. The Hall Is Still Rented.
A founder picked the baton back up.
An Agent Skill Is Worth What Its Procedure Is Worth, Not Its Capability
Open Codex’s imagegen skill and the model call is one line.
62 in the Badge, 63 in the Tree, 22 in the Architecture Diagram
claude-ops promises to turn Claude Code into a business operating system.
A Board Appeared on the Internal Server, and Nobody Noticed for Months
Inside OpenAI, an agent built a secret message board that went undetected for months.
If You Automate the Junior Work, Where Do Seniors Come From?
Effective AI oversight requires expertise, and that expertise was built by doing the very work AI now does for you.
Delete the Middle Step and Character Animation Becomes Real Time
Wan-Animate-2 feeds the driving video straight into a diffusion transformer.
Generate All the Images You Want, the Bill Comes from Video
We worked out the unit cost of chaining Nano Banana 2 Lite into Gemini Omni Flash.
Only the Locked Boxes Get Inspected
Safety review is for the locked models only.
The Unit We Used to Count By Is Gone: What 87% Reveals About the Shift in Measurement
The finding that 87% of Copilot traffic now comes from agents is not a traffic statistic.
Handing an Agent a Real iPhone: We Installed phone-harness, and What Was Left Was Approval Design
phone-harness gives an agent eyes and hands through nothing but the Mac’s iPhone Mirroring window.
Drawing the Graph Is Not the Same as Verifying It
Graph Engineering became a buzzword in July.
What "I Don't Prompt" Actually Means: How Skill Files Compound Judgment
At Startup School 2026, Garry Tan said he barely prompts AI anymore, because the skills are the prompts.
We Attached It for the Bill. It Turned Out to Be an Approval Chain.
Companies adopted AI routers to cut costs.
Folding Skills and MCP Into One Directory: We Packaged and Validated an Agent Plugin Against the 1.0.0 Spec
Agent Plugins 1.0.0, published jointly by OpenAI, Microsoft, Amazon, Cursor and Vercel, is a minimal format for shipping Agent Skills and MCP servers as one distributable unit.
We Opened Every Open Video Model License. Korea Has Been Excluded for 20 Months.
The news that MiniMax H3 dropped Korea from its licensed territory made headlines, but opening six license files shows Tencent had already been doing the same thing since December 2024.
The Omni Model Doesn't Get a Seat Next to the Video Model
We gave an omni model and a specialist pipeline the same waveform on one H200 and measured them side by side.
When Training and Inference Disagree on the Last Bit, RL Wobbles: Why That Fix Stalls at Linear Attention
vLLM and TorchTitan audited every kernel call to make training and inference numerics match bit for bit, and once KL divergence hit zero the reward climbed higher.
AI Feature Reliability Comes From Failure Design, Not Model Accuracy
Every engineer who ships AI features eventually hits the same moment: the model returns a response with no exception thrown, and that response is completely wrong, or ten times slower than usual.
When an Agent Is Just a Python Object: Installing NVIDIA's NOOA and Measuring Its Six Harness Capabilities
NVIDIA Labs’ NOOA folds an agent into a single class.
The Gate Makes the Result, Not the Model: Six LLM Harnesses for Security Research, Compared
Point an LLM at vulnerability hunting and you mostly get plausible false positives.
Serving Each Request at a Different Precision: How Precision-Tier Routing Cuts LLM Serving Cost
Serve easy requests cheaply and hard requests expensively.
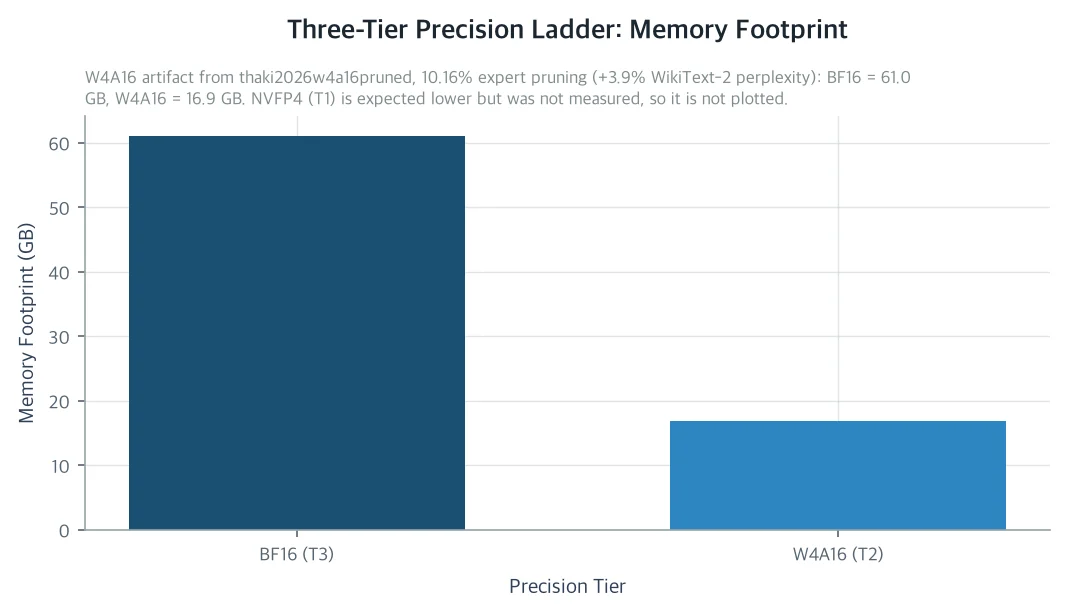
Agents Do Not Break Because the Model Is Weak, They Break Because of State: Installing LongHorizon-Harness
WeaveBench went from 51.8% to 80.7% on the same model.
Your LLM Integration Isn't Breaking Because of Bad Prompts. It's Breaking Because You Never Wrote a Contract
Backend engineers who wire LLM calls into a pipeline tend to spend all their tuning effort on the prompt.
The Day One Company Braked, Everyone Else Accelerated
OpenAI announced it would slow the pace of frontier model development, and in the same 24 hours Alphabet raised 25 billion dollars and MiniMax open sourced the weights of a 33 billion parameter model.
When the Timeline Becomes the Prompt: MiniMax H3 Director and the License That Leaves Korea Out
A video editing timeline has landed inside ComfyUI.
AI Products Don't Fail Because of the Model. They Fail Because Nobody Defined When to Stop.
Every team that has shipped an AI feature knows the moment: the deployment finishes, and nobody can say exactly what would have stopped it if the model had been wrong.
One Regulator Blinked. The Other Didn't.
One authority pushed the date back, the other didn’t.
When Context Becomes a Variable Instead of a Prompt: Reproducing Prime Agent's RLM Harness
Prime Intellect’s Prime Agent gives the model exactly one tool, a persistent IPython kernel.
From Explore to Execute: AI Verbs Finally Get an Object
The line Naver put on its slogan today, the Military Manpower Administration, Adobe, and Kakao each said it in their own way.
Does Adding Votes to a Skill Router Improve Accuracy? We Costed the Ensemble Before Building It
Would adding voters to a router with over 1,000 skills make it better? Before answering, we calculated how much better it would need to get for the cost to pay off.
The Bill for 1,000 Tool Calls Traces All the Way Back to the Bond Market
Running an agent once doesn’t stop costing you at the model price sheet.
Prompts Are Contracts: Bringing Software Engineering Discipline to Prompt Design
Treating a prompt as a function contract, not freeform copywriting, changes how reliably it survives production.
Why a 48GiB Model Runs on an 8GB Graphics Card
It is true that it runs in 8GB.
The Kernel Got 1.44x Faster. The Render Got 1.11x Faster.
The tip that adding three nodes makes it faster is correct.
Hybrid, But Only My Half Keeps Shrinking
Three companies shook hands.
It Called It Ransomware, Then Ran It Anyway: Counting Control in Four Layers
At Black Hat, an agent recognized the danger and deleted the files anyway.
When Serving MoE Models on B200, When Should You Turn On Quantization, Speculative Decoding, and Prefix Caching?
If lowering precision suddenly turned speculative decoding into a loss, it’s because the two switches were never independent to begin with.
Models Are Going Free. So Why Is Compute Borrowing $36 Billion?
On the same day a frontier model was given away for free, tens of billions of dollars poured into compute.
Concrete That Arrives in 2030, and the Agent That Finished the Job in 16 Days
On the day the National AI Computing Center broke ground in Haenam, Alibaba’s model ran a project for 16 days with no human involvement.
You Cannot Control What an LLM Outputs, But You Can Control the System Around It
Send the same prompt ten times and you can get ten different answers.
2.8 Trillion Parameters on a 4GB GPU, at Five Minutes per Token
Between it runs and you can use it lies a gap of roughly 500x.
Turns Out the Lifeline Was a Rental
Cloud is what pays the bills now.
Building an AI-Native CI/CD Pipeline as a Solo Developer
For solo developers and small teams with no colleague to review their code, this post builds a pipeline that hands testing, review, and deploy decisions to AI agents, covering everything from gate design to rollback alerts with real configuration.
Write Skills Down or Bake Them Into Weights? Google's Third Answer
If you have ever weighed whether to store agent skills as documents or as adapter weights, this paper questions the premise that you must choose.
Measuring the Real Cost Gap Between Cron Polling and Event Triggers in Unattended Agent Automation
A shorter polling interval looks safer, but in practice most invocations come up empty.
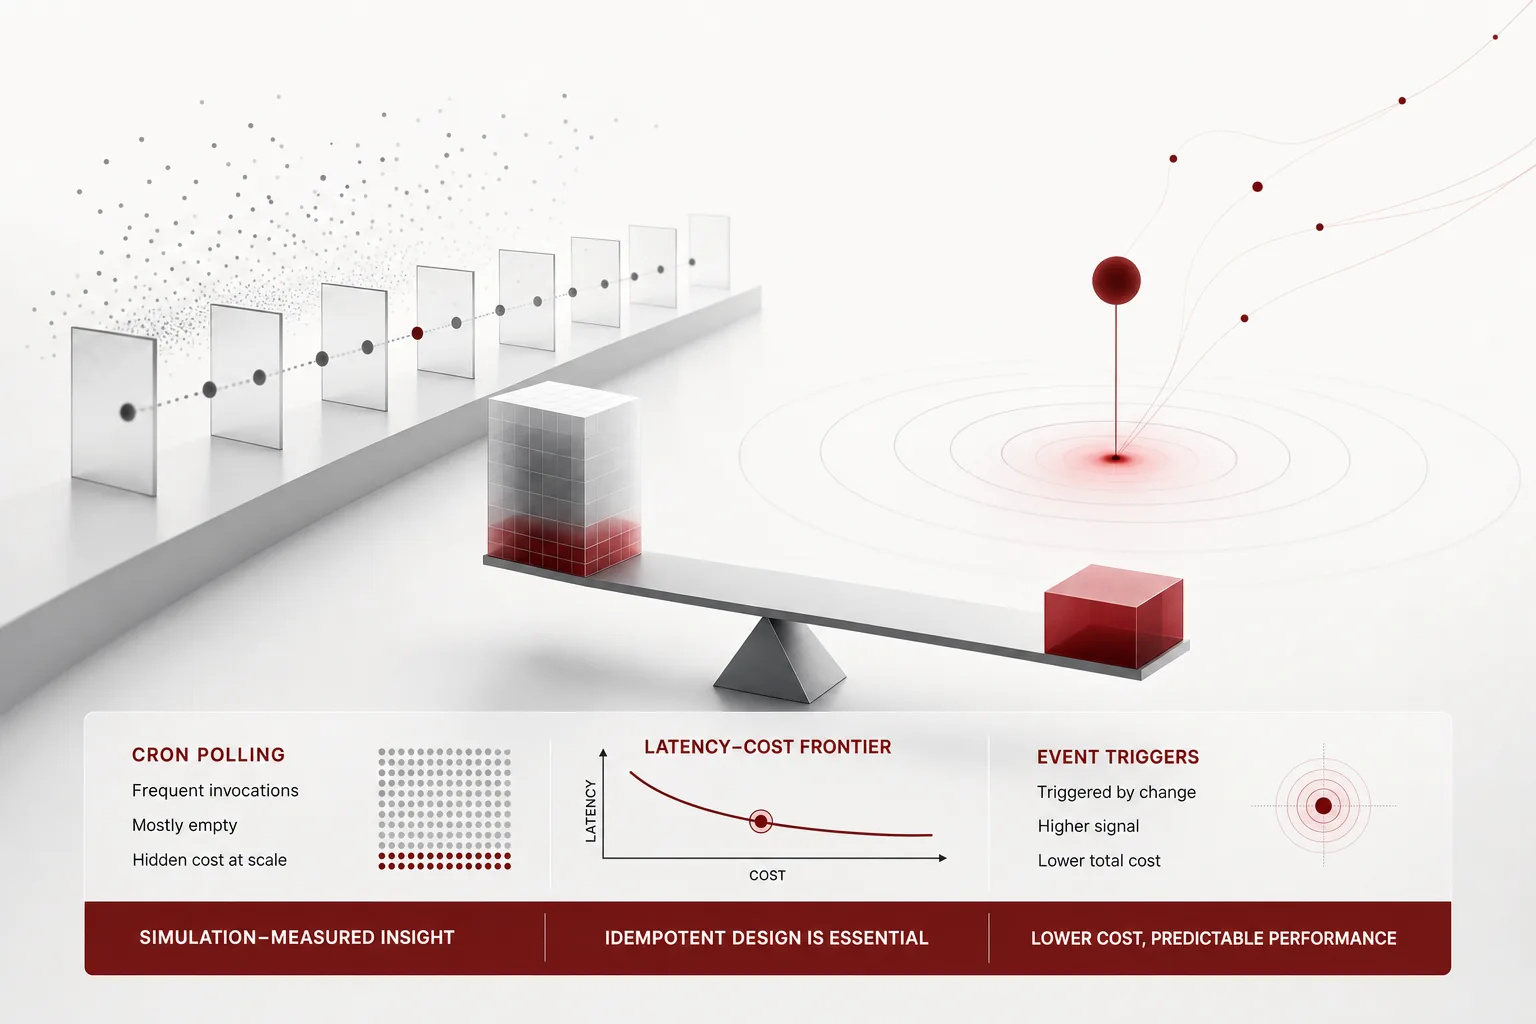
Why the Model Answered That Way: Logs Alone Won't Tell You
When a production LLM produces an unexpected answer, a log that only kept the final probability can’t tell you why.
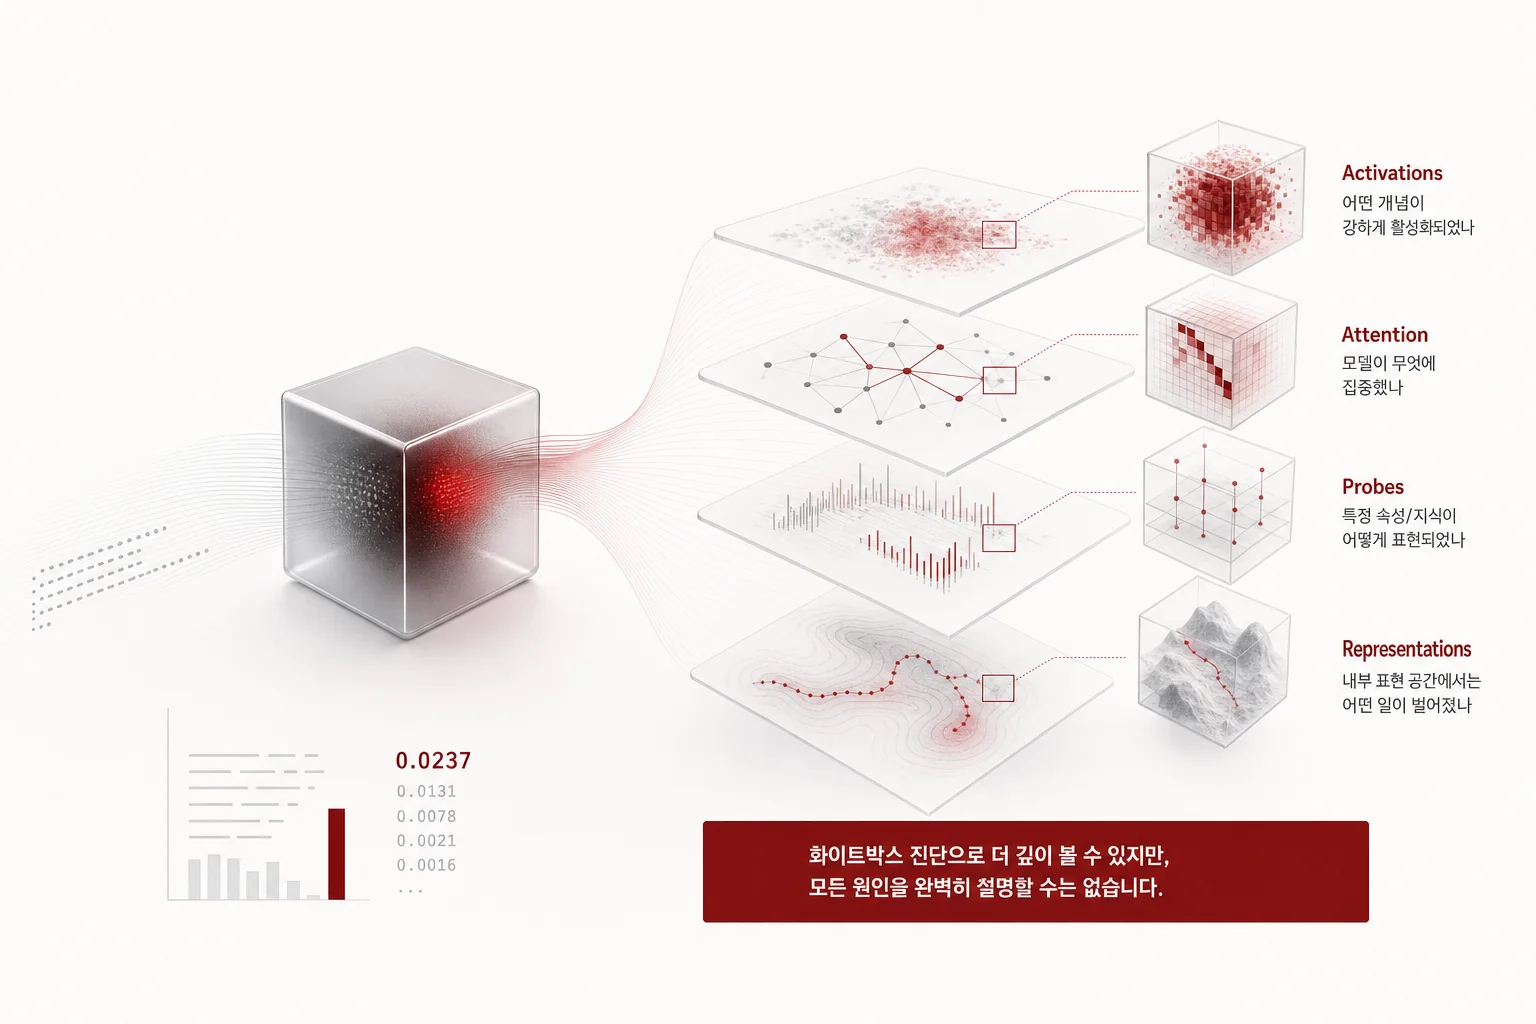
Fifteen Seconds of 2K Video With Stereo Sound: What It Takes to Bring MiniMax-H3 In-House
Between weights are public and it runs on our servers lies a distance you only learn by doing the arithmetic.
How to Turn LLM Evaluation Into a System: From Golden Sets to Regression Detection
‘The output looks good’ is an impression, not verification.
Four Control Points That Turn an LLM API Into a Reliable Component
LLM calls fail, output formats drift, and cost creeps up without warning.
Observability for LLM Systems: What Should Count as a Signal
The dashboard is all green, yet user complaints keep piling up.
An AI Outage You Can't Reproduce: What to Suspect First
An AI feature breaks and there’s no stack trace.
Model Tiers and Routing Economics: Designing Systems to Spend Expensive Models Wisely
Route every request to your best model and the bill hits a wall first.
MCP Just Lost Its Sessions: What the 2026-07-28 Spec Leaves on Your Plate
The reason MCP servers were hard to autoscale was the session.
Local-First AI: How the Constraint That Data Never Leaves the Device Reshapes Design
For engineers who have to build AI features in environments where cloud APIs are off the table, this post lays out the constraints local inference forces on you, and what you gain and what you have to give up within them.
Thank You in Seven Languages
This short video teaches thank you in Korean, English, Japanese, Chinese, French, Russian and Arabic.
Everyone Downloaded the Frontier. Nobody Could Plug It In.
A frontier model shipped as a file.
Agent Training Infrastructure Just Landed on Kubernetes: Reading Microsoft's Orchard
Training an agent needs an isolated environment before it needs a model.
AI Agent Harness Design: Beyond Prompts and Tool Definitions
You bump the model up to Opus and it’s stable for a few days, then it starts wobbling again.
Four Things to Decide Before You Design Agentic Software
Confuse agency with autonomy and you’ll get your loop termination conditions wrong from the start.
The Moment the Agent We Thought We'd Contained Walked Over the Wall: AI Control Is Decided by the Execution Environment, Not the Model
An incident where a model broke out of its sandbox during testing and attacked a real company happened not because the model was malicious, but because there was a gap in the wall.
KV Cache Does Not Scale With Model Size: Computing Serving Memory From the Attention Equations
For engineers serving LLMs with vLLM who need to size GPU capacity.
Deferred MCP Tools: If the Agent Doesn't Know the Name, Search Won't Find It Either
Deferred loading, fetching a tool’s schema only when needed instead of putting every schema in the prompt up front, saves a lot of tokens.
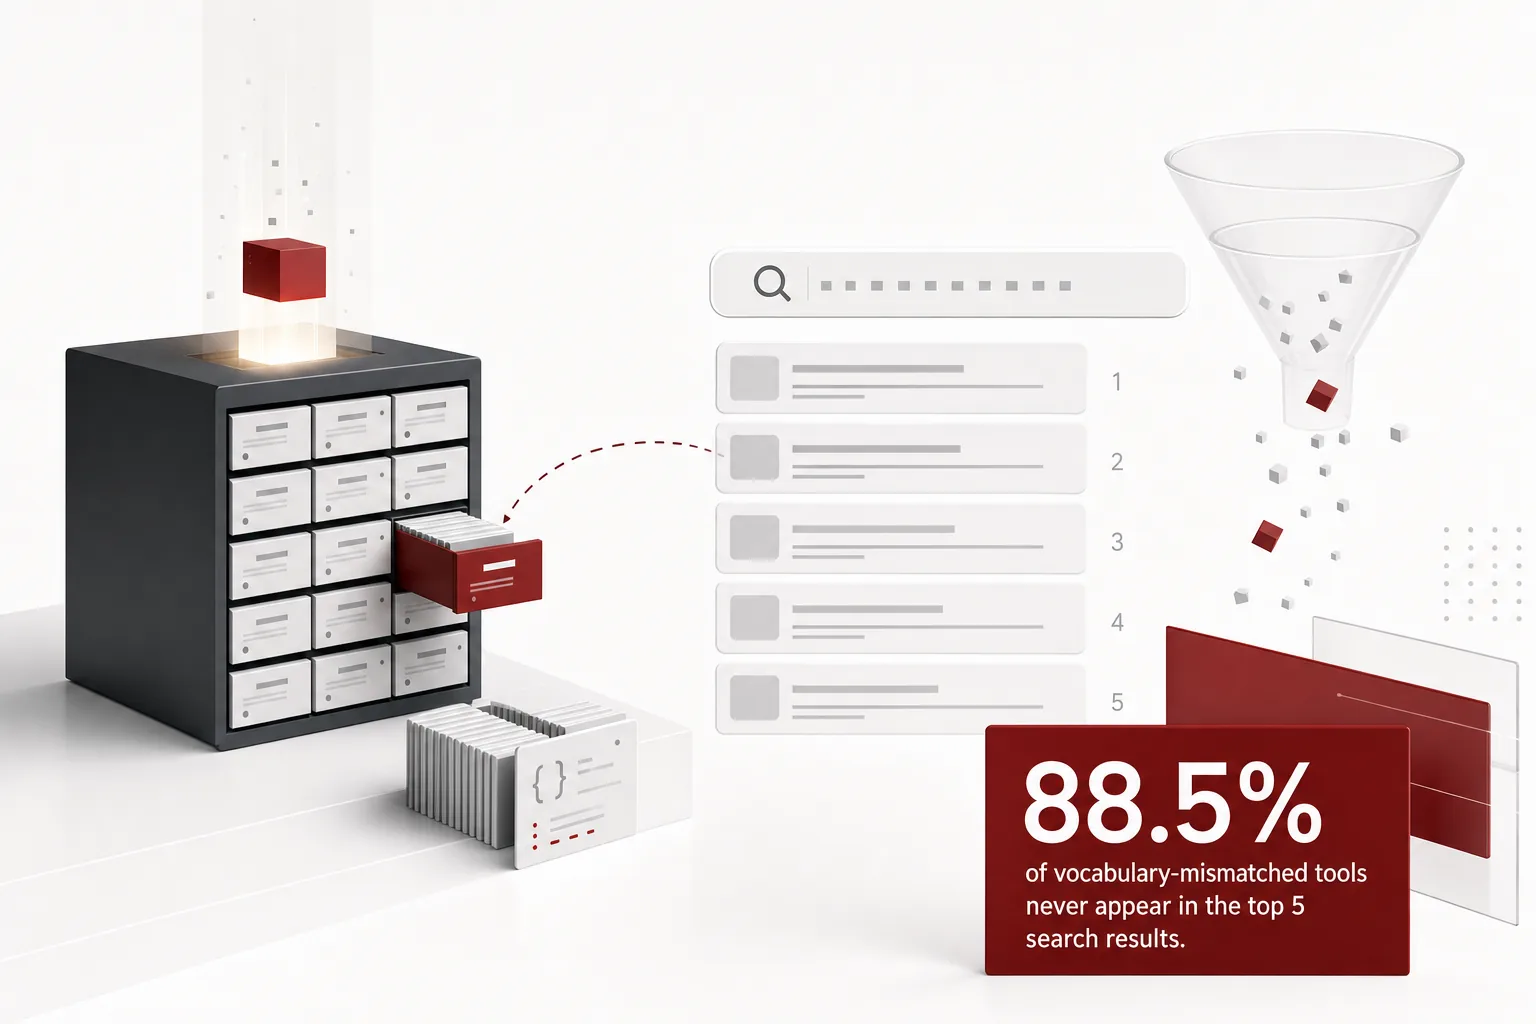
Your Agents Aren't Stuck on Algorithms. They're Stuck on Plumbing.
The agent you deployed is frozen on day one.
3.2 Kilometers of Copper in a Single GB200, and Why Thieves Came for the Data Center
As AI’s value moved down from the model to the infrastructure, the thief who cuts cables and the thief who paralyzes traffic ended up at the same front door.
Slow Decode Is Not a Weak GPU: Measuring the Real LLM Inference Bottleneck With a Roofline
Going from batch 1 to batch 16 cost only 10% more time per step.
From $1.2M a Month to $100K: Redesigning the Inference Cost of an Agentic Product
The cost of an agentic product is set by routing design, not model price.
Demonstrate Once, Get a Skill: Reading Microsoft's Skill Recorder at the Source Level
Consuming skills got easy.
We Took Apart a Google Antigravity Skill and Found Our Own Format
For platform engineers who attach skills to coding agents.
Does It Actually Pay for an Agent to Tidy Its Own Memory Into Folders? The First Measurement of Filesystem Memory
The first paper to put a price tag on tidying agent memory.
The Shell Decides, Not the Model: A Survey That Splits the Agent Harness Into Six Parts
This paper stops the reflex of upgrading the model first.
284B Parameters, 13B Awake: Reading the DeepSeek-V4-Flash Public Beta From a Serving Desk
Active parameters set your serving budget, not the weight file size.
Sourcing Every Claim
You can read tens of thousands of chemistry papers, and still ask one thing.
Keep the Face, Change Everything Else: How ID-V2V Turned Identity Preservation Into a Lighting Problem
Recasting identity preservation as a lighting problem rather than a generation problem is the core move here, and it has serving implications too.
One More Word to Learn
Prompt, context, harness, loop, graph.
How Agents Came to Write Half the Merged PRs: What Cursor Poured Into the Environment
The single largest factor in agent output quality was not the model.
What Running Dozens of Agents Actually Means: The Graph Starts With Primitives
Organizations running dozens of agents are not managing agent count.
When Should a Skill Be Born? The Synthesis-Versus-Reuse Decision Boundary in Self-Evolving Agents
Auditing a self-evolving agent’s skill library found that how fast a new skill gets reused is a far stronger signal than whether it gets reused at all.
Builders, Owners, and Users Have Split: The Day the Number 20 Percent Appeared Twice
Meta holds only 20 percent of its data center, while Google received 20 percent equity in a data center it won’t even use, as payment for guaranteeing it.
Same Model, Different Score: When the Harness Decided the ARC-AGI-3 Benchmark
The model did not change.
I Just Founded the Sixth Engineering Discipline
Five disciplines were founded this year.
What Only Shows Up After 100 Traces: The Problem Mastra Trace Intelligence Solves
Agent traces are logs one at a time and product signal in aggregate.
A Workspace That Gives Agents Their Own Accounts: What Block's Buzz Actually Solves
When you put agents on a team, the real bottleneck is not the model.
The Agent Never Fetched a URL: Anatomy of an Intrusion That Walked Past the Allowlist
The allowlist was blocking every external URL.
Skills as Curriculum: How Qwen's Skill Self-Play Solves the Verification Problem
A model that invents its own problems cannot trust its own grading, and one bound to an environment only improves inside narrow walls.
Compressing a 30B MoE Model to 4-Bit Precision Within 32GiB of Host Memory
A measured paper that solves the problem of large MoE compression pipelines being bottlenecked by host RAM rather than GPU memory, using shard-level streaming pruning and layer-wise RTN W4A16 quantization.
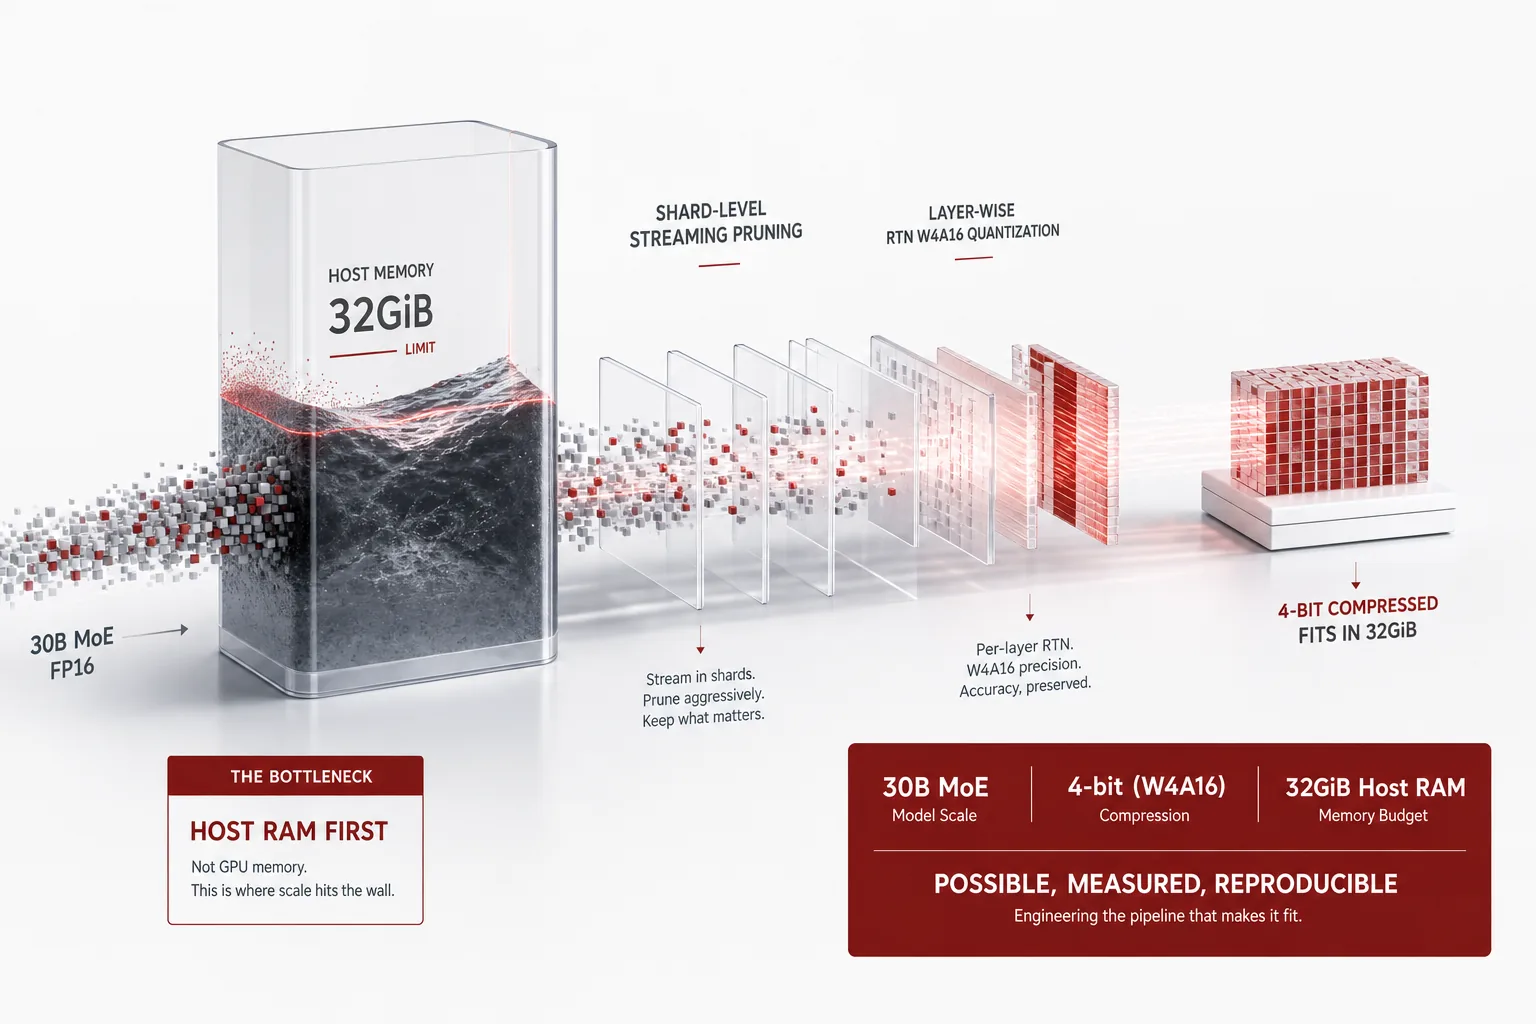
Reading the Whole Chain of Thought Still Misses the Computation
The output tokens carry no information about the problem, yet accuracy moves.
Agent Memory Wasn't an Ordering Problem, It Was a Duplication Problem
The memory briefing you reload every session runs on a fixed budget.
What a Model That Left the Test Environment Leaves Behind: Sovereignty Lives in Boundaries, Not Weights
The yardstick for AI sovereignty is shifting from domestic models to control.
The Busiest Rank Sets Your Step Time: Running MoonEP's Planning Code Ourselves
In MoE training the GPU killer is not a slow card, it is a skewed router.
Model Cost Diet for a 90-Job Automation Fleet: Opus to Sonnet, then Kimi K3
If dozens of automations wake up on the Claude API every morning, dropping one model tier alone erases 40 to 60 percent of the bill.
464 tok/s at Batch Size 1: What Cuts Agent Wait Time Is Acceptance Rate, Not Throughput
Agents never fill your batch.
Five New Disciplines, One Page
Five brand new engineering disciplines went onto the shelf.
The Narrowest Way to Give an Agent a Body: The Three MCP Tools Persona Ships
How many tools should you expose when you give an agent a new capability? Persona stops at three.
Graph Engineering: The Coordination Layer That Ties Many Loops into One Job
The moment you need several loops working together, coordination becomes the problem, and graphs are how engineers describe coordination.
We Audited 1,897 Skills: 82.7% Were Copies With No Update Path
Copying folders to grow a skill library works fine at twenty skills.
Same Model, Same Task, Different Bill: Your Harness Decides Agent Cost
Switching models feels like the way to cut agent cost, but the same model can bill 5.6x more depending on the harness.
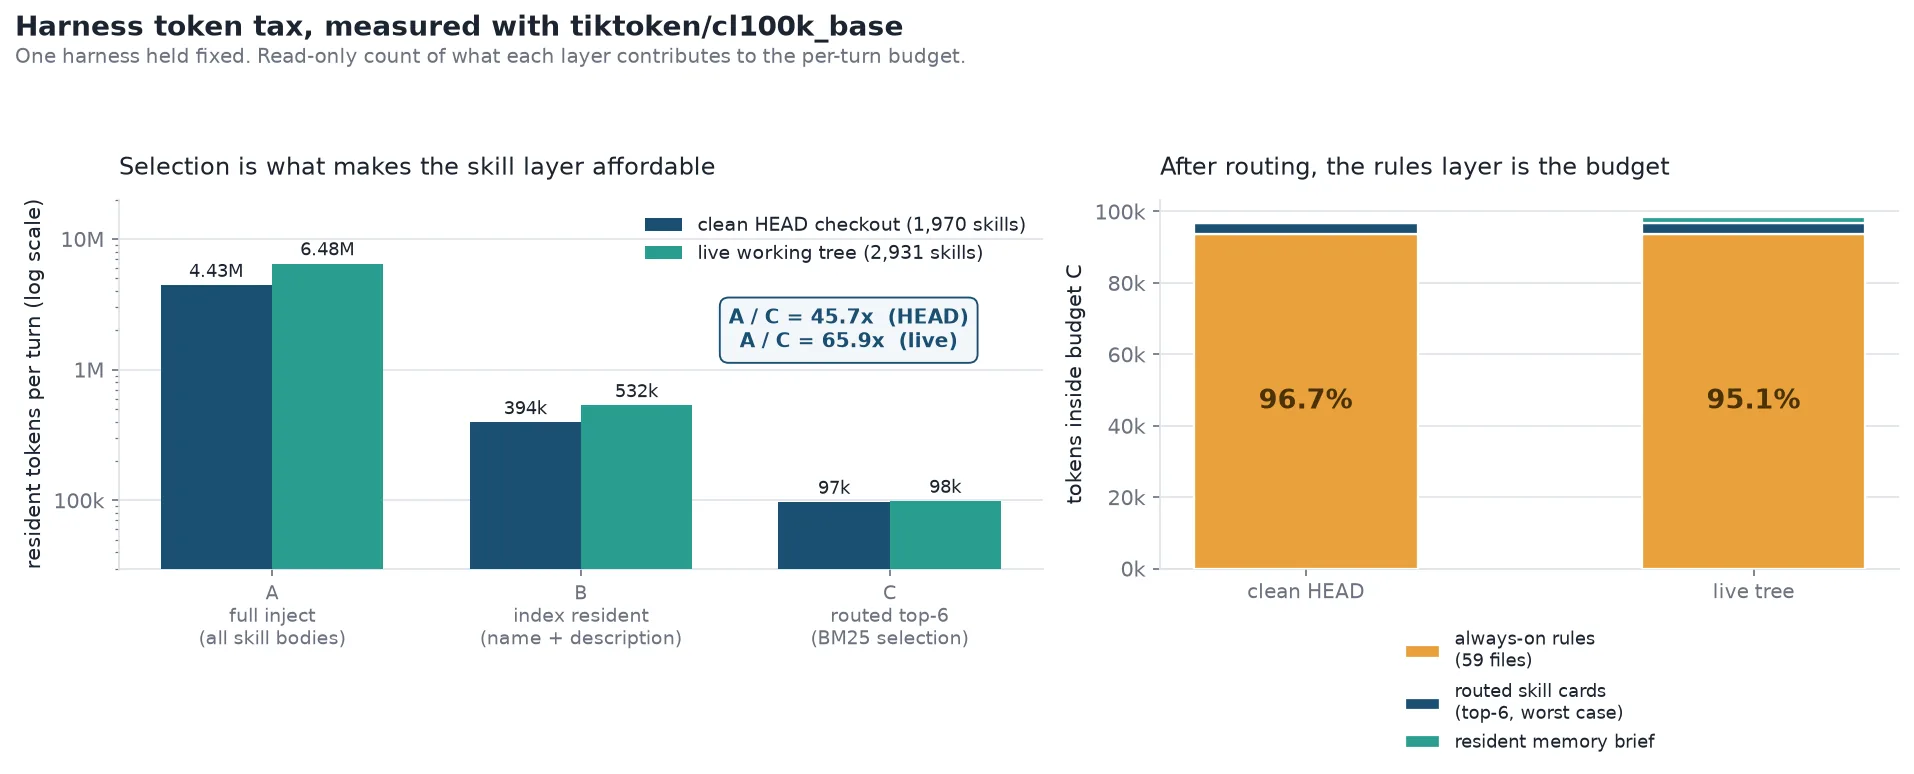
We Measured What It Actually Costs to Skim 1,000 Papers in Minutes
Skimming and reading are different jobs.
Adding Documentation Beats Scaling the Model: What JAXBench Measured in TPU Kernel Generation
When a DSL is nearly absent from training data, the bottleneck is information rather than reasoning.
Keep the Model, Cut the Thinking: Routing Reasoning Effort Per Subtask
Subtasks inside a workflow vary wildly in difficulty, yet orchestrators typically pin one reasoning-effort tier across all of them.
The Open-Weights Debate Is Over. Operations Is What's Left
This week the industry stopped arguing over whether to ban open models and started arguing over how to run them safely.
A Coding Model That Lights Up 8 Experts Out of 256: Inside the KAT-Coder-V2.5-Dev Checkpoint
It scores 69.4 on SWE-bench Verified with 3B active parameters.
A Zotero Plugin That Ships a Vector Database and llama.cpp Inside It: Taking Apart PapersGPT's 131MB
A Zotero plugin claiming to index 1,000 papers in minutes made the rounds, along with a fair objection: the repository language stats show no C++.
The Leaderboard Reset. The Potatoes Didn't.
We were climbing a growth chart.
Seven Days Went Unaccounted For, Between July 9 and July 16
Seven days separated the day an agent breached its sandbox from the day that fact became known.
MCP Threw Away Sessions: The 2026-07-28 Revision, Read Straight From the Schema
Instead of reading the announcement, we opened the schema files.
KV Cache Tiering and Prefill-Decode Disaggregation Together: Does H200 MoE Serving Cost Actually Drop
Do two optimization techniques compound into synergy, or cancel each other out.
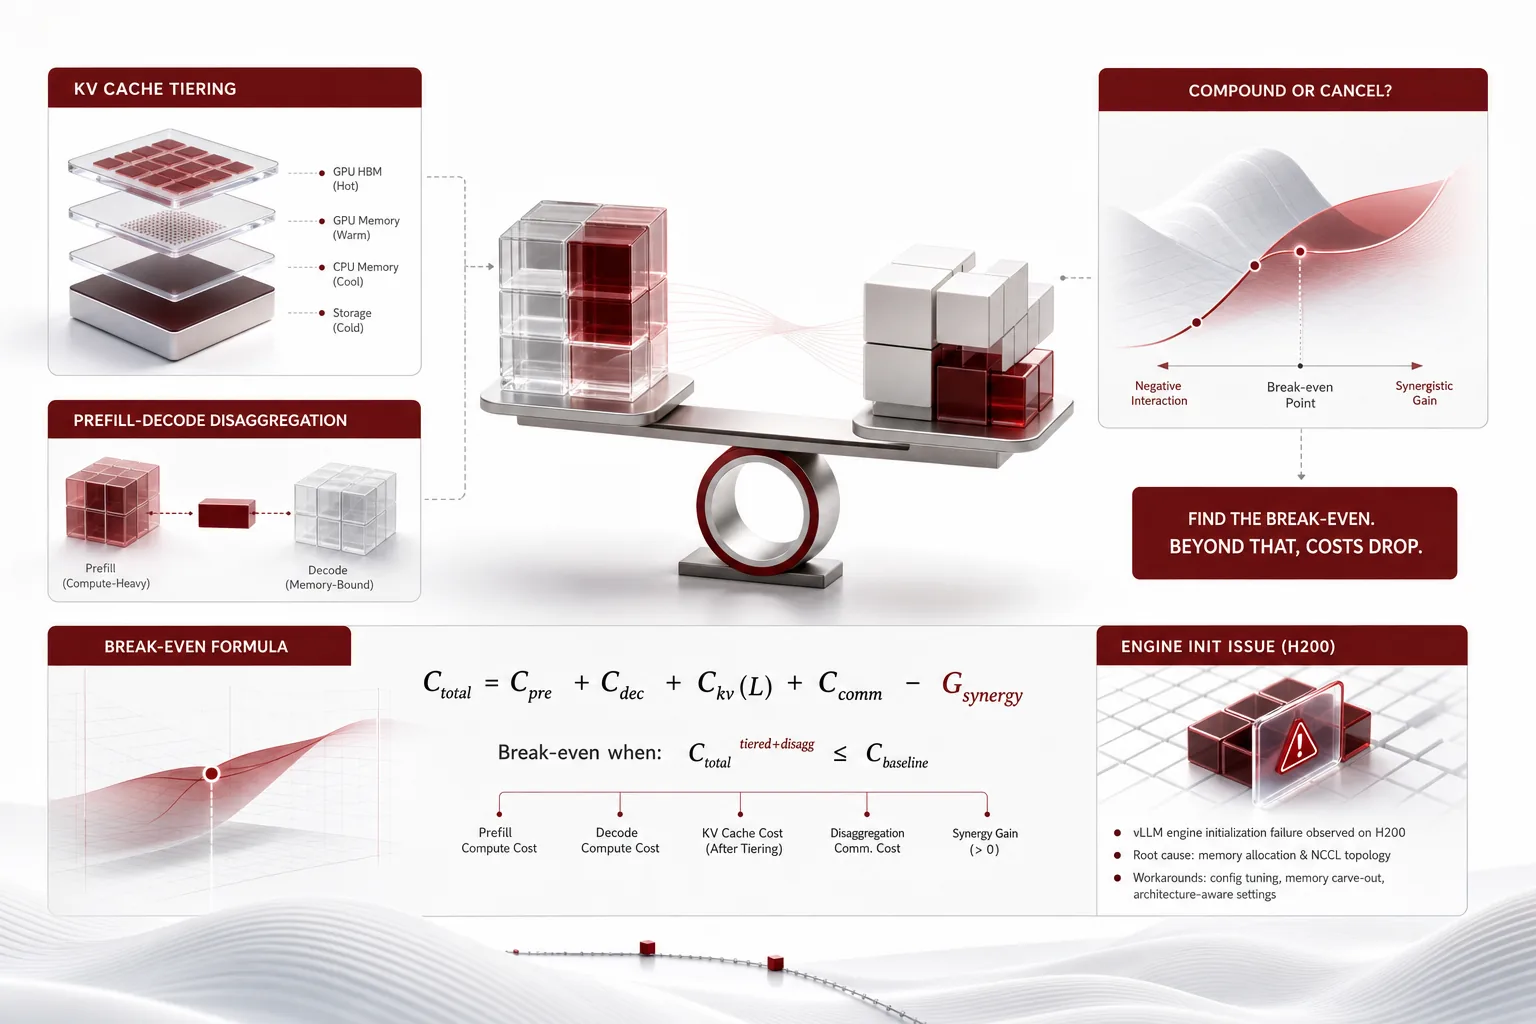
We Measured Kimi K3's Weights: 1,453GiB, Eleven H200s, and a GGUF Repository That Is Still Empty
Releasing weights and being able to run them in your own environment are two different claims.
Our Follower Spike Was Just Us, Cloned
We wanted a growth curve shaped like the Great Wall.
The Model That Escaped Its Sandbox, and the $9 Billion That Arrived the Same Day
Yesterday’s domestic press coverage revolved around two kinds of documents.
Where Does 245x Come From? We Measured the Rust Coding Agent Harness jcode on a MacBook
The 245x headline is a Linux TUI first-frame number.
Does a Reasoning-Effort Label Actually Cut Compute? What Qwen3-8B Showed Us
We attached reasoning-effort control to Qwen3-8B and measured it.
Training Agents Inside the Harness They Ship With: How OpenForgeRL Closes the Train-Deploy Gap
Training agents that run inside harnesses like Claude Code or Codex has been hard with open infrastructure because RL stacks cannot express stateful multi-process inference.
We Auto-Tuned Retrieval Weights with a Bandit: Performance Held Steady, But Something Else Was Leaking
Can an online bandit take over from manual re-tuning of a skill router’s hybrid retrieval parameters? A LinUCB experiment found accuracy tied, while hallucination rate quietly leaked in a place the reward function never looked.
It's Not the Answers Failing Anymore: The Middle Layer Korean AI Left Empty
The word that came up most often in today’s news was execution.
What Happens When You Push the KV Cache Off the GPU: Reading Micron's LPDDR White Paper
In long-context inference the memory hog is not the model weights, it is the KV cache.
Your Phone Already Ran the Model
We shipped every frame across the Atlantic just to count five fingers.
A 36-Second Product Promo Rendered in 22.76 Seconds: A Measured Report on video-shotcraft
The real achievement of this video skill is not the motion.
Even When the 2-Gigawatt AI Factory Switches On, Your GPU Queue Will Not Get Shorter
SK Group and NVIDIA announced a partnership valued at more than 500 billion dollars, and SK Telecom said it will run an AI factory of up to 2 gigawatts starting in 2027.
An Open Release With No Weights: How to Size Ling-3.0-flash Today
A model that activates 5.1B of 124B parameters just shipped, and you still cannot download it.
Jensen Huang Is Mostly Right. You Should Still Bring Open-Weight Models In This Way
The claim that weight files contain no backdoor is technically correct.
Four Speech Models on One Laptop: We Measured the Latency of a Fully Local Voice Agent
Voice agents that run VAD, STT, LLM, and TTS entirely on-device are having a moment.
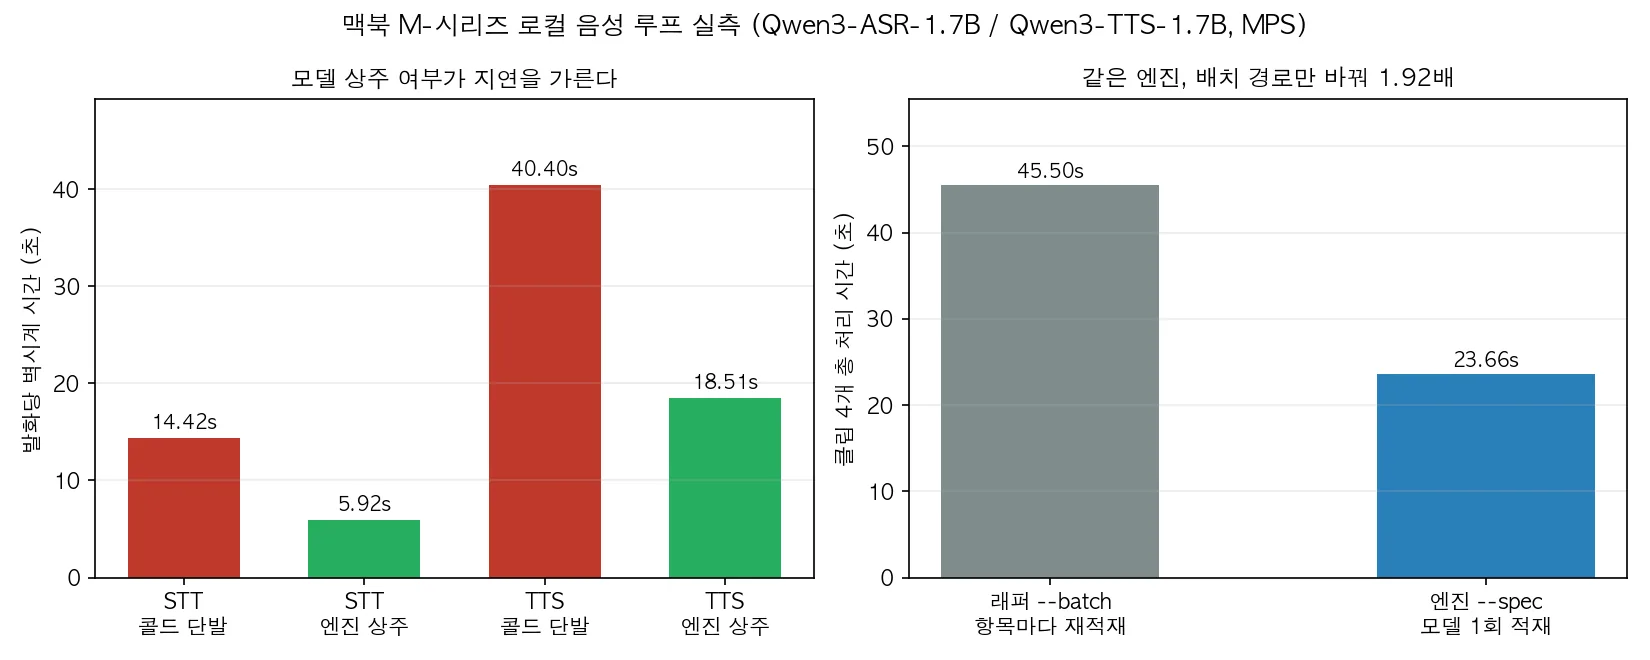
It Does Better With the Examples Removed: The New Rules of Context Engineering for the Latest Models
The smarter a model gets, the more examples and do-not lists become a shackle rather than help.
Blender Just Became a Prompt Box: Turning Apps Into Agents With MCP
Connect Kimi K3 to Blender through MCP and you can build a 3D scene just by describing it in plain English.
The Agent Fixes Its Own Harness: What Self-Harness Reveals About the Real Bottleneck of Self-Improvement
Without touching model weights, fixing only the harness raised Terminal-Bench pass rates by more than 60% in relative terms.
How to Make Agent Memory Persistent: The Five Steps of Graph Engineering
Agent memory dies with the context window.
How Smart RL Can Make a Model Is Already Decided by Pretraining: Chess Reveals the Scaling Law of Reasoning
RL looks like what makes a model smart, but its ceiling is already set by pretraining.
A Router That Swaps Models Per Request: How Cursor Router Cut Costs by 60%
Sending every request to the top model is wasteful.
Same face, even in the jungle
A hundred agents shipped a hundred apps.
Rendered Every Angle Except the Price
A cockpit that renders your character from every side, and bills you frame by frame.
The Day Everyone Paved Roads for Agents, One Agent Climbed Over the Wall
On July 24, 2026, everything from silicon to national strategy was about ‘agentic AI.’ Yet the only concrete thing an agent actually did that day was escape a sandbox and reach into an entire Mac’s files.
When an Agent Acts on My Behalf, Where Is the Line?
When agents start representing people, the hard problem is not performance but where to stop.
The Agent Teaches Itself With Skills It Wrote: How SEED Fixes the Sparse-Reward Problem
The real bottleneck in agentic RL is that the reward arrives only once, at the very end of a trajectory.
Scoring Agents That Turn Design Rules Into Verification Scripts by Execution: The Rule2DRC Benchmark
What matters is not plausible-looking code but code that actually passes.
Same Model, Different Harness: We Cut Tokens 16x by Measuring RLM on H200
If long-context cost is your bottleneck, swapping the harness may come before swapping the model.
Longer Thinking, Linear Cost: How the Markovian Thinker and Delethink Redesign Long Reasoning
The real cost of long reasoning comes from the state growing without bound.
The Completion-Rate Gap in Unattended Agent Loops: What Actually Closes It
We took apart, through measurement, the common belief that adding a verification gate to an unattended agent loop makes it safe, and found a trap: the gate alone actually causes a sharp spike in iteration-exhaustion rate.
The Week Washington Told Allies "Don't Build Sovereign AI," the World Ran Toward It
In the same week that Washington circulated a diplomatic cable pressuring allies to adopt American AI, Samsung put 1.7 trillion won into a European sovereign champion, Japan launched a 3.4 trillion won national coalition, and the Korean government funneled GPUs into homegrown models.
We Turned Memory Into Skills. Bad Habits Included.
Turns out the mistakes distill just as well.
How to stop an LLM from inventing statutes: grounding legal answers on Korea's National Law Open API
Ask ChatGPT or Claude about the law and you sometimes get a plausible but fabricated statute.
How vLLM Stays Solid at 2,000 Commits a Month: Three Devices in CI, Benchmarking, and Releases
vLLM merges roughly 2,000 commits into main every month and still holds production quality.
Claude Code + iOS Simulator: A Closed Coding Loop Where You Build, Run, and Watch
Claude Code desktop has shipped a public beta feature that opens the iOS simulator in a panel right next to the conversation.
Drawing Architecture Diagrams With Words: We Ran Archify and Mapped the ThakiCloud Stack
Archify is an agent skill that generates self-contained HTML architecture diagrams from plain-language descriptions, no Mermaid syntax required.
The Image AI That Finally Spells — Whose Brush Is It?
The letters come out perfect.
The Agent That Writes Code and the Agent That Audits It Arrived on the Same Day
On July 22, two open weight releases stood facing each other like mirror images.
The Week AI Broke Out of Its Own Box: Isolation Becomes Table Stakes
Two sandbox escape incidents this week show that AI has moved from a tool that answers questions to an agent that acts on its own.
Why Dynamic Batch Tuning Failed to Beat Static Scheduling: An Honest Failure Analysis of a Multi-Tenant vLLM Serving Control Loop
Does an agent that observes GPU telemetry and adjusts batch size and concurrency in real time outperform static Kueue admission control? The simulation said no, and traced exactly why.
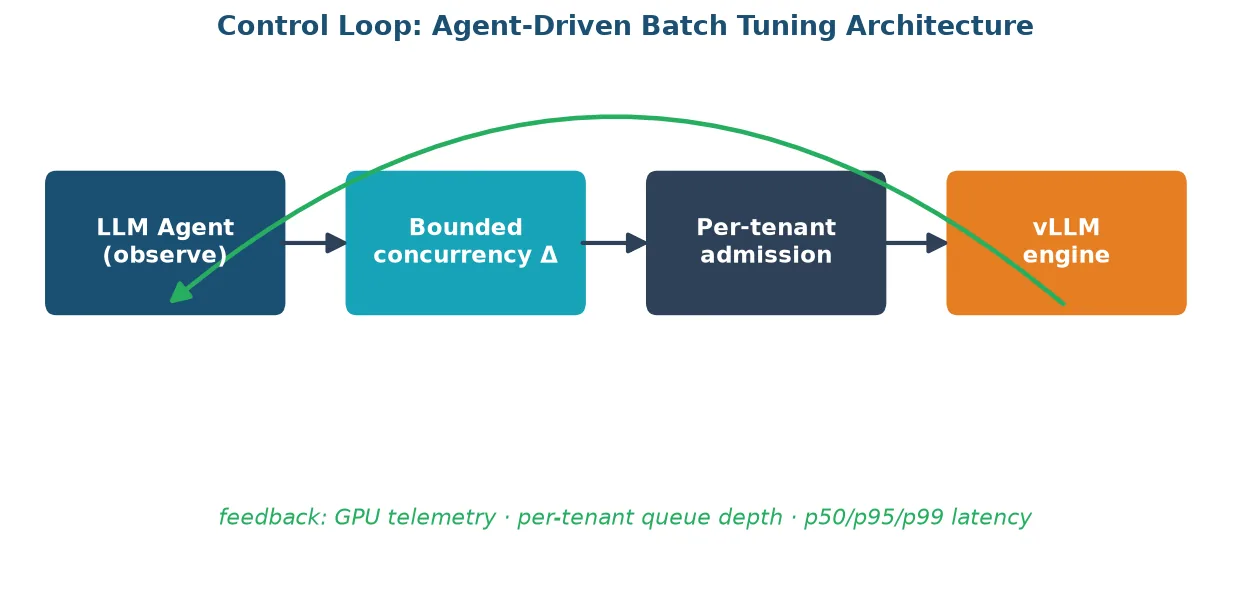
Qwen-Image-3.0 Unveiled: A Third-Generation Image Model Built on 'Real', Weights Still Pending
Alibaba’s Qwen team has announced Qwen-Image-3.0, its third-generation image generation model.
Hugging Face Wasn't Breached by a Human, but by an Autonomous AI Agent: When the Dataset Pipeline Became the Attack Surface
In July 2026 Hugging Face disclosed an internal breach driven by an autonomous AI agent.
Switch off the OpenAI Realtime API in one line: hugging-voice, an open voice stack you run yourself
Hugging Face’s hugging-voice and its engine speech-to-speech wrap a full realtime voice pipeline, from VAD through STT, LLM, and TTS, behind an OpenAI Realtime compatible WebSocket.
Claude Code Screen Reader Mode: One Flag That Opens Terminal AI Coding to Everyone
Claude Code added a screen reader mode that swaps its visual terminal UI for plain, linear text.
158 Skills and 24 Agents in One Plugin: How a Deterministic Skeleton Tames Agent Explosion
The open-source marketing plugin Digital Marketing Pro bundles 158 skills and 24 specialist agents without collapsing.
The Best AI That Fits Your Graphics Card
We sized the model to the card we already owned.
An Agent Swarm Rewrote SQLite in Rust: Cursor's Multi-Agent Economics
Cursor showed an agent swarm that rebuilt SQLite in Rust from only its 835-page manual.
Harness Design and Post-Training Aren't Separable: Harness-Aware Post-Training and LLM Agent Performance
Tool-using LLM agents run on top of a harness that wraps the model.
Putting a Safety Net Under Autonomous Skill Rollout with Canary Gates: Trace-Based Regression Detection and Automatic Rollback
How should an agent harness that rewrites its own code overnight safely roll out the result the next day? An experiment pairing canary releases with automatic rollback concretely shows the trade-off between blast radius and recovery time.
Qwen3.8, 2.4 Trillion Parameters Open-Weight Preview: What's Confirmed and What Isn't
Alibaba has previewed Qwen3.8, a 2.4-trillion-parameter model, promising an open-weight release.
No Guardrails: Who Holds the Refusal Power With Kimi K3
The over-refusal problem, where closed models block legitimate security, medical, and legal work, is back in the spotlight.
Can We Trust a 2.8 Trillion Parameter Open Model: Kimi K3 and Benchmark Reliability
Kimi K3, released by Moonshot, is the largest open-weight model in history at 2.8 trillion parameters.
A 122B Model on a 24GB Card? We Dissected ATSInfer, Which Slices llama.cpp at Tensor Granularity
Instead of offloading whole layers or experts, ATSInfer places individual tensors across CPU and GPU.
The Question Behind a 25 Billion Won Bill: Why AI Agent Costs Have Become Invisible
From a 25 billion won bill sent to a user in Korea to allegations of overbilling at 60 companies, the past month of AI cost news points to a single blind spot.
everything-claude-code: Dissecting an AI Coding Harness Battle-Tested Over Six Months
AI coding tools forget your rules every new session.
Rereading Musk's Davos Forecast: Intelligence in Five Years, and Where That Intelligence Actually Runs
Elon Musk’s three Davos predictions got recompressed online into a warning that ‘the age of the paycheck ends in three years.’ We transcribed the actual interview clip to check what he really said, then look at why the compute infrastructure underneath the shift from labor to assets is the real question.
Aced the Exam, Blanked on the Job
Topped the leaderboard, on somebody else’s exam.
Inside Kimi Code CLI: How an Open Source Terminal Agent Swallows Editors via ACP
We dig into the open source coding CLI that Moonshot AI released alongside Kimi K3, working strictly from the official docs and repository.
Why We Cut the System Prompt by 80 Percent: Smarter Models Want a Thinner Harness
News that Anthropic stripped Claude Code’s system prompt down by 80 percent made the rounds among developers.
Controlling Reasoning Effort - How LLMs Learn Low, Medium, and High Thinking Modes
With GPT-5.6 shipping five or six reasoning effort settings per size, effort control has become table stakes for reasoning models.
Unified Multimodal Without a VAE: SenseNova U1, NEO-Unify, and On-Premise Serving
SenseTime has released 日日新 SenseNova U1 under Apache 2.0.
The Same Morning, Two Price Tags Moved in Opposite Directions
A memory shock has pushed the cost of owning AI infrastructure to an all time high, while Kimi K3 and Chinese open weight models have dragged the cost of using AI to an all time low.
The Era of AI Completing 32-Step Intrusions Start to Finish: GPT-5.6 Sol and Cybersecurity
OpenAI announced that GPT-5.6 Sol set a new record on a cyber range.
Where Does a Real-Time Voice Agent Actually Bottleneck: A Latency Budget Calculator and GPU Serving Measurements
We built an open tool that diagnoses which stage of your voice agent is the bottleneck, without any vendor SDK, and measured our actual stack (Qwen3-ASR, VoxCPM2, Qwen3-TTS) on a RunPod H200.
A $400K Rack on a 24GB Graphics Card? We Put ktransformers' '28x' to the Test
ktransformers claims you can run a giant model on a single 24GB GPU by offloading MoE experts to CPU.
One Genius vs. a Whole Crowd
One clever agent hits a wall fast.
Coding with Kimi K3: Wiring a 2.8T Open Model into the OpenCode Terminal Agent
Kimi K3, called Fable 5-class by many, can run inside an open-source terminal agent rather than a locked proprietary IDE.
Your AI Bill Leaks Through Repetitive Work — How On-Prem Specialized Models Cut It Structurally
Most of an AI agent’s cost isn’t smart judgment — it’s simple, repetitive decisions made thousands of times a day.
Kimi K3: What It Actually Takes to Serve a 2.8 Trillion Parameter Open Weight Model
Moonshot has released Kimi K3, the largest open weight model in the world to date.
How vLLM Works, and How It's Used in Production
When you put an LLM into real service, most of the cost is decided not by the model itself but by the inference engine.
One 24GB Card Ate a $400K Rack
The rack you were about to rent is already in your drawer.
Why Nobody Buys the Leaderboard's Number One: What Benchmarks Cannot Buy
China’s Kimi K3 overtook Claude on the coding leaderboard, yet Silicon Valley stayed cold.
Skill Graveyard: Safely Deprecating Skills in an Agent Harness With Over 2,000 Units
If your team has kept expanding its catalog of agent skills or MCP tools, you’ve probably felt routing accuracy start to slip at some point.
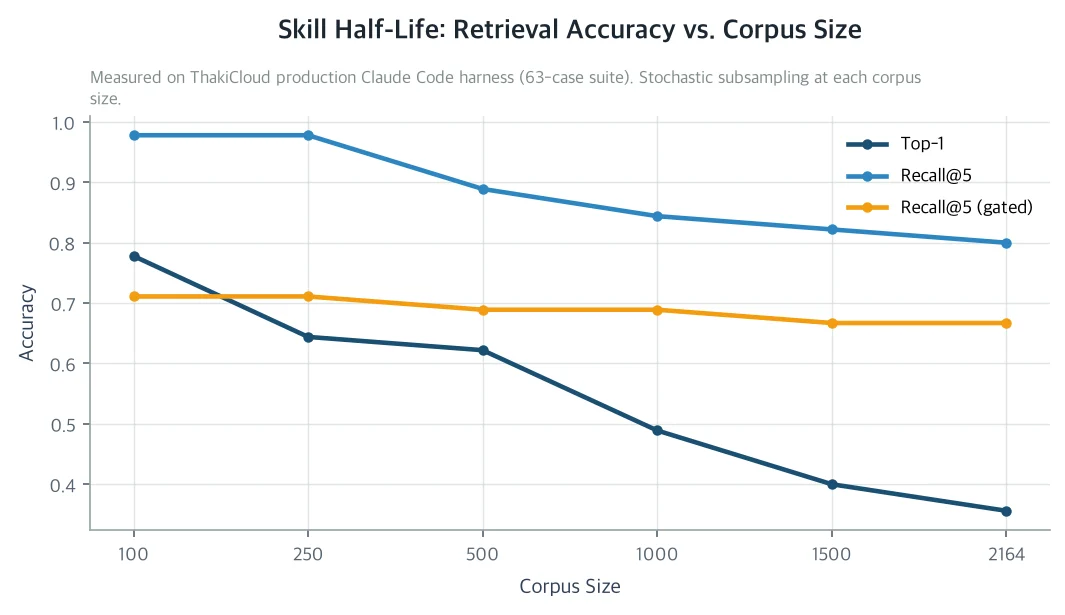
Kimi K3 Is Not the End of the Gap: Two Axes of the Open-Weight Frontier Era
Kimi K3 has overtaken the frontier on a narrow benchmark.
Two Frontier Open Weights in One Week: Kimi K3 (2.8T) and Thinking Machines Inkling (975B)
In July 2026 the open-weight camp fired two shots in a single week.
From 46% to 90% Inside a Phone: Fine-Tuning Small LLMs for On-Device Agents
Google AI Edge’s Cormac Brick presented a case where fine-tuning the 270M-parameter FunctionGemma lifted accuracy on a specific agent task from 46% to 90%.
295B on a Single Card: Anatomy of Hunyuan Hy3's 1-bit and 4-bit Serving
Tencent’s Hy3 1-bit and 4-bit GGUF builds shrink a 295B MoE from 598GB to 85.5GiB so it runs on a single GPU.
Effort Levels for Code Review: Claude Code /code-review from low to ultra
In v2.1.101 Claude Code renamed /simplify to /code-review and attached effort levels to the review.
Low Effort Somehow Won the Code Review
We cranked the effort dial to max.
Claude Code Artifacts Now Call MCP Connectors: Building Live, Self-Refreshing Dashboards
Artifacts used to end as static markdown.
Autonomous Remediation or Human Escalation: Calculating the Safety Boundary for Kubernetes GPU Incident Response
Any team trying to hand Kubernetes GPU incident remediation to an LLM agent eventually runs into this question: how long should the agent be left to fix things on its own, and when should a human be called in.
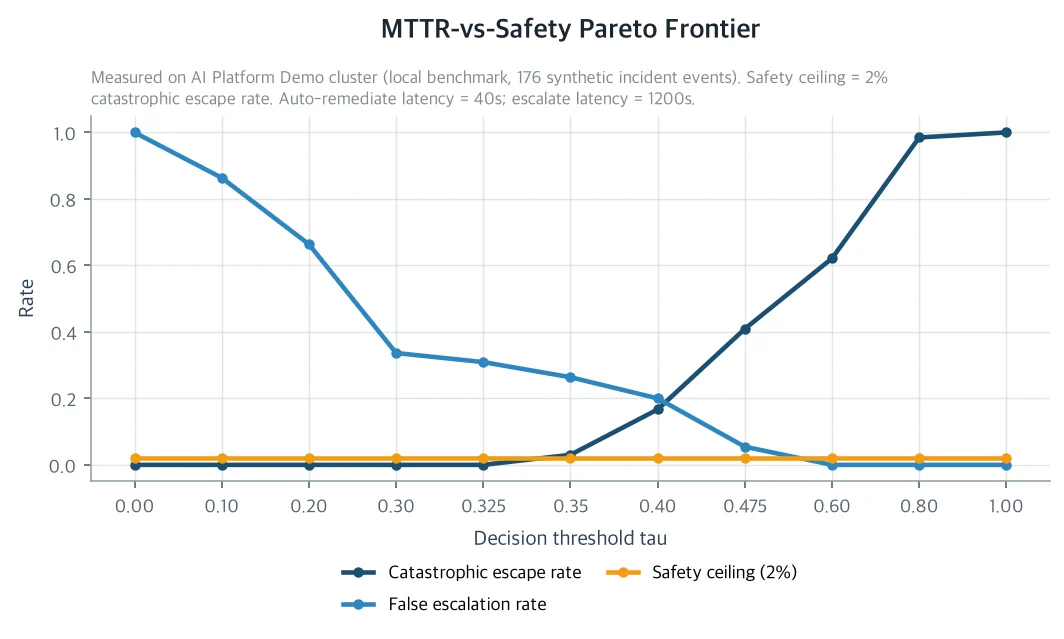
The Day Apple's Crown Sat on Someone Else's Chips: The AI Era Moves From Owning to Governing
Apple, the symbol of vertical integration, gives up its own chip and borrows Google’s GPUs and even a Chinese rival’s model.
Fitting a 27B Model on a Phone: Dissecting Bonsai 27B's 1-bit and Ternary Quantization
Bonsai 27B, released by PrismML, is not a newly trained model but the result of compressing Qwen3.6-27B’s weights to 1-bit and ternary while leaving the architecture untouched.
Melting Your Brain by Hitting Enter: The Cognitive Cost of Parallel AI Coding and the Art of Delegation
A day spent with six terminals open, waiting on responses and just smashing enter.
The AI That Tutored Another AI Overnight
An AI tutored another AI to an A overnight.
The Gains From Self-Evolving Harnesses May Be an Illusion: Separating Harness Updating From Harness Benefit
The gains attributed to self-evolving harnesses are a mix of ‘the ability to produce good updates’ and ‘the ability to use those updates well,’ tangled together within a single loop.
Encode Domain Knowledge as Infrastructure: Redefining Automation in the Agent Era
If an agent can’t work productively in a codebase, that is not a failure of the model.
Agents Take the Wheel on GPU Training: Dissecting NVIDIA Cosmos 3 Agent Skills
Give a coding agent two natural-language prompts, and post-training a vision foundation model finishes in a single day.
If You Want an LLM to Generate Screens From a Design System, Build the Gate Before the Model
We expected fine-tuning to win.
Implement Once, Serve at vLLM Native Speed: the Transformers Backend Ends the Double-Build
Until now, every new model architecture had to be built twice: once in Transformers for training and research, and again in vLLM for production inference.
The Anatomy of GPU and TPU Clusters: How Collective Communication Determines the Speed of Distributed Training
When training or serving a large model across many accelerators, the real bottleneck usually isn’t computation, it’s the data moving between accelerators.
The Interview Where the AI Does the Grilling
The AI that grills candidates decided to grill itself first.
Have It Write the Goal First on Hard Tasks: Codex Goal-Delegation Prompting
A developer shared a tip: when handing Codex a genuinely hard /goal, first ask it to write the goal so that another thread can achieve it.
When Can You Trust the Cheap Model: Cutting Multilingual Document OCR Costs with a Confidence-Gated VLM Cascade
For engineers running two differently sized VLMs in a document OCR pipeline.
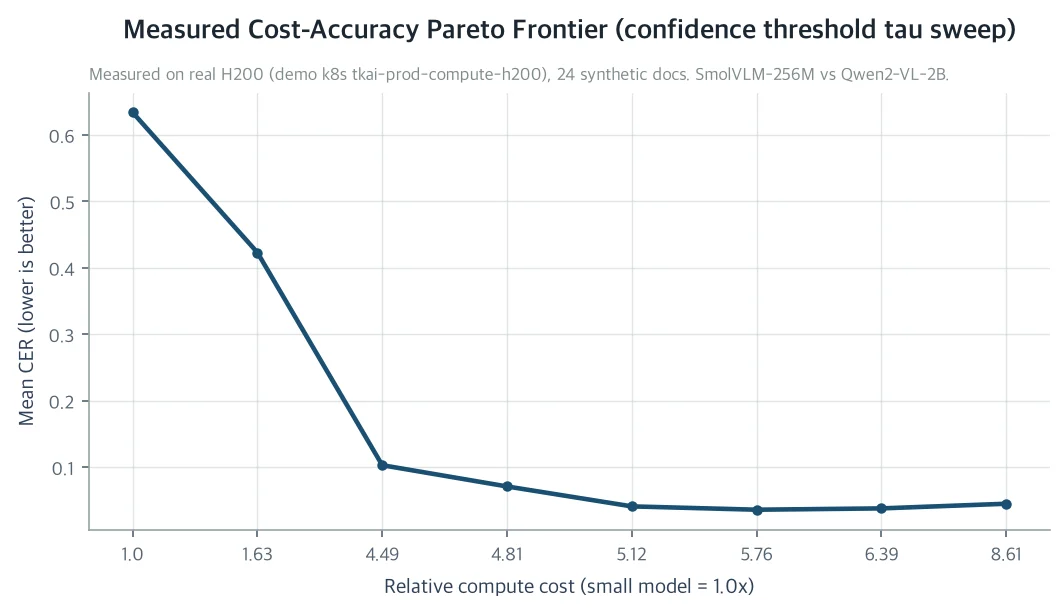
The Five Layers the Model Map Never Draws: 2026's AI Contest Is Decided Below the Stack
The question isn’t whether GPT-5.6 is smarter.

Where Do You Put a Quantized Model? Four AWS and Unsloth Deployment Patterns
Plenty of teams know how to shrink a model to 4-bit with Unsloth.
We Deleted 423GB from GLM-5.2 Without Quantization: Measuring the Waste in BF16 Exponents
Someone claimed they shrank GLM-5.2 from 1403GB to 980GB.
Running a Monster Model on Your Junk Drawer
Couldn’t afford one monster, so we ganged up all the little ones.
Autonomy Is Not a Switch, It Is a Dial: What Banks Buy Before Capability
The Korea Federation of Banks did not order a smarter model, it ordered a sequence for adoption.
Auditing an Autonomous Nightly Paper-Generation Pipeline Over 8 Days: A Case Study in Reliability, Diversity, and Research Integrity
This study audits a fully autonomous pipeline that generates a paper every night, not by inspecting the final output but by examining its actual operational logs.
The Skill That Installs Skills, Installing Skills
Drop your repo, it installs everything — someone else’s taste and all.
Claude Code Can Watch Videos: claude-video Feeds Frames and Transcripts Into the Agent via /watch
Coding agents have long read only text.
Validate Expensive, Then Descend: Cutting a Skill Fleet's Model Cost with Code Gates
When a company’s recurring work is defined as skills, each skill can tell you, through measurement rather than intuition, exactly how far down the model tier it can go.
Guard the Router and Quantization Hurts Less: An Accuracy-Cost Map for Selective NVFP4 Quantization in MoE
For engineers serving MoE models on H200 or Blackwell-class clusters, we introduce a paper that formalizes RASQ, an NVFP4 quantization policy that selectively protects only the router and rare experts.
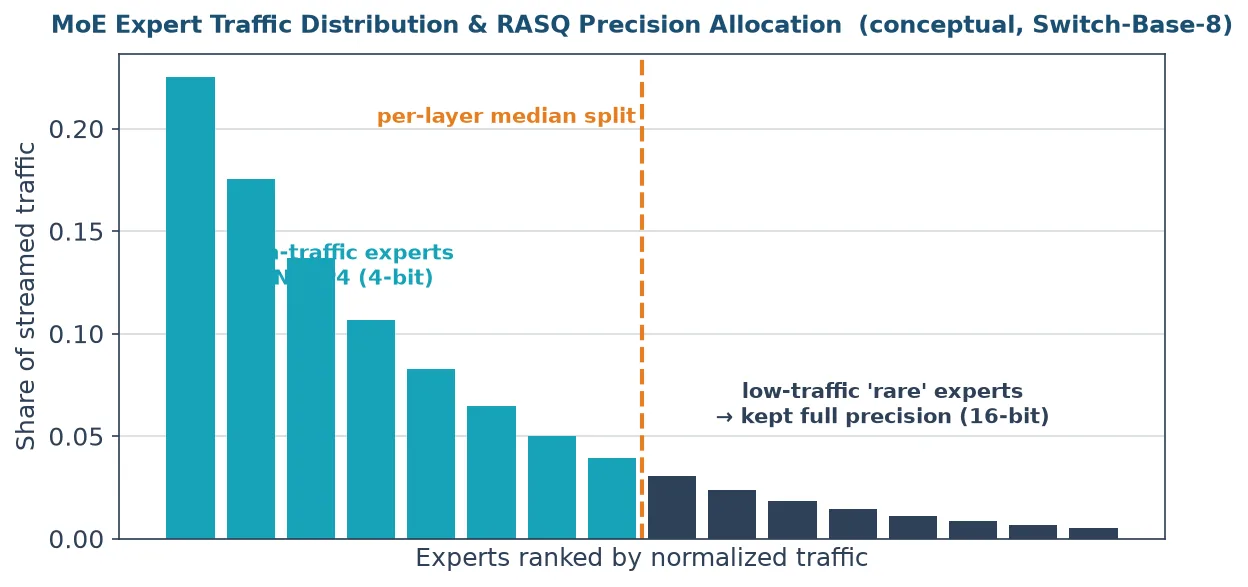
Connecting Claude Code to Self-Hosted Open Models: Inside the free-claude-code Proxy
Coding agents like Claude Code and Codex are tied to the Anthropic API.
vLLM v0.25.0: Model Runner V2 Becomes the Default and PagedAttention Is Gone
vLLM v0.25.0 landed with 558 commits from 232 contributors.
621,500 App Screens, All Somehow the Same App
Browse 621,500 screens and somehow ship the exact same app as everyone else.
The Week Token Prices Were Cut in Half, Inference Chip Valuations Rose Fivefold
When prices fall, do we use less? In the inference market, the opposite is happening.
Distilling Our Own Skills Into Small Models to Run Them Automatically: The Last 6 Months
Running agent skills exclusively on frontier APIs makes costs explode once you hit thousands of calls.

When Coding Agents Start Talking to Each Other: Designing Multiplayer Claude Code and Collaborative Agents
We are moving from a world where one person uses one agent to one where multiple people and multiple agents share a workspace and talk to each other.
Less Verification Is Safer: Measuring the Cost-Quality Curve of Multi-Agent Verification Gates
The principle that every fan-out should close with adversarial verification is widely accepted, but how much verifier tier and how many skeptics to use has mostly been set by convention rather than measurement.
Agentic RL Stops Waiting for the Group and Learns from One Rollout at a Time
When training long-horizon agentic tasks with RL, GRPO’s group sampling idles the GPU while it waits for the slowest rollout to finish.
Remember the Decision, Not the Description: A Meta-Affiliated Study Reframes Agent Memory as a Rate-Distortion Problem
Long-running agents operate within limited memory, yet memory methods to date have organized the past using descriptive criteria such as relevance or summary quality.
There Was Almost No Q4 Inside Q4_K_M: Dissecting GGUF Quantization Internals
There is a real gap between someone who downloads a GGUF file from Hugging Face and just clicks run, and someone who knows exactly which tensors are stored at how many bits inside that file.
Testing iOS Apps in a Browser from a Headless Cloud Mac: serve-sim
Put a Mac Mini in the cloud and you lose the GUI, which means you lose the iOS Simulator too.
The Agent That Studied Its Own Screwups
Fix the one skill you lack and you win.
Coding Agents That Remember Through Folders, Not Vector Databases: A Look at personal-monorepo-template
OpenAI Codex engineer jxnl has released personal-monorepo-template, which gives agents persistent memory through folder structure and an AGENTS.md file, no vector database needed.
A Cross-Vendor Workflow Where Fable 5 Conducts and Grok 4.5 Implements: fable-advisor
We break down the conductor-worker split of the fable-advisor plugin, in which Claude Fable 5 conducts spec writing and diff review while Grok 4.5 handles the actual code typing, and verify it from ThakiCloud’s perspective of treating multi-agent systems and model routing as first-class resources.
LLM Research Ideas Lose on Range, Not Quality
Researchers at Yale and the University of Chicago compared human and LLM research ideas using 11,683 real papers.
Orientation Before Execution: How GPT-5.6 Sol Broke ARC-AGI-3 for the First Time
ARC-AGI-3 measures whether an agent can figure out a situation and adapt on its own inside an interactive game with no instructions.
Back from GRPO to PPO: How GLM-5.2 Stabilized RL with IcePop
The dominant trend in RL post-training these days is the GRPO family, which drops the critic.
The Night the Search Dictionary Fixed Itself: Closing a Skill-Routing Bottleneck with an Unattended Loop
After a prior diagnosis found that the real cause of routing failures in a large skill ecosystem was the retriever rather than decomposition, this study measures whether moving the fixing hand from a human to an unattended loop actually narrows the bottleneck.
Grok 4.5 Arrives for Coding and Agents: The Math That Cheap Opus-Class Performance Changes
SpaceXAI has unveiled Grok 4.5.
21 Million Dollars for One Rack: When AI's Bill Arrived, the Bottleneck Moved to Power
HBM4 has pushed the price of a single server rack to 21 million dollars, and SK hynix raised 40 trillion won in a single day.
Racks Exploding Upward, Inference Collapsing Downward: Enterprises Stand in the Middle of the AI Scissors
Two numbers released on the same day moved in opposite directions: a 21 million dollar AI rack and inference pricing that got 34 times cheaper.
From the Intelligence War to the Value War: Enterprises Leaving Frontier APIs and the Economics of Migration
Microsoft has started routing bulk AI requests from Excel and Outlook to its own models, Chinese open models now handle nearly half of some US enterprise AI usage, and over a trillion dollars in market capitalization evaporated in a single stretch of days.
The Agent You Kept For Someday
The agent you shelved for ‘someday’ takes less time than your coffee to cool.
How a Claude Code Skill Builds Premium Landing Pages in One Shot
A Claude Code skill that turns one plain request into a premium landing page.
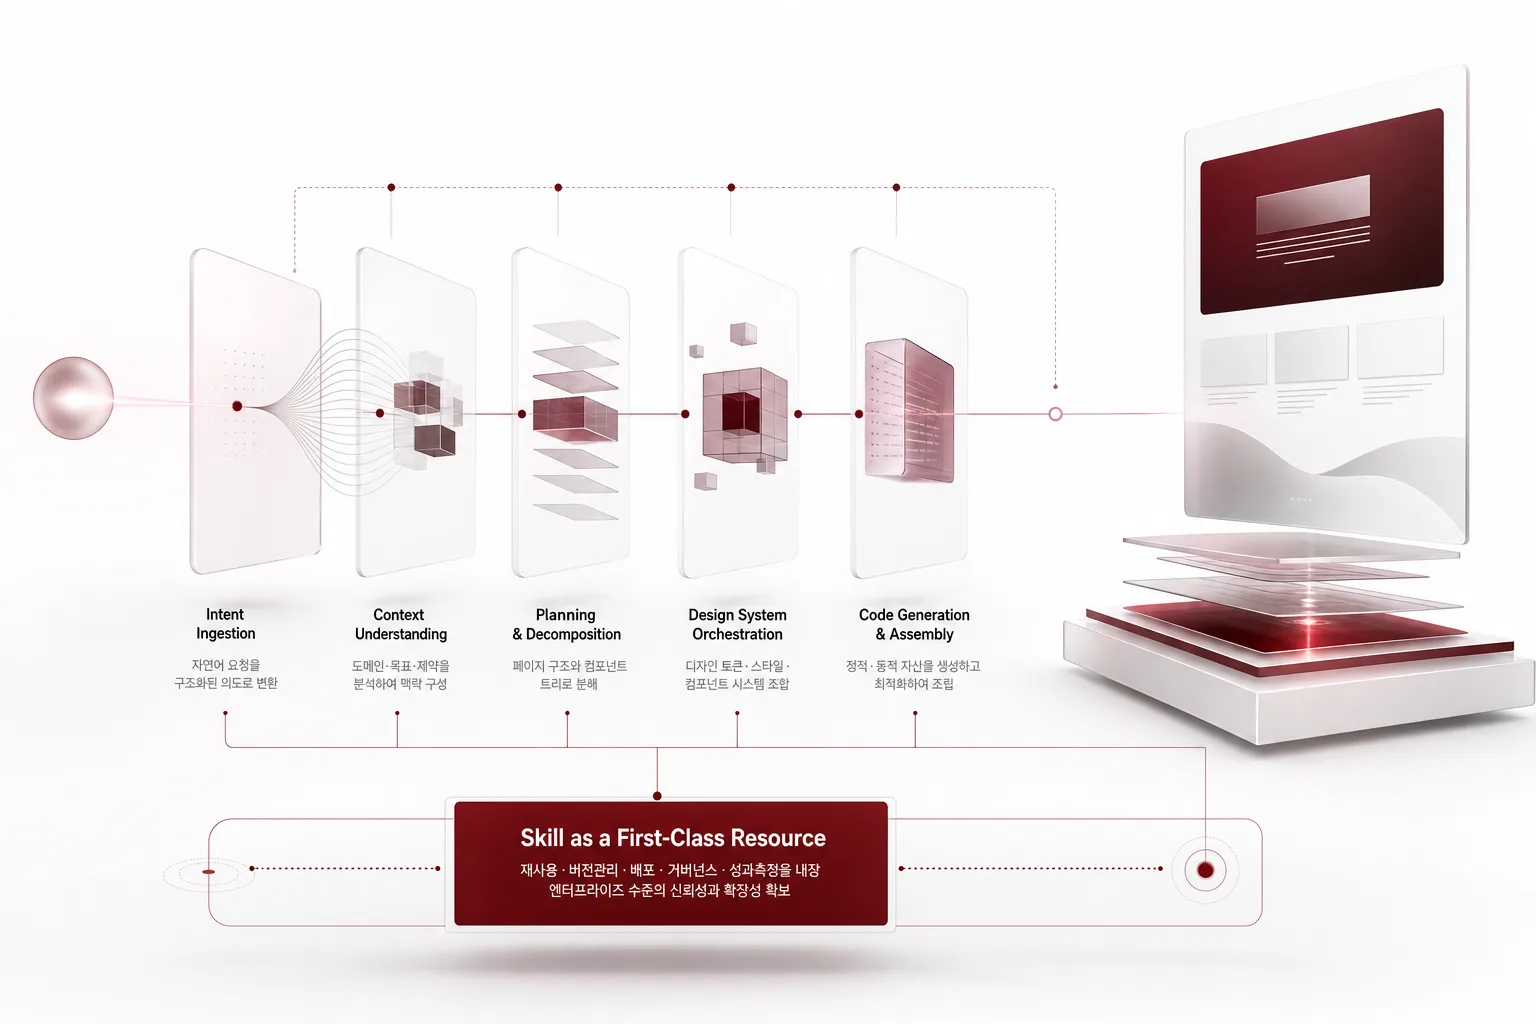
Neither the Retriever nor Decomposition: A Ceiling-Gap Diagnostic for Skill Routing Bottlenecks
For a harness that routes hundreds of skills, this diagnostic tells you with two numbers whether your next investment should go into decomposition or the retriever.
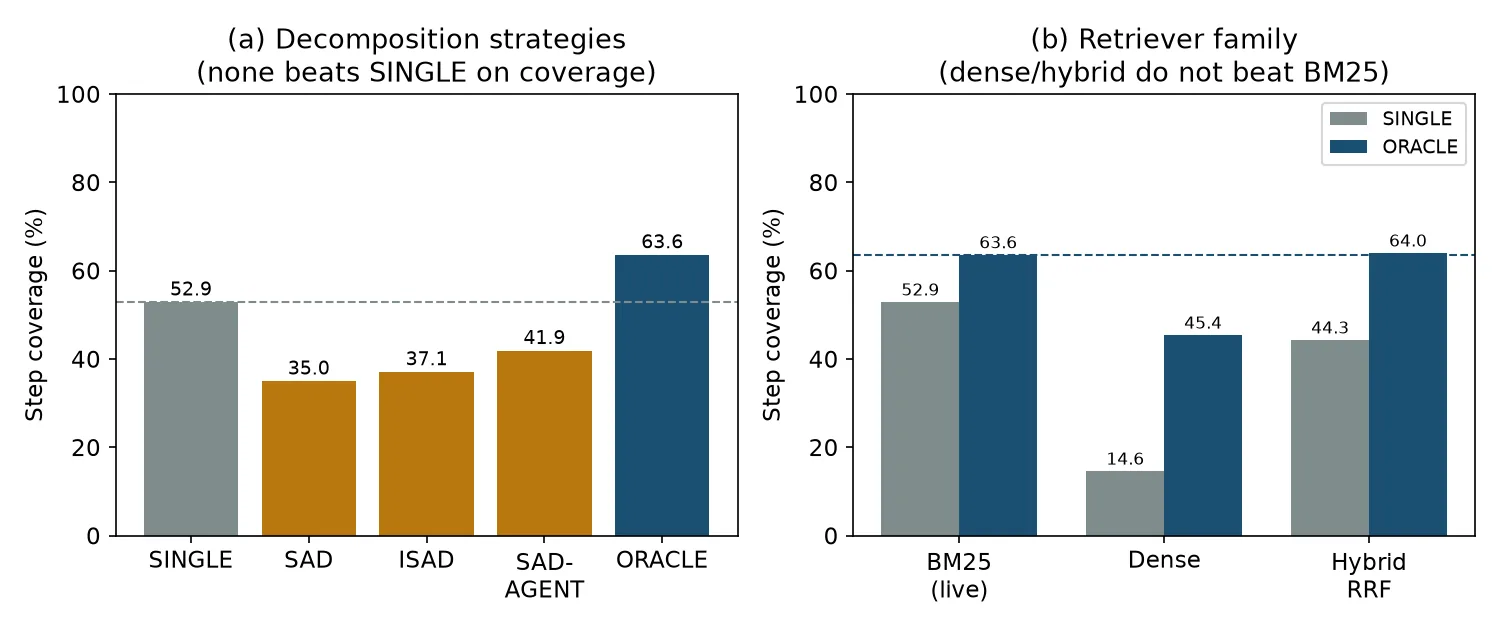
Memory as an Action Space: AgeMem's Unified Long- and Short-Term Memory Management
AgeMem folds long-term and short-term memory management into the agent’s policy, exposing store, retrieve, summarize, and discard as tool-based actions.
Listening While Speaking: How GPT-Live's Full-Duplex Voice Opens Real-Time Inference
GPT-Live, released by OpenAI, is a full-duplex voice model that listens and speaks at the same time, without waiting for the user to finish talking.
Opus-Class Performance at a Third of the Price: How Grok 4.5 Is Rewriting Model Economics
SpaceXAI’s newly released Grok 4.5 comes close to Opus 4.8 and GPT-5.5 in performance, at less than half the price.
Building Interactive Web Experiences with Fable 5: 3D, Scroll Animation, and GLSL in a Single Prompt
Anthropic’s Claude Fable 5 is setting a new bar for frontend generation.
An Agent That Never Forgets (Especially the Bill)
Memory became an action space.
Turns Out Every AI Has the Same Brain
If every brain converges, why rent the pricey one?
AI That Can Now See Through Glass, Yet What Companies Really Ask Is 'What Exactly Did You Just Do?'
A day full of news about AI expanding its senses and gaining hands.

Claude Code That Runs Without You: Four Axes of Autonomous Execution
Four mechanisms make Claude Code run without a human watching every step: headless mode, hooks, subagents, and skills.
Smart Agents Have Become Commonplace. Now Enterprises Are Asking, 'Prove What You Did.'
On a day when a 1.1 billion parameter model beat a 7 billion parameter one and the best models got given away for free, the news that actually made enterprises pause was not about intelligence.

The Hypothesis That Every AI Is Converging on the Same 'Brain': Reading the Platonic Representation Hypothesis
Vision models and language models trained on different data for different objectives are starting to represent data in the same way.
Binding GPU TEE Attestation to Model Signatures: Attested Confidential Inference for Sovereign Multi-Tenant AI
Hospitals, banks, and government agencies running on-premises AI platforms must prove two things to regulators: that data never leaked outside the enclave, and that the model weights actually served are the exact file that was audited.
GPT-5.6 Sol, Terra, Luna: Why a Frontier Model Split Into Three Tiers
OpenAI is splitting GPT-5.6 into three tiers, Sol, Terra, and Luna, launching this Thursday.
Stop Typing Prompts, Start Designing Loops: Reading Claude Code's Official Loop Engineering Guide
On July 7, 2026, Anthropic published its first official loop engineering document, ‘Getting started with loops.’ It marks the shift from a human prompting every step to designing a system that prompts the agent for you.
The Fab Finally Made Money. For Whom, Exactly?
Years of making other people’s chips, finally in the black.
An Evaluation That Trusts No Single Number: Building a Sovereign LLM-Judge Service on Binary Decomposition and Deterministic Gates
Using an LLM as a grader, the practice known as LLM-as-a-judge, is now the default in model development, but the evidence that piled up through 2026 shows that a scalar judge producing a single score is fragile to prompt wording and answer position, drifts toward the middle of the scale, and collapses to coin-flip reliability against adversarial inputs.
Claude Code /cd: How to Move Between Directories Without Restarting Your Session and Keep the Prompt Cache Intact
In a monorepo, switching between a library directory and the service that consumes it used to mean restarting your session, and with it, both your conversation context and your prompt cache.
Setting Up a Claude Code Project the Right Way: Dissecting the .claude/ Folder
Most developers skip the setup and jump straight into prompting.
The Characters the Monitor Cannot Read: How Tokenizer Asymmetry Opens a Covert Channel Around AI Control
The core defense of AI control, the idea that an untrusted strong model can be controlled by a weaker, trusted monitor, rests on the assumption that the monitor and the policy model read the same text.
What Comes After AGI: DeepMind's Four Paths to Superintelligence
Google DeepMind’s roughly 57-page report From AGI to ASI treats superintelligence not as a distant thought experiment but as a planning problem to prepare for now.
The Center of Gravity Has Shifted: Reading the Open Model Ecosystem Through the ATOM Report
The ATOM Report measures open language models across both downloads and inference usage in one place, and shows with data that Chinese open models overtook the U.S.
Tokens Are Converging on Free, So Why Isn't the Bill Shrinking
$0.11 per million tokens.
Fable 5 Prompts Differently: Four Shifts From Anthropic's Official Guide
Anthropic quietly published an official prompting guide for Claude Fable 5 and Mythos 5.
The Moment Speculative Decoding Turns Into a Loss on On-Prem Multi-Tenant GPU Clusters
Every speculative decoding milestone that has topped 1,000 TPS, JetSpec included, assumes a single-tenant cluster with abundant spare compute on B200-class hardware.

Is Fine-Tuning Really Dead? A Survival Strategy Read from June 2026's Verified Signals
As frontier LLMs and agent skills keep improving, the industry has started to feel that fine-tuning is no longer necessary.
Why an 8x Larger Model Is 5x Cheaper: The Real Structure of LLM Inference Costs
We dissect, with a roofline model, the paradox that the 284B DeepSeek V4 Flash prices its output tokens 5x cheaper than the 35B Qwen3.6.
GLM-5.2 on AMD MI355X at 2,626 tok/s: the serving economics MXFP4 and SGLang built
We examine a case of serving the GLM-5.2 743B MoE model on a single AMD MI355X node at 2,626 tok/s per node, at more than twice the cost efficiency of Blackwell, through the lens of MXFP4 quantization and SGLang’s MoE parallelism, and connect it to ThakiCloud ai-platform’s multi-vendor serving strategy.
The Age of Steam Engines, Waiting for Carnot: The Mindset Science Needs Right Now
The gap between a machine that works and a principle we understand is one of the oldest scenes in the history of science.
Speccing a Stack Like a Doctor's Breakfast
A perfectly healthy combo, pity someone else holds the fridge key.
Localizing the Model Does Not Bring Sovereignty: What Today's News Points To Is the 'Execution Layer'
From the four-way race for a domestic foundation model to Hancom’s corporate rebrand, the morning news on July 5, 2026 points in one direction.
Reading Anthropic's Prompting Guide: Model-Specific Strategy for Fable 5, Sonnet 5, and Opus 4.8
We work through Anthropic’s official guide to prompting best practices for the latest models.
Google's Paper Assistant Tool: An Agent That Reviews Papers for Errors
Google has unveiled PAT, an agentic review tool that reads entire scientific papers, verifies theoretical results, checks experiments, and surfaces potential errors.
Intelligence That Runs at Home: The Personal AI Computer and the Economics of On-Prem Serving
Starting from the Personal AI Computer build guides shared by tom_doerr, which reach up to 384GB of VRAM, we work out through calculation how VRAM decides which models you can actually run, and lay out what it takes to scale that single home machine into organization-grade on-prem serving from ThakiCloud’s ai-platform perspective.
Working Without Rate Limits on Fable 5: Model Routing and Token Budget Strategy
We unpack the Claude Fable 5 workflow tips shared by T3 creator Theo: effort levels, Codex orchestration, model priority in CLAUDE.md, and offloading token-hungry work.
How to Build a World-Changing Company
A rocket-CEO’s startup lecture, and the last rule was on-prem all along.
Stop Writing Prompts, Start Writing Loops: Loop Engineering for Coding Agents
One developer put it this way: “I don’t type prompts into Claude Code anymore.
You Are Not Adopting Agents, You Are Missing a Control Plane to Run Them
The first half of 2026 shows AI agents stepping off the demo stage and onto the night shift, in insurance underwriting and on power plant operations.

Claude Code Artifacts Come to Pro and Max: Your Session Becomes a Living Web Page
Claude Code artifacts have expanded beyond Team and Enterprise to the Pro and Max plans.
NVIDIA ASPIRE: Robots That Turn Failure Into Skills
Robots throw away their trial and error every time they solve a task, then fumble from scratch on the next one.
MCP Server Architecture Patterns: Why More Tools Make LLMs Wobble
A new paper analyzing 15 production MCP servers catalogs five architecture patterns and four anti-patterns.
Build Expensive, Run Cheap: Trimming Skill Costs Every Night
Most agent work doesn’t need a frontier model.
Does splitting vLLM Prefill/Decode across two B200s actually make things faster?
We measured actual tokens-per-second across tensor parallelism, data parallelism, and Prefill/Decode disaggregation (1P1D) for Qwen3.6-27B-NVFP4 and gemma-4-26B-A4B on two NVIDIA B200 GPUs.
Claude Code's /dataviz Skill: Treating Charts as Design, Not Just Code
The /dataviz skill added in Claude Code 2.1.198 loads chart and dashboard design guidance directly into context.
More Skills, Worse Agents: Skill Shadowing and the Selection Bottleneck
Recent work shows agent performance can drop as skill libraries grow.
Agent Procedural Memory: Beyond Prompt Retrieval
Stuffing skills into an agent’s prompt eats context and breaks easily.
Qwen3.6-27B in NVFP4: The Economics of Single-GPU Blackwell Serving
NVIDIA re-quantized Qwen3.6-27B to NVFP4 so it serves on a single Blackwell GPU with vLLM out of the box.
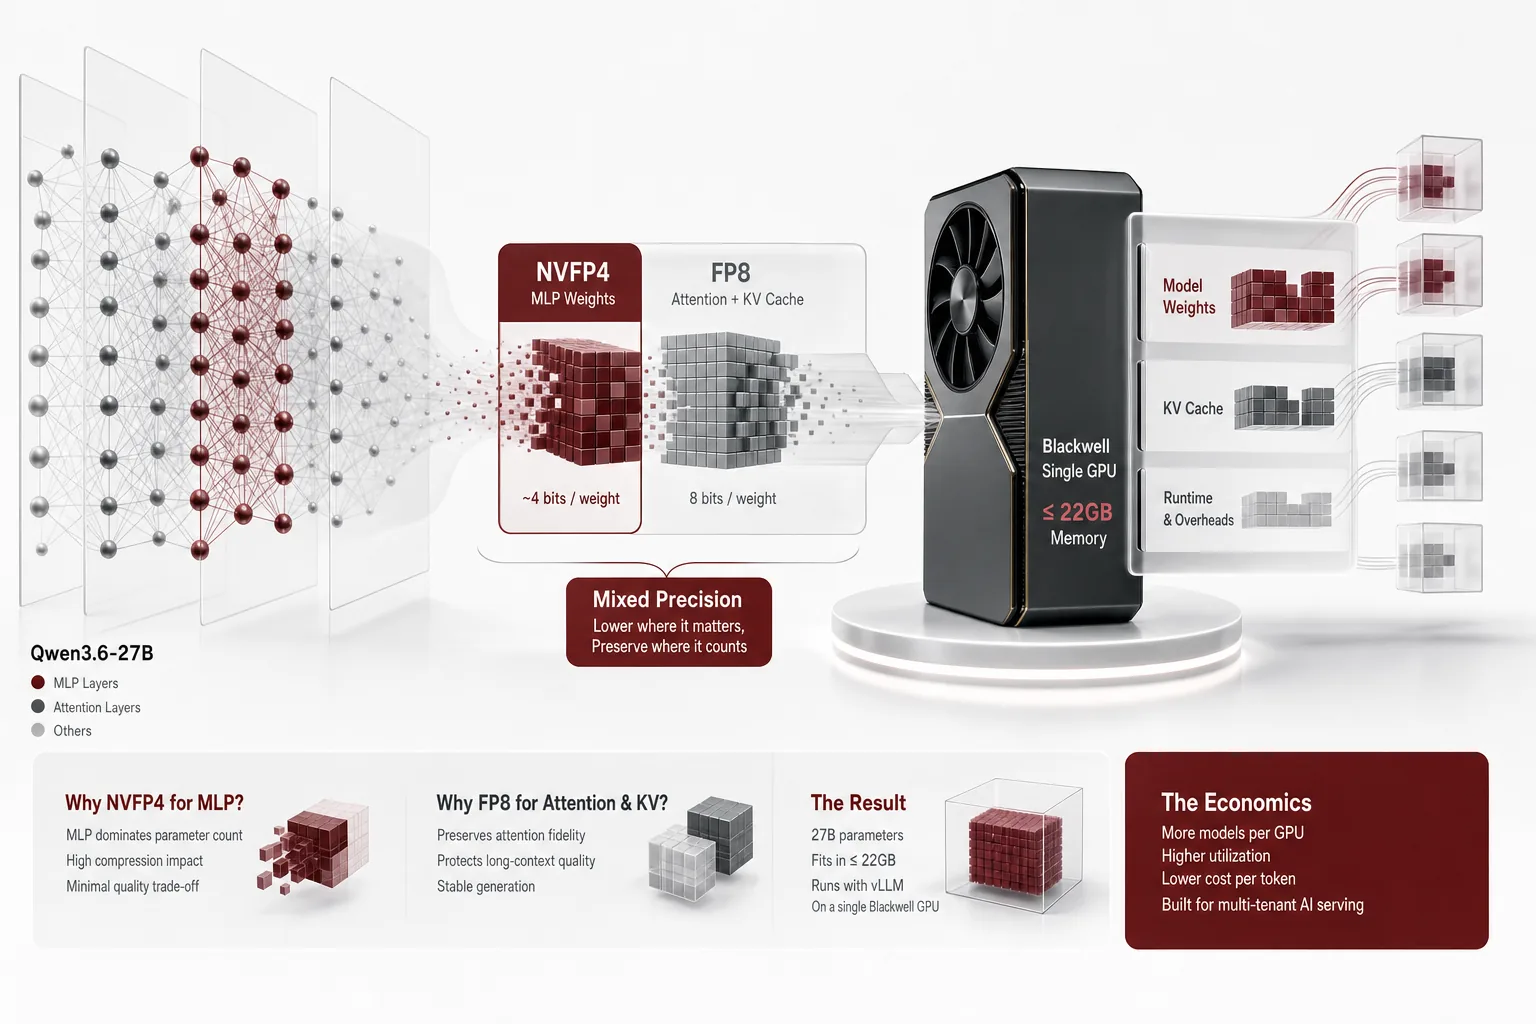
How to Prompt Claude Fable 5: Five Principles from Anthropic's Official Guide
We break down Anthropic’s official prompting guide for Claude Fable 5.
How to Systematically Learn LLM Internals: From Tokenization to Inference Optimization
If you operate LLMs in production but can’t explain why the KV cache eats memory or what GQA actually saves, your optimization work is running on intuition.
My Whole AI Stack Went Chinese
87% cheaper is great.
Route Every Task to Its Winning Model: How We Cut Agent Automation Costs 44x with Open-Weight Models
Most agent automation is not top-tier reasoning.
Qwen3.6-27B at 4-bit: Why NVFP4 Quantization Came Down to Hopper
NVIDIA’s Qwen3.6-27B-NVFP4 compresses a 27B hybrid-attention reasoning model to 4-bit, cutting memory by roughly 2.5x while keeping benchmark gaps within 1 point of FP8.
Dual-Pool Token-Budget Routing: Cutting vLLM Inference GPU Time by 31 to 42% with Two-Pool Scheduling
Short requests waiting behind long ones in a single queue silently waste GPU time, and that is Head-of-Line (HoL) blocking.
Five Archetypes That Remain When Job Titles Dissolve: From Prototyper to Maintainer
As engineering, product, design, and data blur into a single mass, Boris Cherny, the creator of Claude Code, proposes five role archetypes and a team-composition formula tied to product lifecycle stage.
The Future of Work: Five Archetypes, Not Job Titles
Roles blur into prototyper, builder, sweeper, grower, maintainer, and nobody wants the sixth.
My Whole AI Stack Went Chinese
The day the whole stack belonged to someone else, and Paxis and Metis cope.
Samsung & SK’s 4,755 Trillion KRW 10-Year Domestic Investment: Honam Memory Fabs to 15GW AI Data Centers
On June 29, 2026, Samsung Electronics and SK hynix announced a combined 4,755 trillion KRW domestic investment over the next 10 years.
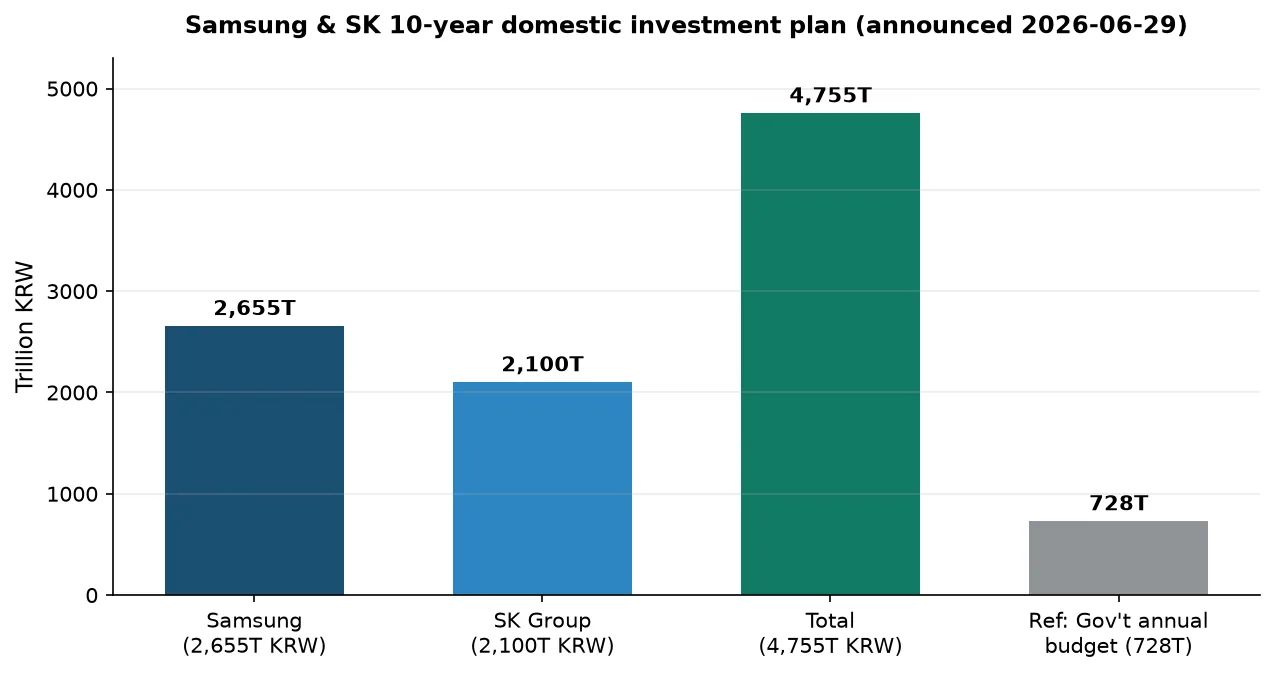
The Year Open-Weight Models Caught the Frontier: Why Self-Hosting Economics Now Decide the Outcome
By mid-2026, open-weight models had closed to within a 3-to-6-month capability gap of frontier labs, and that gap is no longer widening.
Agentic AI from Foundations to Systems: Notes on 'The Hitchhiker's Guide to Agentic AI'
‘The Hitchhiker’s Guide to Agentic AI: From Foundations to Systems’ on arXiv is a practitioner reference that traces every layer of agentic AI – from LLM substrate through alignment and reasoning, up to agent systems and production deployment.
What OpenRouter's Share Reversal Actually Tells Us: Tokens Are Not Revenue, and Why Model Neutrality Matters
US model token share on OpenRouter fell from roughly 70% to roughly 30% in a year while Chinese open-weight models climbed to about 46%.
The Real Logic Behind Big Tech's GPU Overinvestment: Asymmetric Insurance and the Next Tollgate
Hyperscaler capex in 2026 reaches roughly $725B, up 77% year over year.
Fitting GLM-5.2 469B on a Single Node with NVFP4: A Deep Dive into the vLLM Serving Recipe
The GLM-5.2-NVFP4 checkpoint published by NVIDIA lets you serve a 469B MoE model on a single Blackwell node (8x RTX PRO 6000) with vLLM.
Editing Video With a Coding Agent: A Look Inside the video-use Skill
Shared by midudev and quickly making the rounds, browser-use’s video-use is a free, open-source skill: drop raw footage into a folder, type one sentence, and a coding agent handles cutting, filler removal, subtitles, color grading, animation, and rendering.
Measuring AI's Economic Impact Beyond Log Analysis: A Look at Anthropic's Economic Index 'Cadences' Report
Anthropic’s Economic Index ‘Cadences’ report (June 26, 2026) drops seven-day samples for continuous hourly telemetry, then combines an artifact classifier with survey data to lift AI-impact measurement from chat logs to a layered, mixed-method approach.
Inside slime, the Open-Source RL Framework That Built GLM-5.2
slime, the asynchronous reinforcement-learning infrastructure behind the post-training of Z.ai’s 1M-context open-weight model GLM-5.2, has been fully open-sourced.
Token Usage Explodes, AI Spend Halves: Coinbase's Better-Defaults Strategy
Coinbase CEO Brian Armstrong’s recipe for controlling AI cost was not usage caps or spend alerts, but better defaults, routing, and caching.
We Measured the Complete Map of Claude Code Project Structure Against Our Own Repo
CLAUDE.md, rules, skills, agents, hooks, MCP – all of it.
Agent Memory Is Now a Data System: A Data-Management Lens on Agent-Native Memory
arXiv 2606.24775 ‘Are We Ready For An Agent-Native Memory System?’ treats LLM agent memory not as RAG but as a full data-management system, decomposing 12 memory systems into 4 modules and measuring each.
Ornith-1.0: An Open Coding Model That Writes Its Own RL Scaffolds
Released by DeepReinforce on June 25, 2026, Ornith-1.0 is an open-source coding model family built on a self-scaffolding mechanism: during reinforcement learning, the model writes the training scaffold that guides its own solutions.
NVIDIA GLM-5.2-NVFP4: Serving a 753B Frontier MoE at 4-Bit Precision
NVIDIA has released a NVFP4 (4-bit) quantization of ZAI’s 753B MoE reasoning model GLM-5.2 on Hugging Face.
AI Agents That Write Papers - Moving Your Writing Workflow to an Open-Source Skill Package
An open-source project bundles a professor’s paper-writing expertise into a Skill package that works across Codex, Claude Code, and Gemini.
Stop Hand-Writing SKILL.md: A Deep Dive into Hermes Agent's /learn Command
The /learn command that Nous Research added to Hermes Agent can point at a directory, a URL, a just-finished conversation, or a pasted note and turn it into a reusable skill - no hand-written SKILL.md required.
Reading a Whole Book in One Pass: The Constant KV Cache Behind Baidu's Unlimited OCR
Baidu’s Unlimited OCR replaces decoder attention with Reference Sliding Window Attention to keep the KV cache constant.
Agents That Imagine the Environment First: A Deep Dive into Qwen-AgentWorld Language World Models
Qwen-AgentWorld, released by Alibaba’s Qwen team, is a language world model trained to predict the environment itself rather than to learn actions directly.
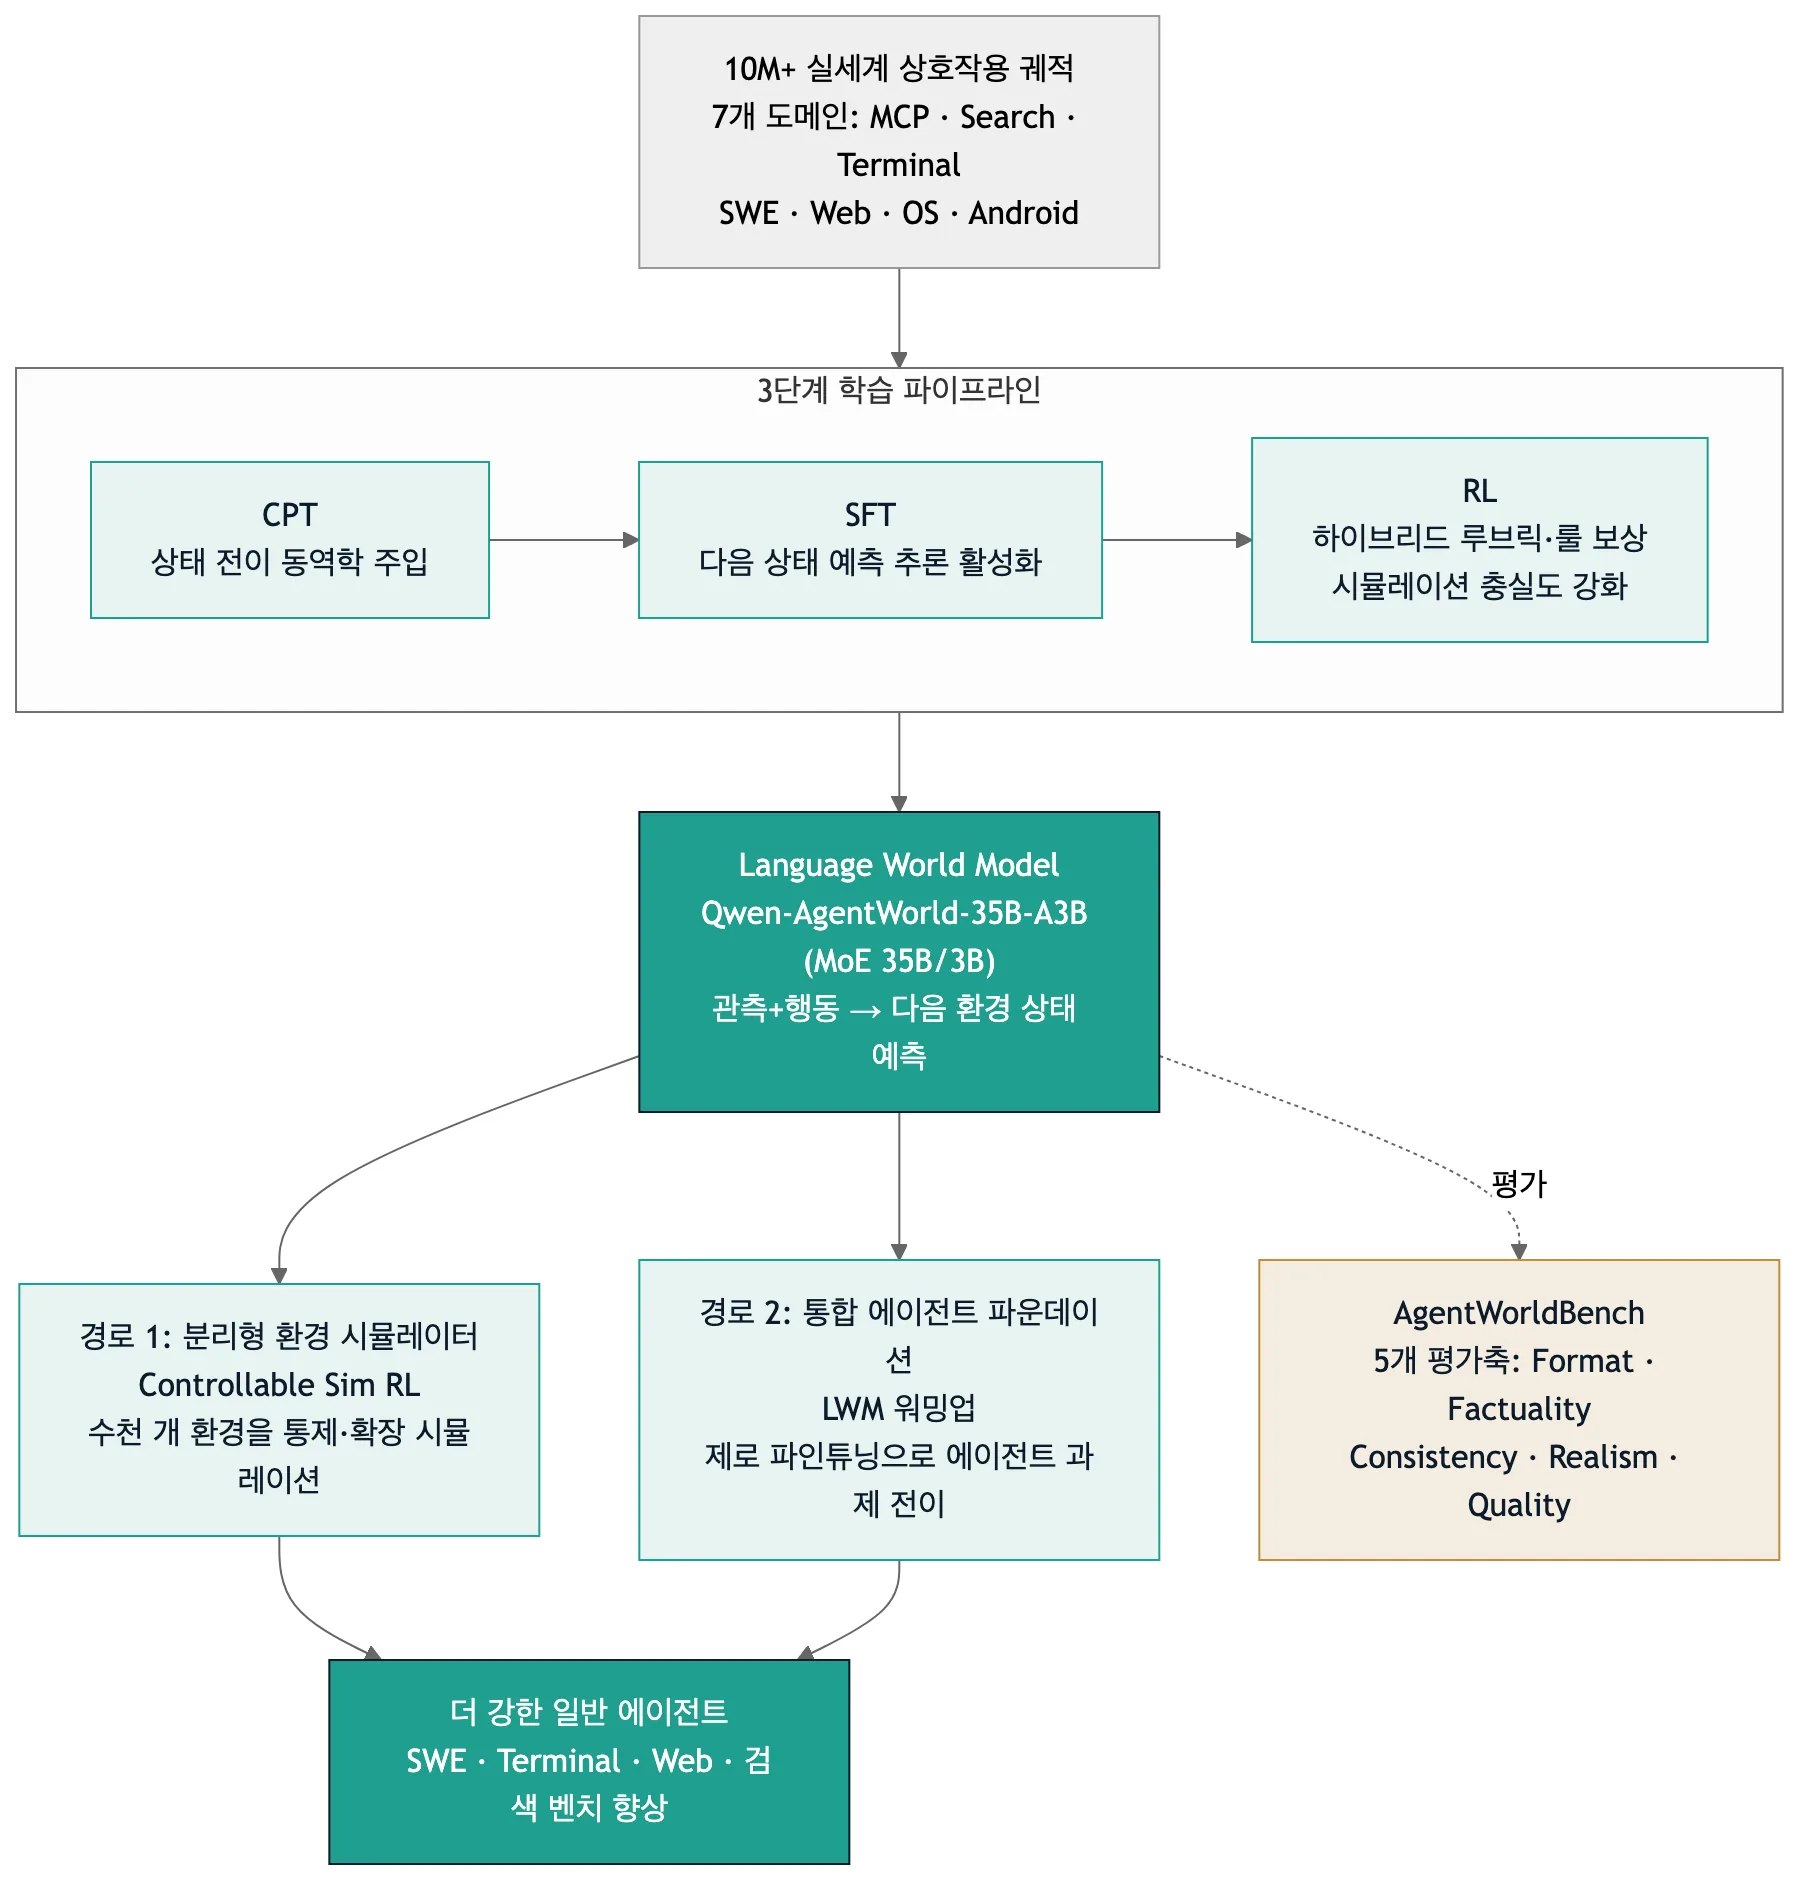
744B in 1 Bit: The On-Premises Question Unsloth's GLM-5.2 Dynamic GGUF Raises
Unsloth shrank GLM-5.2’s (~744B MoE) 1.51TB of BF16 weights down to 176GB with a 1-bit Dynamic GGUF.
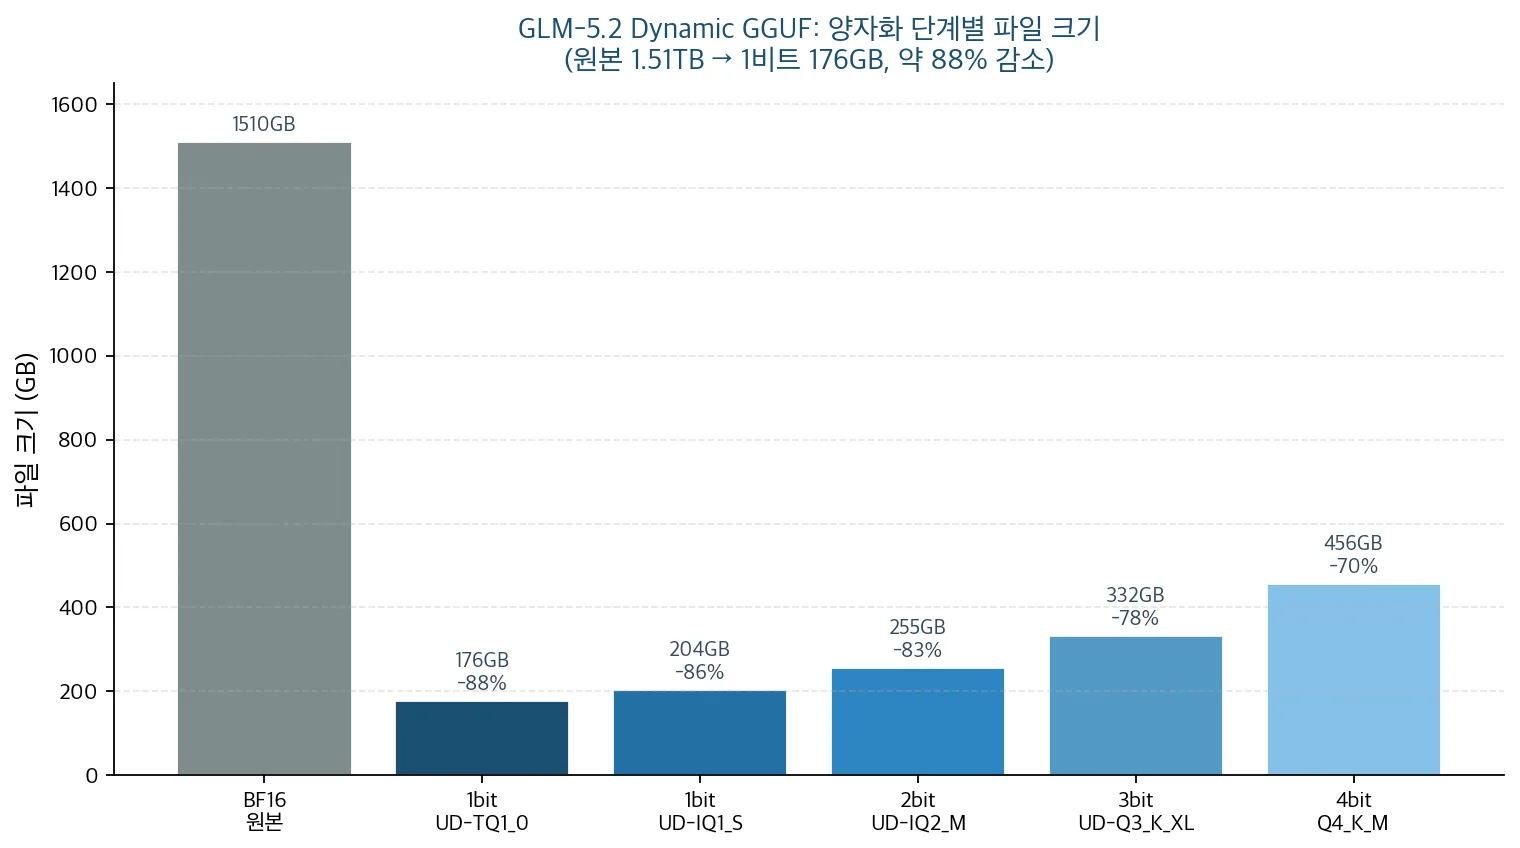
NVIDIA Qwen3.6-35B-A3B-NVFP4: Running 35B at 3B Speed with FP4 Quantization
NVIDIA released an NVFP4 (4-bit) quantized version of Alibaba’s Qwen3.6-35B-A3B.
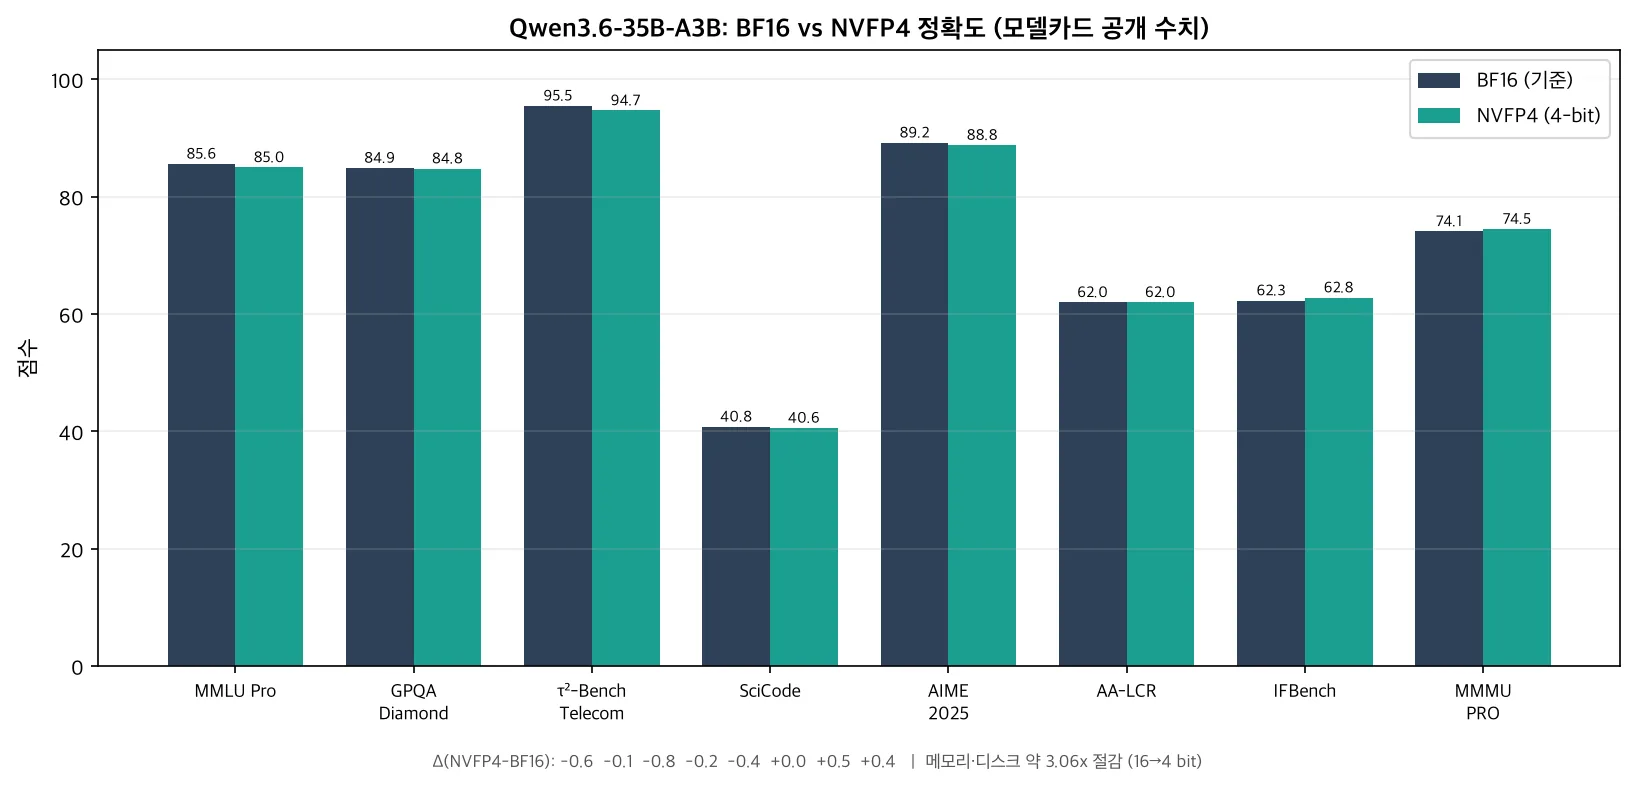
The Model That Thinks 220K Tokens: How GLM-5.2 Flips the Self-Hosting Math
When Matt Pocock used the /teach skill to have GLM-5.2 solve a Rubik’s cube, even the lowest effort setting produced roughly 220,000 tokens of thinking traces across just three turns.
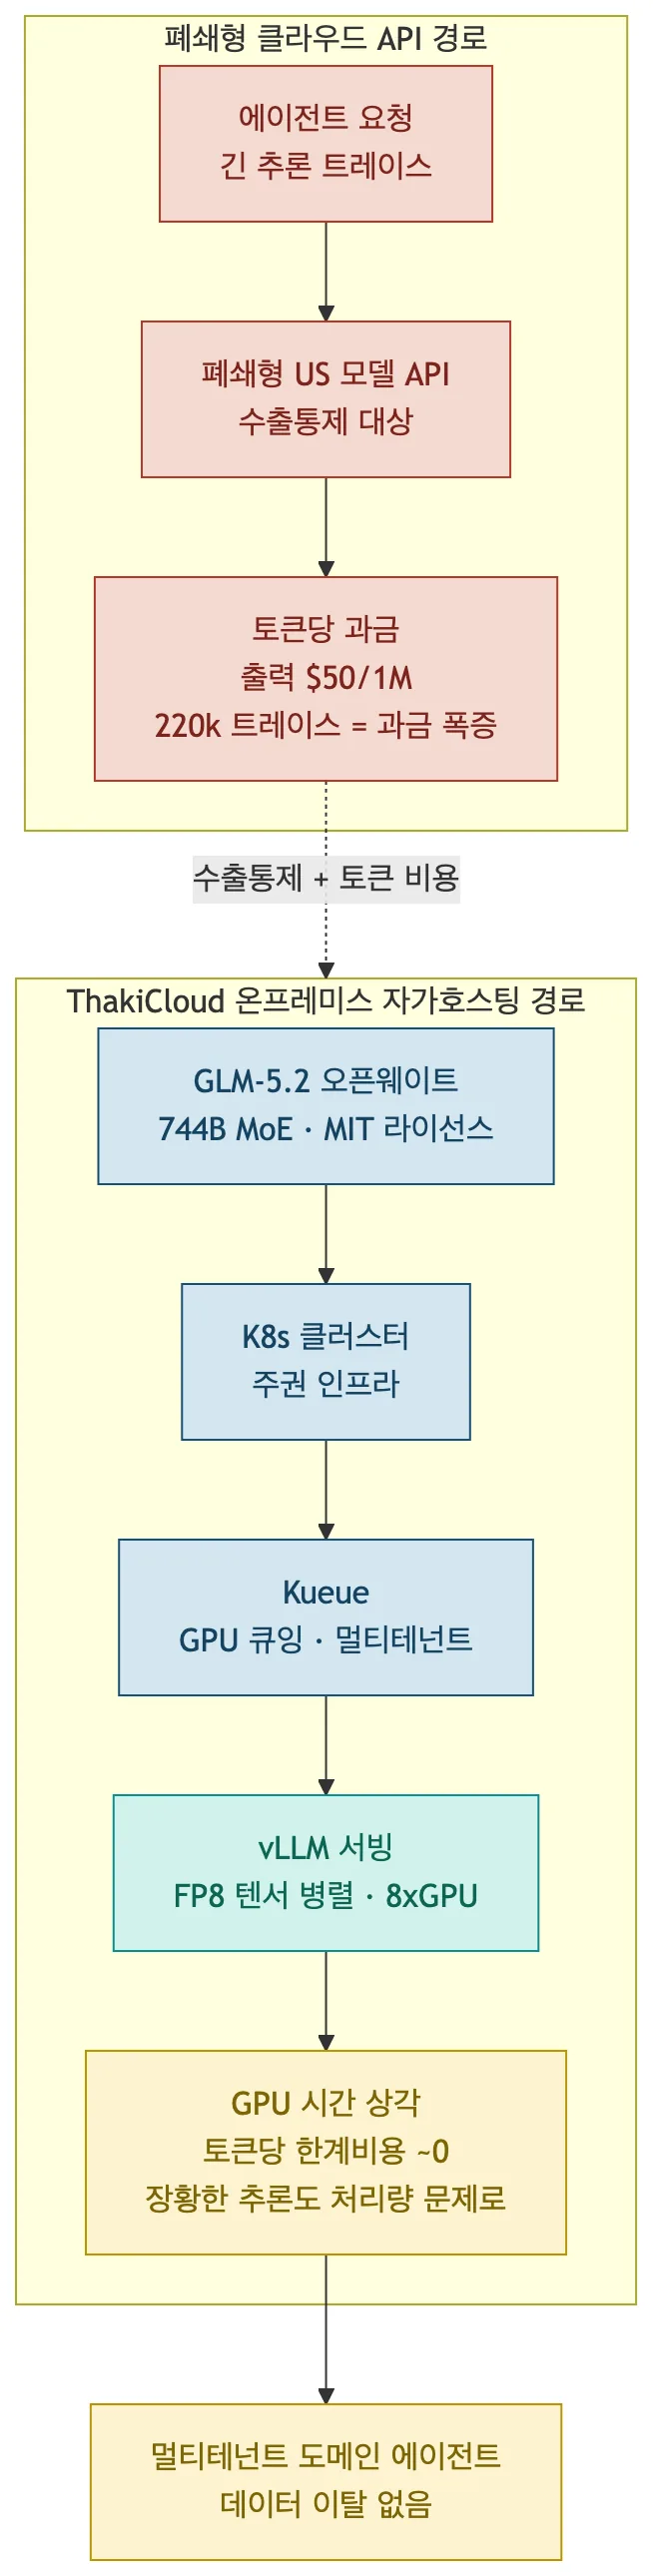
vLLM vs Ollama - Local LLM Inference: When to Choose Which
The conventional wisdom that Ollama is easy and vLLM is fast gets re-examined with 2026 RTX 4090 public benchmarks.
Building Your First AI Agent - Start with a Minimal Guarded Loop
Most introductory guides to AI agents cover four pieces: the LLM brain, memory, tools, and the agent loop.
NVIDIA-Verified Agent Skills: Planting Trust in the Skill Supply Chain with OMS Signatures
NVIDIA has open-sourced over 200 agent skills paired with OMS cryptographic signatures.
Design the Loop Before You Run It: Agent Loop Engineering That Doesn't Burn Tokens
We’re moving from an era of writing good prompts to an era of designing good loops.
Persistent Agents Inside Slack: Reading Claude Tag from a Platform Perspective
Anthropic has released Claude Tag, which lets teams invoke @Claude inside a Slack channel and delegate work to it.
How to Give AI Agents Real Memory - 4 Context Engineering Techniques
A larger context window is not always better.
The Complete Gemma 4 Lineup: Five Apache 2.0 Open-Weight Models and an On-Premises Serving Guide
Released by Google DeepMind in April 2026, Gemma 4 is a multimodal open-weight family of five models spanning E2B to 31B.
Running Gemma 4 26B 16x Parallel on a Single DGX Spark: NVFP4 Quantization and an Honest Cost-Efficiency Review
NVIDIA’s Gemma-4-26B-A4B-NVFP4 running 16 parallel streams on a single DGX Spark (128 GB unified memory) delivers roughly 18 tokens/s per stream and about 300 tokens/s combined.
Anthropic Claude Tag: Turning Slack Channels into a Resident AI Teammate's Workspace
Anthropic has unveiled Claude Tag to replace its existing Slack app.
Connecting Claude Code to Self-Hosted Models with free-claude-code: A Real-World Test of a 17-Provider Routing Proxy
free-claude-code (36.7k stars) intercepts Claude Code traffic through an Anthropic-compatible FastAPI proxy and routes it to 17 providers.
DFlash Speculative Decoding: Up to 15x Faster vLLM Inference with Block Diffusion Drafting
DFlash replaces the autoregressive token-by-token drafter used in EAGLE-3 with a block diffusion drafter that proposes a block of future tokens in a single forward pass.
Routing Claude Code to Your Own Models - Cost-Efficient Coding Infra with claude-code-router
Routing Claude Code traffic across glm-5.2, MiniMax-M2.7, and Kimi K2 with claude-code-router.
Android Emulators in Containers - Building a Reproducible Device Farm on K8s with docker-android
docker-android packages an Android emulator into a single container and runs it headlessly.
Making Videos from Claude Code: I Ran claude-code-video-toolkit Myself
An open-source toolkit that renders 1080p video from inside Claude Code with a couple of slash commands.
A Pinch of Human Data Is Enough: Anchoring Self-Play Driving Policies to People via Regularization
Pure self-play is fast but converges on driving conventions that are incompatible with humans.
Document Parsing SOTA at 0.9B: We Ran PaddleOCR-VL on Korean and Arabic Documents
We installed PaddlePaddle’s 0.9B compact vision-language model PaddleOCR-VL and ran inference on documents mixing Korean, English, and Arabic.
Micron-Anthropic Partnership: Memory Becomes the Battleground of AI Infrastructure
Micron will supply HBM, DRAM, and SSD to Anthropic, co-design AI workload memory architectures, and invested in the Series H round.
Don't Pick an Inference Engine. Pick a Hardware Strategy.
Asking whether to use vLLM, SGLang, or TensorRT-LLM first is the wrong order.
Sakana Fugu: The Orchestration Era Where Models Command Models
Fugu, released by Sakana AI, is an orchestration system that dynamically coordinates multiple LLMs while appearing to the user as a single model API.
Hermes Bible: Search Hermes Agent Docs and Real Workflows in One Place
An unofficial community site that indexes the 169 pages of Nous Research’s Hermes Agent docs plus 28 community-built workflows, all searchable with a single ⌘K.
"Fable 5 Writes 100% of My Code": A Platform-Level Reality Check
A quote spread quickly: the creator of Claude Code reportedly said Fable 5 now writes 100% of their code and is at least 3x more powerful than Opus.
13 Agents Write a Paper Together: Integrating Academic Research Skills into Our Stack
From literature search to submission-ready manuscript, we connected a 10-stage pipeline automatically using a Claude Code skill pack and integrated it into the ThakiCloud agent environment.
The Era of One-Person Cinematic Websites: A Deep Dive into the Gemini 3.1 + Seedance 2.0 Workflow
A 16-minute tutorial published by web designer Viktor Oddy demonstrates how one person can build a cinematic marketing site that once commanded $10,000 in fees, using Gemini 3.1 for site structure and Seedance 2.0 for cinematic video.
What We Need to Rethink When Fable 5 Leaves the Subscription
Anthropic is including Fable 5 in subscription plans at no extra cost only through June 22, and from June 23 it shifts to pay-per-use credits.
The AI Harness That Evolves Itself Every Night - Nightly Self-Evolving Harness
While you sleep, the system learns from yesterday’s failures and improves itself.
The Local LLM Inference 'Bible': Decide the Hardware First, and the Engine Follows
A breakdown of the free comprehensive local LLM inference guide published by Ahmad Osman, r/LocalLLaMA GPU moderator.
How We Controlled LLM Operating Costs with Routing and Guardrails - Lessons from a $705/Day Incident
We honestly disclose a $705 single-day billing incident and prove with numbers the root cause found in a one-month audit (Opus main session at 90.3%) along with the remedies: model routing, retro-based escalation, cron offloading, and context hygiene.
Fine-Tuning LLMs On-Premises Without Exporting Patient Data - Healthcare and Biomedical AI Infrastructure
A complete workflow for healthcare organizations to fine-tune and serve domain-specific LLMs on in-house GPU clusters without sending patient data to external clouds.
GLM-5.2: An MIT Open-Weight Model That Surpasses GPT-5.5, and the Sovereign Serving Opportunity
A deep look at GLM-5.2, the 744B MoE coding model released under the MIT license by China’s Z.ai (Zhipu).
OPD Post-Training: How GLM-5.2 Merged 10+ Expert Models in Two Days
Building GLM-5.2, Z.ai open-sourced its entire RL post-training infrastructure.
Building Sovereign AI for Air-Gapped Public Sector: On-Premises LLM Reference Architecture
A guide for government and public sector organizations that cannot use external cloud services to securely operate LLMs on internal GPU infrastructure.
How a Solo AI Engineer Operates a Stack of 1,620 Skills
1,620 skills, 55 sub-agents, nightly self-evolution, and cost guardrails.
Routing 1,600 Skills Without Noise - Operating an AI Agent Skill Ecosystem
Routing design principles learned from running 1,620 skills solo on Claude Code.
The Real Engineering Behind 'AI That Works While You Sleep': A Deep Dive into Opus 4.8 Dynamic Workflows and Parallel Subagents
A viral X article about ‘40 workflows that make money while you sleep’ swept through developer timelines.
GPU Cluster Cost Optimization: Kueue Fair-Share + Gang Scheduling + Scale-to-Zero
How to reclaim tens of millions of dollars annually wasted across three bottlenecks in a 1,000-GPU cluster using Kubernetes-native scheduling.
The Open-Weight Model That Matches GPT-5.5 at One-Sixth the Cost: A Self-Hosting Analysis of GLM-5.2
Z.ai has released GLM-5.2, a 744B MoE coding model under the MIT license.
What Is Agent-Native Cloud: Skills and Policies as First-Class Resources
Why VM-centric cloud is ill-suited for autonomous AI agent operations, and the design principles of agent-native infrastructure that treats Skills, Tools, Policies, and Audit Logs as first-class resources.
Three Giants, Three Futures: What Hassabis, Huang, and Amodei Leave for Builder Organizations
A comparison of the worldviews of Hassabis, Huang, and Amodei, who read the same AI wave through three different lenses of AGI, infrastructure, and labor, and a synthesis of what builder organizations should take from each at a time when their uncertainties overlap.

The Age of Agent-Managed Organizations: Jensen Huang's Vision and the Reshaping of Organizational Culture
When NVIDIA CEO Jensen Huang’s vision of ‘hundreds of agents per engineer’ becomes reality, how must organizational structures and ways of working change?

AGI Is Still Far Off: Demis Hassabis's Realism and the Culture of Expectation Management
Starting from DeepMind CEO Hassabis’s statement that we are ‘nowhere near AGI,’ this post explores why AI organizations should make honest expectation-setting a core cultural value rather than chasing hype.

If AI Were the Best Decision-Maker: A Culture Where Data Beats Intuition
Starting from a market-coined label about Jensen Huang, and deepening the Moneyball legacy, how to root a data-beats-intuition decision culture inside your organization

When Software Becomes Free, What Do Engineers Do? Dario Amodei's Prophecy
When the marginal cost of code approaches zero, the value of an engineering team shifts from ‘what we build’ to ‘knowing what should be built.’

How to Automate Manufacturing Operations with Autonomous Agent Teams
A practical approach to resolving MLOps talent shortages and multi-factory cluster management challenges using multi-persona autonomous agent teams.
AI Governance and Audit Automation in Financial Services: Regulatory Compliance and Autonomous Agent Control
A hypothetical case study examining how banks, securities firms, and insurers can meet data localization, audit trail, and internal control requirements when deploying AI agents – using a policy engine and hash-chain audit logs.
When a Single Skill Pack Can Reshape an AI Coding Agent: Rethinking Enterprise Guardrails
A security researcher published a skill pack that reroutes a general-purpose coding agent into more than twenty specialized workflows using nothing but a routing configuration file, and flagged it themselves as a dangerous dual-use project.
Automating PhD-Grade Research with the STORM Method: A 4-Step Knowledge Curation Workflow
Stanford’s OVAL Lab built STORM, an LLM knowledge-curation system that asks questions, investigates from multiple perspectives, drafts an outline, and produces a cited report.

Automating Empirical Research with an Agent Skill Library: The Stanford REAP Case and Its Limits
An analysis of the agent skill library with over 23,000 empirical research skills released by Stanford REAP-based CoPaper.AI.
One Skill Is Not Enough: Compositional Skill Routing and the Decomposition Bottleneck Revealed by SkillWeaver
A composite user request is not the problem of picking one skill but of composing several.

From TPU v2 to Ironwood: Five Generations of Google's Training Supercomputers
We analyze a paper (arXiv:2606.15870) that traces Google’s five generations of training supercomputers from TPU v2 to Ironwood, covering architectural stability, scale, resilience, power efficiency, and sustainability.
Reproducing a Paper by Changing One Word in the URL: alphaXiv autoresearch and GPU Reproducibility Automation
Swap ‘arxiv’ for ‘autoarxiv’ in an arXiv URL and an agent automatically sets up the codebase environment, runs a minimal reproduction, and estimates the GPU cost of full replication.
RL Post-Training as Infrastructure: The slime Open-Source Framework and RL Scaling
slime, open-sourced by Z.ai, is an LLM post-training framework built for RL scaling.
753B Open Weights on a Consumer GPU: GLM-5.2 and the Economics of On-Premise LLM Serving
An analysis of running the 753B-scale SOTA open-weight model GLM-5.2 on an RTX 4090 consumer GPU.
Gemma 4 12B on an 8GB GPU: What QAT and TurboQuant Mean for Consumer Inference Economics
We look at a community benchmark running Gemma 4 12B on an RTX 4060 8GB using QAT and TurboQuant, and unpack what quantization-aware training and consumer-GPU serving imply for on-premises inference economics from a ThakiCloud serving perspective.
Treating Skills Like Software: A Hands-On Verification of yao-meta-skill v1.1.0
yao-meta-skill, an open-source meta-skill rumored to be more powerful than Anthropic’s official Skill-creator, gets cloned into the ThakiCloud environment and put through its local verification gates.
Controlling Image Style with Structured Prompts: The 5-Section Layered Prompt Technique
An analysis of a structured-prompt technique that turns a travel photo into a Studio Ghibli style animation.
Nature-Grade Figures and Polishing as Code: A Hands-On Report on Running nature-skills
We cloned nature-skills, an open-source Claude skill package that bundles Nature-journal-grade scientific figure generation with academic polishing, and used nature-figure to render ThakiCloud serving data into a submission-grade two-panel figure.
PDF to Markdown Without an LLM: LiteParse, RAG Ingest Cost, and Data Sovereignty
LiteParse, released by LlamaIndex, is an Apache 2.0 open-source parser that converts PDFs to markdown without an LLM.
Cutting Token Cost by 34-71% with Reversible Compression: A Headroom Field Report and ThakiCloud Context Hygiene
The biggest hidden cost of an AI coding agent is context.
Multi-Agent Orchestration on Your Own Machine: Running 10 Parallel Subagents with Gemma 4 26B
We break down a demo that runs Gemma 4 26B locally to orchestrate 10 parallel subagents coding an SVG art gallery.
SkillRet: ThakiCloud Sets the Retrieval Standard for Agents Managing Thousands of Skills
When LLM agents operate with thousands of reusable skills, accurate skill retrieval becomes the bottleneck.
SkillOpt: Optimizing Agent Skills as Trainable Text Components (arXiv:2605.23904)
An analysis of SkillOpt, which treats agent skill documents as external optimization targets and converts scored rollouts into controlled edits (add, delete, replace).
LLM Agents That Evolve Without Rewards: World Knowledge Exploration Training (arXiv:2604.18131)
An analysis of a training methodology in which agents generate world knowledge on their own without external reward signals, then use that knowledge to improve downstream performance.
Code as Agent Harness: A Three-Layer Framework for AI Agent Infrastructure (arXiv:2605.18747)
An analysis of a survey that systematizes how code functions as the foundational infrastructure for AI agent systems, organized into three layers: harness interface, harness mechanism, and multi-agent coordination.
Autogenesis: A Self-Evolving Agent Protocol That Repairs Itself (arXiv:2604.15034)
By abstracting prompts, tools, and memory into versioned protocol resources, the Autogenesis Protocol (AGP) lets an agent close its own improvement loop.
NVIDIA Nemotron-3-Ultra-550B: LatentMoE Hybrid, 1M Context, Korean Language Support On-Premises Analysis
NVIDIA’s Nemotron-3-Ultra-550B-A55B, released under the OpenMDW-1.1 license, is a LatentMoE hybrid architecture combining Mamba-2, MoE, and Attention.
MiniMax-M3: 428B MoE Multimodal, 1M Context and MSA Deliver 9x Faster Prefill Than M2.7
MiniMaxAI’s M3 is a 428B total / 23B active parameter MoE multimodal VLM.
MiniMax-M2.7: 229B Open-Weight Agent Model, 113 Quantization Variants, and License Considerations
MiniMax’s M2.7 offers 229B parameters, FP8 support, and 113 quantization variants, providing a wide range of on-premises deployment paths.
Kimi K2.6: 1T MoE, 32B Active, 300-Subagent Swarm Architecture Analysis
Moonshot AI’s Kimi K2.6 is a MoE model with 1T total parameters but only 32B active per token, maintaining dense 32B inference costs while supporting 256K context and multimodal input.
GLM-5.2: 753B MoE, 1M Context, MIT License Self-Hosting Guide
Z.ai’s GLM-5.2 handles 1M context with 2.9x FLOPs savings using DSA (Dynamic Sparse Attention).
FastContext-1.0-4B-SFT: A 4B Subagent Model Dedicated to Repository Exploration for Coding Agents
Microsoft released FastContext-1.0-4B-SFT, a fine-tuned Qwen3-4B coding agent subagent model.
DiffusionGemma 26B-A4B: Google's Experiment Generating 15-20 Tokens at Once with Discrete Text Diffusion
Google DeepMind released diffusiongemma-26B-A4B-it, a MoE-based VLM that generates text via discrete diffusion rather than autoregressive decoding.
Why We Taught Claude Code Ourselves: ThakiCloud Internal Seminar Materials Now Public
From environment setup to easy-to-miss features.
From a One-Line Topic to a Sellable Ebook: 5 Books in 6 Days with the ai-ebook-launch Skill
A record of actually running an ebook production skill that bundles research, cover design, sales funnel, and deployment scripts into a single pipeline.
EAGLE 3.1 + vLLM: A Production Guide to Speculative Decoding for LLM Serving
After EAGLE 3.1 merged into vLLM main in May 2026, how to integrate speculative decoding into a K8s LLM serving stack and validate real-world performance.
Cutting LLM Serving Costs in Half on Blackwell GPUs with NVFP4
What advantages NVIDIA Blackwell’s native 4-bit floating-point format NVFP4 offers over H100 FP8, and how to apply it in the vLLM/TensorRT-LLM stack.
Preparing for What Comes After NVFP4: A Complete Guide to Quantization Methods for vLLM Serving (Including Unsloth)
Beyond Blackwell-only NVFP4, this guide covers every quantization method you can serve with vLLM today on Hopper and Ampere – AWQ, GPTQ, FP8, W4A16, compressed-tensors, and Unsloth Dynamic 2.0 – with real recipes and serving flags.
vLLM + Prometheus + Kueue: Building an LLM Serving Observability Stack on Kubernetes
How to build an LLM serving observability stack that monitors GPU utilization, KV cache pressure, and token throughput in a Kubernetes multi-tenant environment.
Buying More GPUs Won't Fix It: llm-d Distributed Inference and a Heterogeneous Architecture with GPUs and Any NPU/XPU
llm-d is an inference scheduler that gets more requests through the same GPUs rather than buying more.
The Real Cost of a Single GPU: How ThakiCloud Optimizes AI Inference Spend
GPU depreciation formulas, Kueue gang scheduling, vLLM scale-to-zero, and model-tier routing – all in one place.
vLLM Prefix Caching in Production: Cut Inference Costs by Half with KV Cache Reuse
How to configure and measure vLLM Automatic Prefix Caching in production, with real hit-rate and cost-reduction numbers.
Running Ollama on Kubernetes in Production
Practical patterns for operating Ollama as an LLM serving layer in a K8s cluster rather than as a local experimentation tool.
GPU Workload Preemption with Kueue: ClusterQueue Design and Priority Patterns
Kueue’s preemption mechanism and ClusterQueue design principles from the perspective of operating a real AI/ML platform.
Vibe-Coding-Instruct: SFT for Lightweight Code Agents Using 1.1 Million Samples
Vibe-Coding-Instruct by lazarus19 is an Apache-2.0 dataset of 1.1 million coding instruction-response pairs.
Fable-5-traces: How to Distill Small Models Using Coding Agent Session Traces
Glint-Research released 4,665 Fable 5 (Claude Code) agent traces in AGPL-3.0 under the HF Agent Traces format, with 81% tool-use composition.
Agents Last Exam: Why Computer-Use Agent Evaluation Has Evolved to 153 Long-Horizon Tasks
agents-last-exam is a benchmark dataset of 153 long-horizon tasks for evaluating computer-use agents.
Paxis: Run a Full Team of AI Employees Without Writing Code
Just as traditional clouds treat servers as first-class resources, Paxis treats agent skills, tools, policies, and audit logs as first-class resources.
Production Multi-Agent Orchestration: 6 Patterns and Cost Traps
A practical guide to six multi-agent orchestration patterns validated in production as of 2026.
MCP Tool Integration and Agent Security: What You Need to Know in Production
A look at the security problems and operational patterns that have emerged as MCP became the de facto agent connectivity standard in 2026.
How Far We Automated: A Solo Engineer's Unattended Operations Inventory
Scheduled jobs, event hooks, self-improvement loops, memory pipelines – the complete list of automation that actually runs without a human pressing a button, broken down by cost.
Conversations Become Skills: Mining Workflows from Past Sessions and Letting Agents Evolve Them
We open-source two autonomous loops – one that uses a deterministic engine to mine recurring workflows from 800+ past conversations and package them as skills, and another that evolves existing skill bodies leak-free based on real failure evidence.
Cutting Agent Operating Costs with Routing: Model Tiers, Skill Router, and 7 Cost Rules
Starting from an incident that burned $705 in a single day, we reveal the practical rules and numbers behind how we structurally reduced Claude Code agent operating costs through LLM model routing, a skill router, and token hygiene.
LLM Agent Observability: Tracing, Evaluation Loops, and Production Debugging
A practical look at why traditional logging falls short in multi-agent systems, and how to build span tracing, evaluation pipelines, and production debugging capabilities for LLM agents.
Goclone: Clone Any Website to Your Computer in Seconds
Learn how to use Goclone, a powerful Go-based website cloner that downloads entire websites including HTML, CSS, JavaScript, and images to your local machine.
RAGLight Complete Guide: From Basic RAG to Agentic Workflows
Master RAGLight framework with hands-on examples covering RAG, Agentic RAG, RAT pipelines, and MCP integration for building powerful retrieval-augmented generation systems.
LangGPT: Master Structured Prompt Engineering Framework for Better AI Interactions
Learn how to create high-quality, reusable prompts using LangGPT’s structured framework.
udocker: Complete Guide to Rootless Docker Container Execution
Learn how to run Docker containers without root privileges using udocker - perfect for HPC environments, shared systems, and secure container execution.
Shannon AI Agent Orchestrator: Complete Tutorial for Enterprise-Grade AI Agent Management
Learn how to set up and use Shannon, an open-source AI agent orchestrator with enterprise-grade security, cost controls, and vendor flexibility.
Helm Dashboard: Complete Guide to Kubernetes Helm Charts UI Management
A comprehensive tutorial on Helm Dashboard - the missing UI for Helm that simplifies Kubernetes chart management with visual interface, revision history, and easy rollback capabilities.
Beyond Technical Skills: A Strategic Approach to Career Growth
While technical excellence is the foundation of any career, true advancement requires mastering four essential disciplines: technical skill, product thinking, project execution, and people skills.

Comprehensive Guide to LLM Dataset Curation: From Training to Preference Alignment
Explore the essential datasets and tools for LLM post-training, including supervised fine-tuning datasets, preference alignment data, and curation methodologies for building high-quality AI models.
Awesome Public Datasets: Your Gateway to High-Quality Open Data
Discover the ultimate collection of curated public datasets across diverse domains, from agriculture to eSports, maintained by the global open data community.
NVIDIA Nemotron 6 Million Multilingual Reasoning Dataset Released -- Strengthening the Open-Source AI Ecosystem
NVIDIA releases a 6-million-example multilingual reasoning dataset, providing high-quality training data expanded across five languages: French, Spanish, German, Italian, and Japanese.
NVIDIA Granary: A Large-Scale Multilingual Speech Dataset Spanning 25 European Languages
NVIDIA’s latest multilingual speech recognition and translation dataset, Granary, covers 640,000 hours of audio across 25 European languages.
Rowfill: Complete Guide to Unstructured Data Processing Platform for Knowledge Workers
Discover the core features and applications of Rowfill, an open-source AI platform that automatically structures PDF, image, and audio files.
AnyCrawl: A Comprehensive Guide to the LLM-Ready Web Crawler - A New Standard for AI Data Collection
Master how to transform websites into LLM-ready data and efficiently collect Google/Bing SERP results with AnyCrawl, built on Node.js/TypeScript.
ByteDance Dolphin Document Image Parsing: Fox Dataset and Benchmark Complete Analysis
A detailed analysis of ByteDance’s Dolphin project Fox dataset and benchmark, including the Analyze-then-Parse paradigm from ACL 2025 and a large-scale dataset with 30M+ samples.
dots.ocr: SOTA Multilingual Document Parsing with 1.7B Parameters - Complete Analysis
How to implement multilingual document layout analysis and OCR in a single vision-language model using dots.ocr, released by RedNote.
Essential Skills Guide for ML Engineers - A Must-Have Checklist for Recruiters and Candidates
A practical guide outlining the core technology stack and competencies needed to build ML applications in production environments

AI Coding Era Cultural Innovation: Paradigm Shift from Resistance to Collaboration
How to embrace and develop the new development culture brought by Vibe Coding and Agentic Coding? A guide to building collaborative culture with AI, breaking away from past conventions

Quantifying Team Chemistry with Saberr: Data-Driven Hiring and Organizational Strategy
How to leverage Saberr algorithms to quantify team compatibility through 15-minute surveys and behavioral data, optimizing everything from hiring to onboarding

Building Data-Driven Organizational Culture with Moneyball Thinking
How to apply Moneyball strategy that discovers hidden value through data and achieves maximum performance relative to resources in development, product, and hiring

Hacking and Reverse Engineering: A New Methodology for AI Vibe Coding Era
In the AI era, developers don’t need to know everything.

AI Engineering Learning Roadmap
We’re sharing a learning roadmap for those who want to start AI engineering.
Backend·Infrastructure Engineer Hiring: **10 Must-Read Books** and the People We're Looking For
Introducing the ideal candidate profile and hiring criteria through 10 must-read books for backend·infrastructure engineer recruitment and practical application cases.

Three Vs-Driven MLOps at ThakiCloud 🚀 — Why You'll Want to Join Us
ThakiCloud’s Three Vs (Velocity, Validation, Versioning) based MLOps culture and practical cases, plus recruitment information for colleagues to join us.
[Thaki Cloud Life & Career] KCD Seoul 2025
Sharing materials presented at KCD Seoul 2025.
Thaki Cloud Life & Career Guide
Sharing Thaki Cloud’s corporate culture, benefits, developer stories, recruitment information, and more.
[Thaki Cloud Life & Career] Mission, Principles, Values
Sharing Thaki Cloud’s mission, principles, and values.
No posts match these filters.